Author: admin

  • MOSS Bounding Box Grid

    MOSS Bounding Box Grid

    MOSS Bounding Box Grid

    Visually editing and fine tuning composition

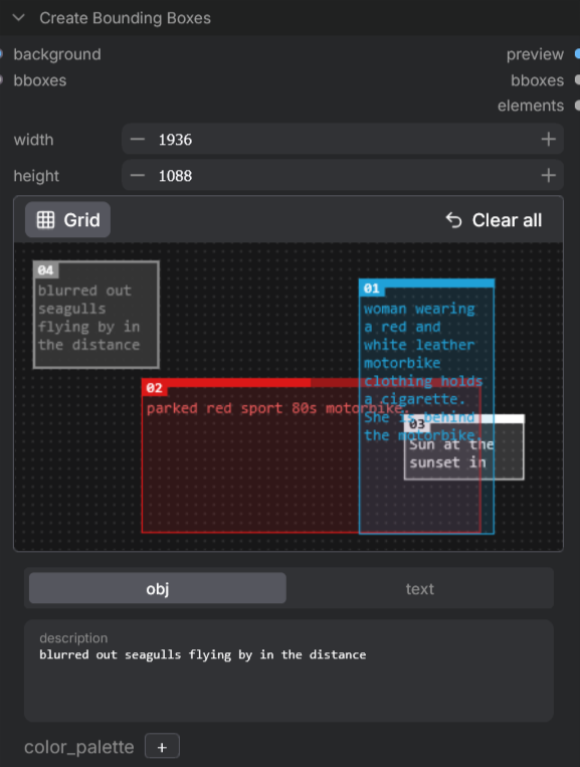
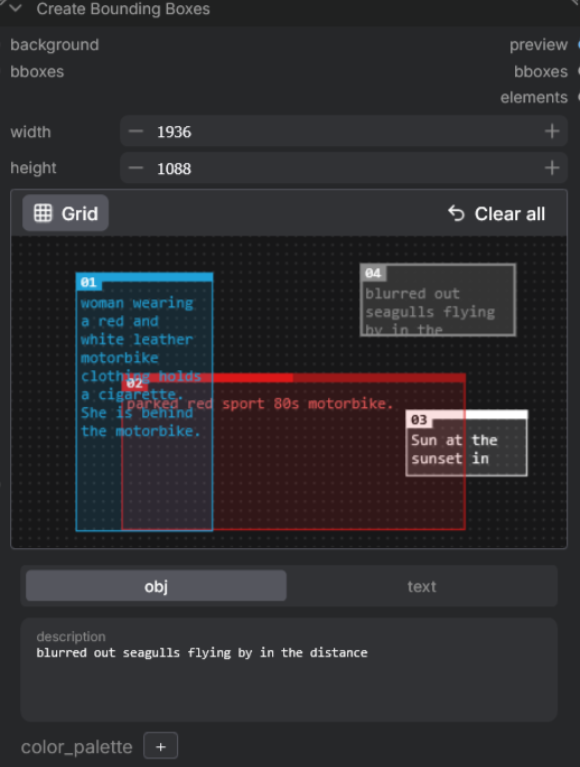
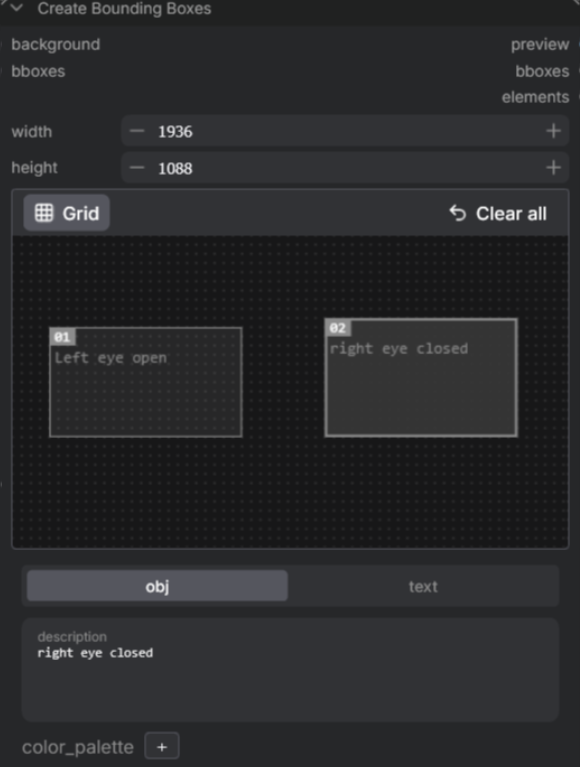
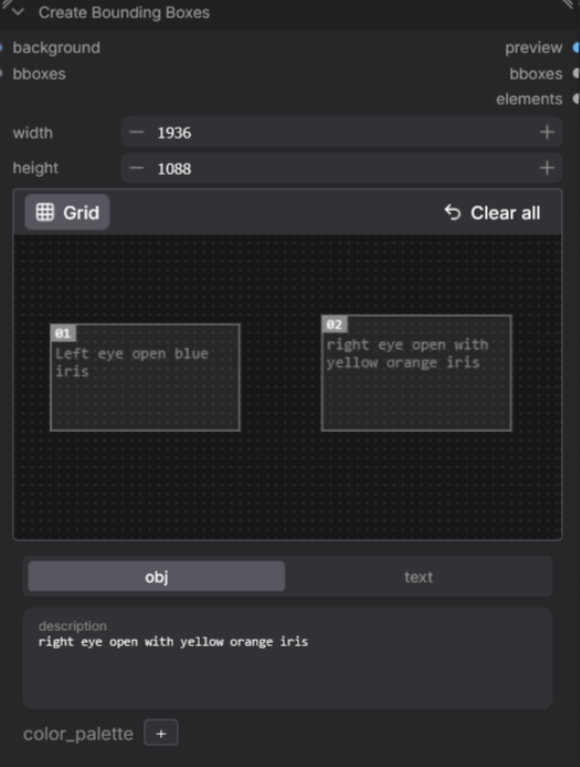
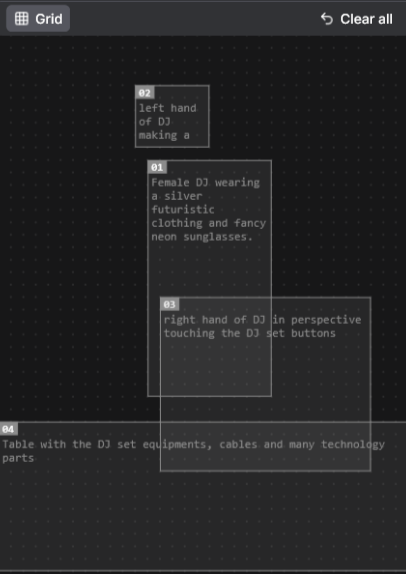
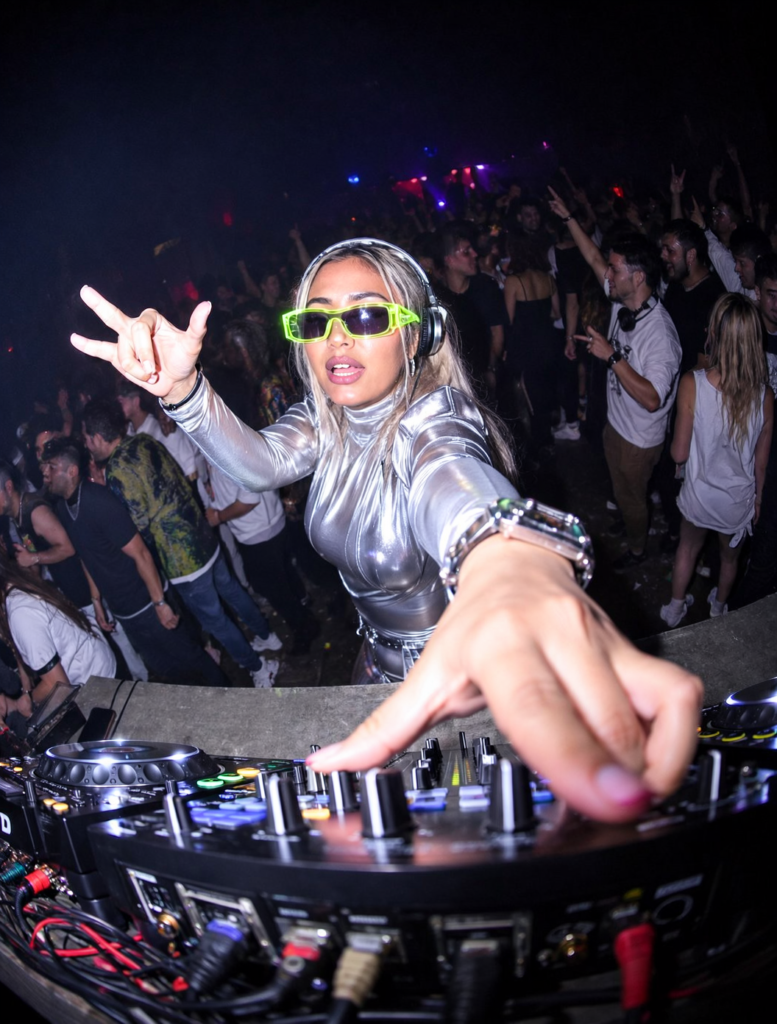
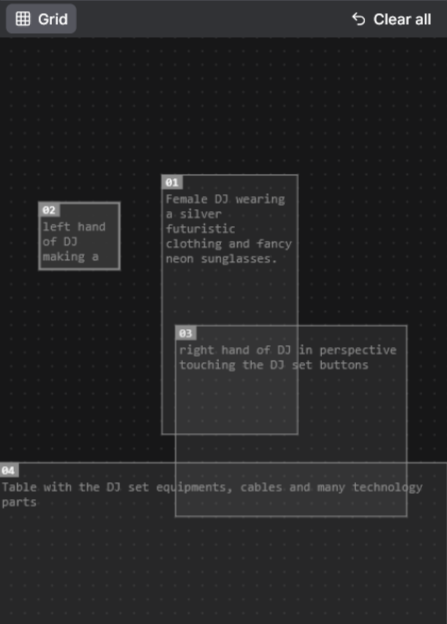
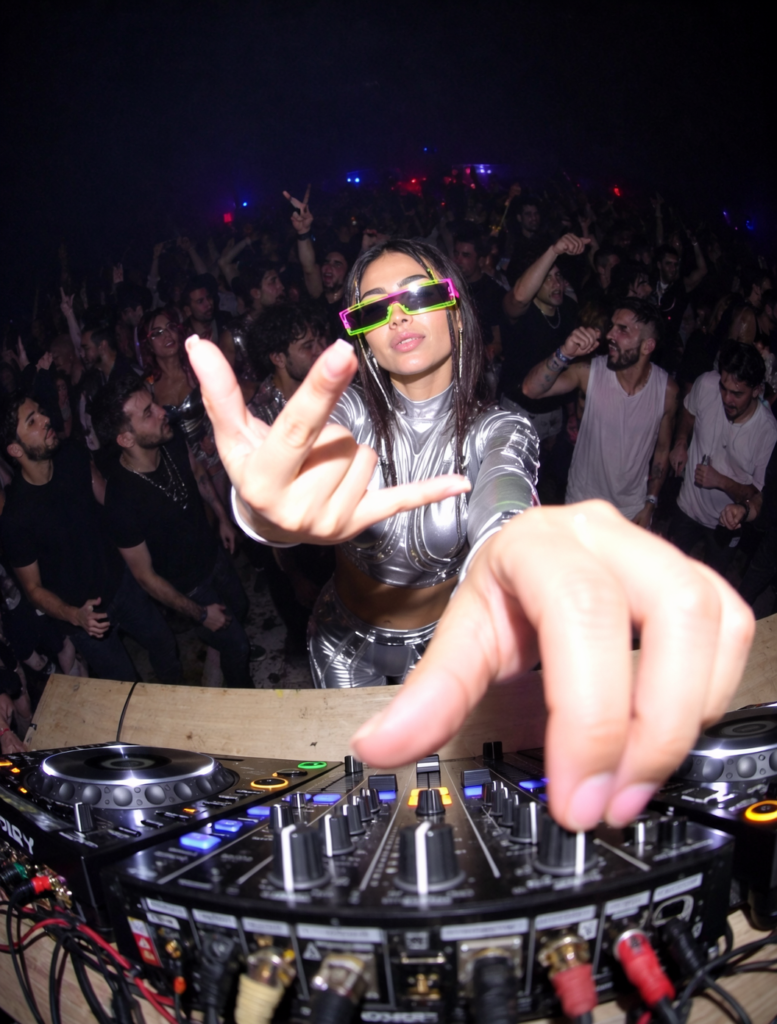
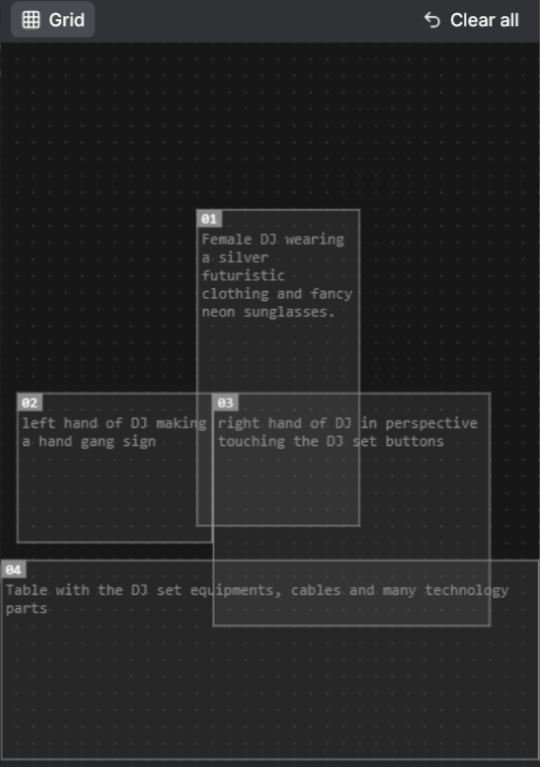
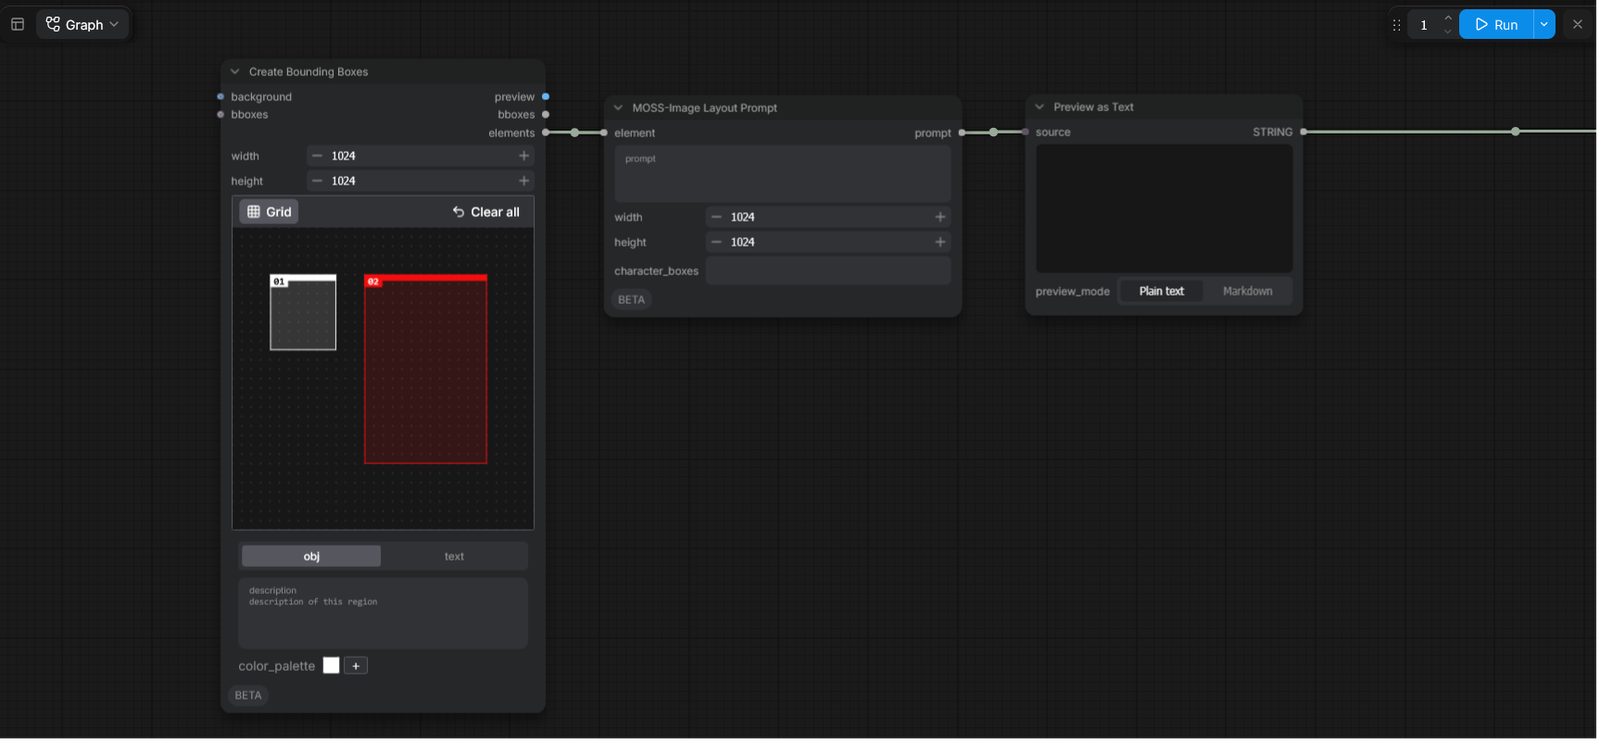
    The Bounding Box Grid node in ComfyUI raised a new technique to layout and position elements within the composition in a visual and more Cartesian precise way. It’s equivalent to the Edit from Qwen, Flux and others well known generative models.

    This study will refer the use of Bounding Box in a MOSS Image workflow.

    Tip 1: if your Bounding Box node is greyed out and you can not draw the rectangles inside the grid area, you need to turn on the Node 2.0 on ComfyUI. You cna do that by clicking the ComfyUI logo and then on Node 2.0.

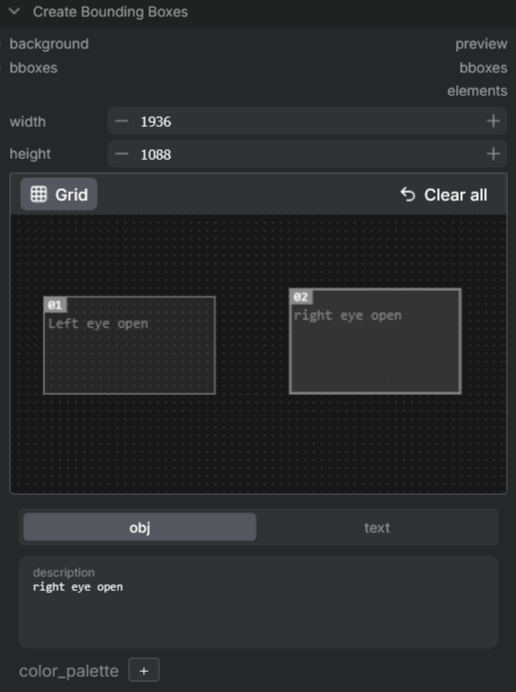
    Tip 2: you have to manually enter the width and height of your output otherwise the box calculation will be a miss. If you change the aspect ratio, you have to change here the dimensions as well.

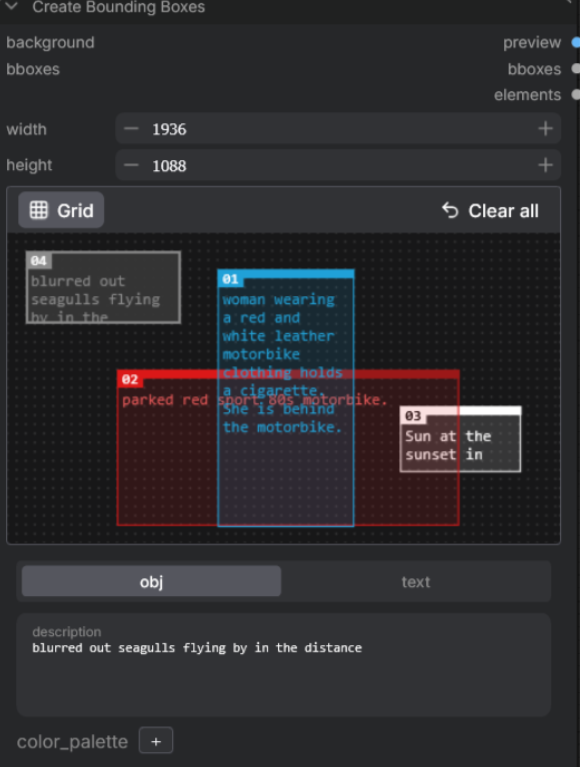
    The workflow requires three new nodes to be setup. Double-click the empty area and choose the Create Bounding Box node, the MOSS-Image Layout Prompt node and the Prompt as Text node. From the first node you will connect the output Elements to the input Element, and the output Prompt to the input Source. To finish, you have to connect the output String to the input of your Positive Prompting, in this case would be Text to Image (MOSS Image).

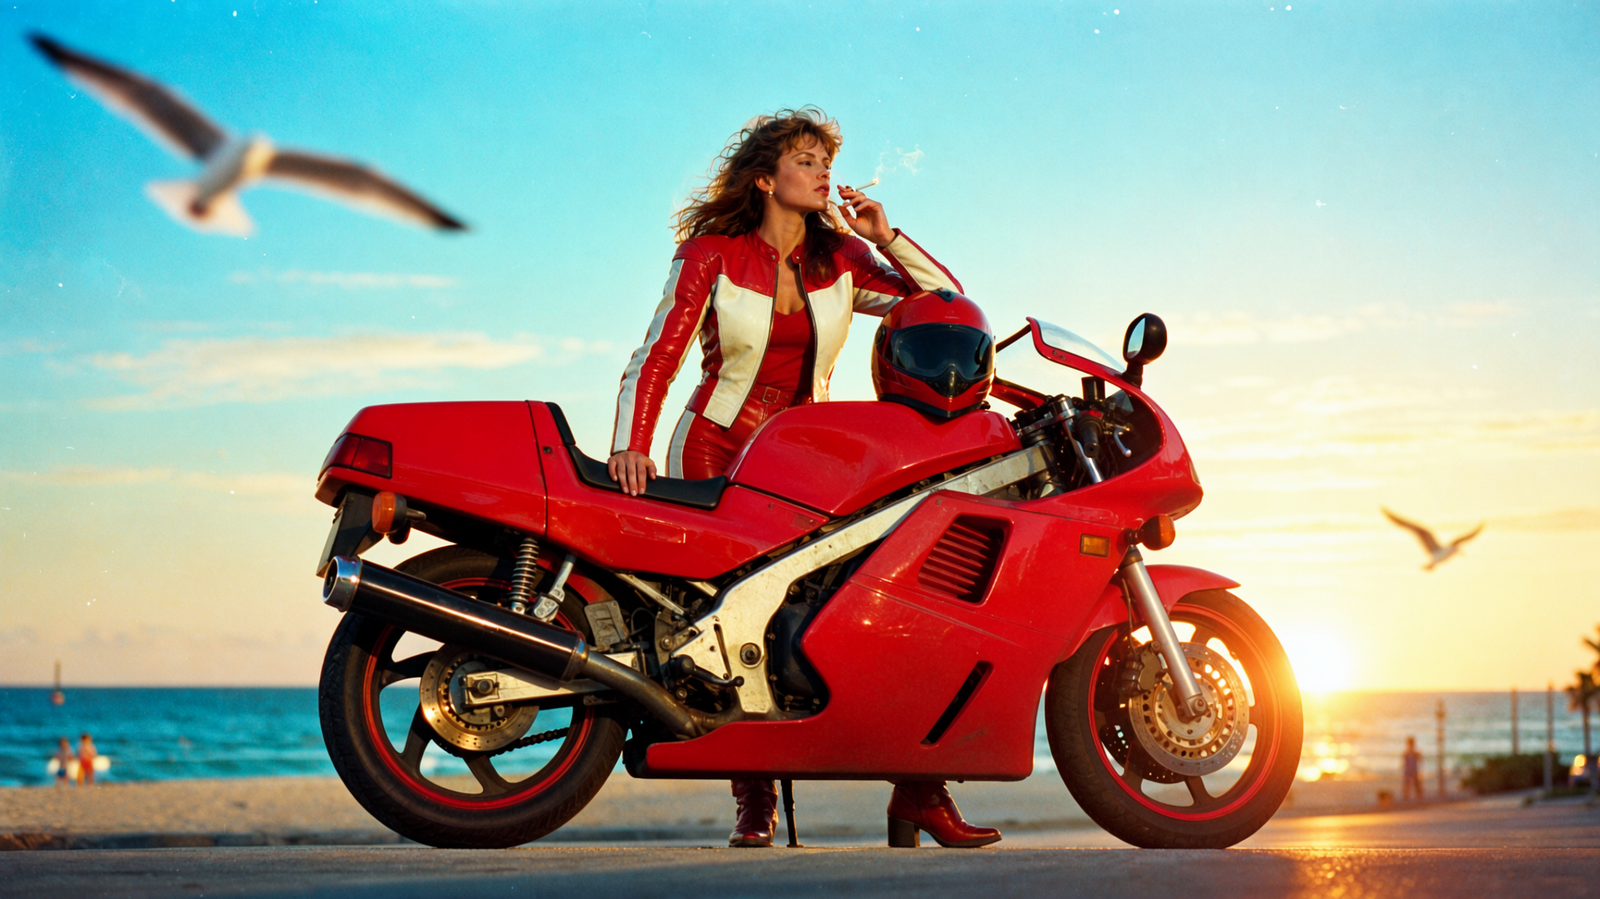
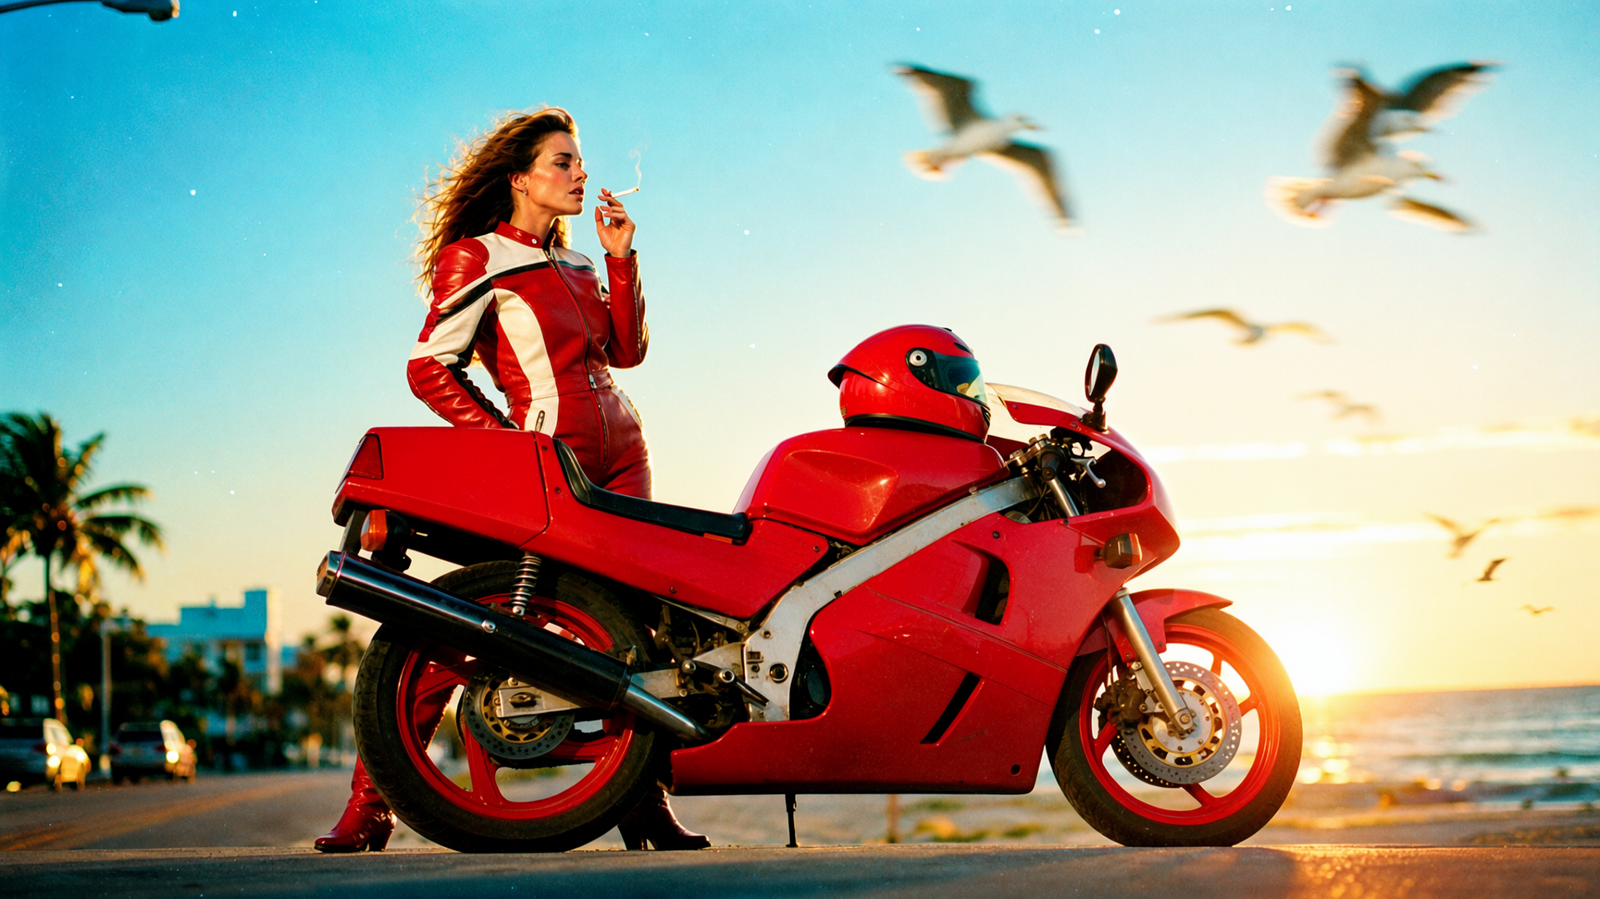
    Once everything is setup, you can start prompting and drawing the rectangles inside the Bounding Box node. Check some examples of how the Bounding Box node can affect the composition.

  • MOSS Image Comparison Chart

    MOSS Image Comparison Chart

    MOSS Image Comparison Chart

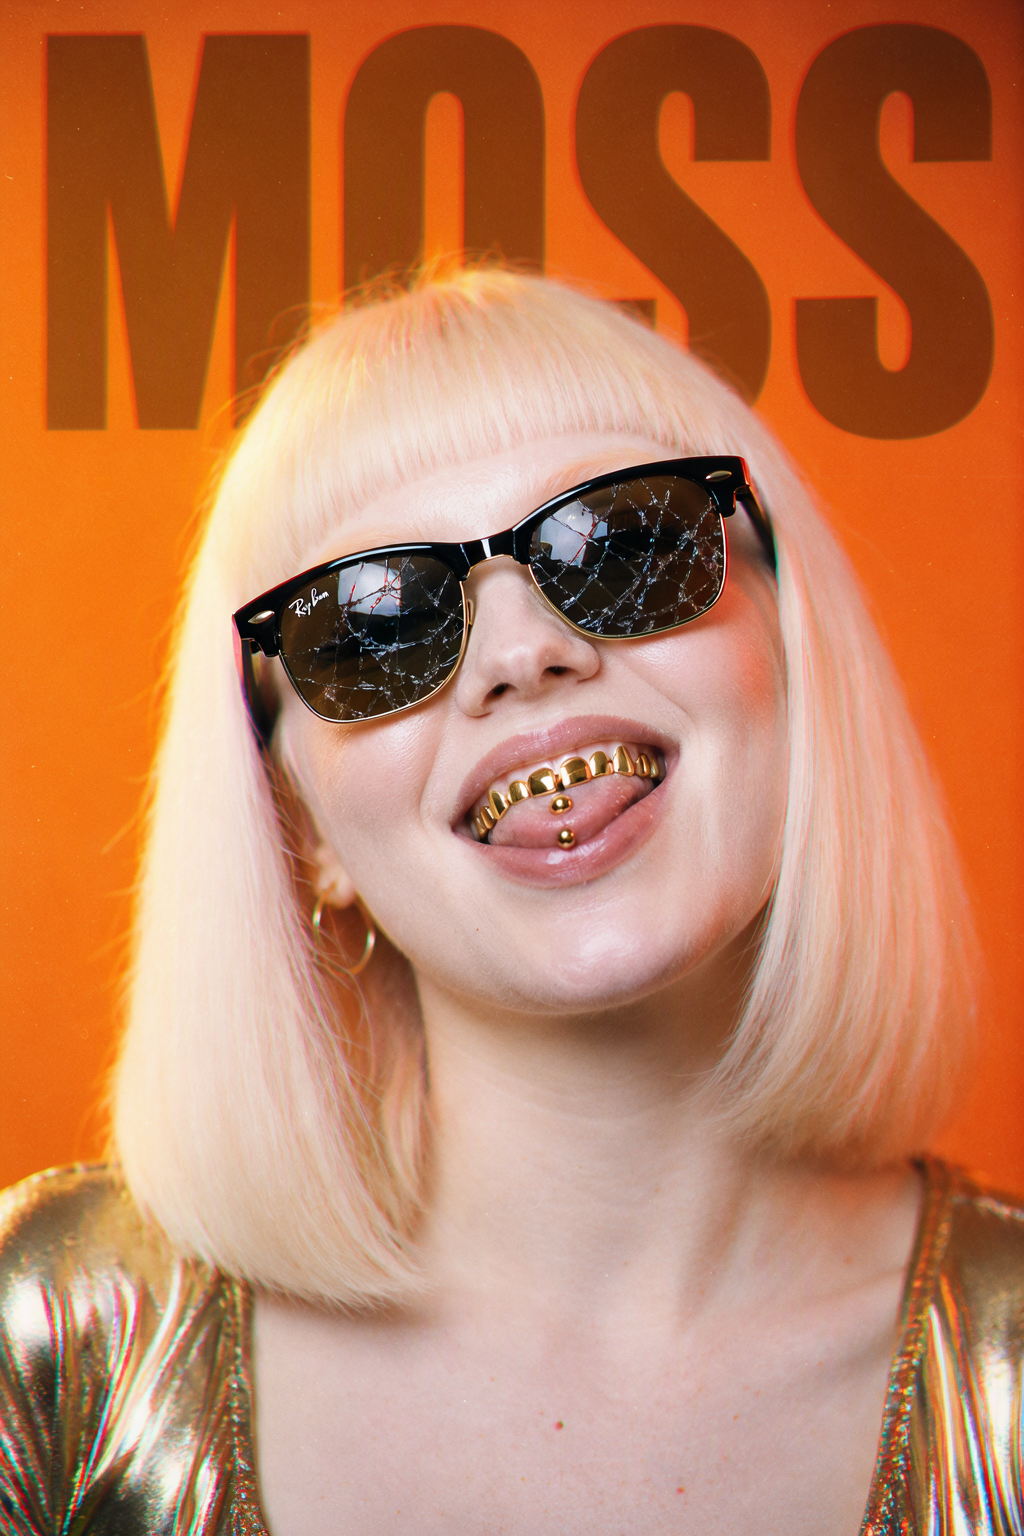
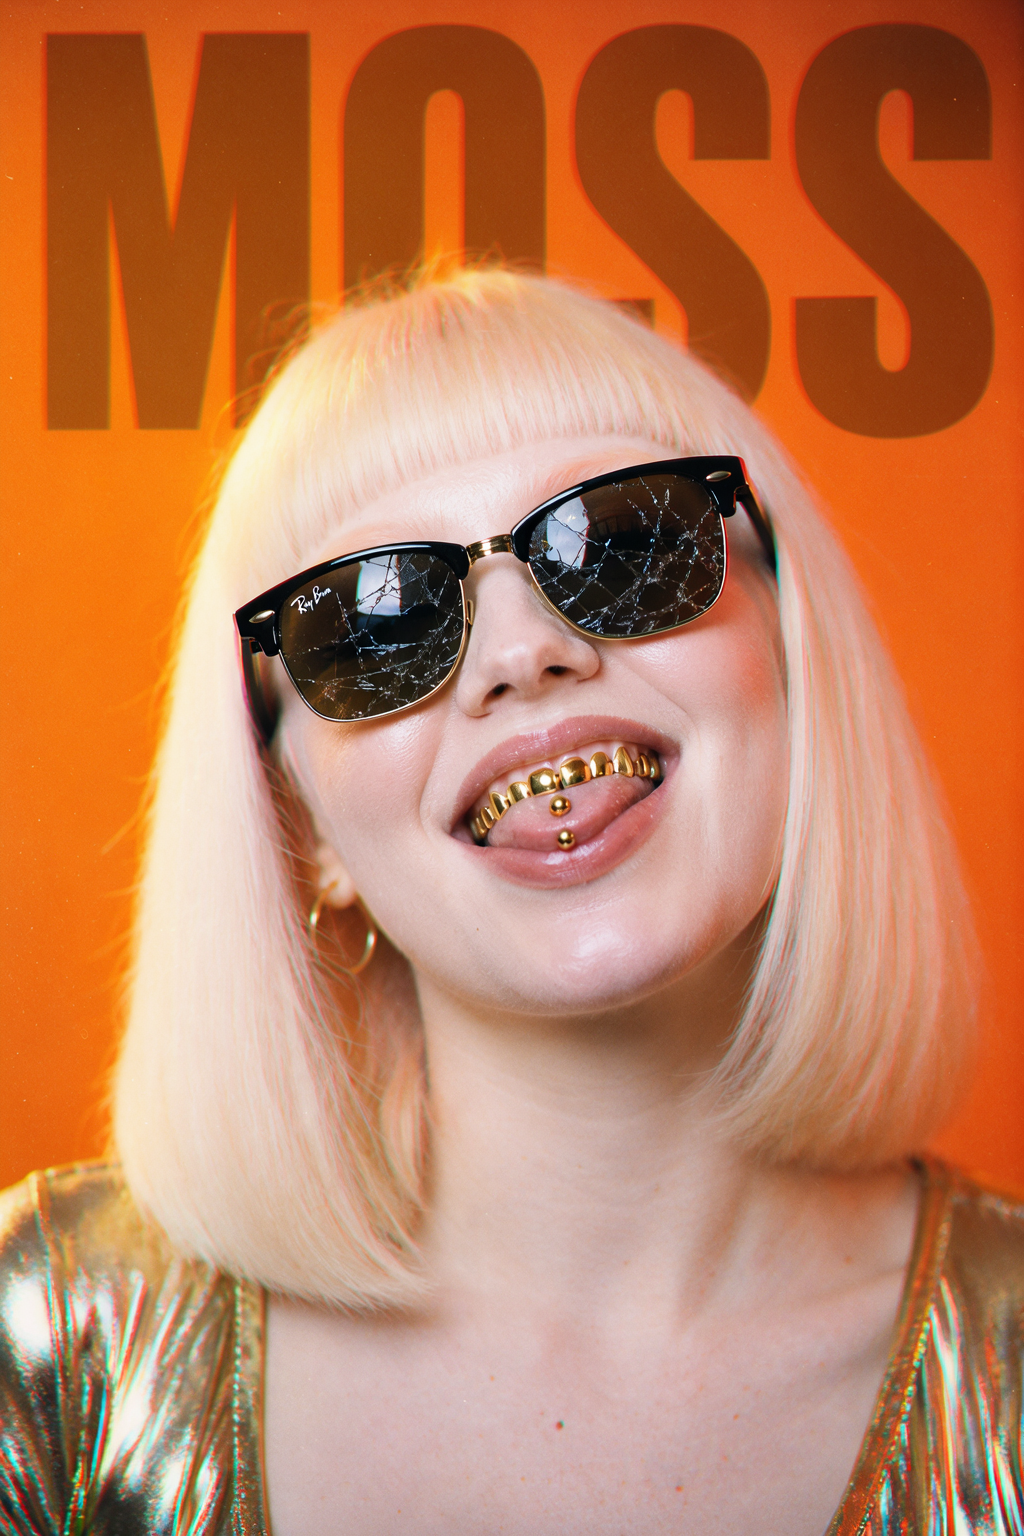
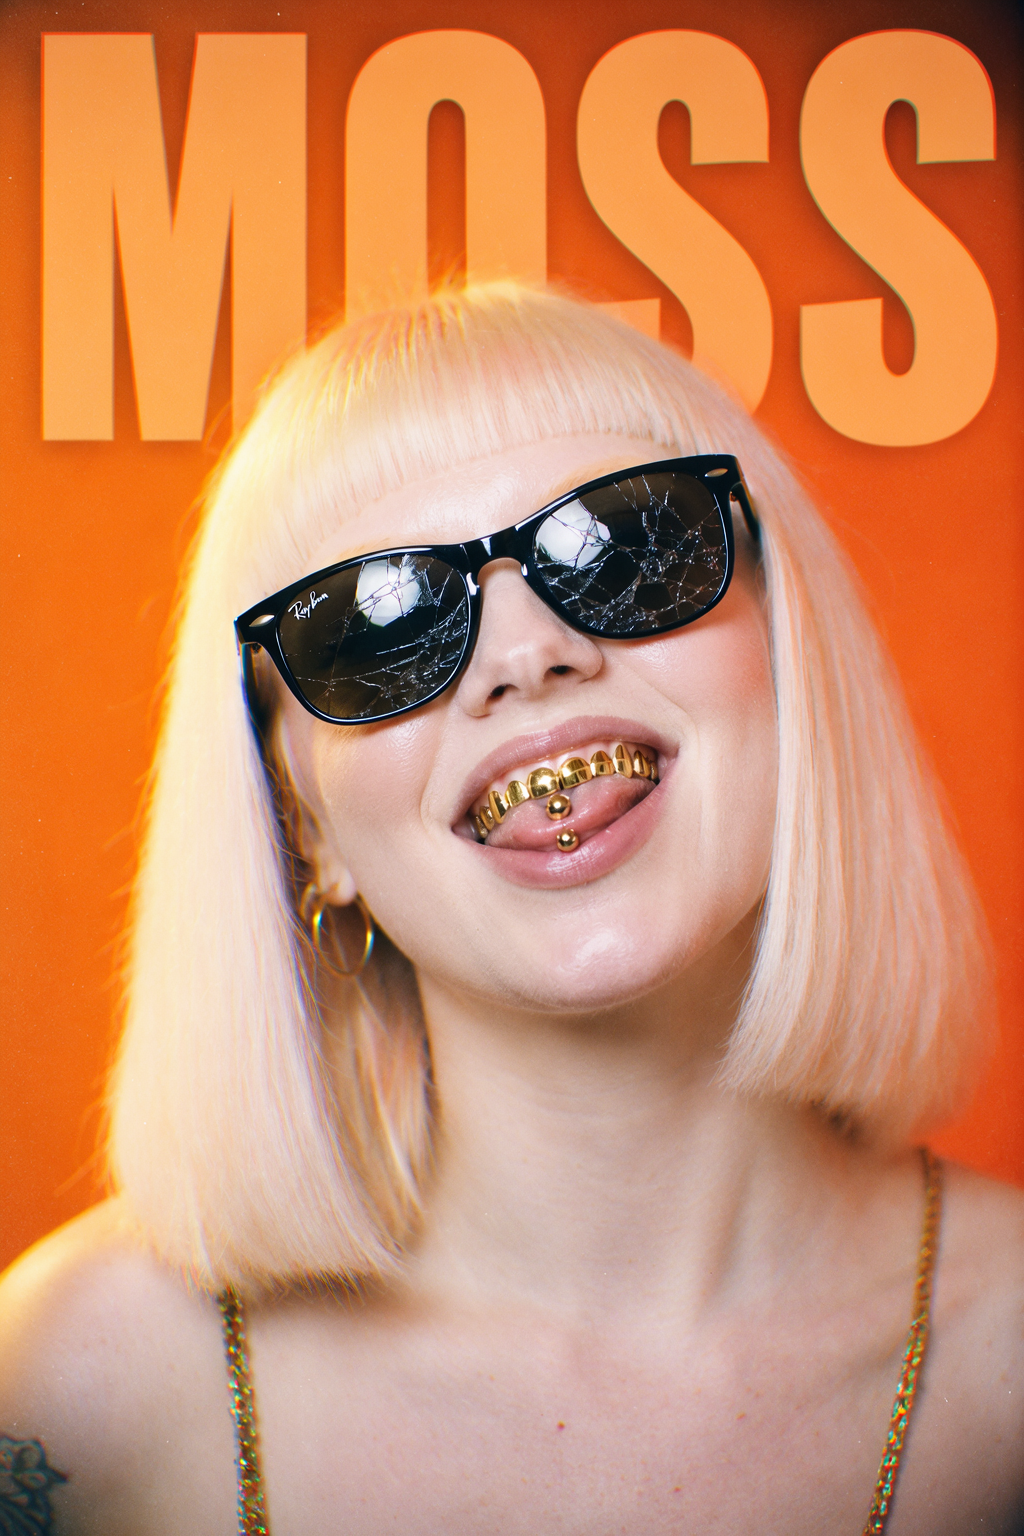
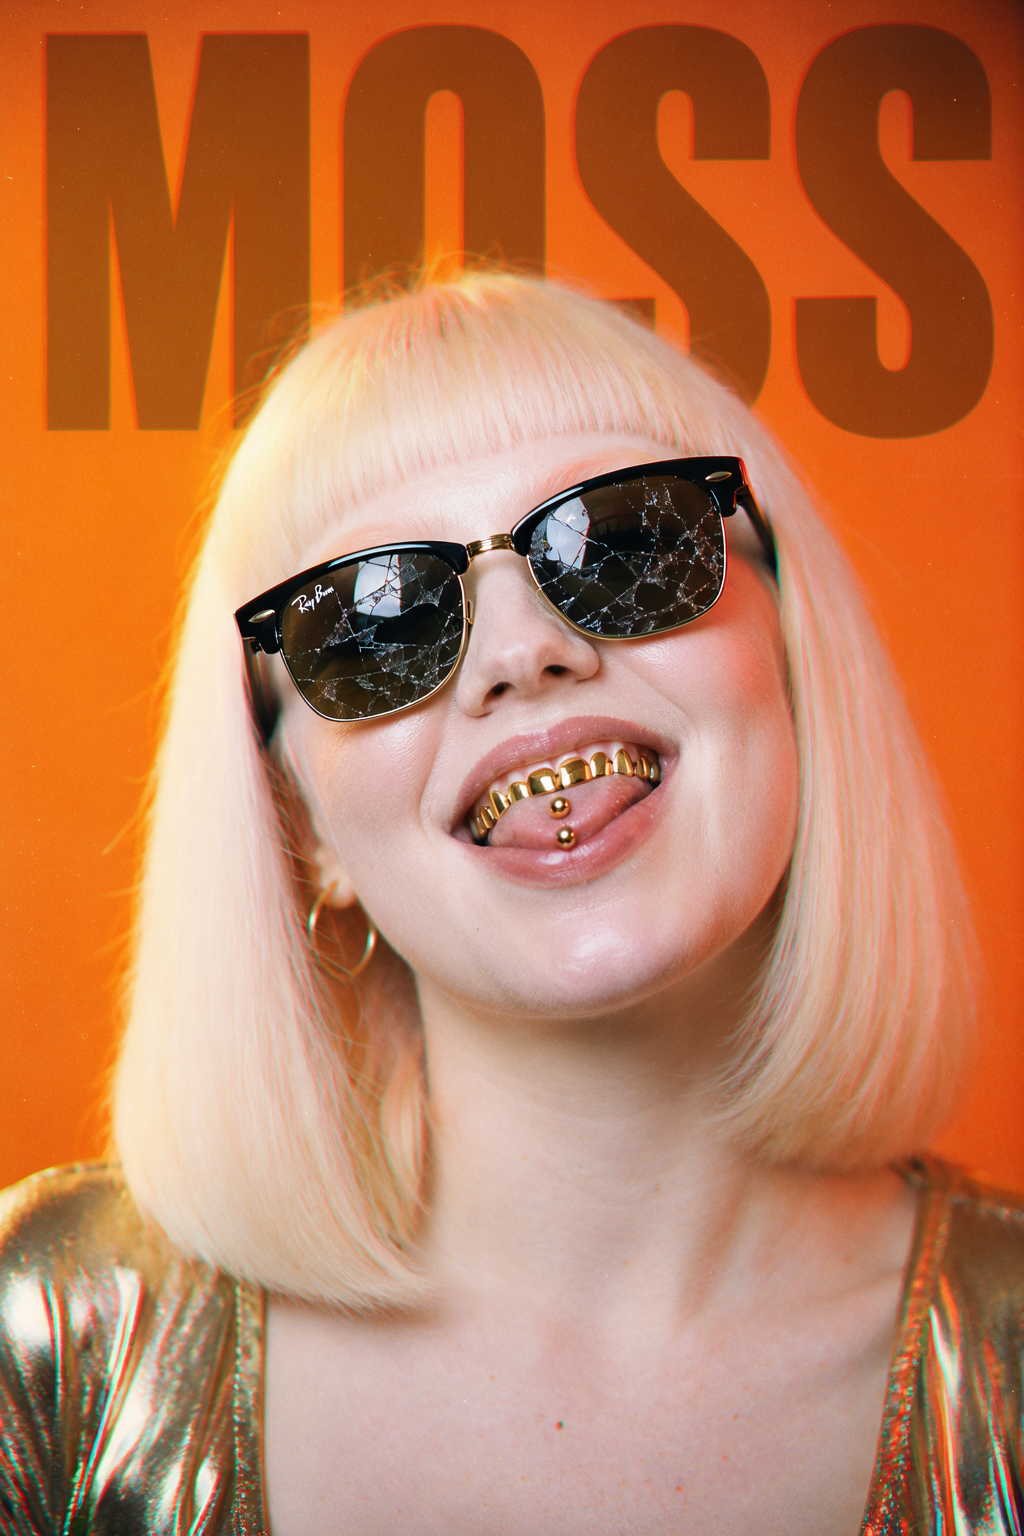
    MOSS Image SFT benchmark

    New Text-to-Image (t2i) models suddenly appears like in waves. This last season we had the surprisingly positive user rated Krea 2,  Z-Image (and Turbo version) and then Qwen Image 2, bringing fantastic photorealist outputs to open image generators. Google’s Nano Banana 2 and GPT2 with extreme high quality outputs were listed on the paid platforms. Now, there is another model shining new to the community and some already claim to be the most realistic open Image-to-Text model to the date. It’s name is MOSS, it does support up to 4K tokens and it comes in two versions: MOSS Image SFT and MOSS Image Base. Both versions are available in ComfyUI, runs on entry-level GPUs and are capable of NSFW content.

    MOSS Image SFT means supervised fine-tuned text-to-image model and is a version prone to render outputs a bit faster, although human faces tend to be similar or rendering less variations even in multiple render batches.

    Moss Image Base means the original model intended to be tuned by the community and to be played along LORAs and other trainings. It was reported to offer more variations on similar rendered batches, but at a cost of rendering speed as it is supposed to use around 50 steps.

    Based on my other successful article on RES4LYF Benchmarking written few months ago, I will reproduce here a similar approach in order to study and better understand how this model behaves.

    You can download MOSS Image model files from Huggingface.

    I find it easier to browse the Templates in ConfyUI (I use the portable version, less headache) and choose MOSS. It will ask to download all the needed files. You just have to move then into the appropriate folders as it is described in the provided workflow.

    I’m running ComfyUI on a Windows PC with a Nvidia Geforce GTX 3080ti. For the sake of comparison, I will be using the exact same prompt, without prompt enhancing, the exact same seed and aspect ratios. I will be changing the sampler, the scheduler, the CFG and the steps amount. Let’s roll!

    Here is the Positive Prompt:

    				
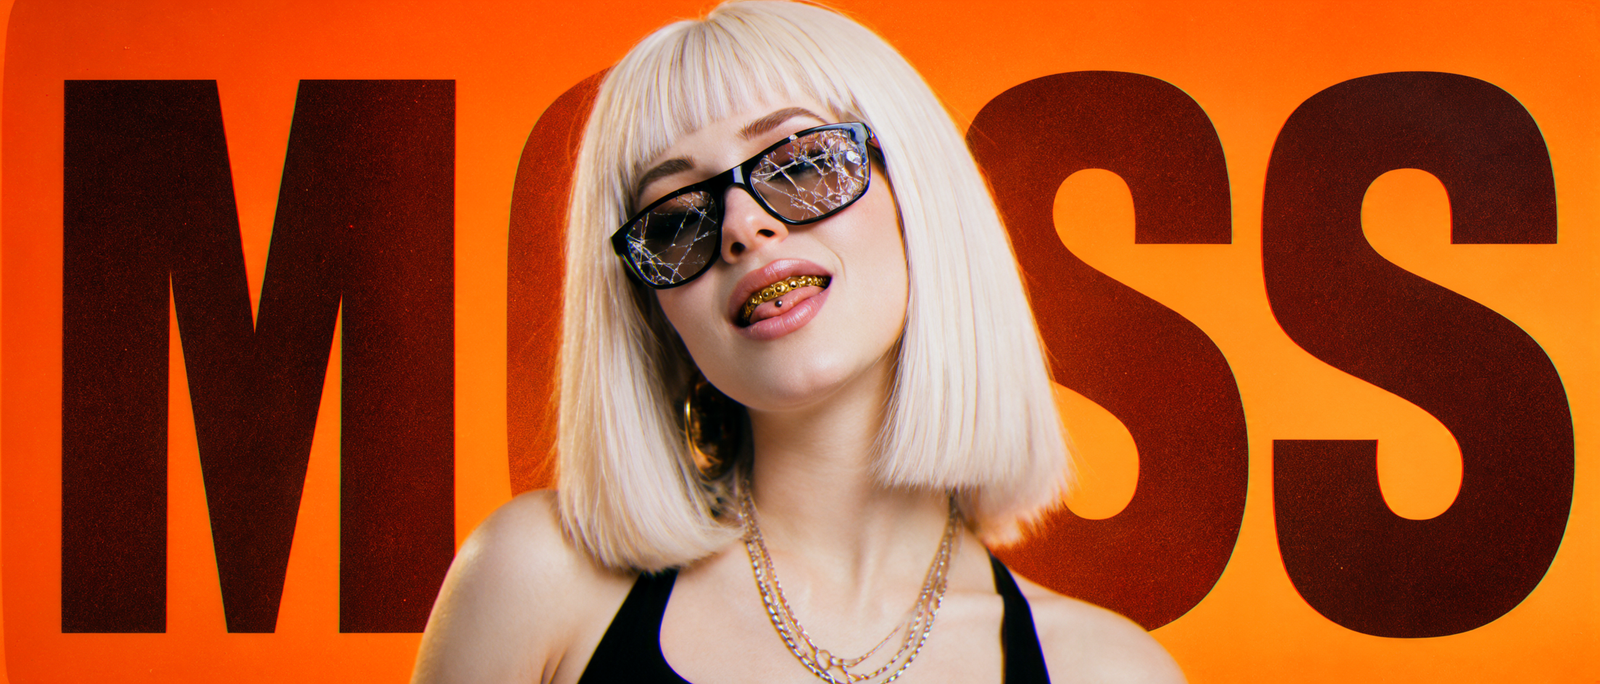
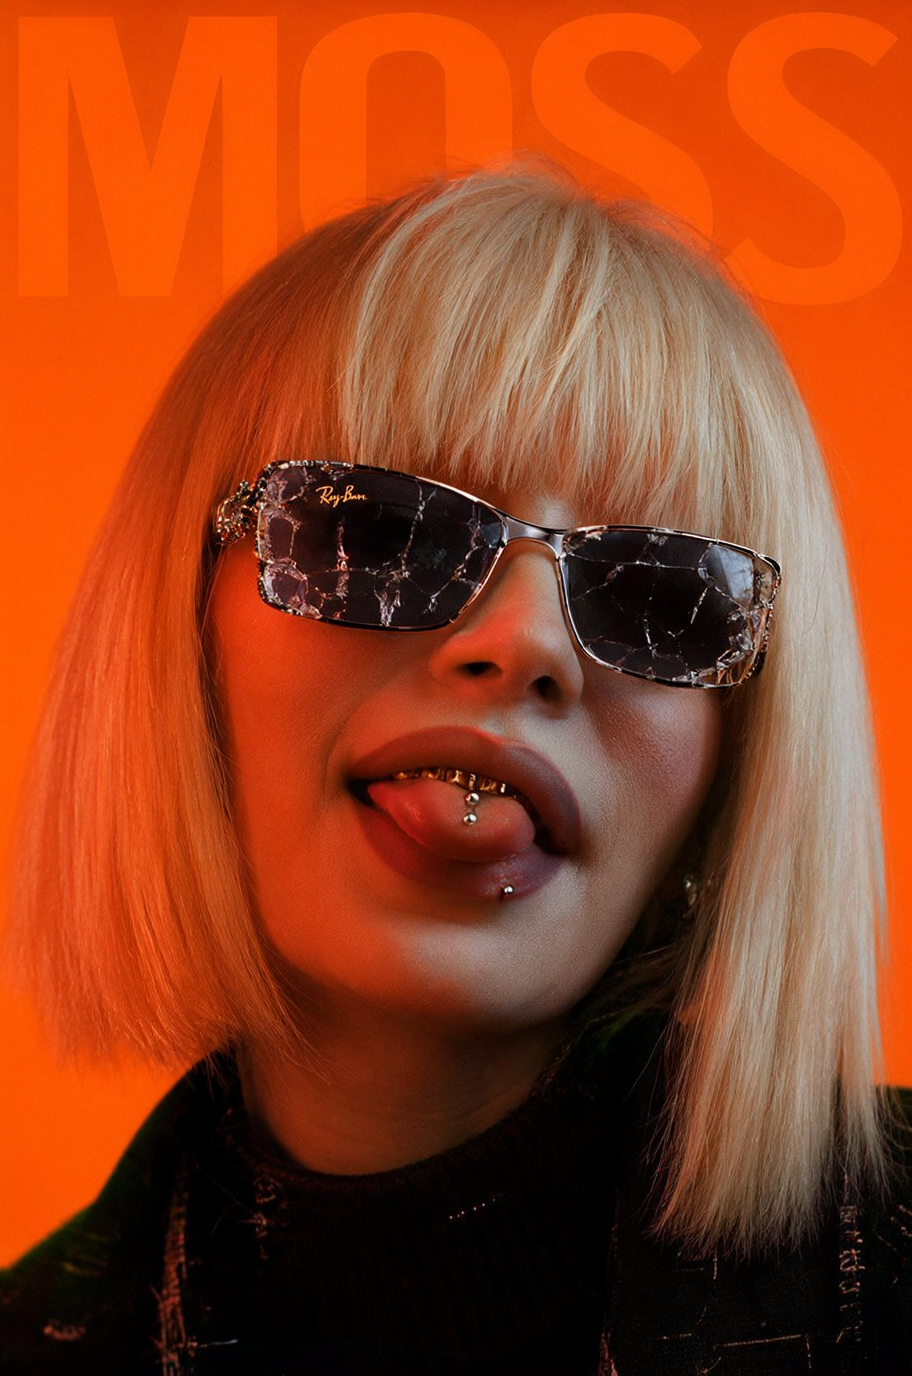
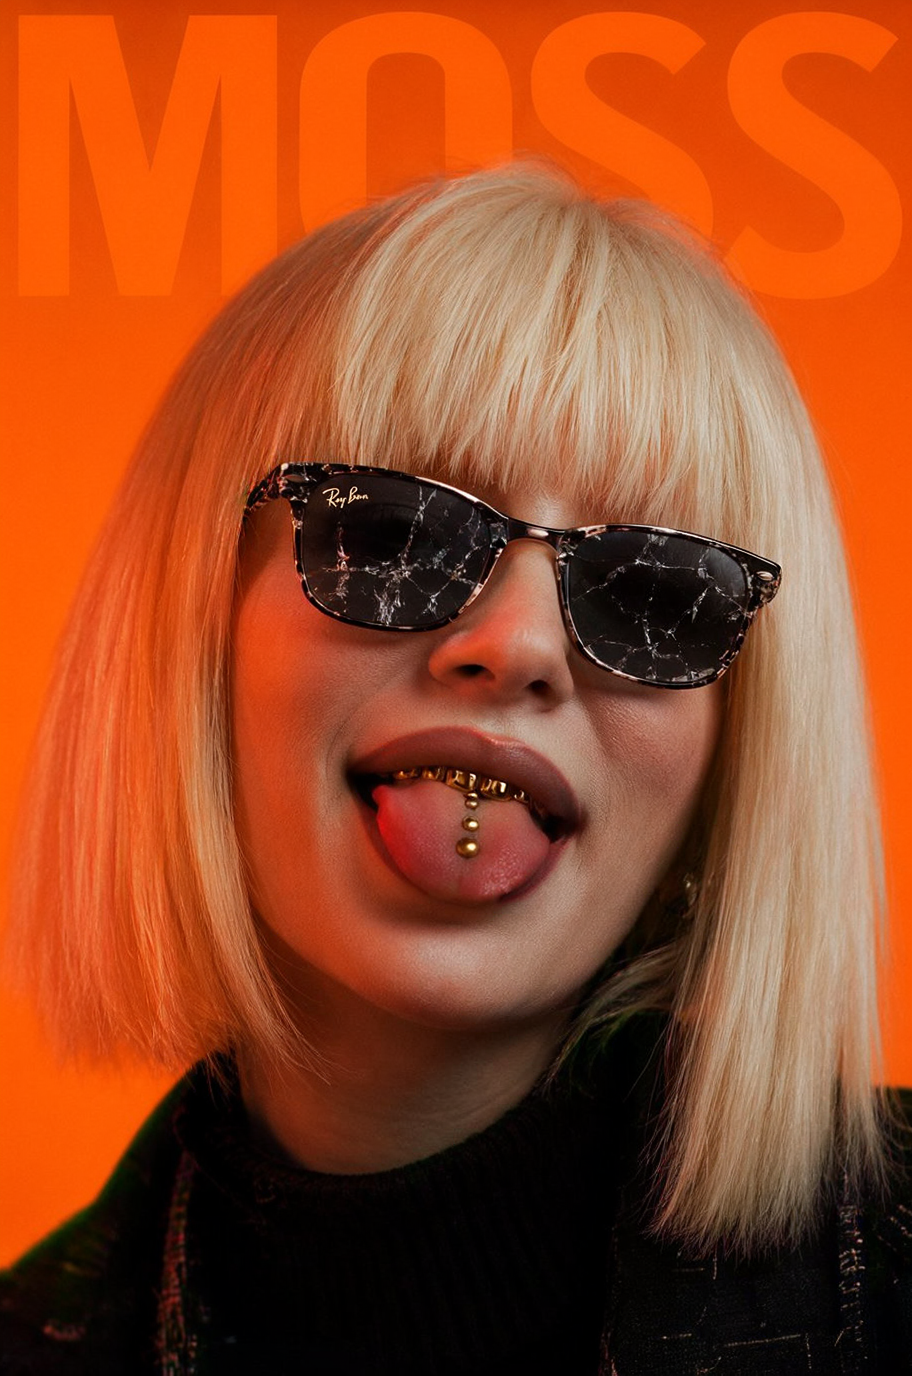
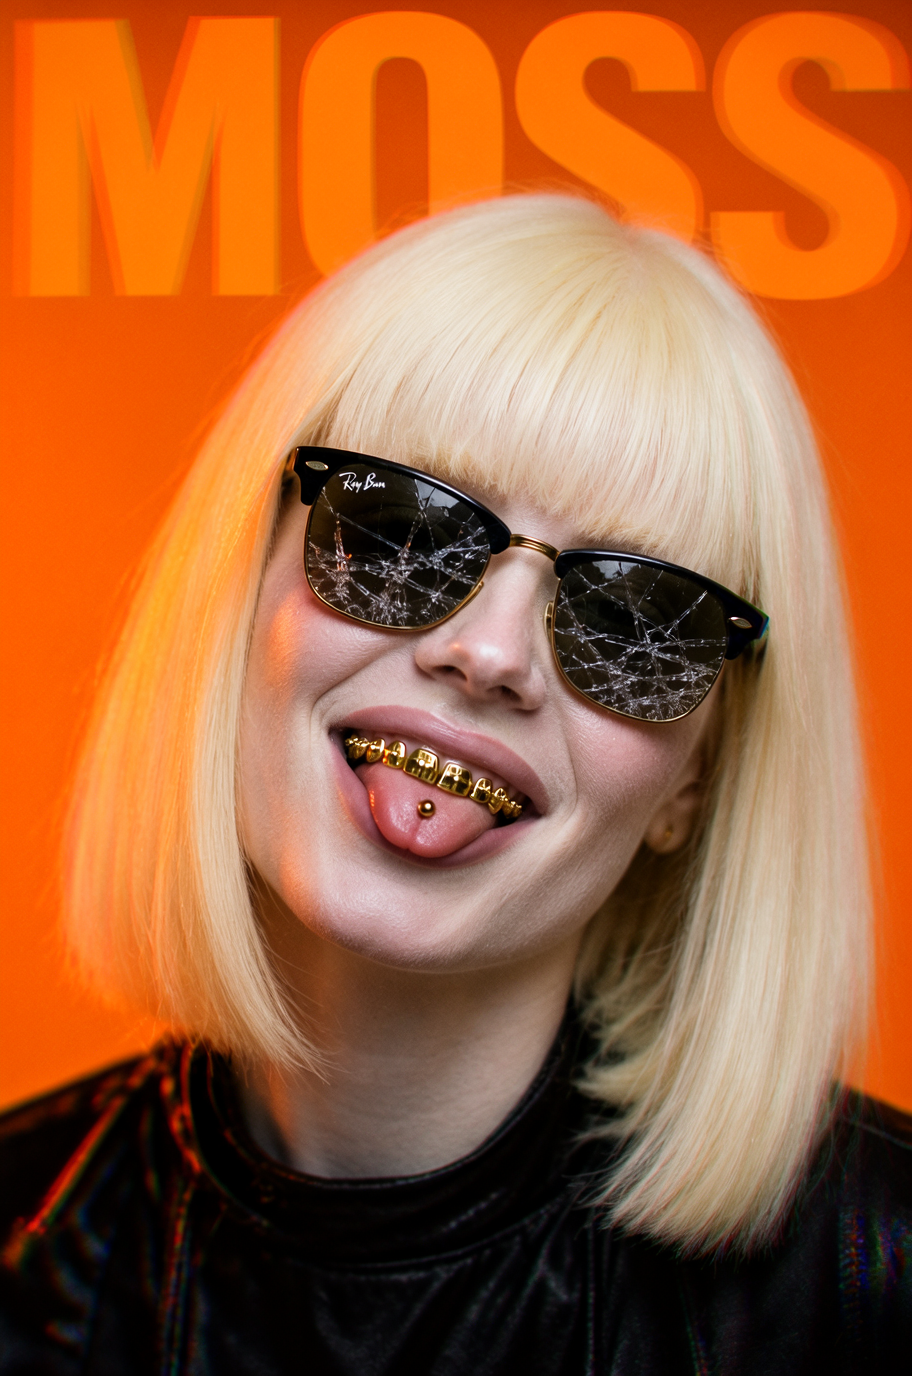
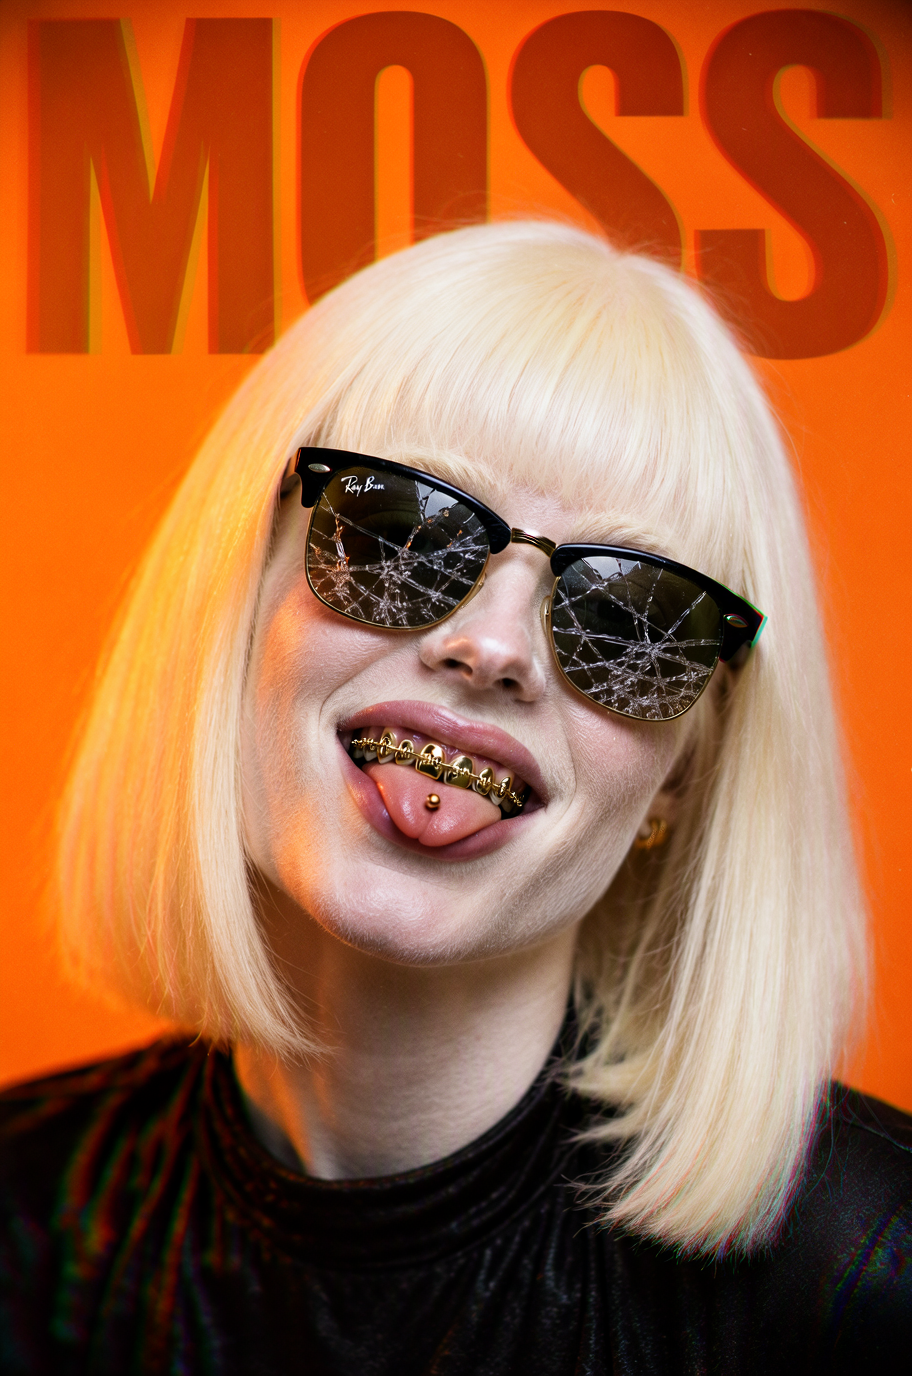
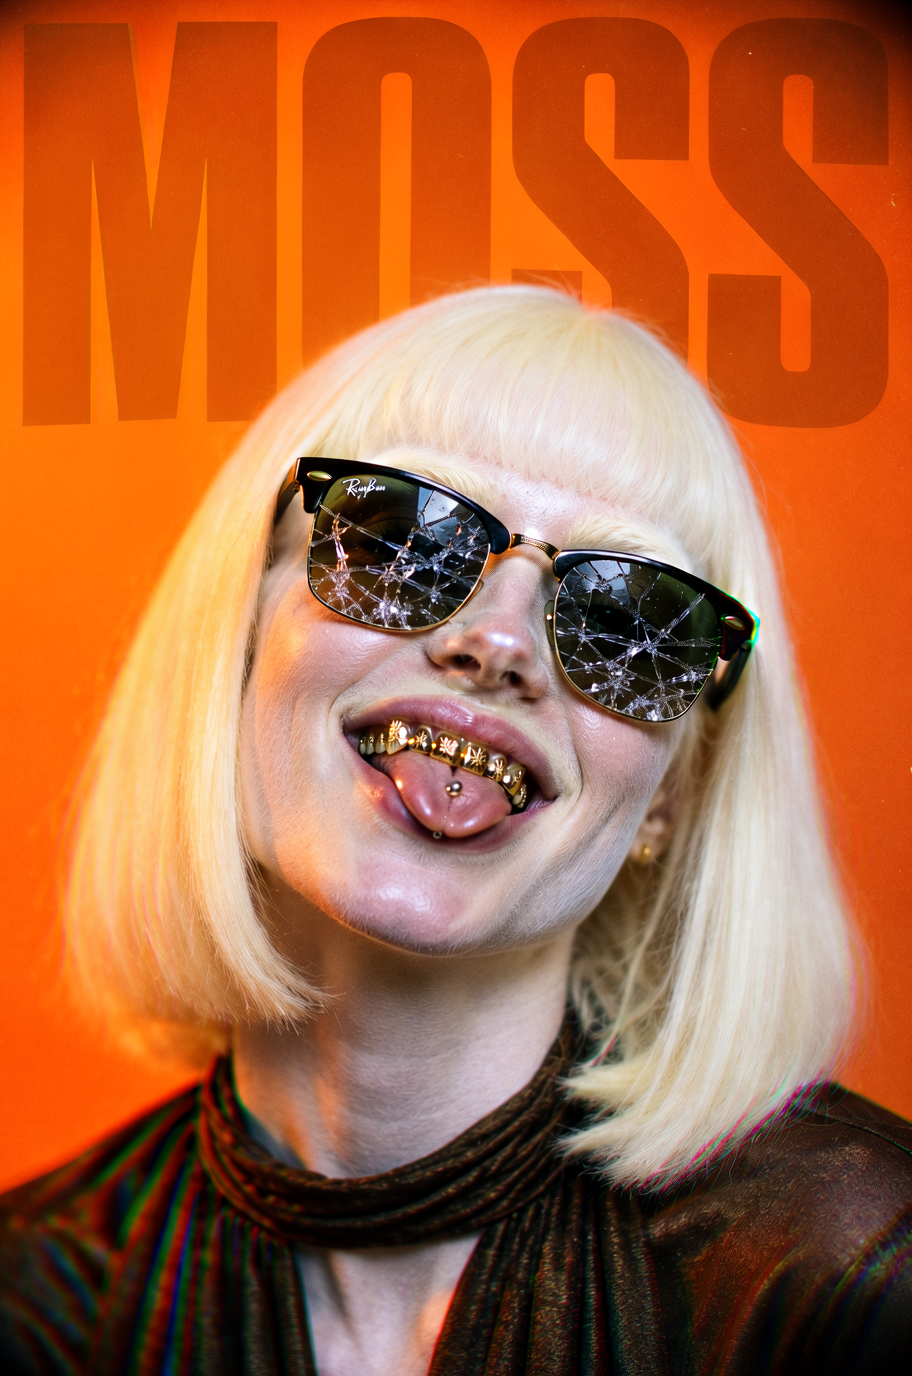
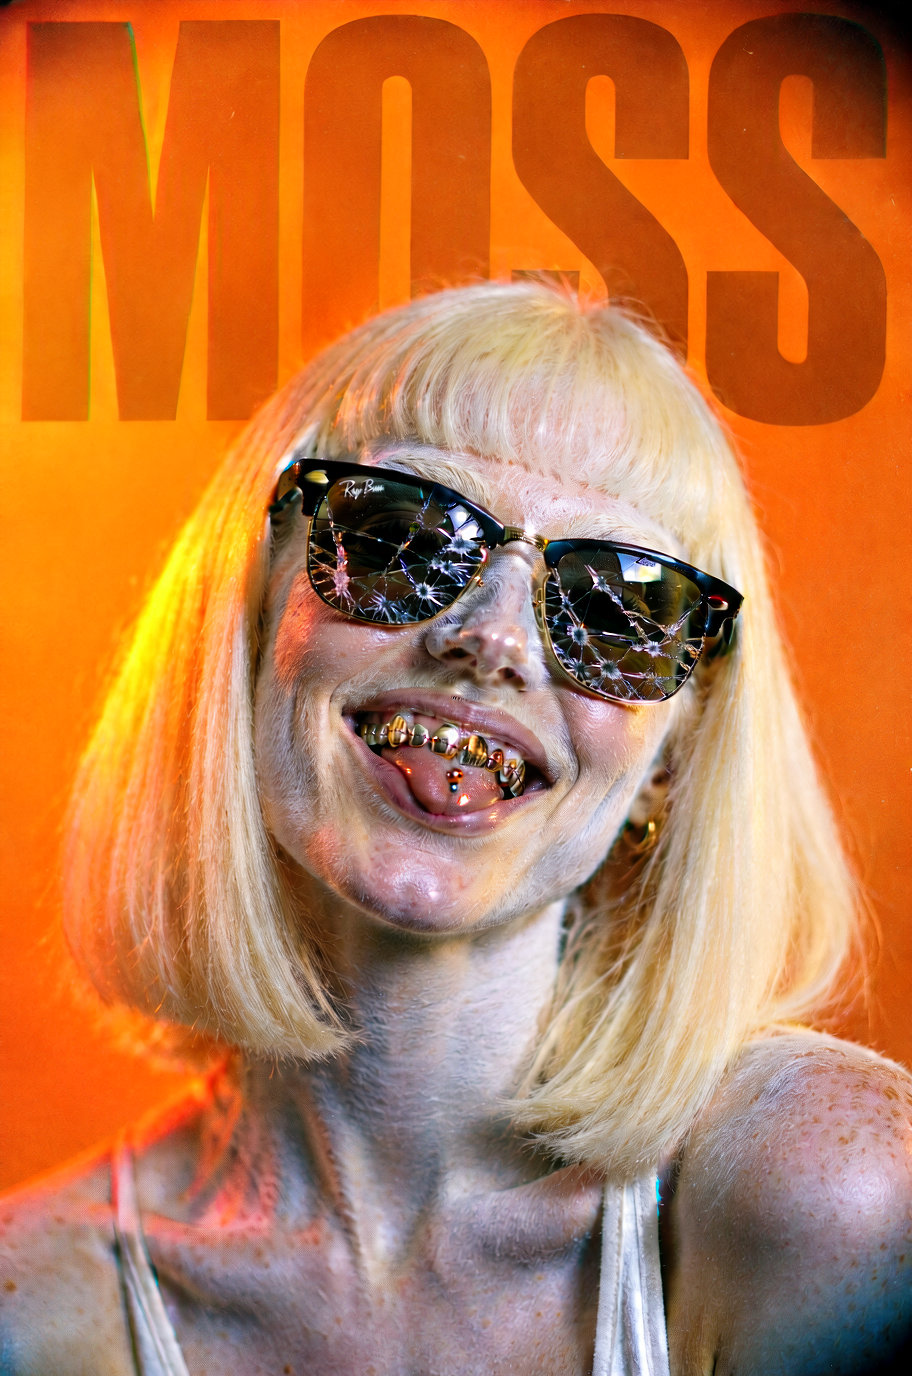
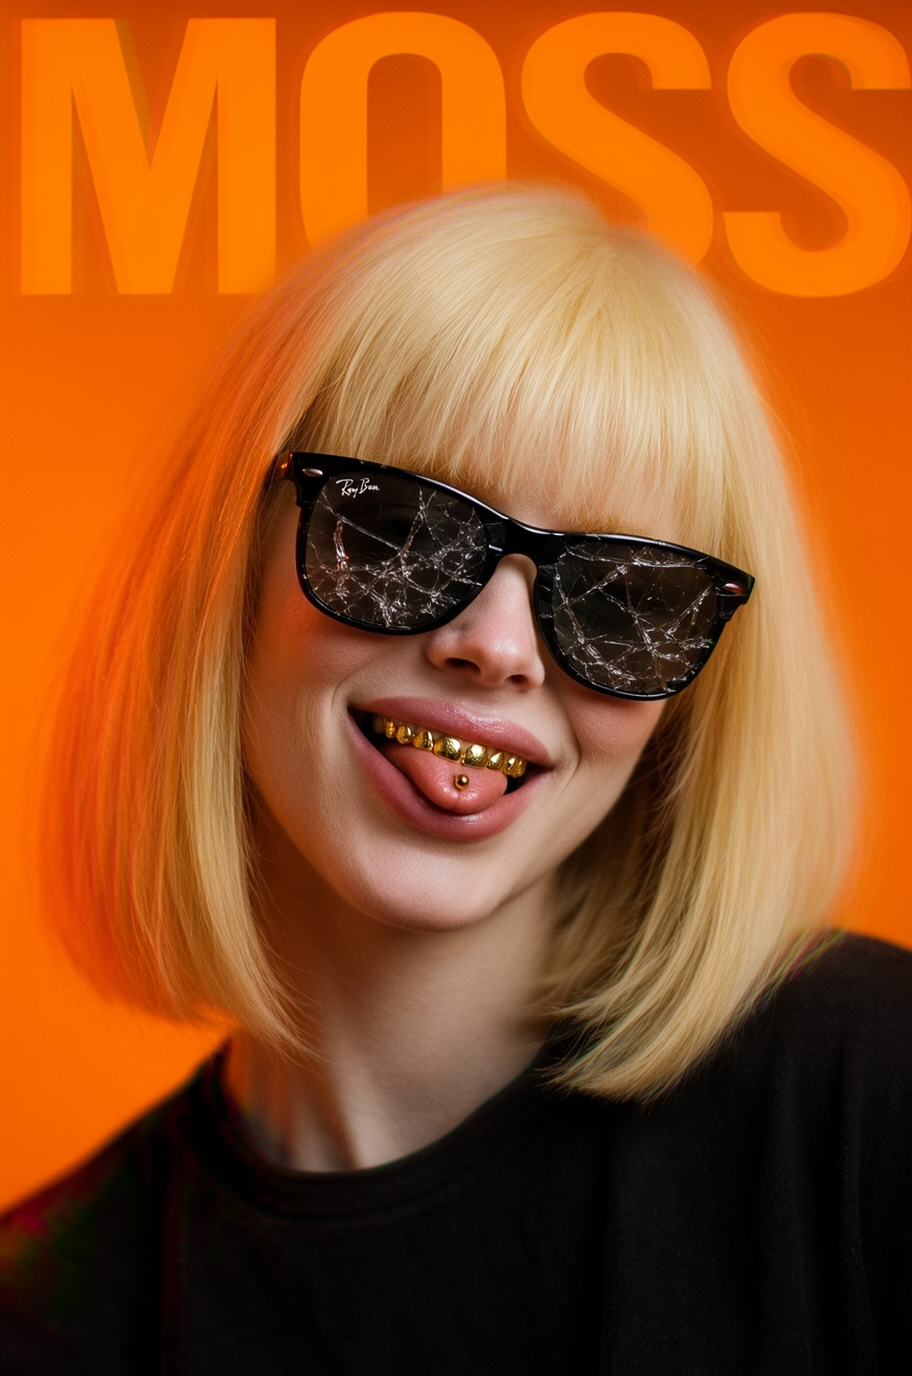
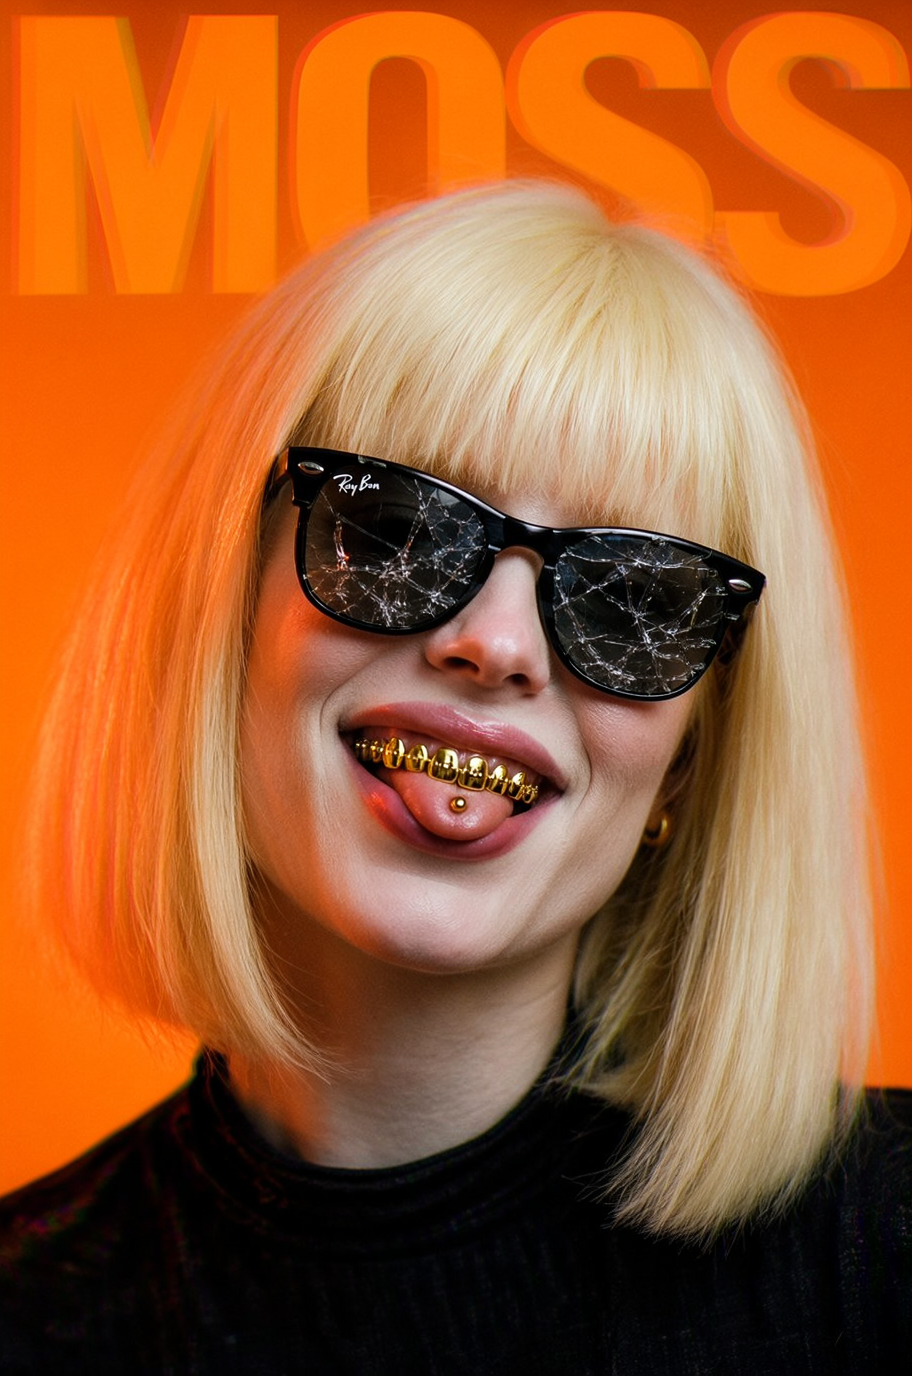
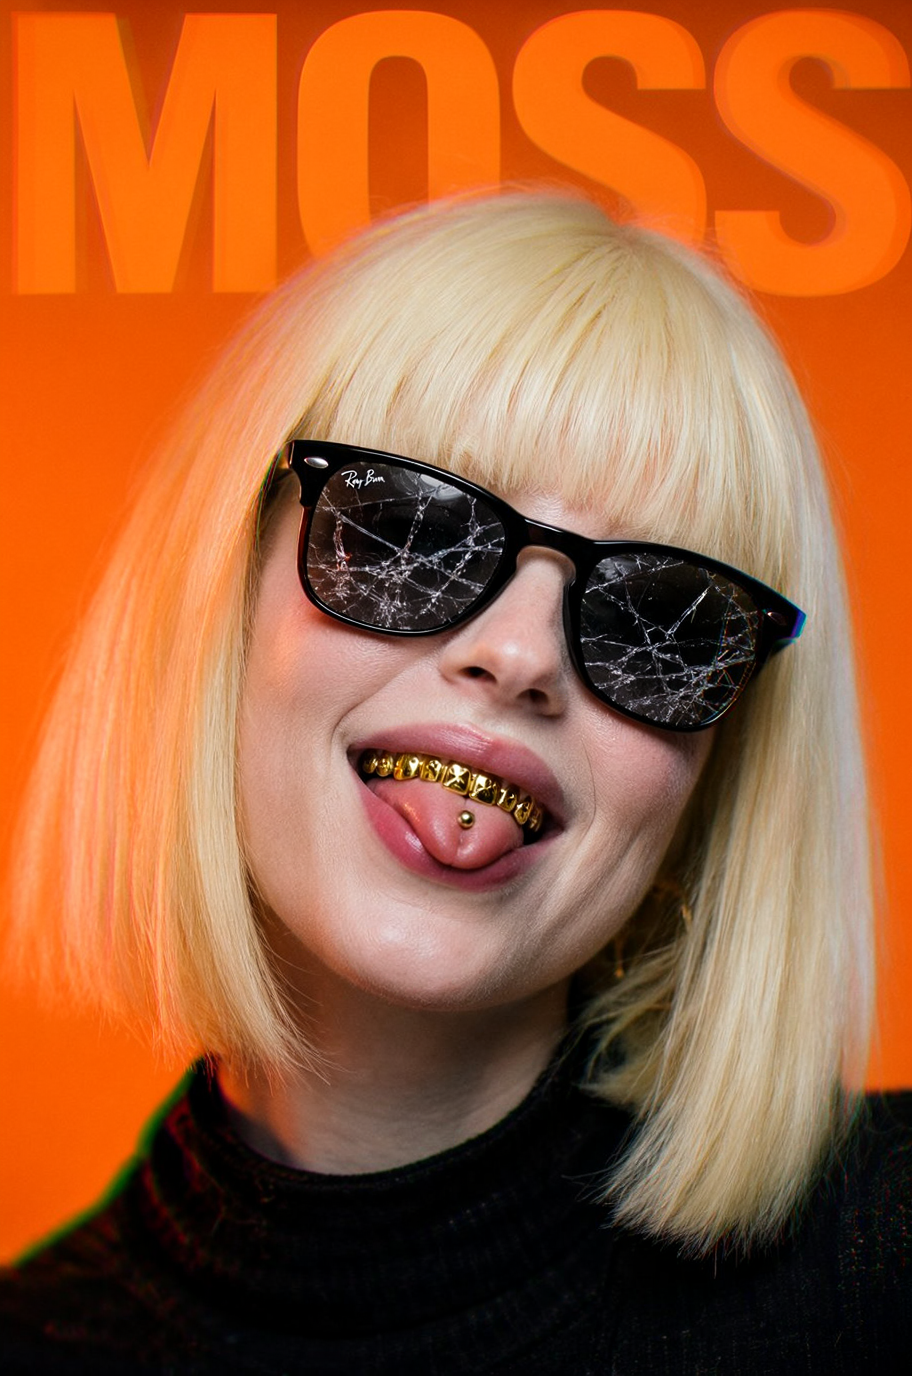
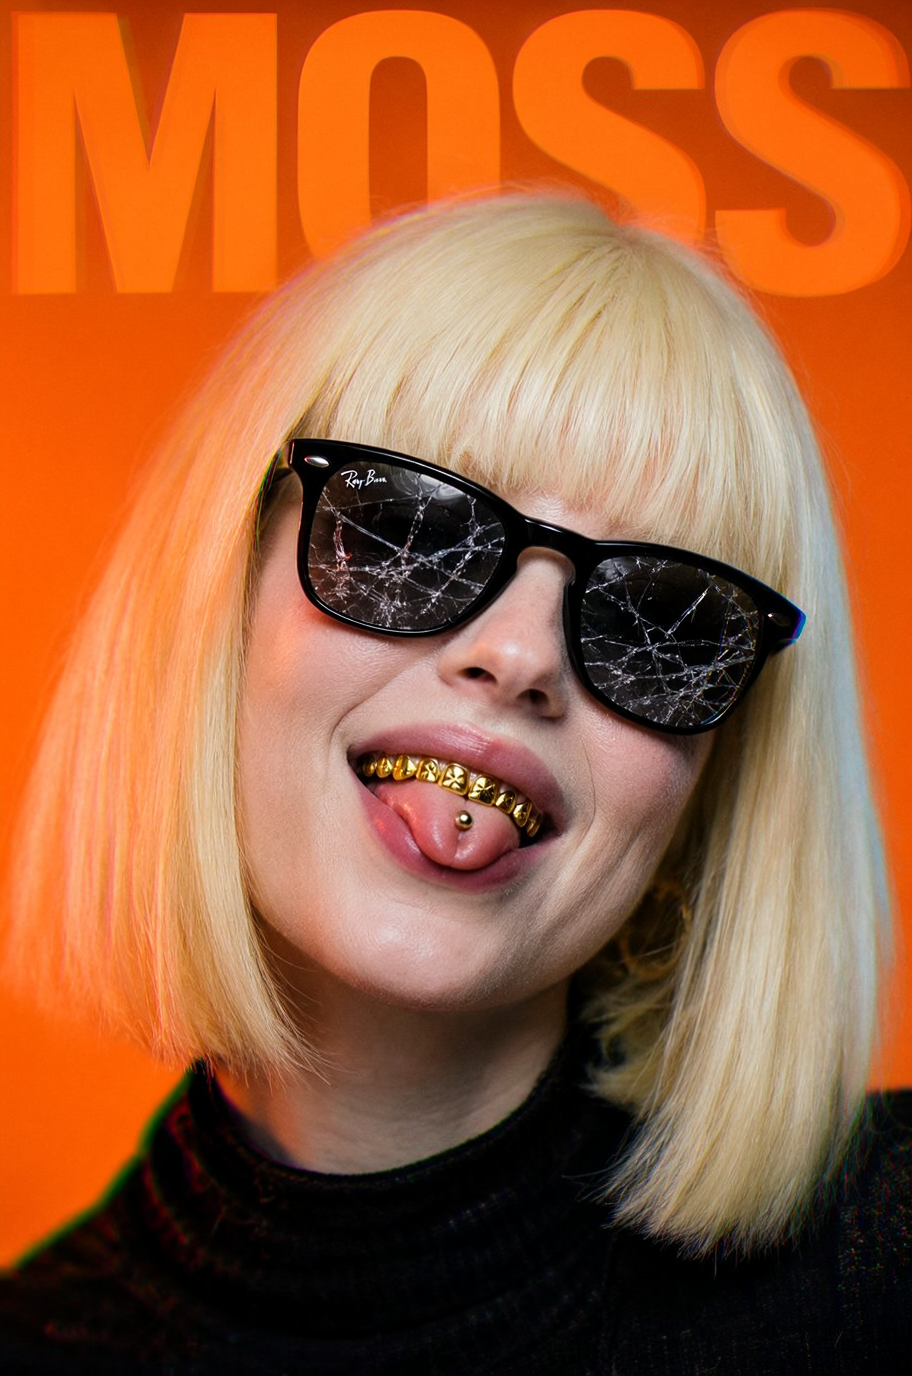
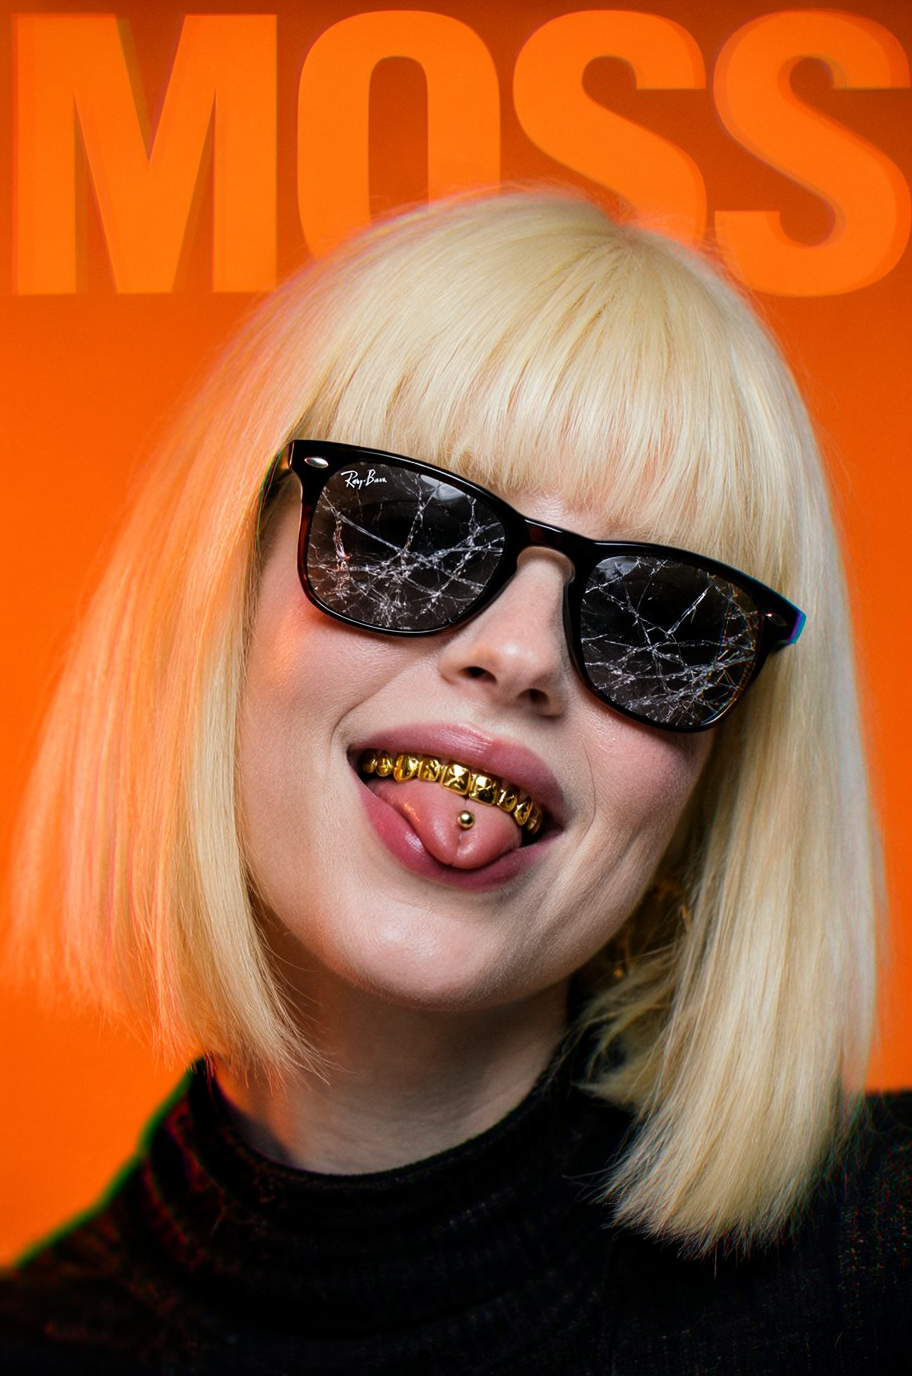
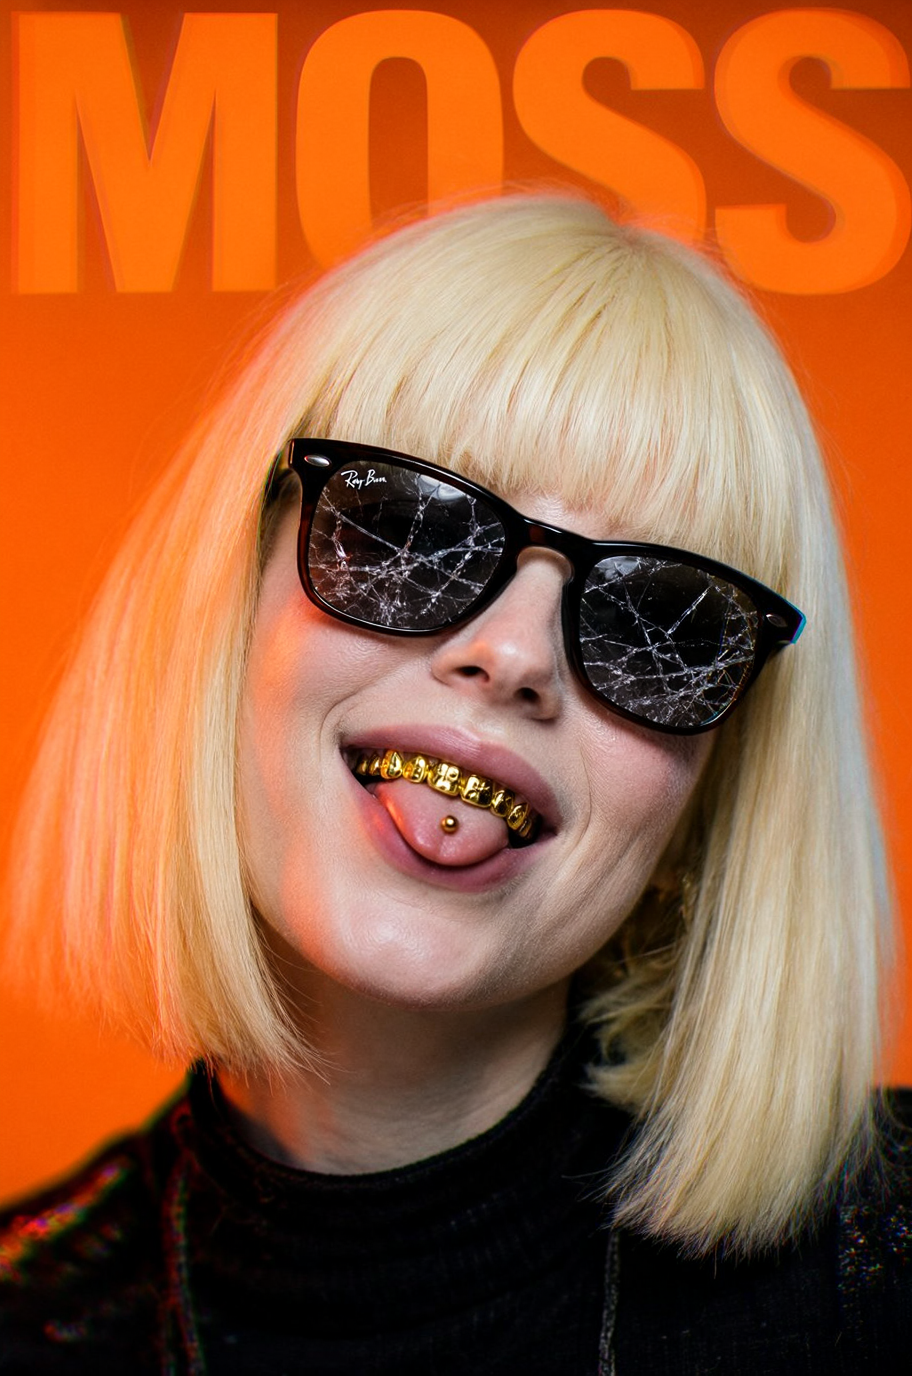
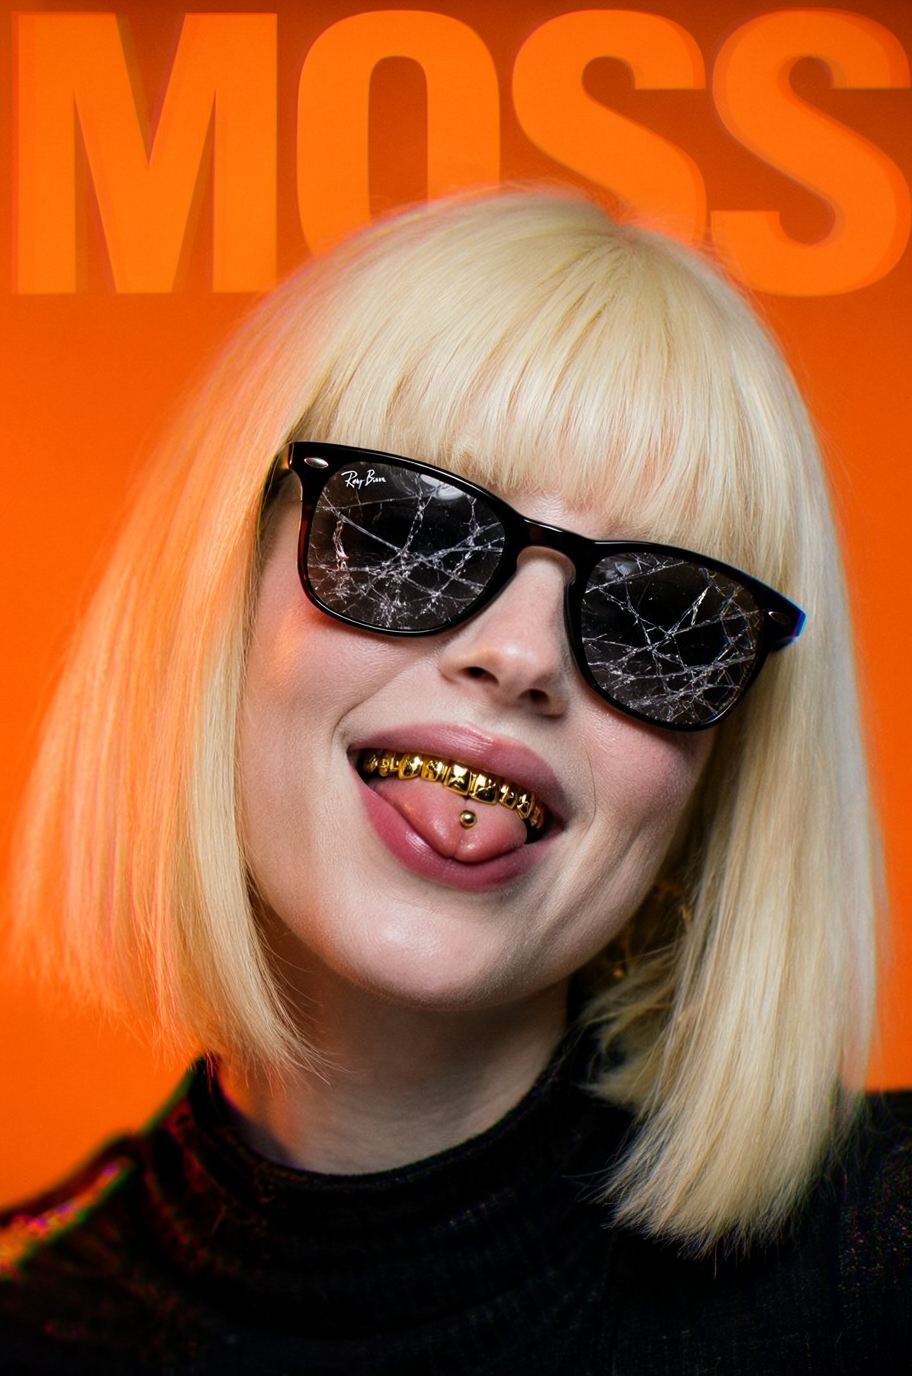
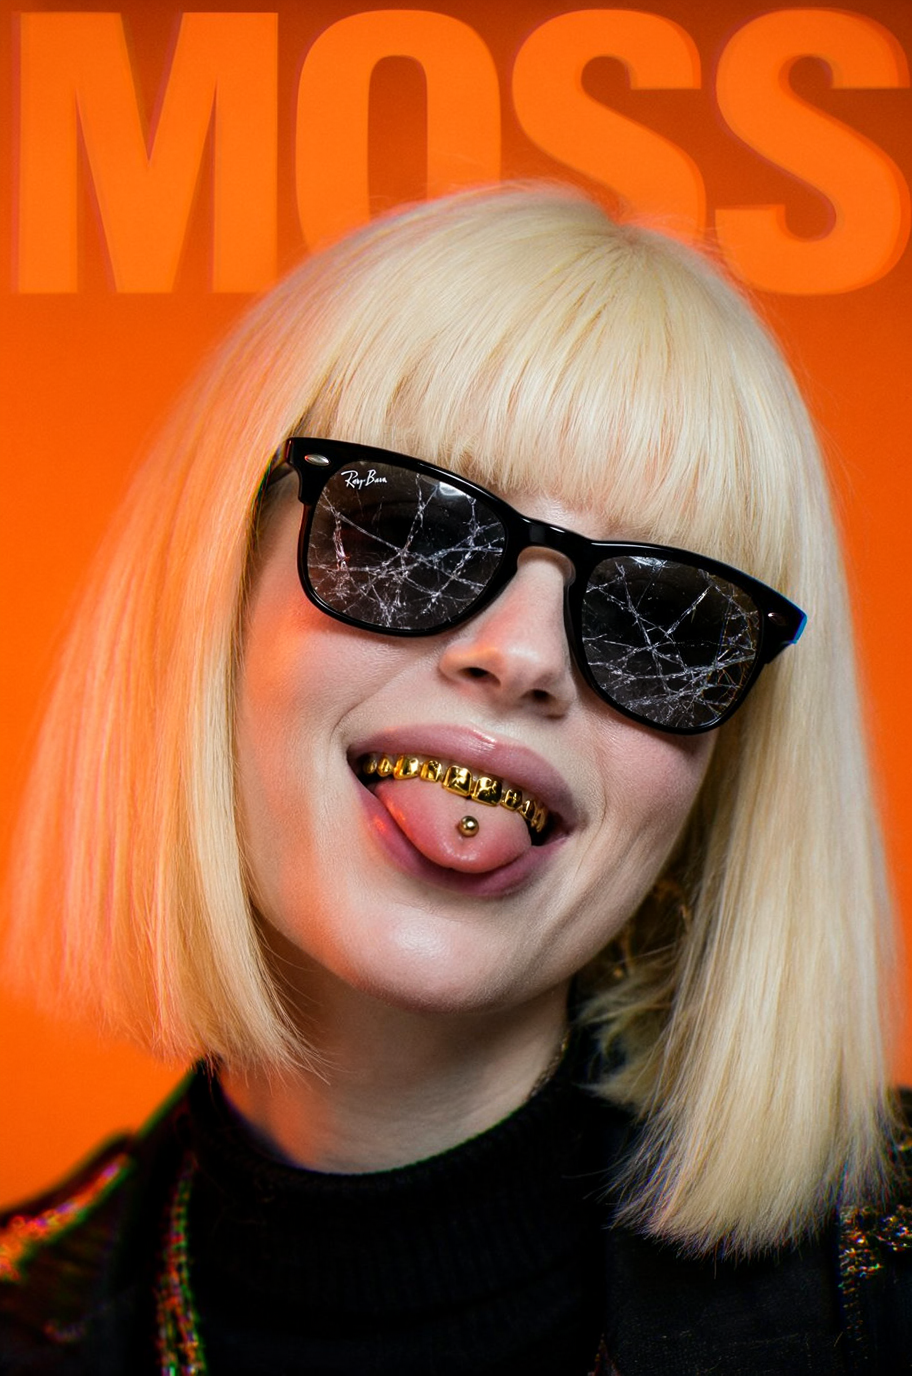
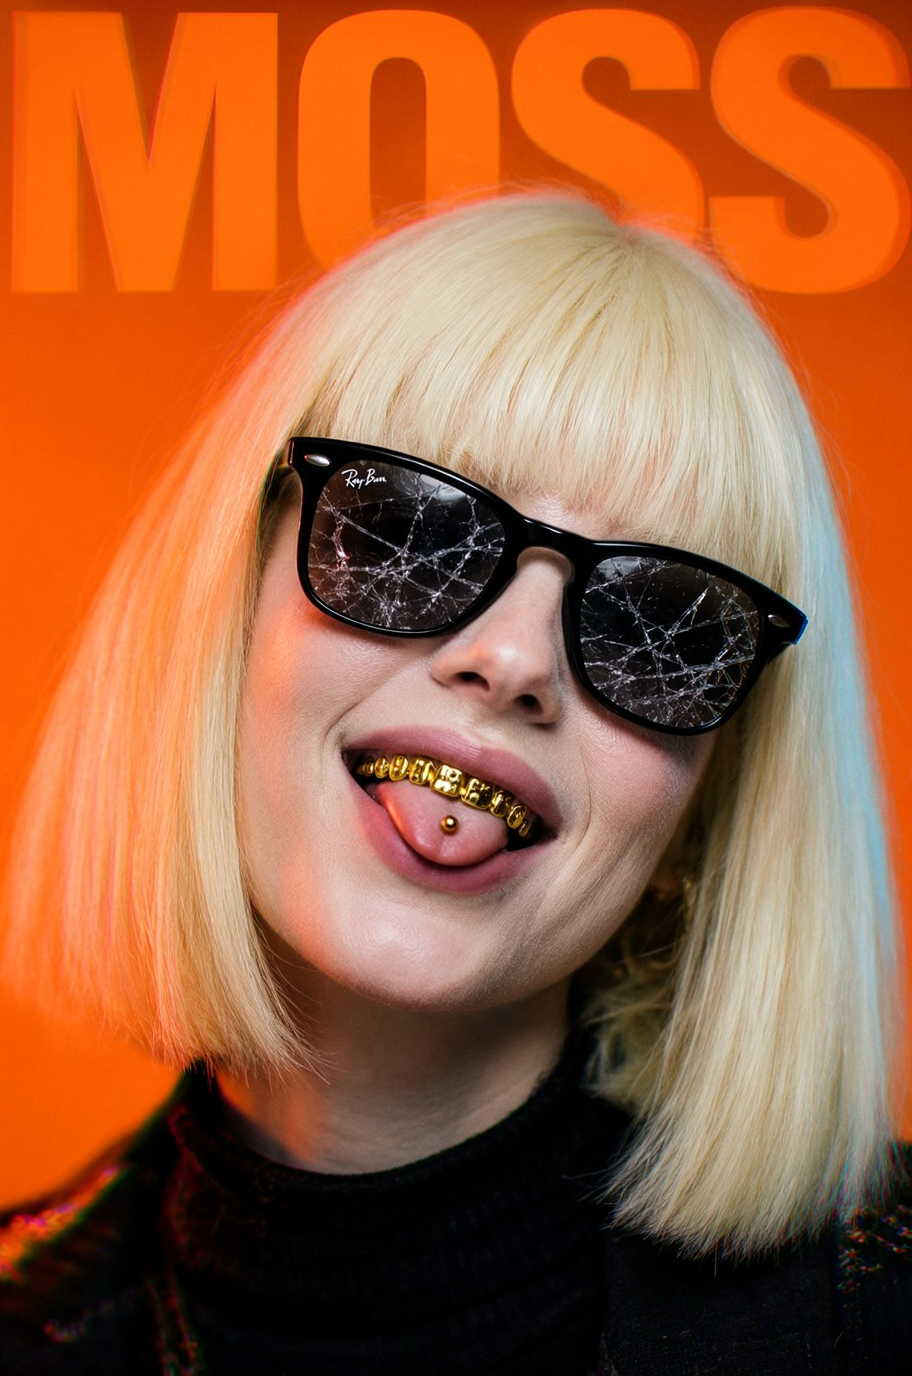
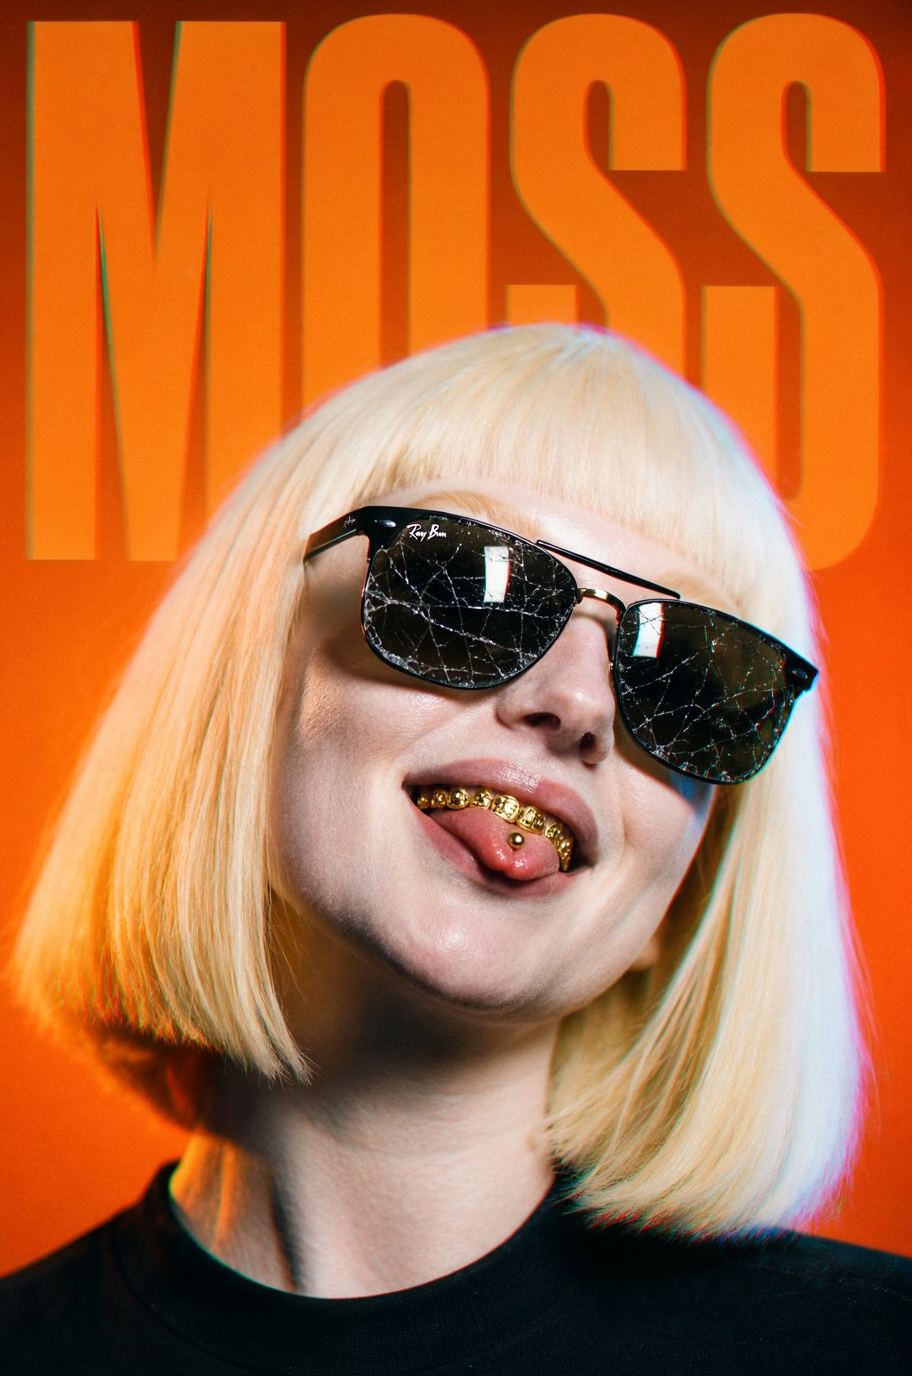
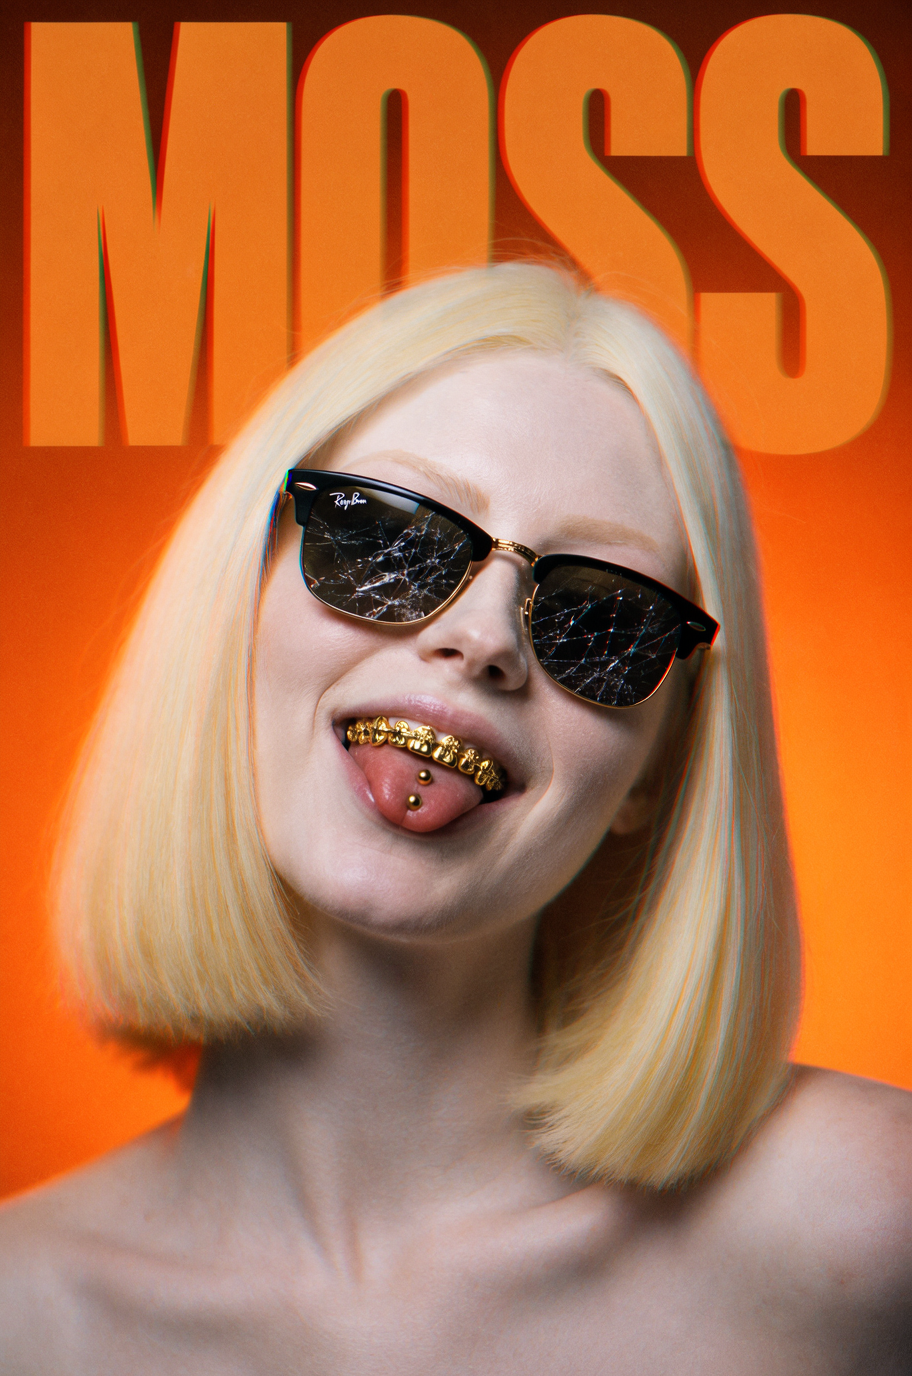
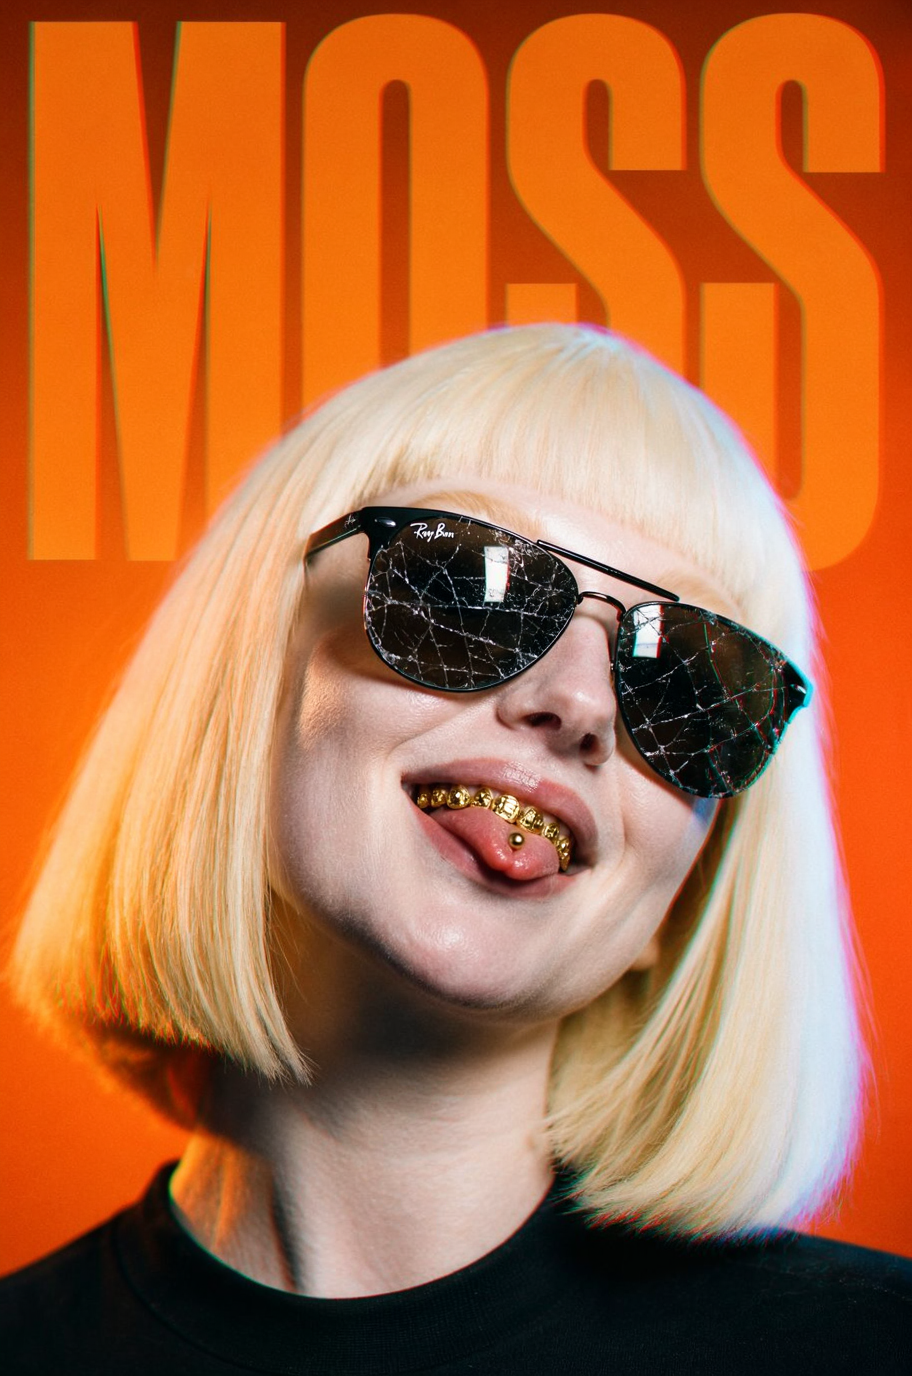
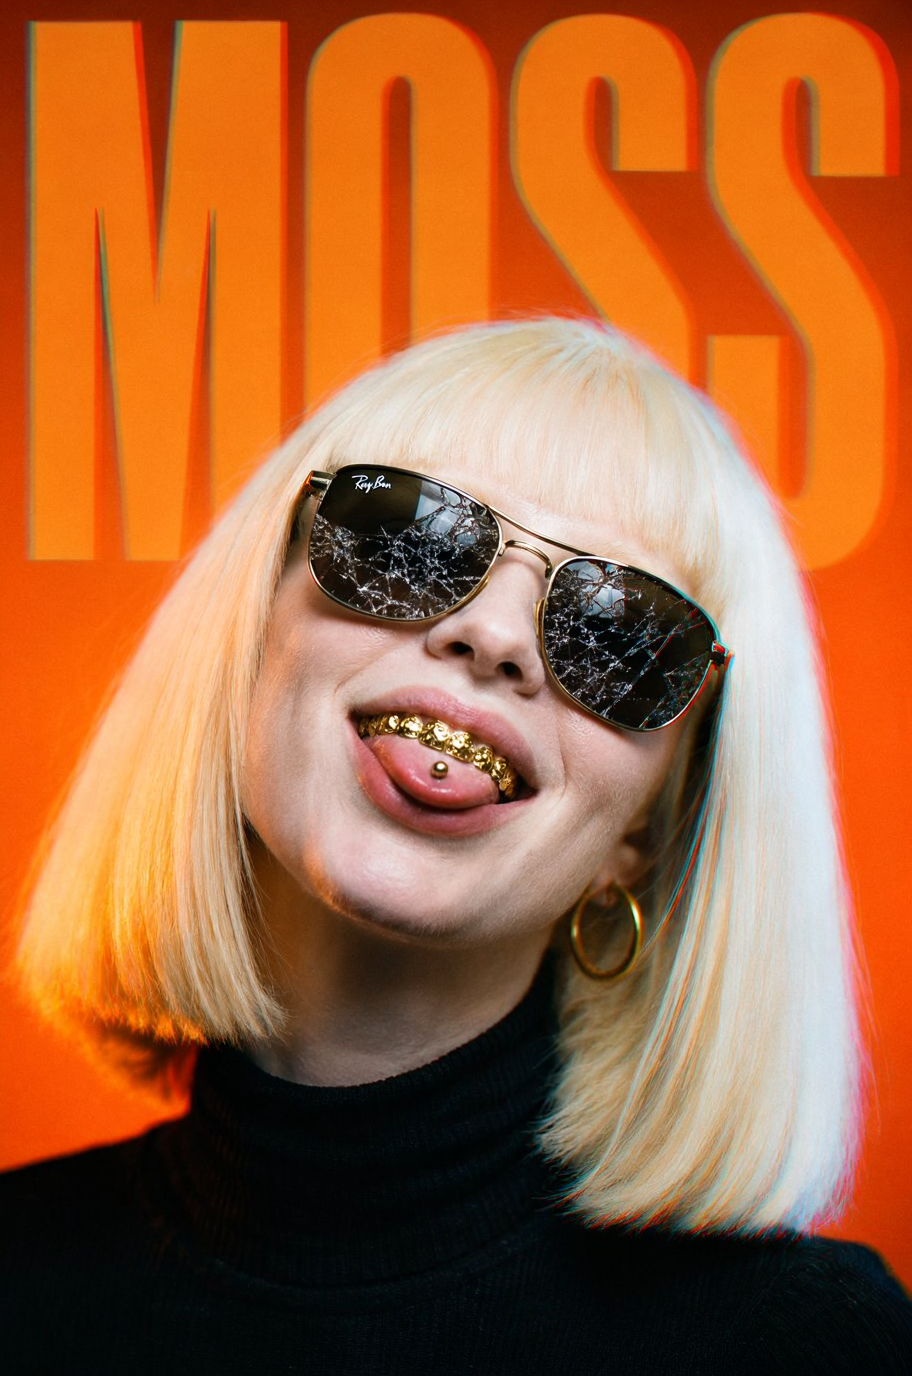
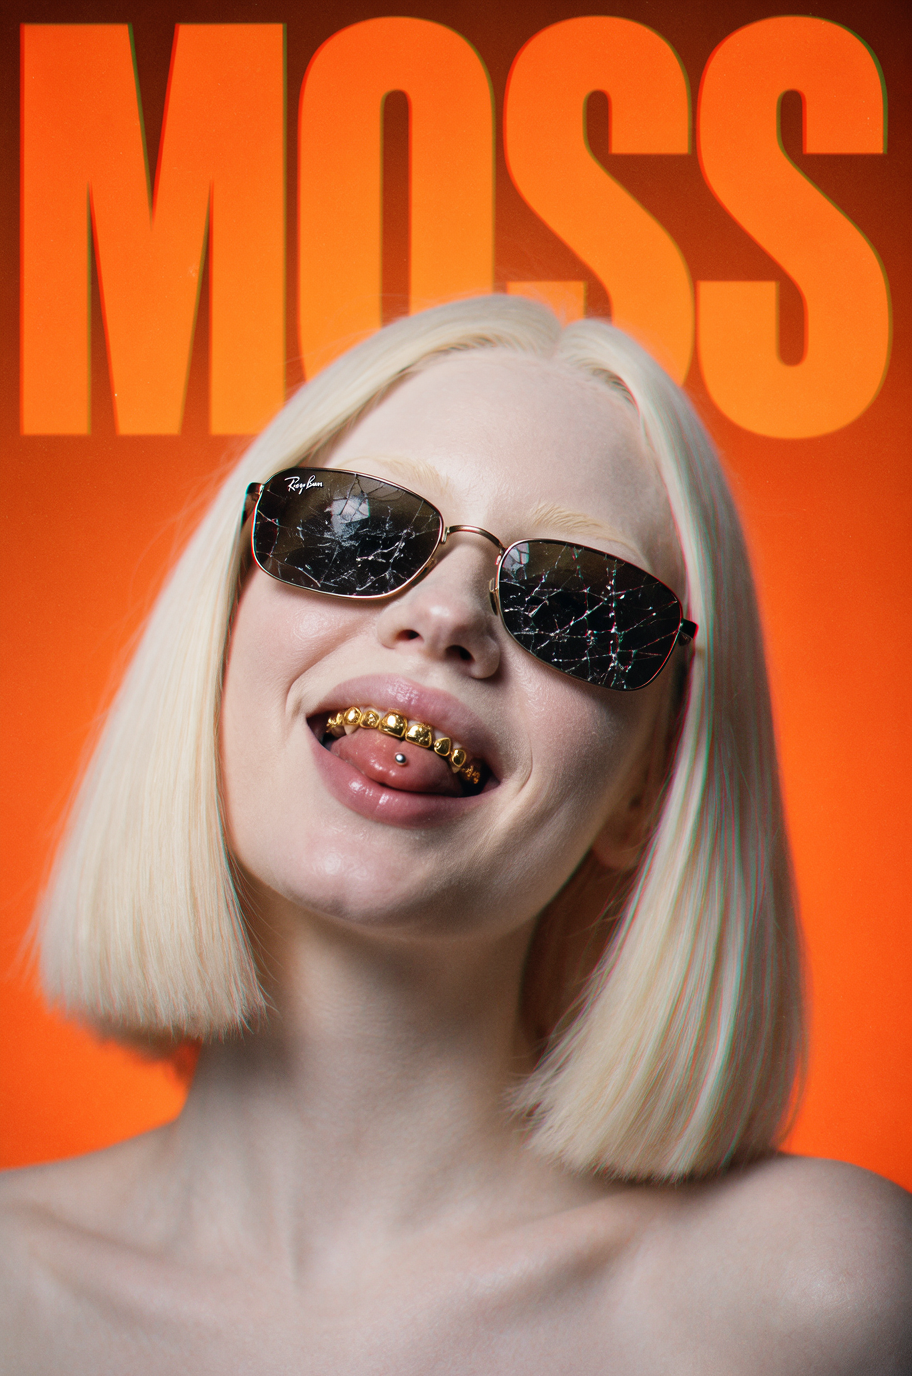
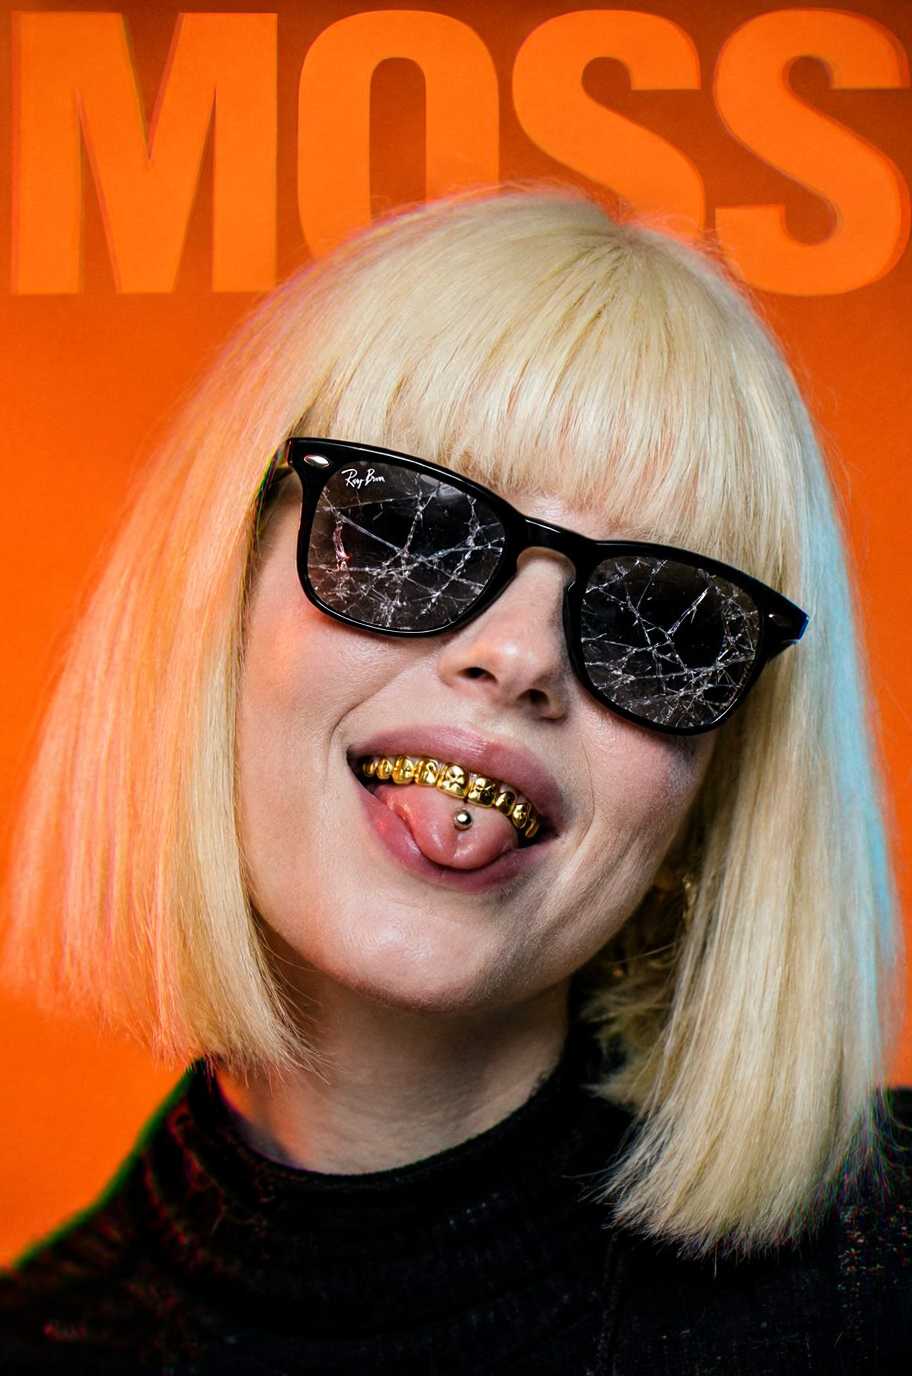
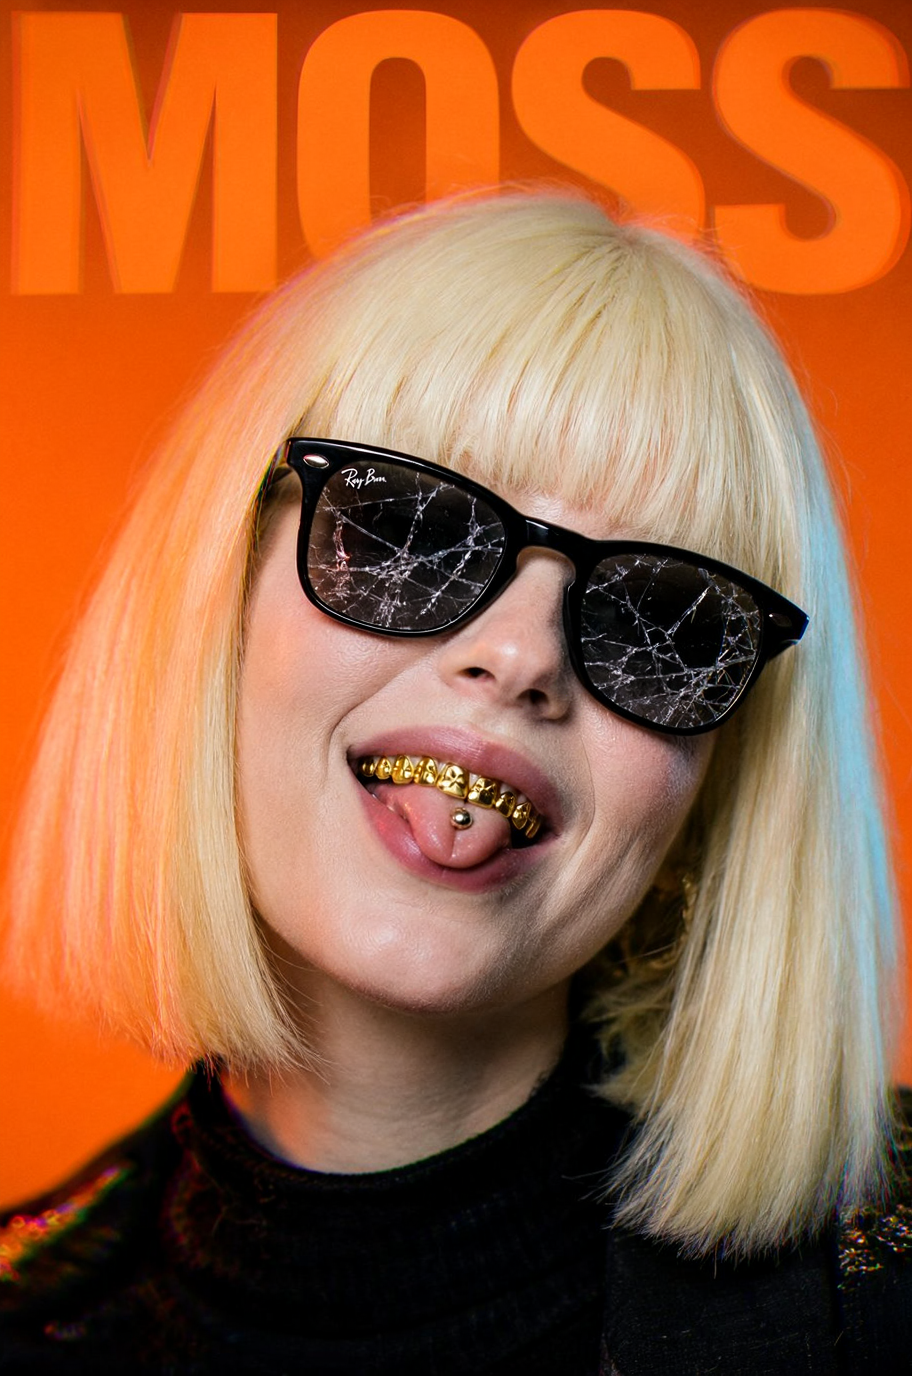
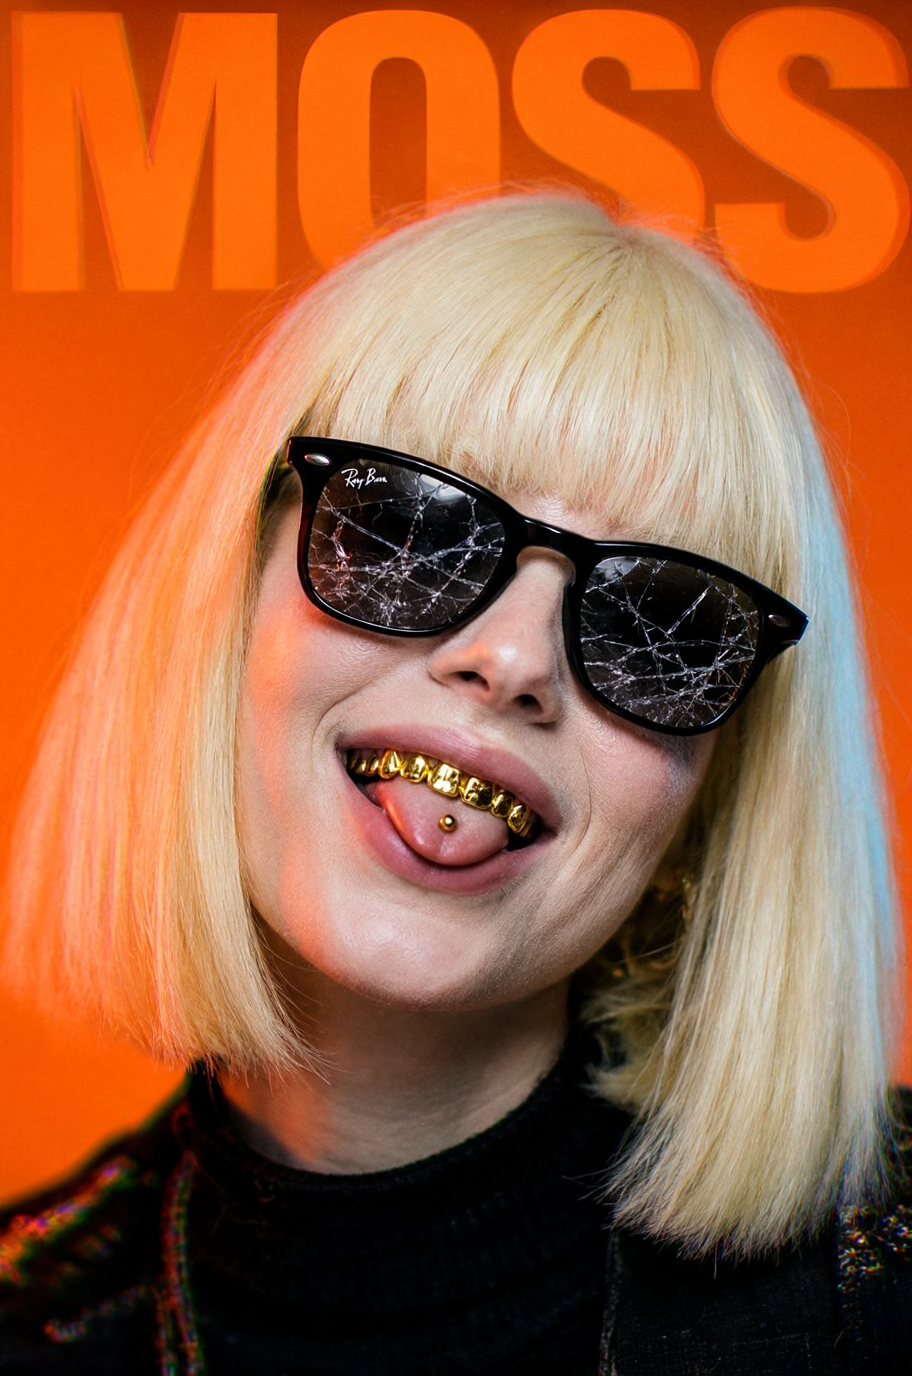
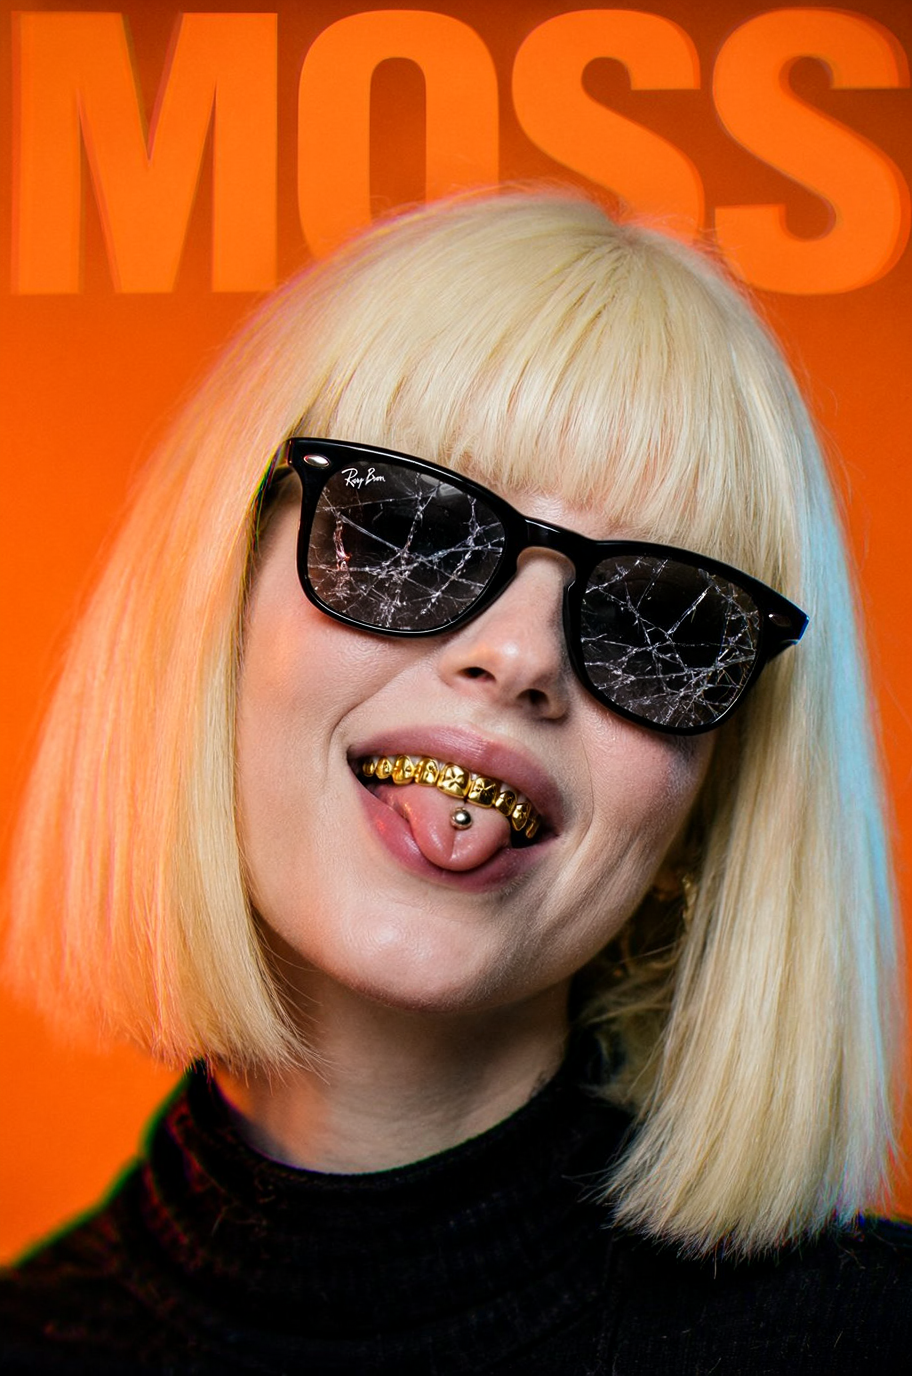
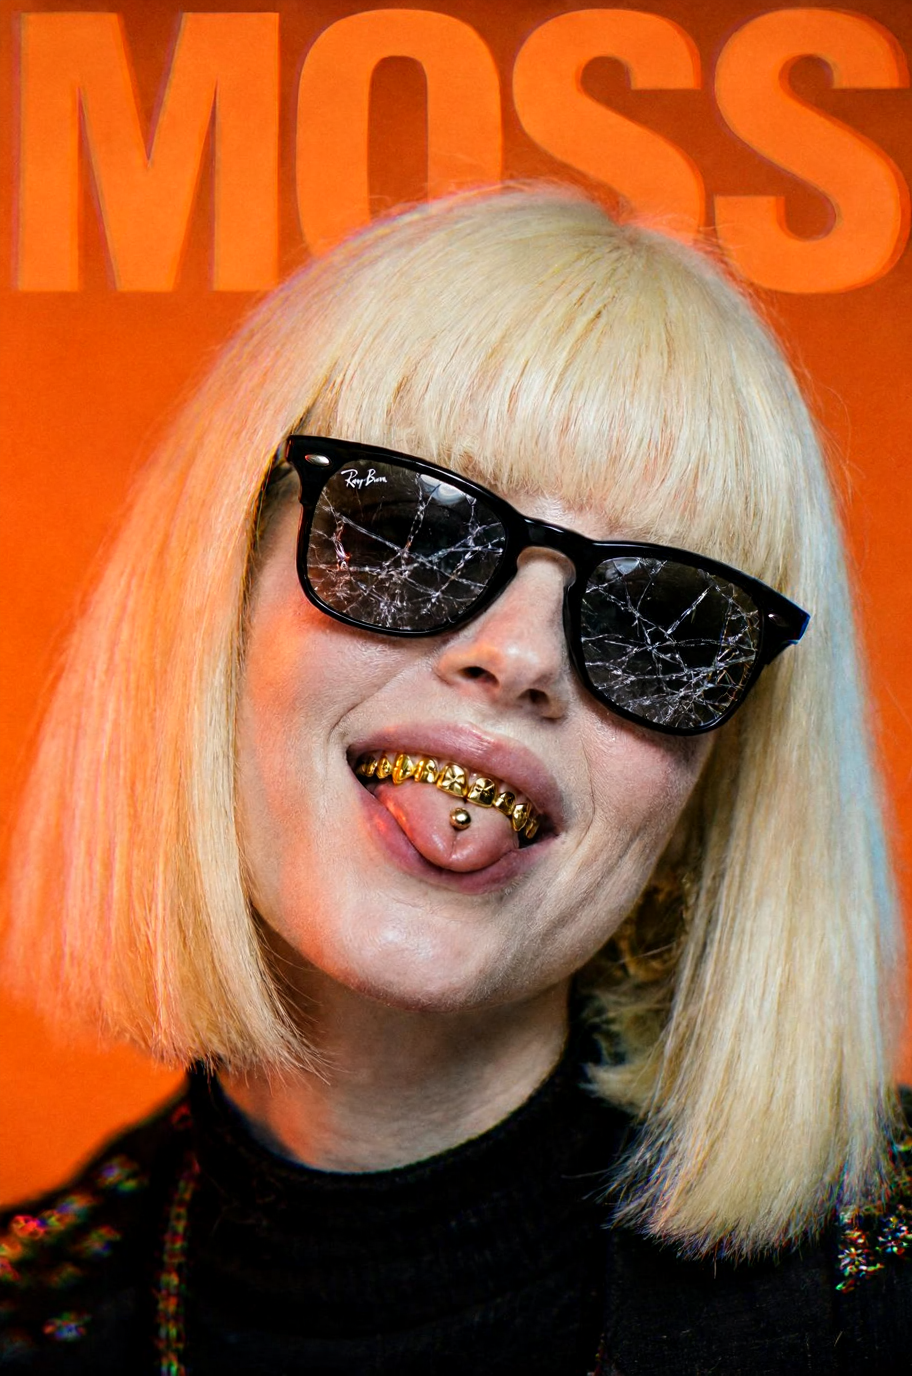
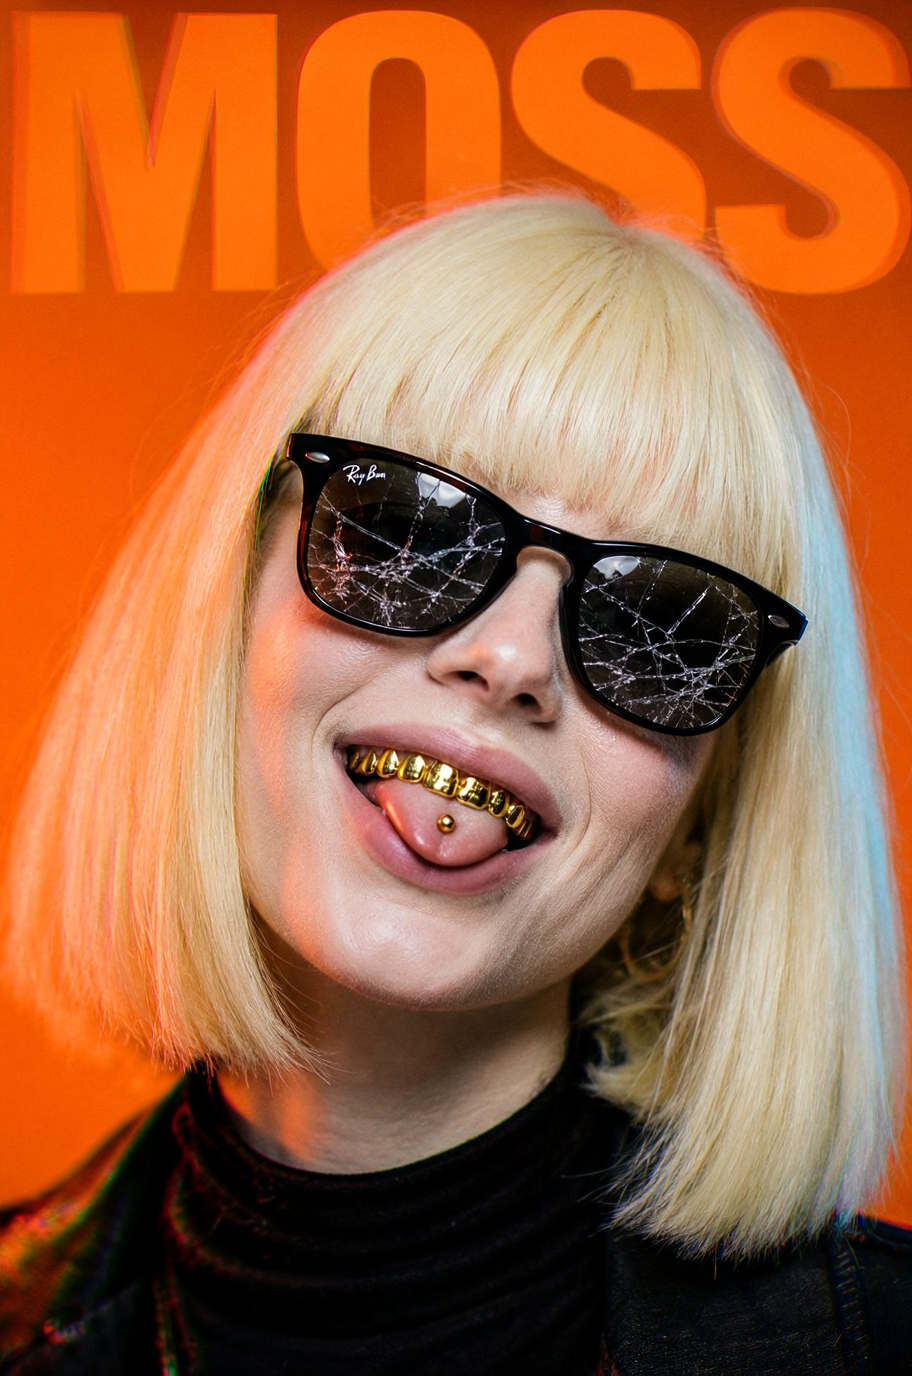
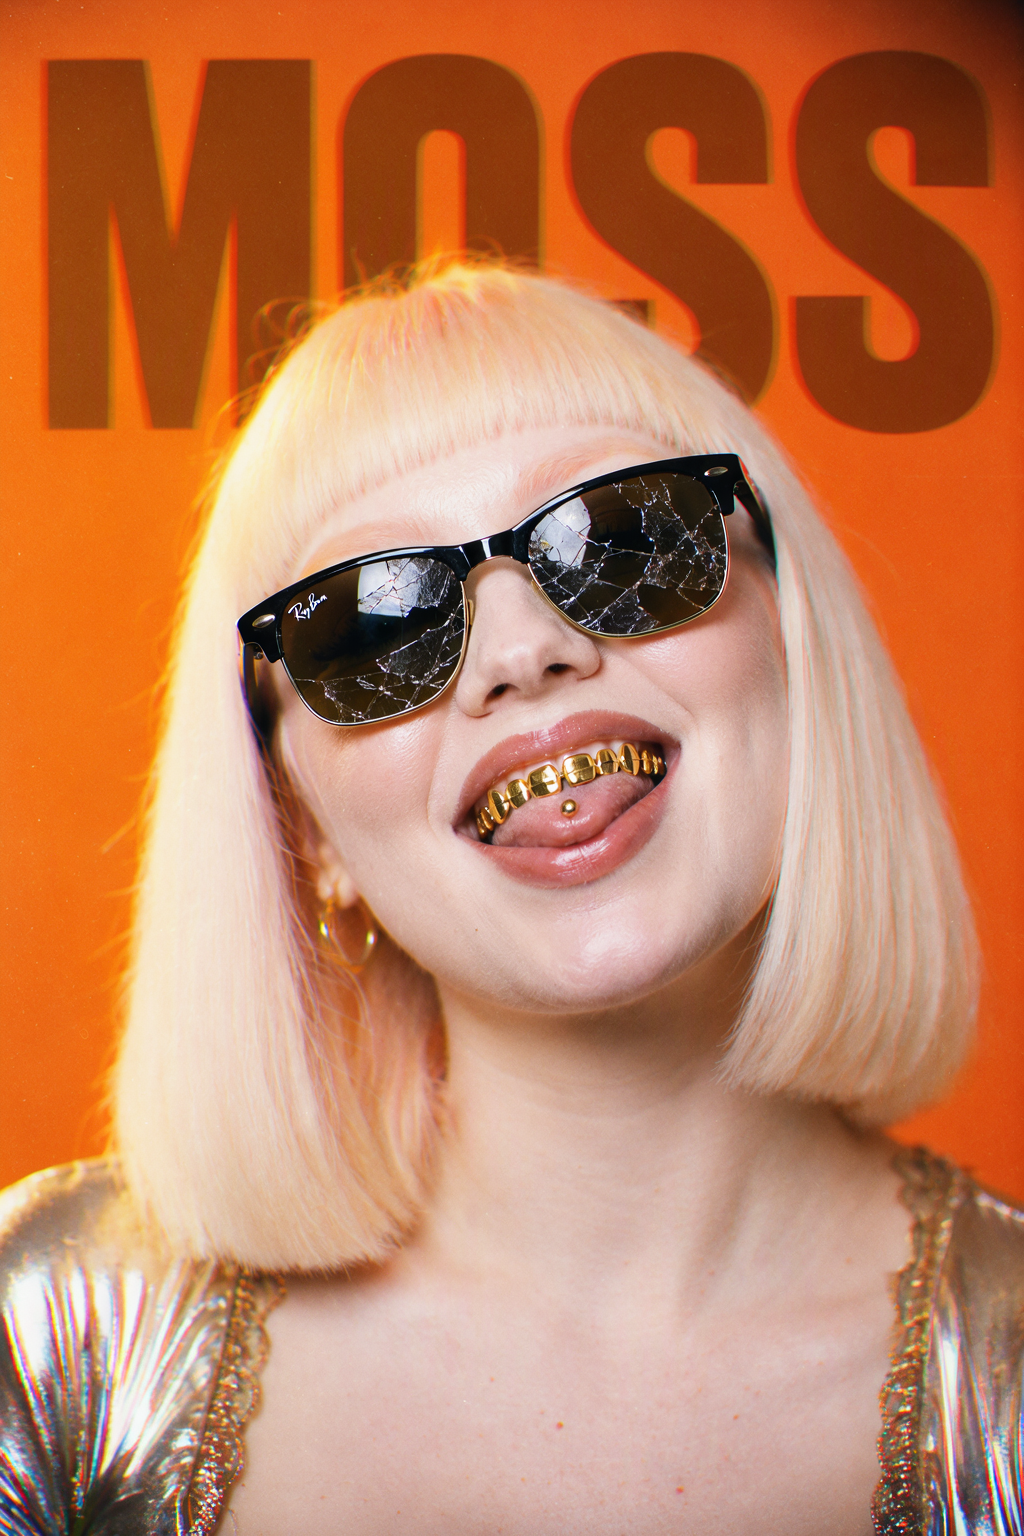
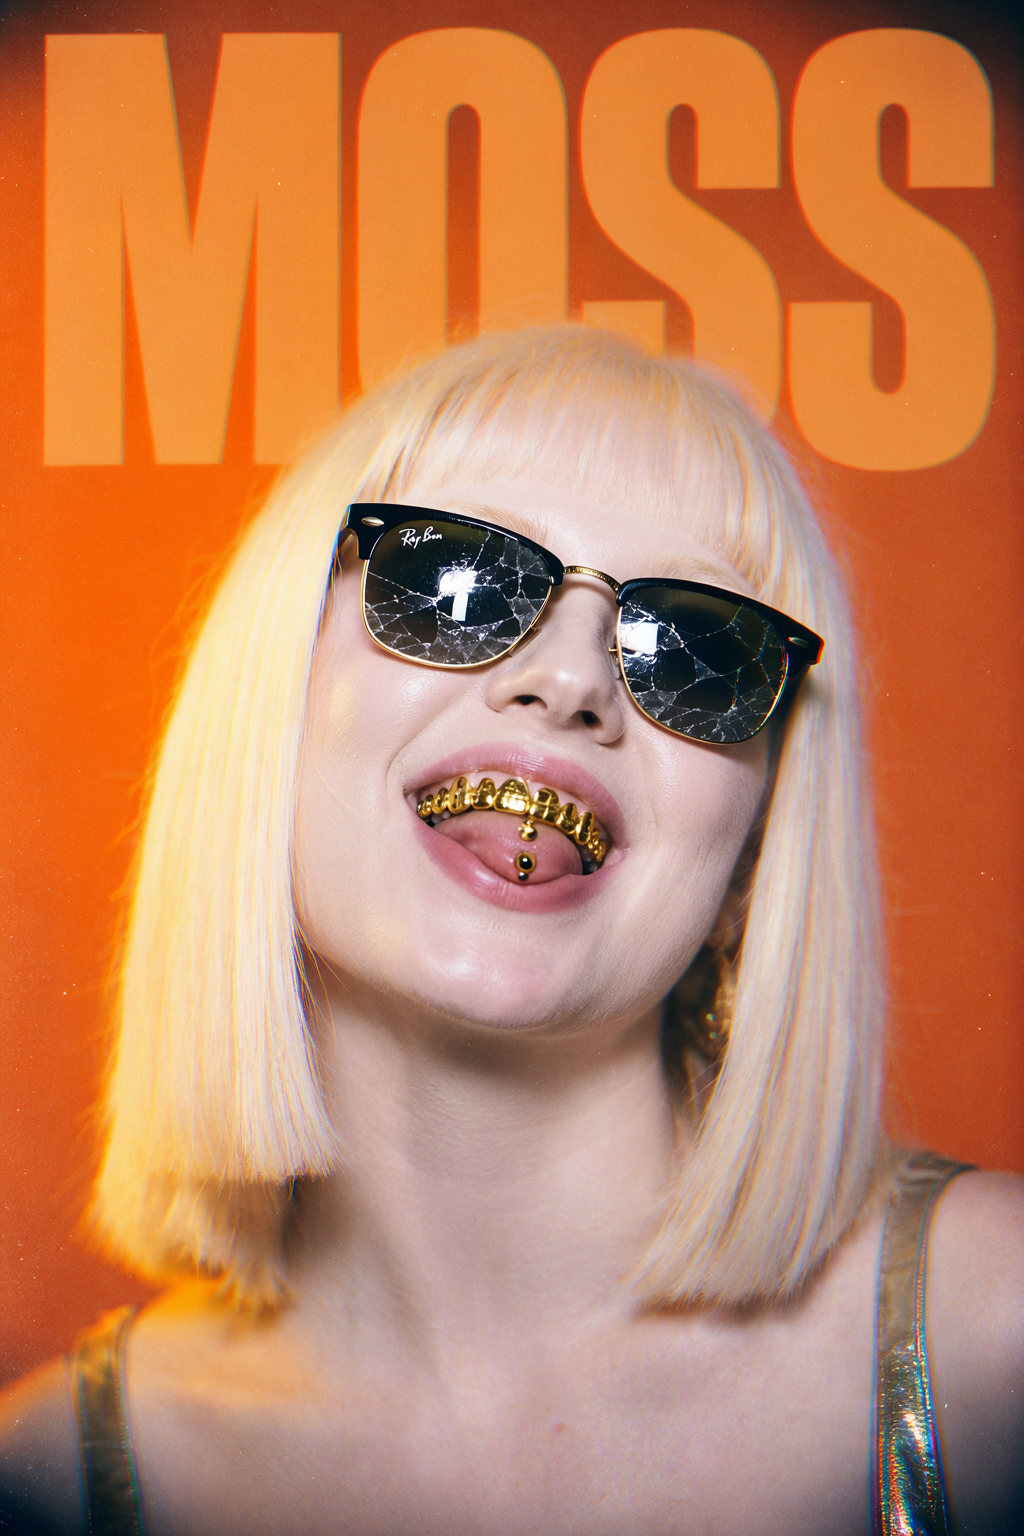
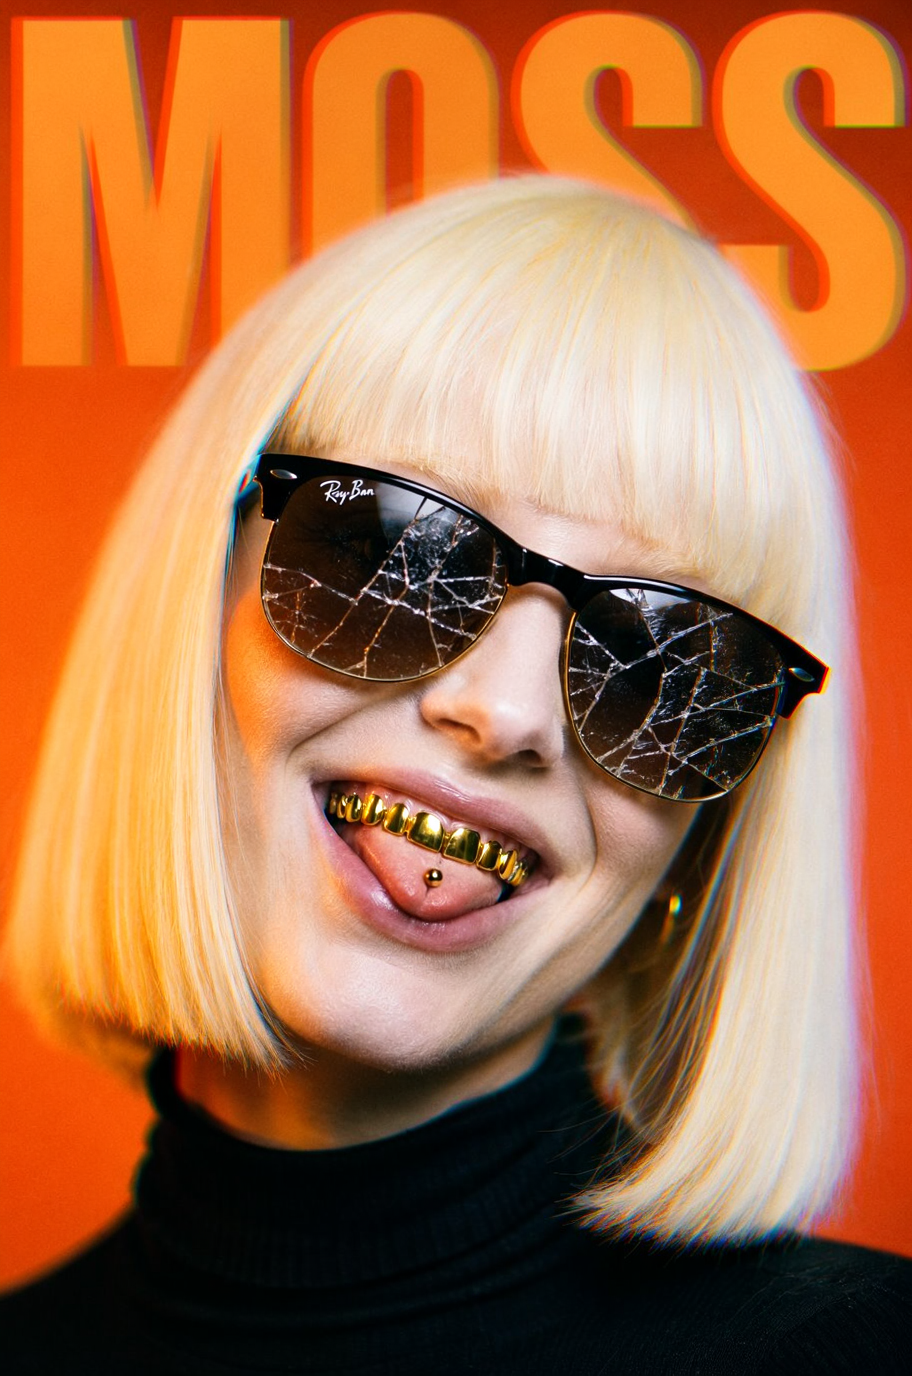
    					Cinematic headshot portrait of an albino beautiful female model around 30 years-old wearing a long bob haircut and Rayban shattered sunglasses. Her head is slightly tilted. She is smiling showing her pierced tongue and her gold plated teeth. Everything is illuminated in a professional studio with 3 light setup and a bright orange background. Behind her head, there is a plain text that reads "MOSS" written in bold sans-serif typography big enough to fill the entire length of composition. Shot on Fuji Film with 85 mm lens, chromatic aberration and a bit of film grain.


    Here is the Negative Prompt:

    				
    					nsfw, low quality, jpg artifacts, bad anatomy, deformity


    Here is the Seed:

    				
    					878922073981414


    Here is the Aspect Ratio:

    				
    					2:3 (Portrait Photo) and 1.2 Megapixels


    BEST RESULTS

    Here are the best CFG + STEPS + SAMPLER + SCHEDULER combinations I found in this benchmark.

    ER_SDE + Normal + CFG 7 + 50 Steps

    Euler + Normal + CFG 7 + 50 Steps

    DPMPP 2M + Linear Quadratic + CFG 7 + 50 Steps

    Res_Multistep + Simple + CFG 7 + 50 Steps

    CFG

    Classifier Free-Guidance, this parameter controls how strict and how creative the generations must adehre to your prompt. Higher values means more freedom, lower values will try to reproduce exactly what your prompted but are prone to breaking.

    Sampler: EULER / Scheduler: BETA / Steps 30

    CFG 0.5

    CFG 1

    CFG 1.5

    CFG 2

    CFG 2.5

    CFG 3.5

    CFG 5

    CFG 8

    CFG 10

    CFG 15

    CFG 25

    CFG 50

    STEPS

    Steps means how many times the latent space should be receive the influence of the CLIP and VAE.

    Sampler: EULER / Scheduler: NORMAL / CFG 6

    Steps 15

    Steps 30

    Steps 50

    Steps 75

    SAMPLER EULER + SCHEDULER

    The combination of Sampler and Scheduler will alter the interpretation of latent data.

    50 Steps / CFG 7

    Euler + Normal

    Euler + Simple

    Euler + Beta

    Euler + SGM Uniform

    Euler + Karras

    Euler + Exponential

    Euler + DDIM Uniform

    Euler + Linear Quadratic

    SAMPLER ER_SDE + SCHEDULER

    The combination of Sampler and Scheduler will alter the interpretation of latent data.

    50 Steps / CFG 7

    ER_SDE + Normal

    ER_SDE + Simple

    ER_SDE + Beta

    ER_SDE + SGM Uniform

    ER_SDE + Karras

    ER_SDE + Exponential

    ER_SDE + DDIM Uniform

    ER_SDE + Linear Quadratic

    SAMPLER DPMPP 2M + SCHEDULER

    The combination of Sampler and Scheduler will alter the interpretation of latent data.

    50 Steps / CFG 7

    DPMPP 2M + Normal

    DPMPP 2M + Simple

    DPMPP 2M + Beta

    DPMPP 2M + SGM Uniform

    DPMPP 2M + Karras

    DPMPP 2M + Exponential

    DPMPP 2M + DDIM Uniform

    DPMPP 2M + Linear Quadratic

    SAMPLER RES_MULTISTEP + SCHEDULER

    The combination of Sampler and Scheduler will alter the interpretation of latent data.

    50 Steps / CFG 7

    Res_Multistep + Normal

    Res_Multistep + Simple

    Res_Multistep + Beta

    Res_Multistep + SGM Uniform

    Res_Multistep + Karras

    Res_Multistep + Exponential

    Res_Multistep + DDIM Uniform

    Res_Multistep + Linear Quadratic

    SAMPLER sa_solver + SCHEDULER

    As commented on this Reddit thread, the user Dw82 suggested the use of SA_SOLVER as primary Sampler for really good results. Here are the results and I must say they do look very realistic and true to the prompt.

    The combination of Sampler and Scheduler will alter the interpretation of latent data.

    50 Steps / CFG 7

    SA_Solver + Normal

    SA_Solver + Simple

    SA_Solver + Beta

    SA_Solver + SGM Uniform

    SA_Solver + Karras

    SA_Solver + Exponential

    SA_Solver + DDIM Uniform

    SA_Solver + Linear Quadratic

    DENOISE

    Denoise parameter means when the algorithm will stop calculating in the latent space and deliver the data to be rendered by the sampler and scheduler. The lower the value, the sooner it stops the calculation.

    Sampler ER_SDE / Scheduler: Normal / 50 Steps / CFG 7

    Denoise 0.7

    Denoise 0.8

    Denoise 0.9

    Denoise 0.95

    Denoise 1

    Conclusion

    MOSS Image is a impressively realistic and fast model that adheres somewhat good to the prompt. I tried longer prompts with more specific details but then it started forgetting to write “MOSS” in the background and sometimes forgetting the albino stereotype. Although it accepts long parameters, further testing has to be done in order to find the correct balance.

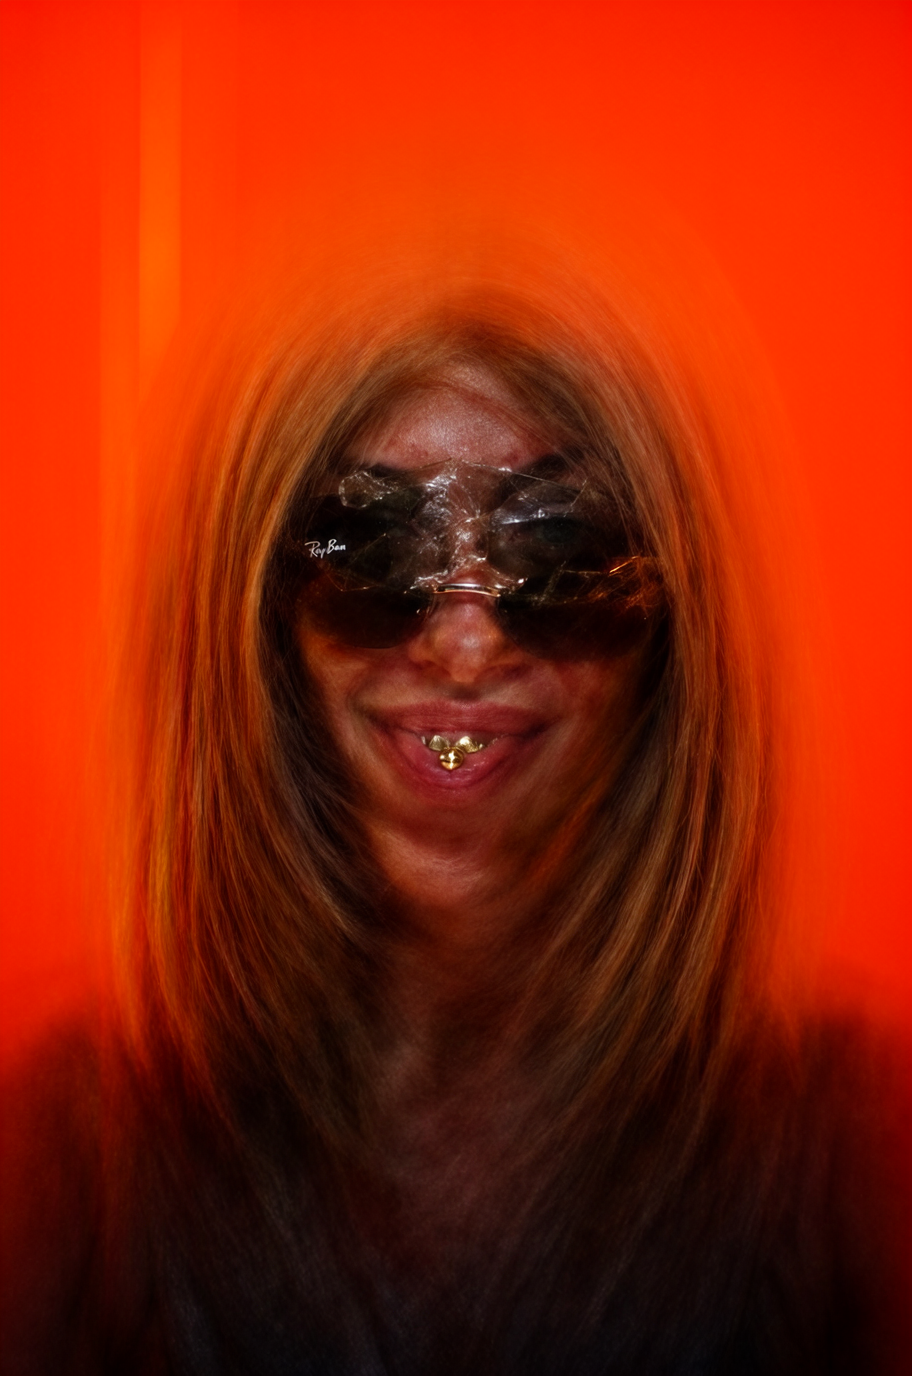
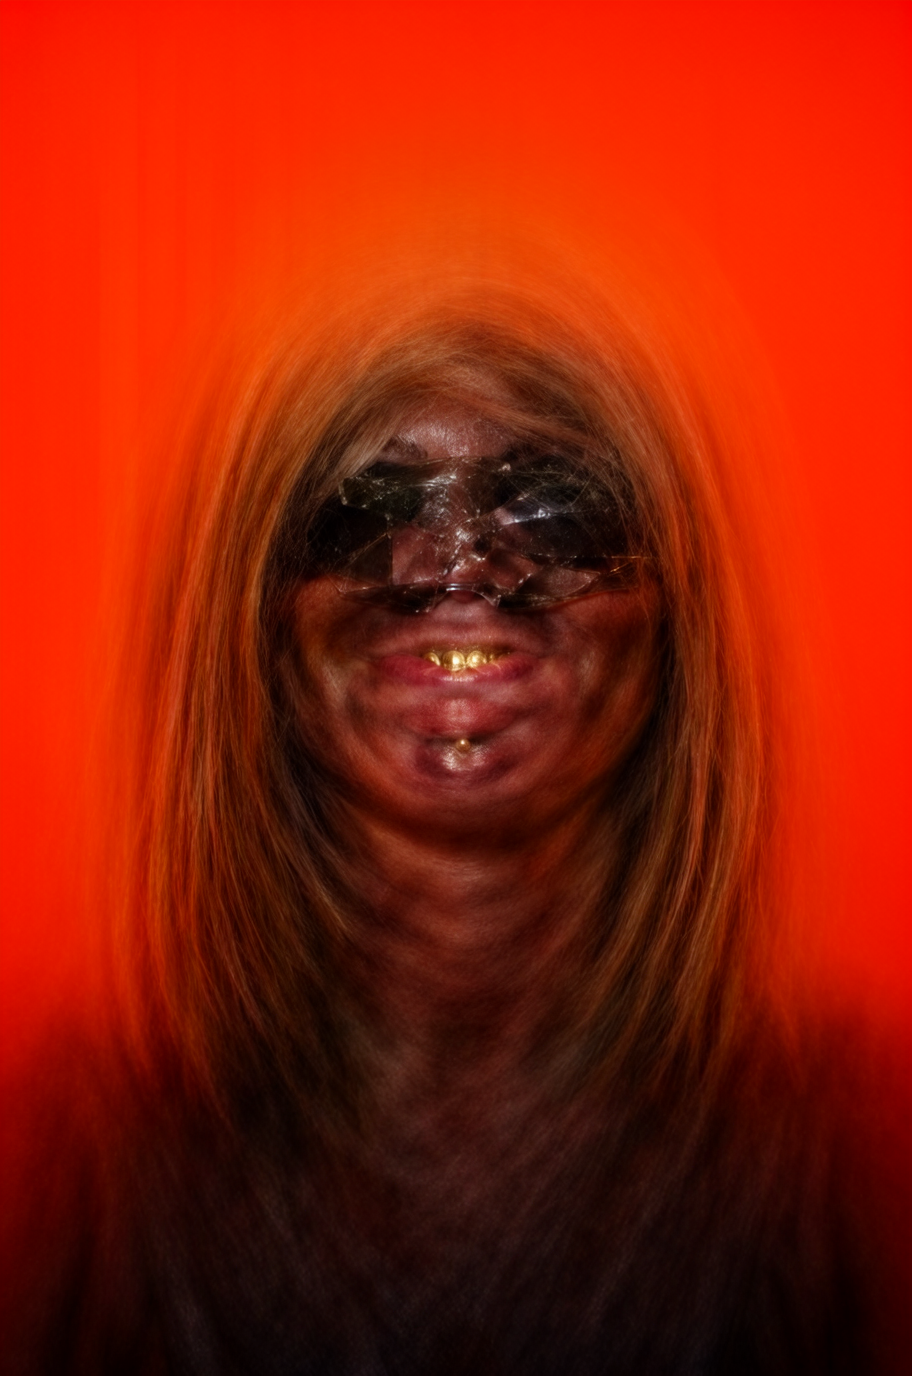
    Sampler and Scheduler combination-wise the ER_SDE and the Euler are surely the top choices and the Scheduler choice really does not matter as results are almost identical. Just Karras and Exponential are proven to break completely the rendered output, then it is safe to stick with Simple, Normal, Beta, DDI, SGM and Linear Quadratic, all of them really maintaining similar if not equal rendering time.

  • Engates AnexoA

    Engates AnexoA

    Engates AnexoA

    Multimedia Product Catalog

    AI-Generated

    Graphic Design

    WebDesign

    The Project

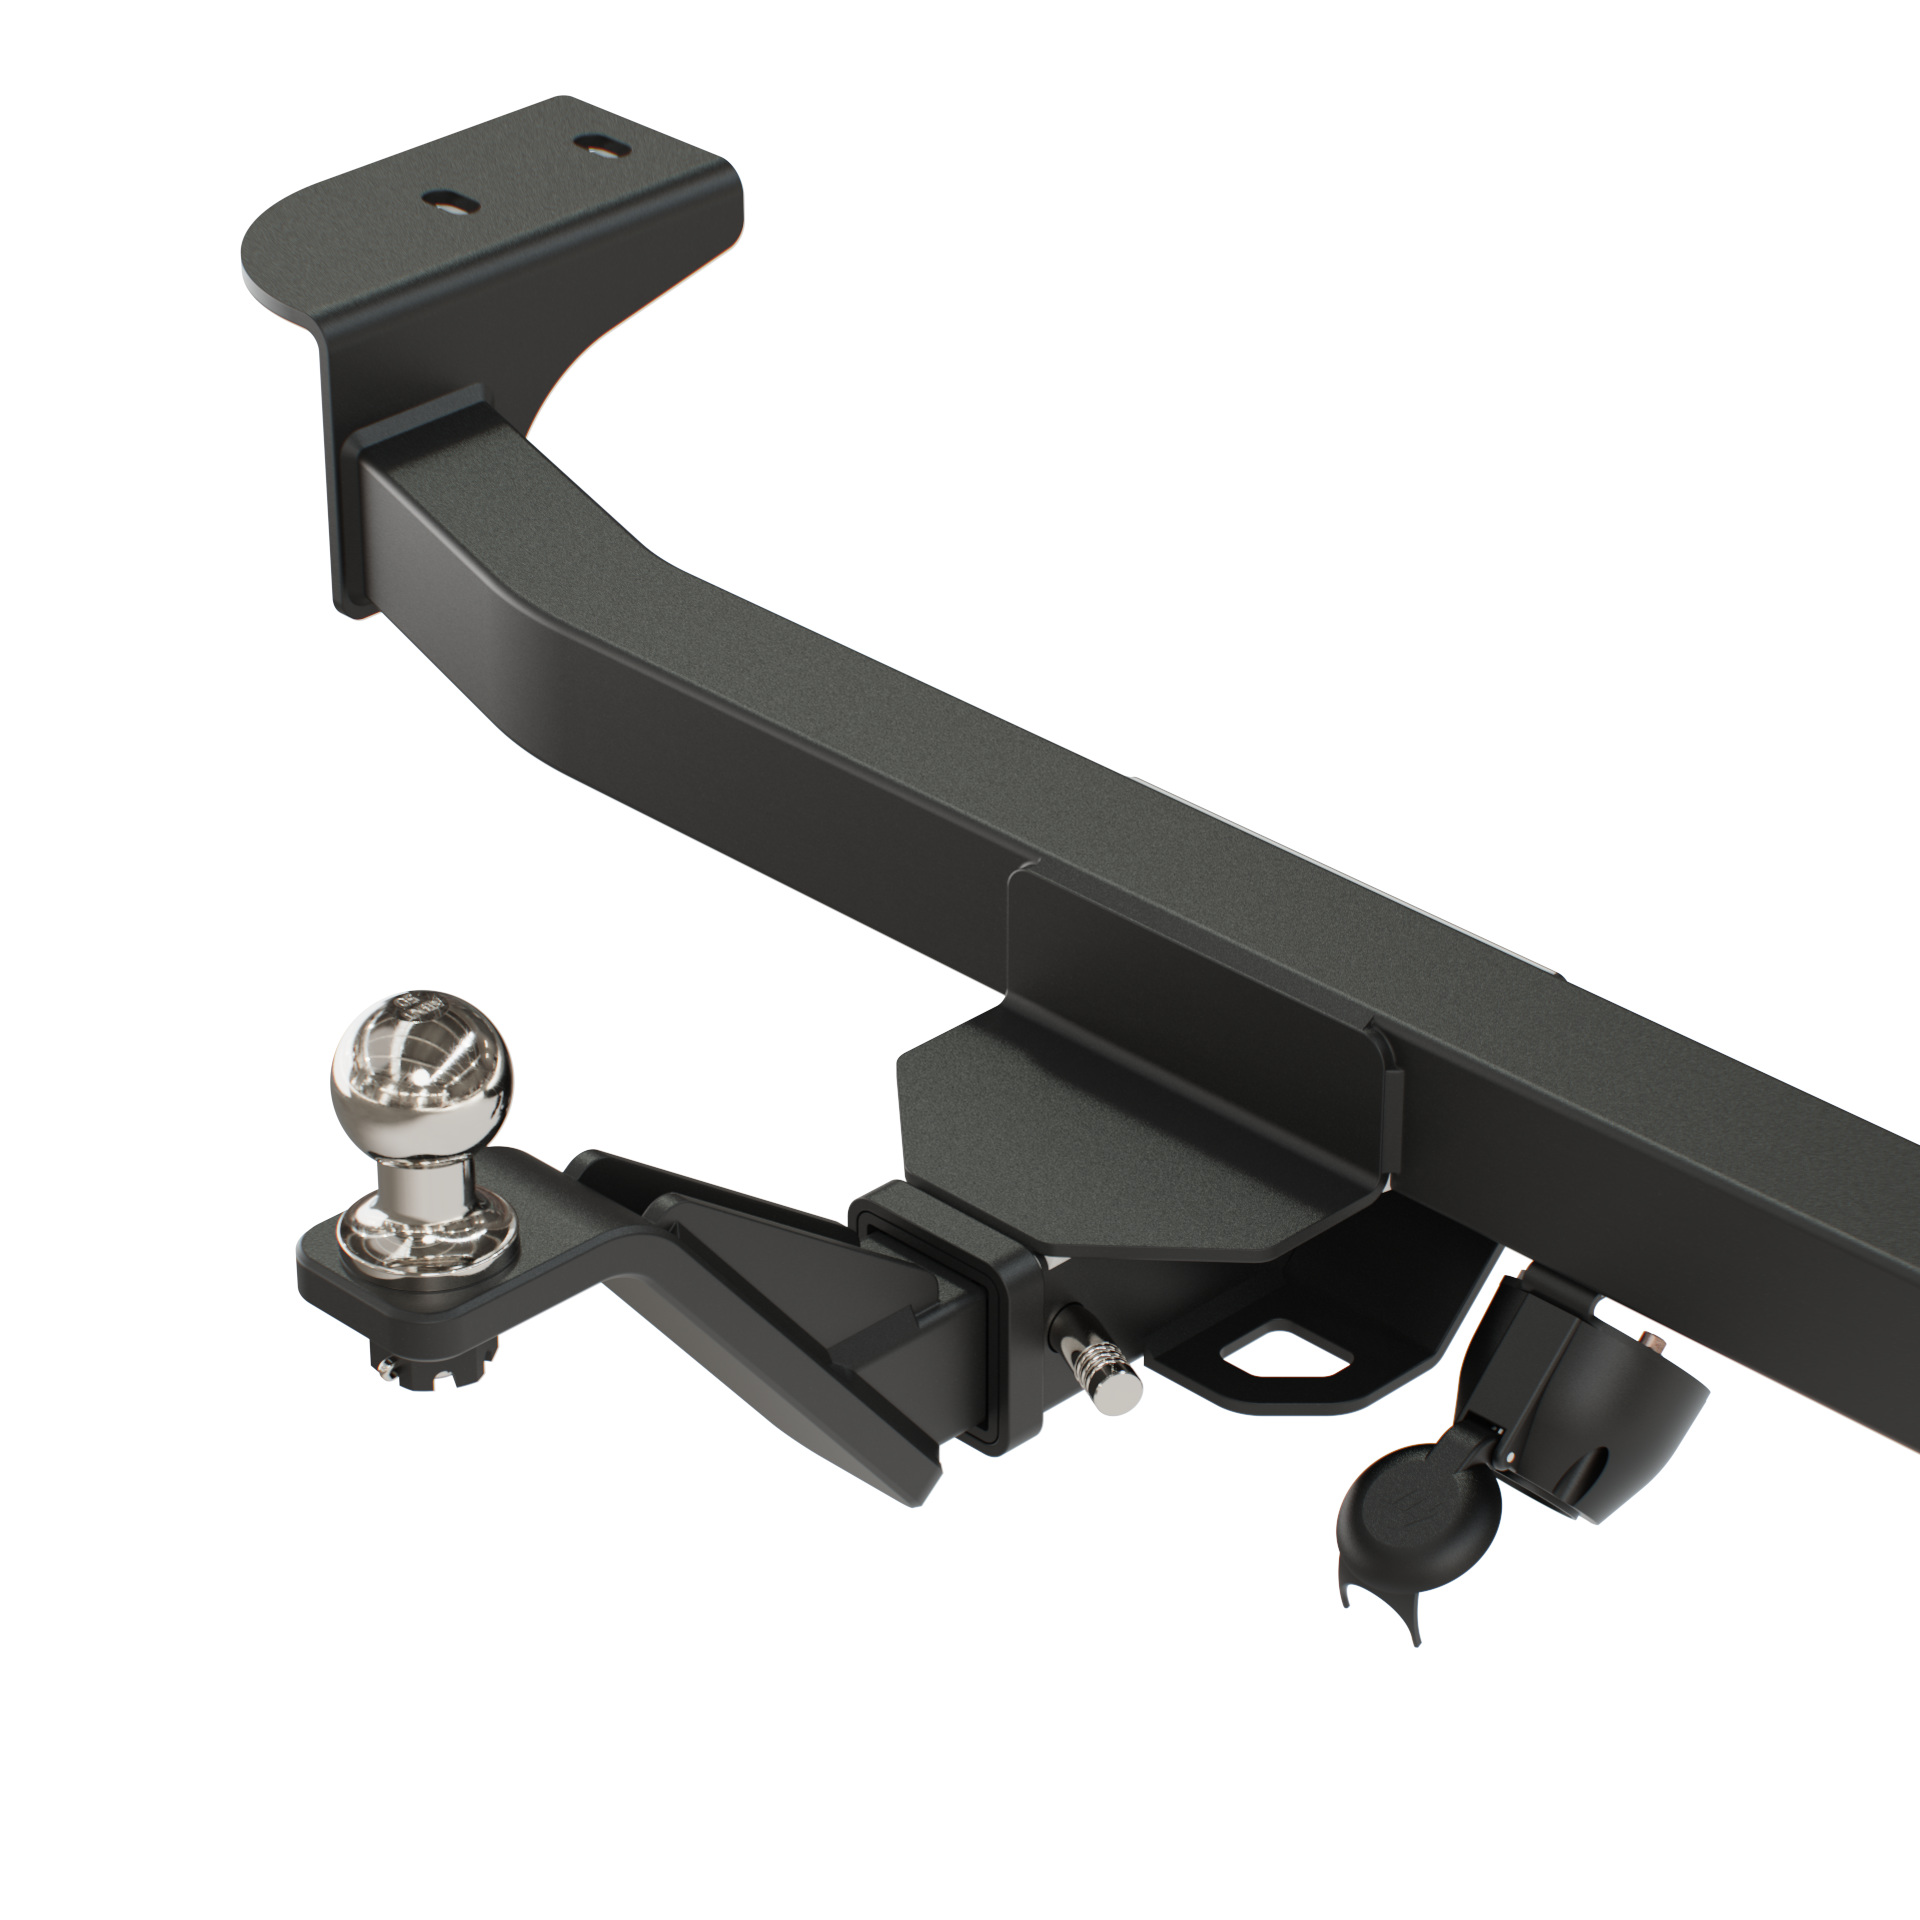
    Anexo A is a brazilian company focused on industrial automotive metallic parts and their key product are towing coupling for Stellantis, owner of such brands like Jeep, Chrysler, Fiat, Peugeot, Citröen, Maseratti and many more.

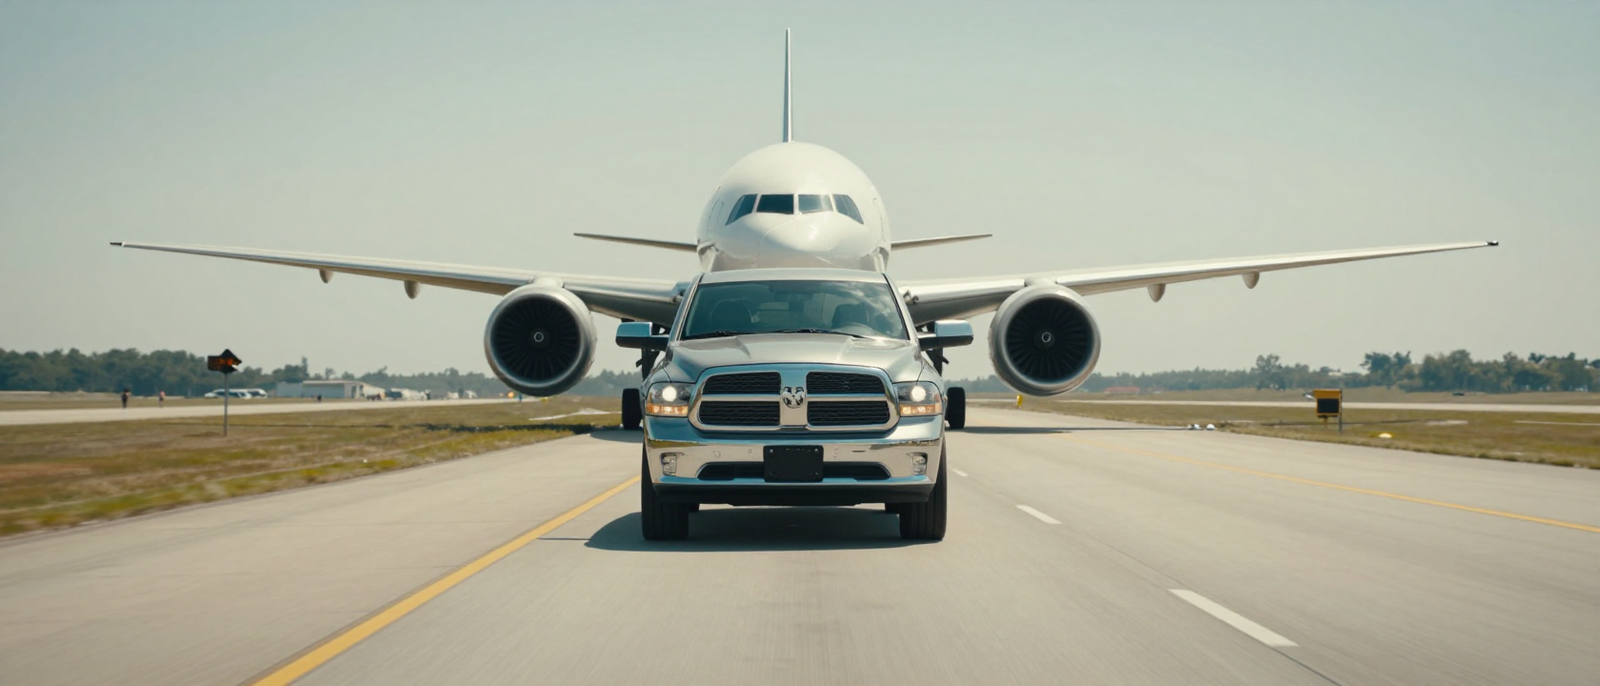
    The company’s pain was their overall poor web presence and product catalog. Our project is based on a multi-checkpoint strategy, starting with their key product: tow coupling. After discussing the options I presented and what the company needed as priority, I advocated for an online catalog such as a webpage where it would be easier to update content, pictures and technical data, better to control access, and we can make use of multimedia elements. After getting the OK for this asset to be created, I decided to use AI-generated content to squeeze the maximum of our allowed budget and deliver a cinematic hero splash screen.

    For the product catalog images, I had access to all the product CAD files and then I rendered everything using Luxion’s Keyshot, so we had acurate and beautiful shot of each product, perfectly aligned to camera angles favouring its intricate structure, over a plain neutral background to be used alongside the webpage.

    3d rendered assets

    All the products were treated in a 3D environment in order to be textured with the right materials parameters and scale.

    I crafted render shots in neutral background color and studio lighting setup to highlight the maximum of each and every detail, giving a premium feel and aesthetics to the product.

    The cinematic video

    The most impactful section of this online catalog is the cinematic video on the hero section.

    Were not for the licensing fees from the 3D software used to render, this could have been the most expensive portion of the project.

    In order to get the artistic direction I was seeking, I had to experiment and combine many AI agents together, from scripting the scene direction and photography, to fine tuning the end prompt.

    It took weeks between finding the prompt recipe combining real world cameras models and brands, lens types and brands, post-production and in-capture glare effects, plus the training sessions of each vehicle to render and behave accordingly each make and model.

    The end result is a stunning cinematic shot compilation with aesthetically light leaks, subtle chromatic aberration and real world dynamics, all later on edited, color corrected and stitched together using Adobe Premiere.

    Each vehicle model was curated and trained as a separate LORA or character, then inserted in a meticulously crafted prompt. Not only this steps were necessary to achieve a realistic cinematic video, but I had to experiment with so many different AI models ranging from WAN (all of their available versions), LTX, Higgsfield native, Seedance (both models), Kling 3.0, Minimax Hailuo, the most expensive of all agents SORA and I even experimented with Grok.

    All in all, it was a fun process, although a bit costly, certainly cheaper than having it recorded in real life with real vehicles, cameras and personel. Having to wait long minutes between each generation ended up costing myself long nights awake just to change a coma or a word to get better results.

    CLIENT

    ANEXO A (Brazil)

    PROJECT SCOPE

    WEBDESIGN
    PROMPT ENGINEERING
    VIDEO EDITING

    SOFTWARE

    MAYA
    PHOTOSHOP
    AFFINITY DESIGNER
    PREMIERE PRO
    KEYSHOT
    HIGGSFIELD
    COMFY UI

  • Kreiselfest 2026 – Zollikofen

    Kreiselfest 2026 – Zollikofen

    Kreiselfest 2026 – Zollikofen

    Joyful Brand Identity for the city’s mega-fest

    Branding

    Graphic Design

    WebDesign

    The Project

    The Kreiselfest (or Roundabout Festival) in the city of Zollikofen, Switzerland, is a large community festival taking place on the main avenue closing the traffic to host the mega-party for two consecutive days, to happen on 4th and 5th September this year, 2026.

    The project is lead by a committee of 40 decision-makers executives that plays a significant role in the city economy. After presenting my brand project’s entry for the event, it was finally awarded as winner and the committee officially adopted this Brand Identity System.

    the Kreiselfest Design System

    The briefing was clear:

    • Logo must have circular or radial elements to remind the two roundabouts where the festival takes place.
    • Logo must be joyful.
    • Logo must depict some kind of movement.
    • Logo must depict music.
       

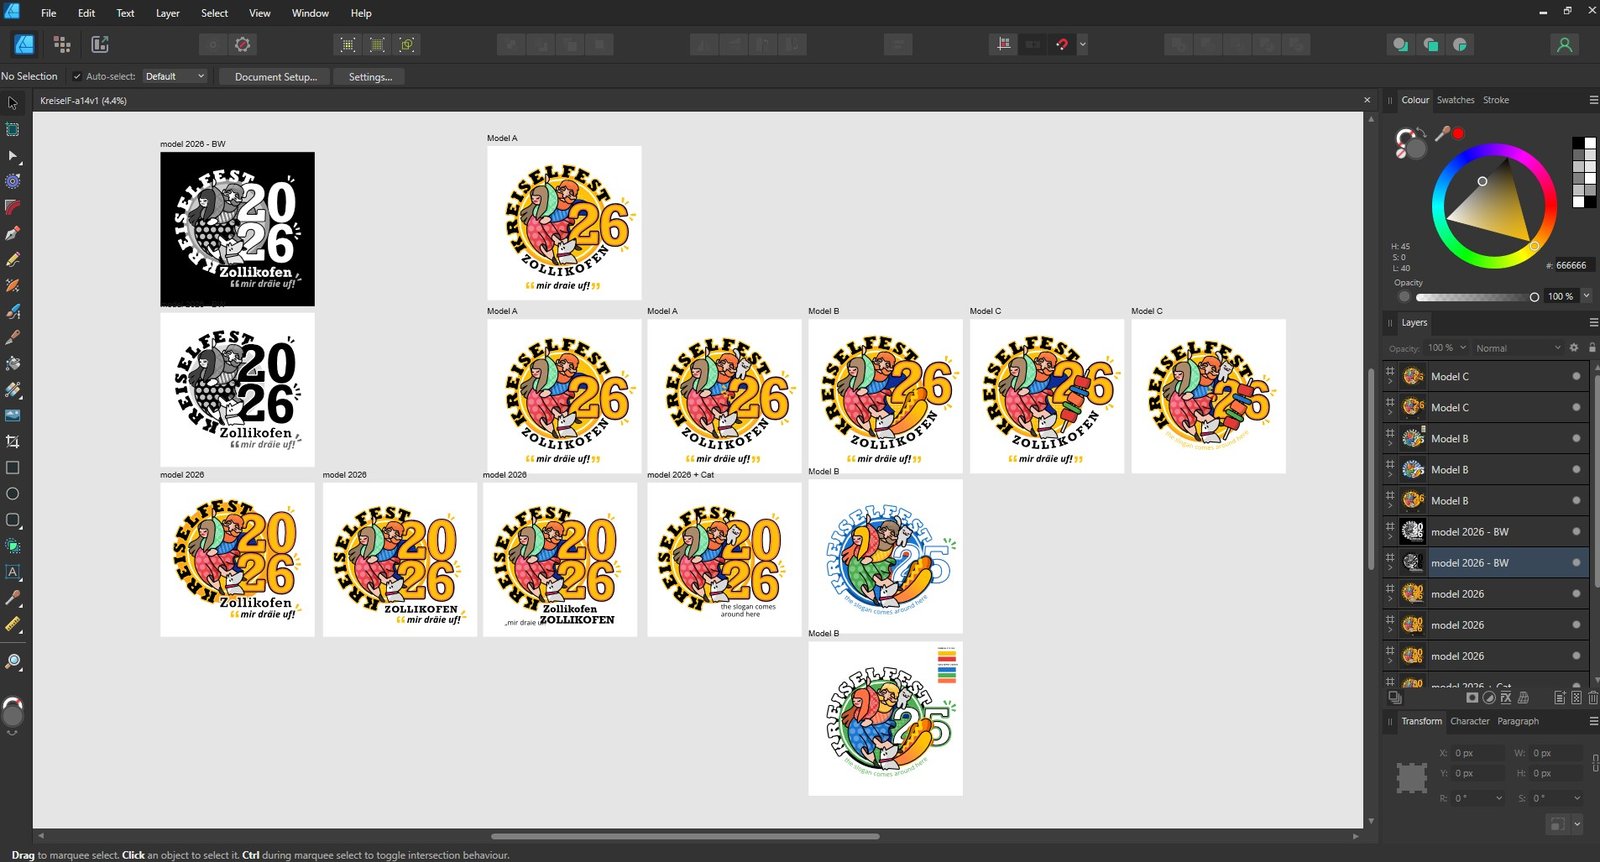
    Based on that I designed the main core logo elements and presented five versions with various elements to choose from, including: dog, cat, hot-dog, barbecue on a stick and number pairing variations.

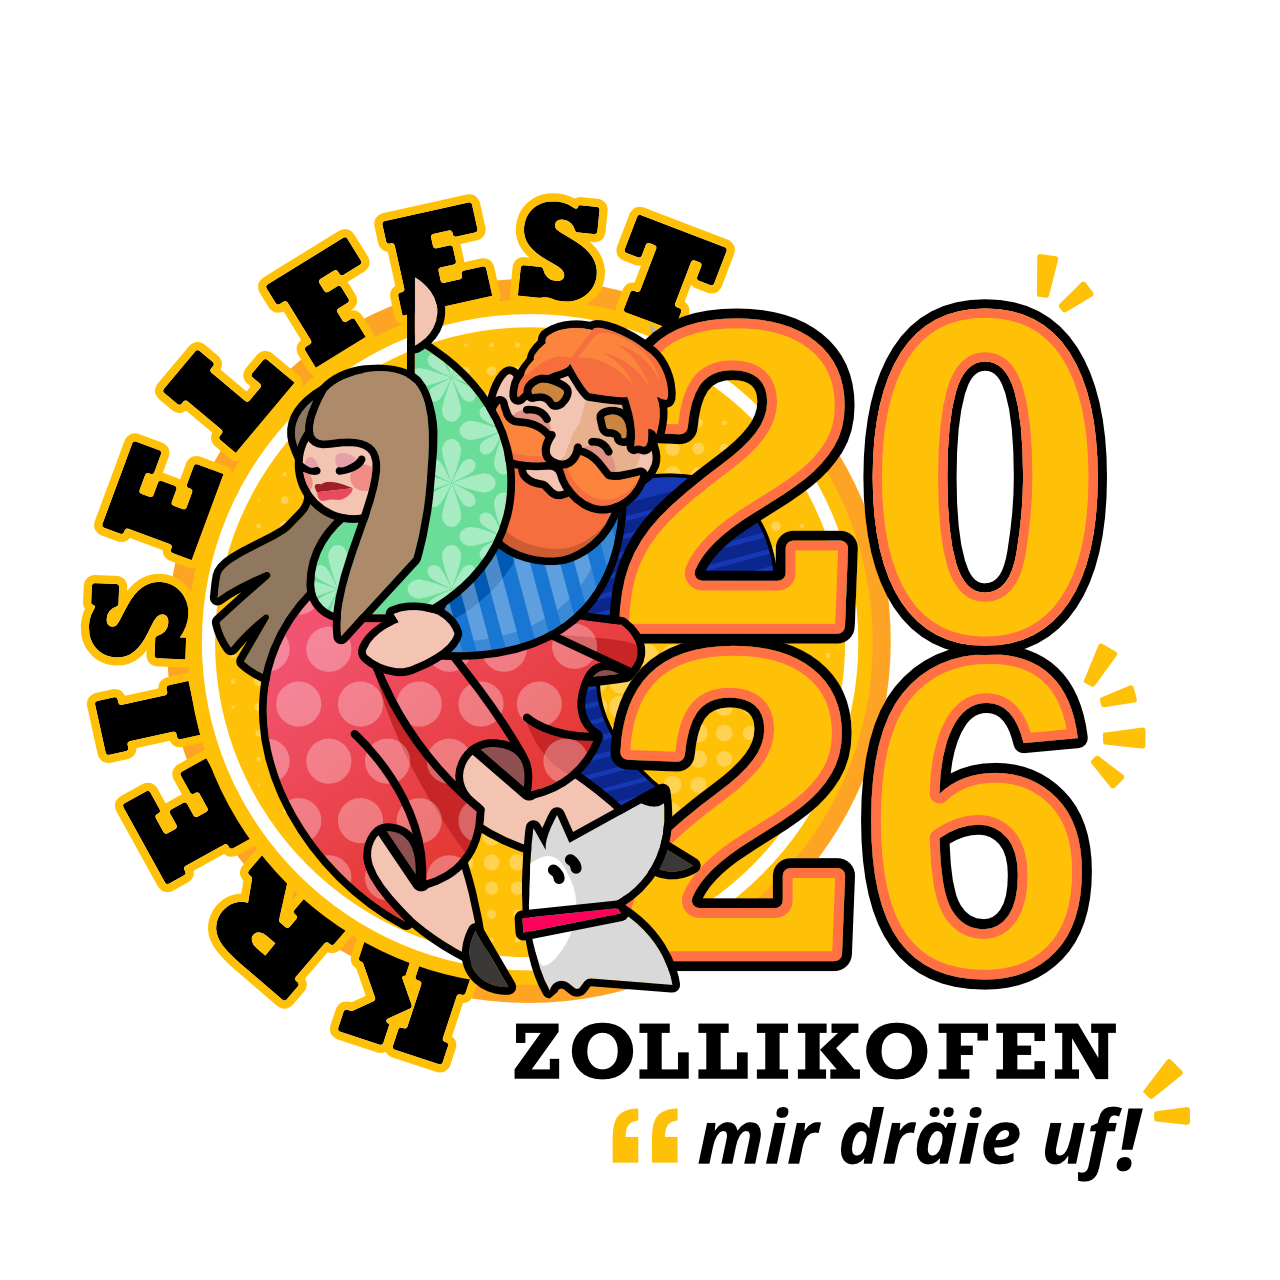
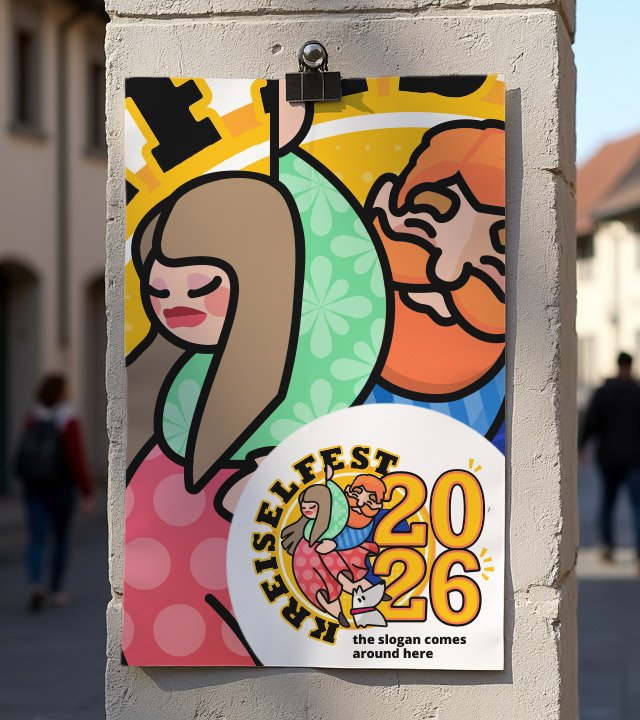
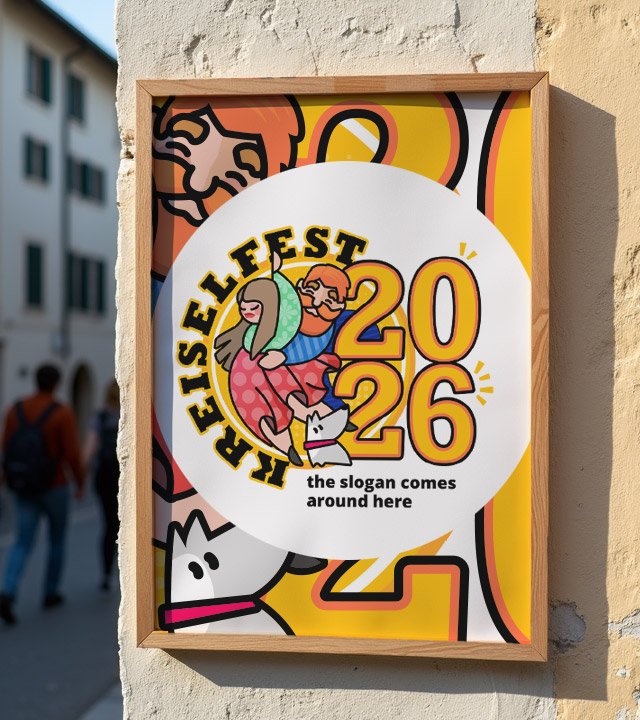
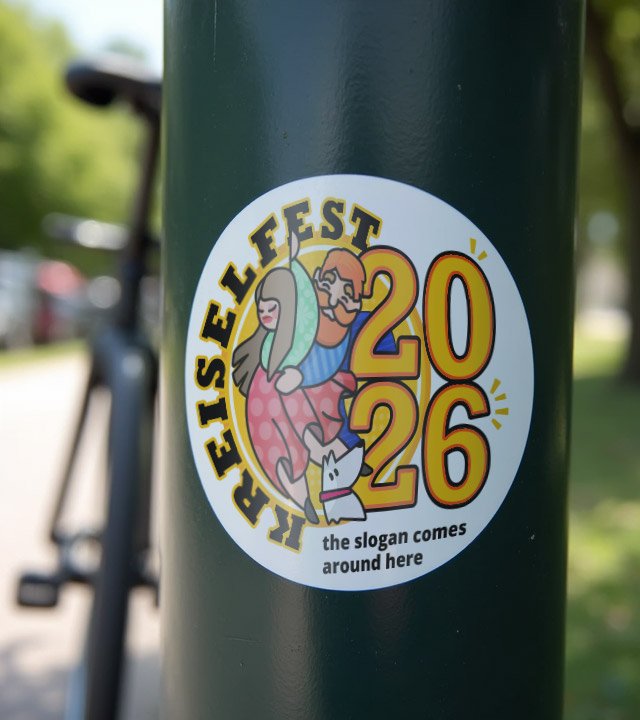
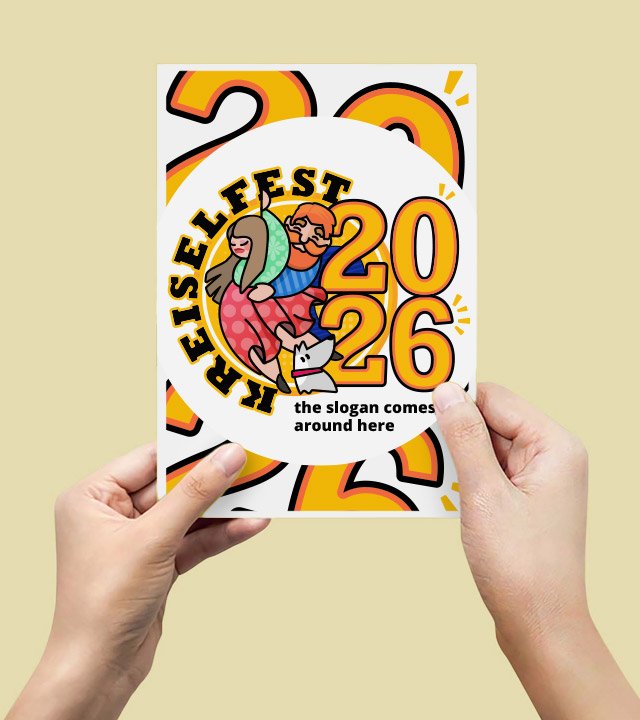
    The chosen version is the one with a dancing couple, a cute dog looking to the huge number pairing 2026 hat houses comfortably the city’s name and the provided slogan.

    The inspiration

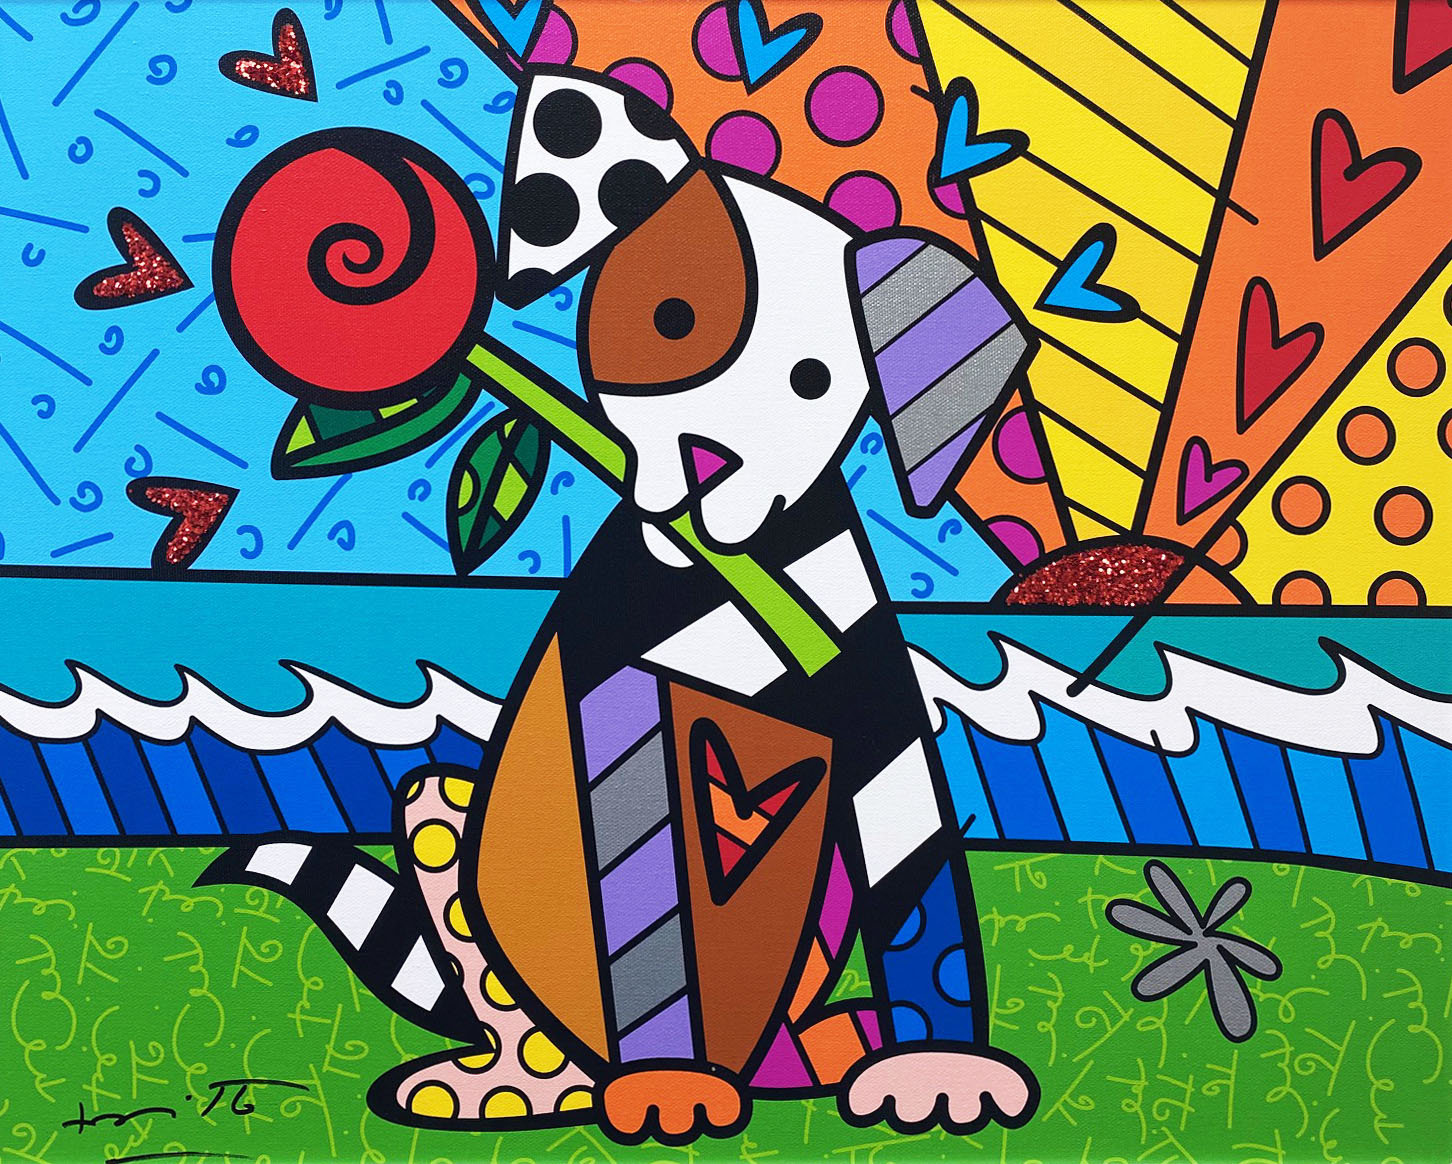
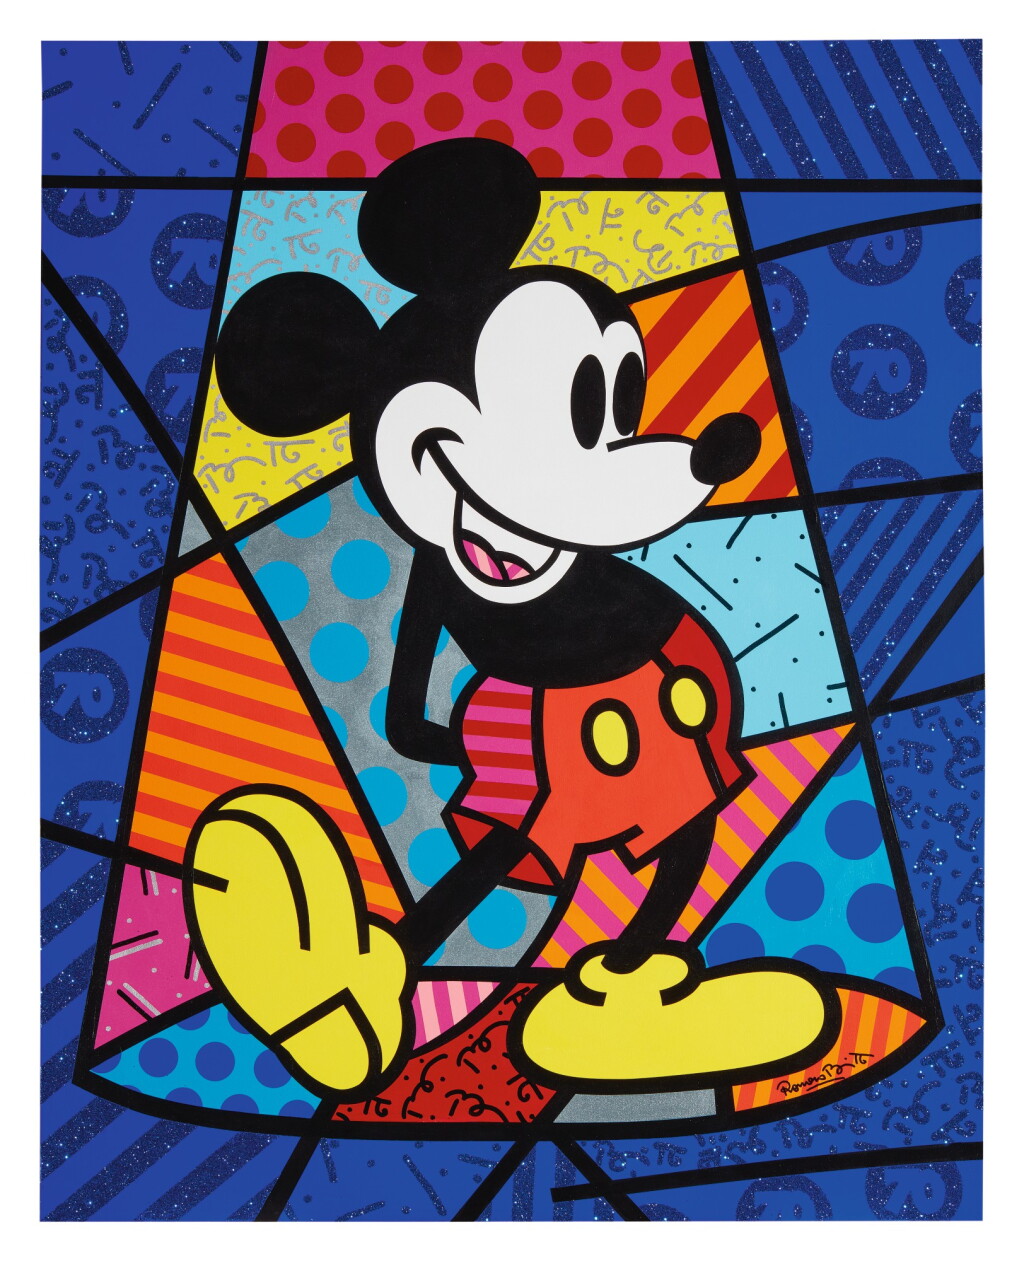
    As to the aesthetic, I took inspiration on the Romero Britto’s artwork, a renowned Brazilian abstract painter, now living in Florida, USA.

    He defines his own artwork as happiness, has an extensive gallery of random subject paints and prices from his canvas can reach up to US$ 2 million for a single painting.

    The vector-like strokes and precise bold lines filled with colorful patterns looks great on digital and printed media, thus, being my first choice to elaborate on the subject.

    Although this being a starting point, our Kreiselfest Brand came out with my own point of view, with quite different line design, weight, clear boundaries, cleaner pattern and a technically controlled color palette.

    The Design Process

    It started with many pencil sketches in my notebook until I found the circle formation with elements inside and typography outside.

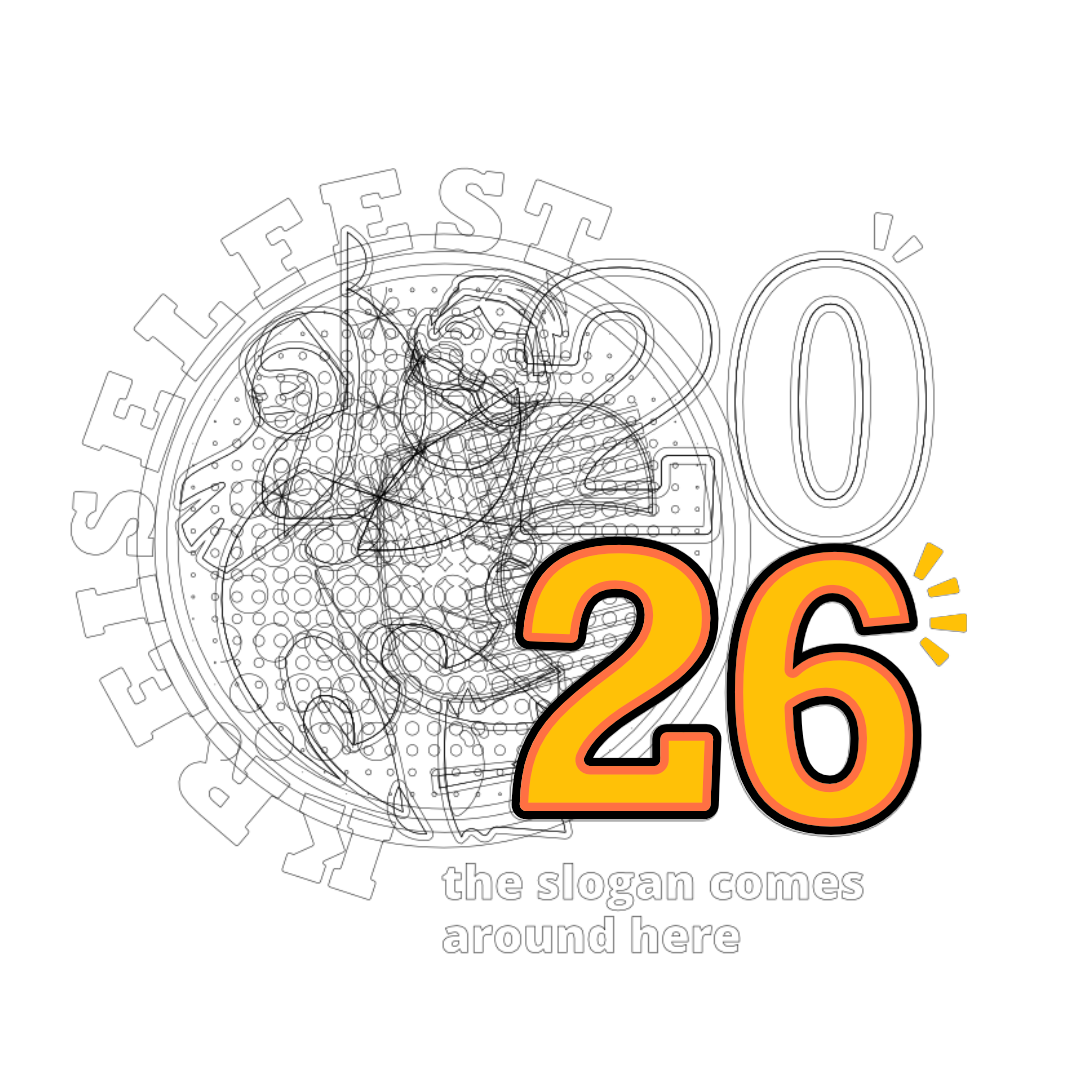
    Once found the core composition, I designed the shapes in vector software and fine-tune all the measurements and adjustments to balance and fit all the elements.

    After that I refined the colors to a limited palette and applied many combination until the most balanced and harmonic was found.

    Kreiselfest behind the scenes
    Behind the scenes: ongoing process with multiple versions

    The final approved version later on included a second logo and a website. The project counts many dedicated worked hours, and it is still ongoing as website evolves. Don’t miss to visit the official Kreiselfest website as well.

    Technically, the logo was a complex puzzle of shapes and patterns, but aesthetically it looked smooth and easy on the eyes.

    Shortly after the logo was done, I got a request to expand the project to a second logo, this time for the side event, the music festival.

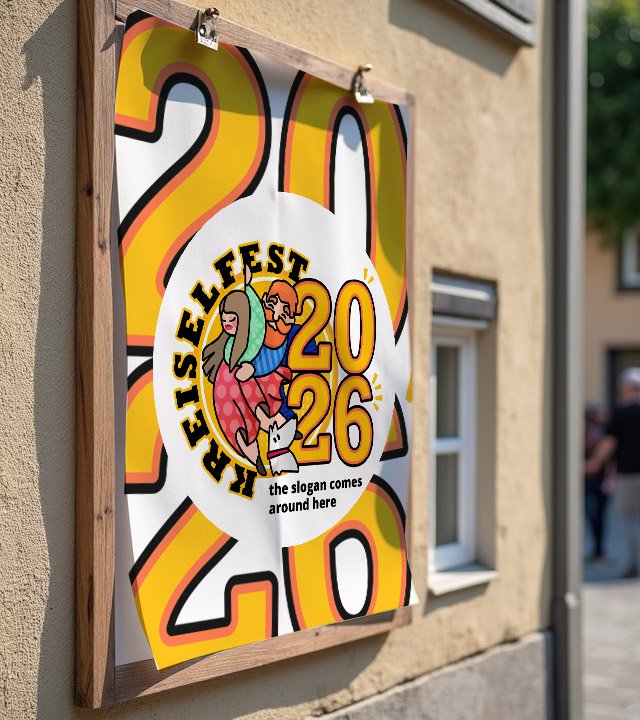
    Before diving into the complimentary logo, the next step of the process was to elaborate the brand guidelines and usage, as well as some mock ups with practical examples.

    The logo was also built to be modular and ready to be update next and upcoming years. The way I built it, it is quite easy to change 26 to 27 or whatever the year number that the next festival will be held.

    But I must admit, if I am to be honored again to manage the brand next festival edition, I would change the main character elements as well, so as the years and festivals goes by, we end up having a collection of logos with diverse characters, creating a world of its own.

    developing brand collateral based on the brand guidelines

    The circular logo could face complex fitting into the square world of monitors and framing for printed media. The richness of this logo allows us to truly play around and find joyful compositions.

    This was done by isolating the logo in a radial neutral border and filling the background with a mixture of its elements, drawing the eye always to the main element and filling with uplifting vibe all around the composition in a less word and more color approach.

    zolli on stage logo

    The Music Event named Zolli on Stage was later added to the project and asked to be designed as a “twin” logo approach.

    For that I used the existing design system and tweaked the characters to a more explicit sign ( music player, singer, dancer ) and used a rather analog color palette with blue and purple being the main mood contributors as the music event usually tends to happen at night. 

    For me, personally, the great addition is the red and white striped pattern added to one character element, clearly honoring the Swiss flag colors and pattern seen in many historical buildings.

    In the end, the main Kreiselfest logo and the Zolli On Stage logo are a great pair that not only look alike, but complements each other to a greater feeling of the event.

    The Kreiselfest Website

    Since the website would have diverse content contributors, I designed the website using Elementor and WordPress for the ease of use and access. The web project started on the brand guidelines and quickly evolved to a website with many pages.

    The key design characteristic is the absence of angular and sharp edges, as the entire project relies on rounded and radial shapes, that also applies to boxes, buttons and sections dividers.

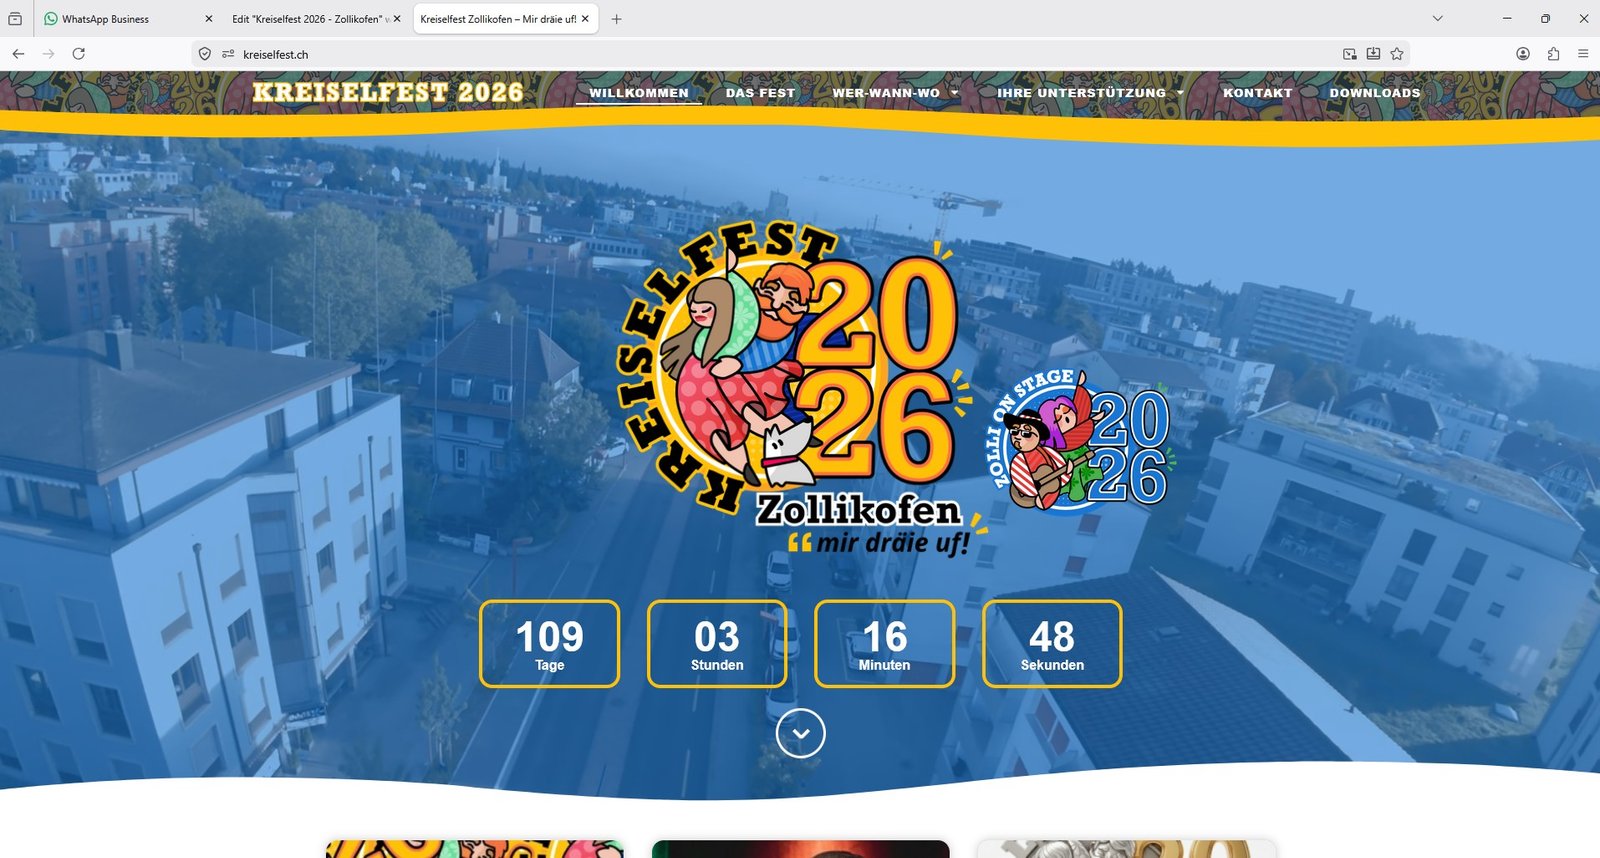
    For the front page I applied a hero banner with a drone-video footage running on the background, showing the overview on where the event will take place. The huge logo is the center piece accompanied by it’s “twin” Music Event logo. Then we have a feature that has a practical role: the live countdown timer, marking the exact time the event will start. Below the fold, we have updated information from the blog.

    CLIENT

    KREISELFEST / ZOLLI ON STAGE (Switzerland)

    PROJECT SCOPE

    BRANDING
    WEBDESIGN

    SOFTWARE

    PHOTOSHOP
    AFFINITY DESIGNER
    WORDPRESS

    My final thoughts on the project

    The project delivers vital information to the public, sells the event to sponsors and will be used as a memory multimedia album after the event. Driving a traffic of thousands of accesses daily, it grew organically with the help of the communication team through an open WhatsApp channel and social media like Instagram.

    This was a rather “different” project, far away from what I am really used to, corporate and serious toned businesses, and I must admit I had fun creating it. To use a more playful color palette and to design characters for a logo, was something I enjoyed and tested my skills at the same time.

    I’d like to thank very much the sponsoring and trust from Intelliworld that not only made it easy for me to understand the project’s needs as well defended the project to the committee board. Huge thanks Scott!

  • KEUNE Cosmetics

    KEUNE Cosmetics

    KEUNE Cosmetics

    3D Render Product Visualization

    3D Modeling

    3D Rendering

    Product Visualization

    Graphic Design

    Fictional Project

    Keune Cosmetics packshot

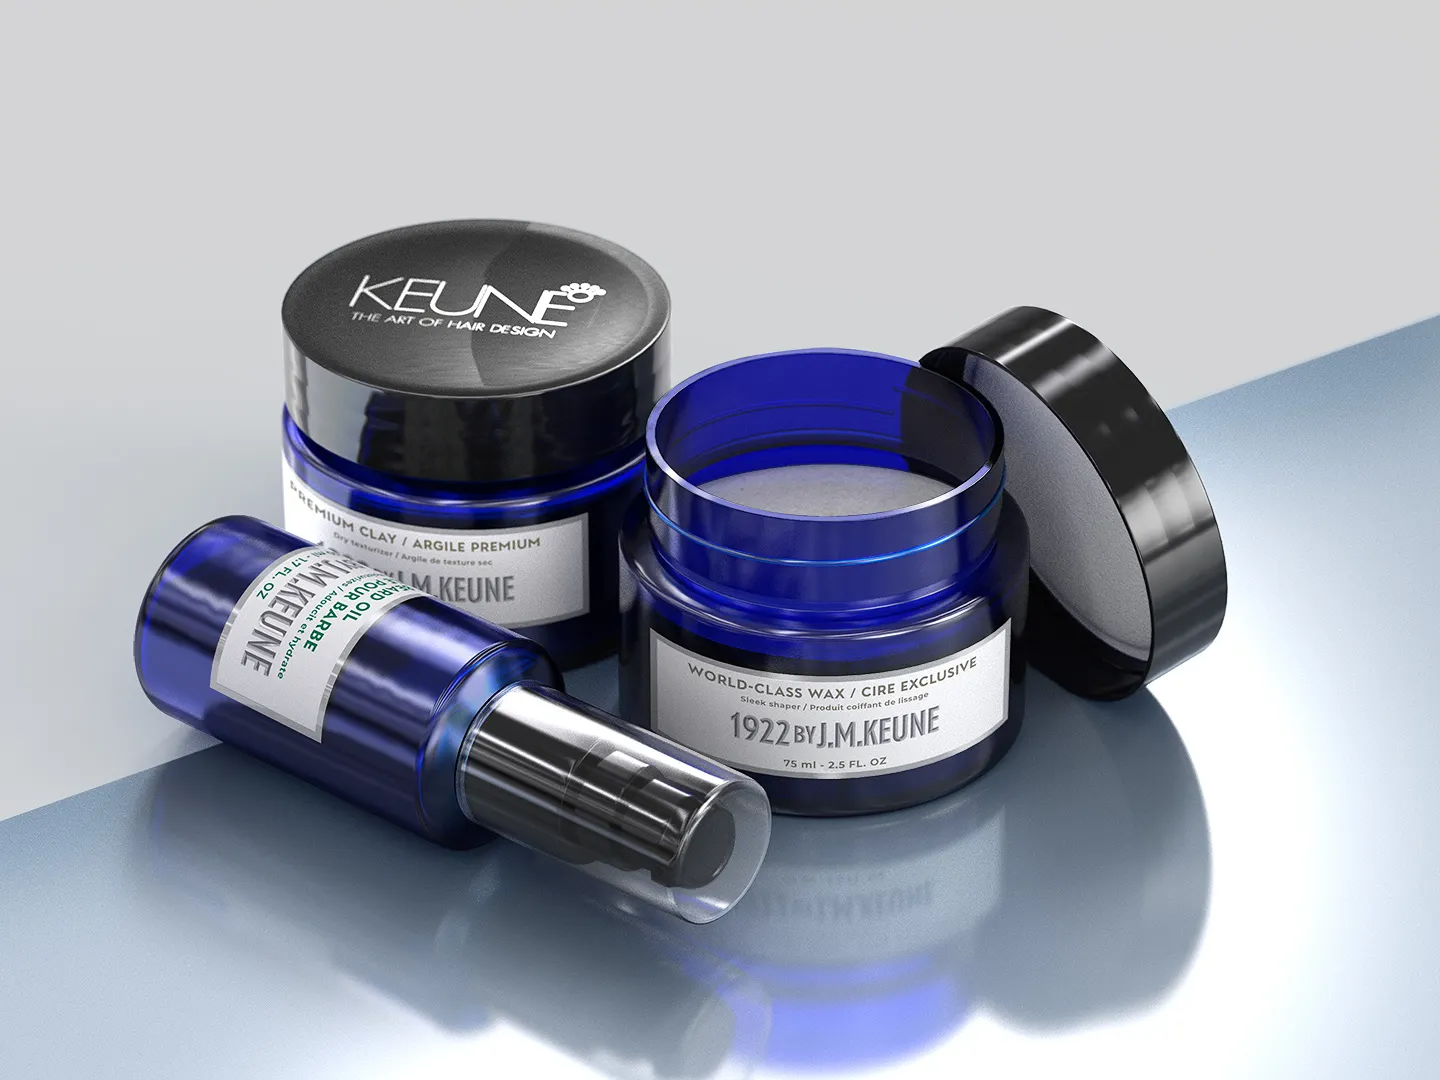
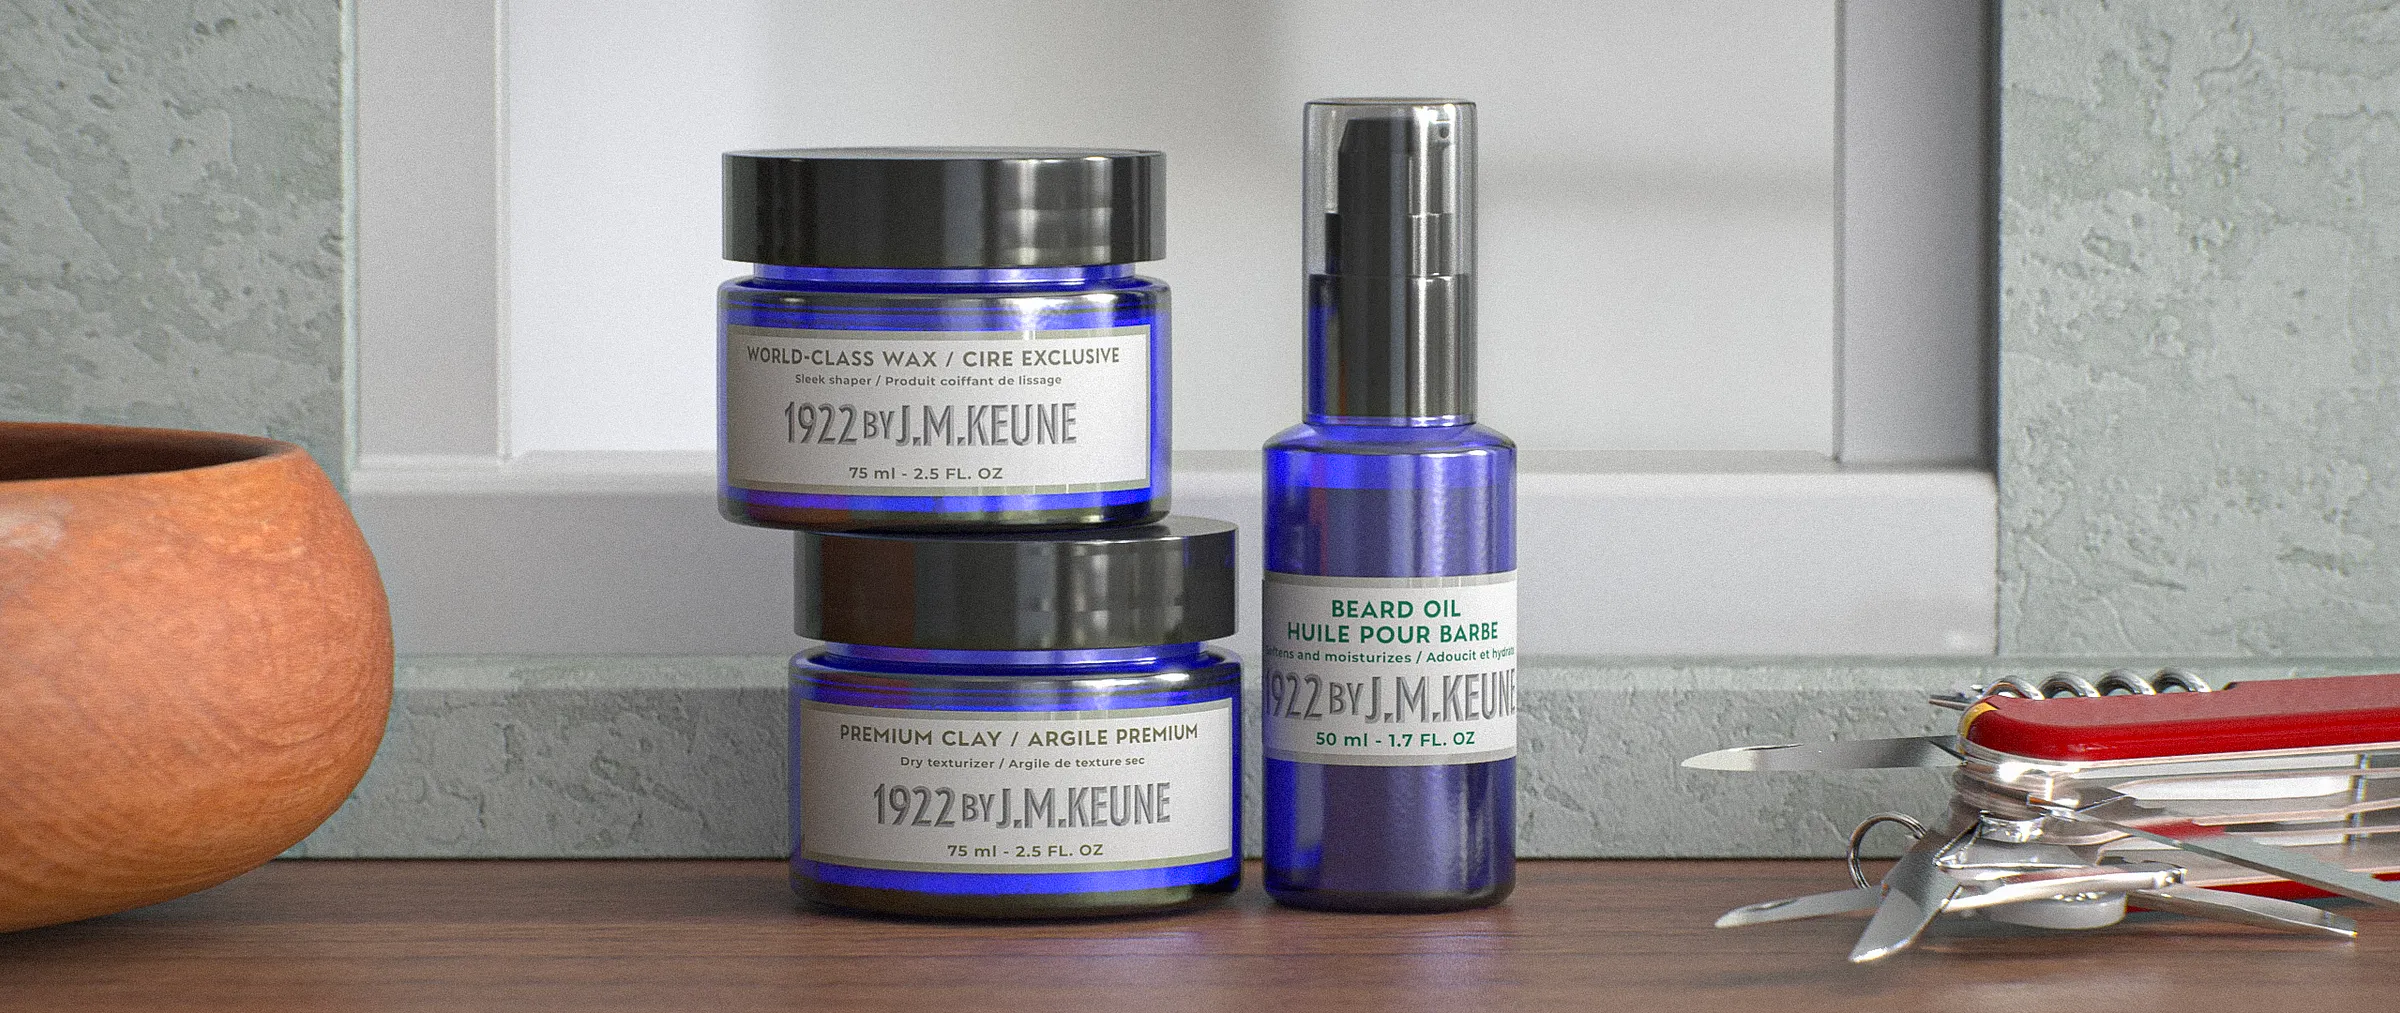
    I 3D modeled the contents of the image on the side using Autodesk Maya using as reference the real products.

    Labels were created using Adobe Photoshop and exported as PNG texture, both the white labels and the transparent cap label.

    The whole 3D composition was then rendered in Keyshot where I fine-tuned the materials, setup the HDRI environment and adjusted the settings for lighting. It was then rendered as a still image.

    Post-processing was done in Adobe Photoshop.

    CLIENT

    PERSONAL

    PROJECT SCOPE

    PRODUCT VISUALIZATION
    3D RENDERING
    MOCKUP

    SOFTWARE

    MAYA
    PHOTOSHOP
    KEYSHOT

    Keune Packshot 3D Product visualization render
    KEUNE Cosmetics, 3D rendered in Keyshot
  • SativaVet CDB Oil

    SativaVet CDB Oil

    SativaVet CDB Oil

    Package Design for Pharmaceutical Industry

    Package design

    3d rendering

    Graphic Design

    mockup

    Veterinary use CDB oil packaging redesign

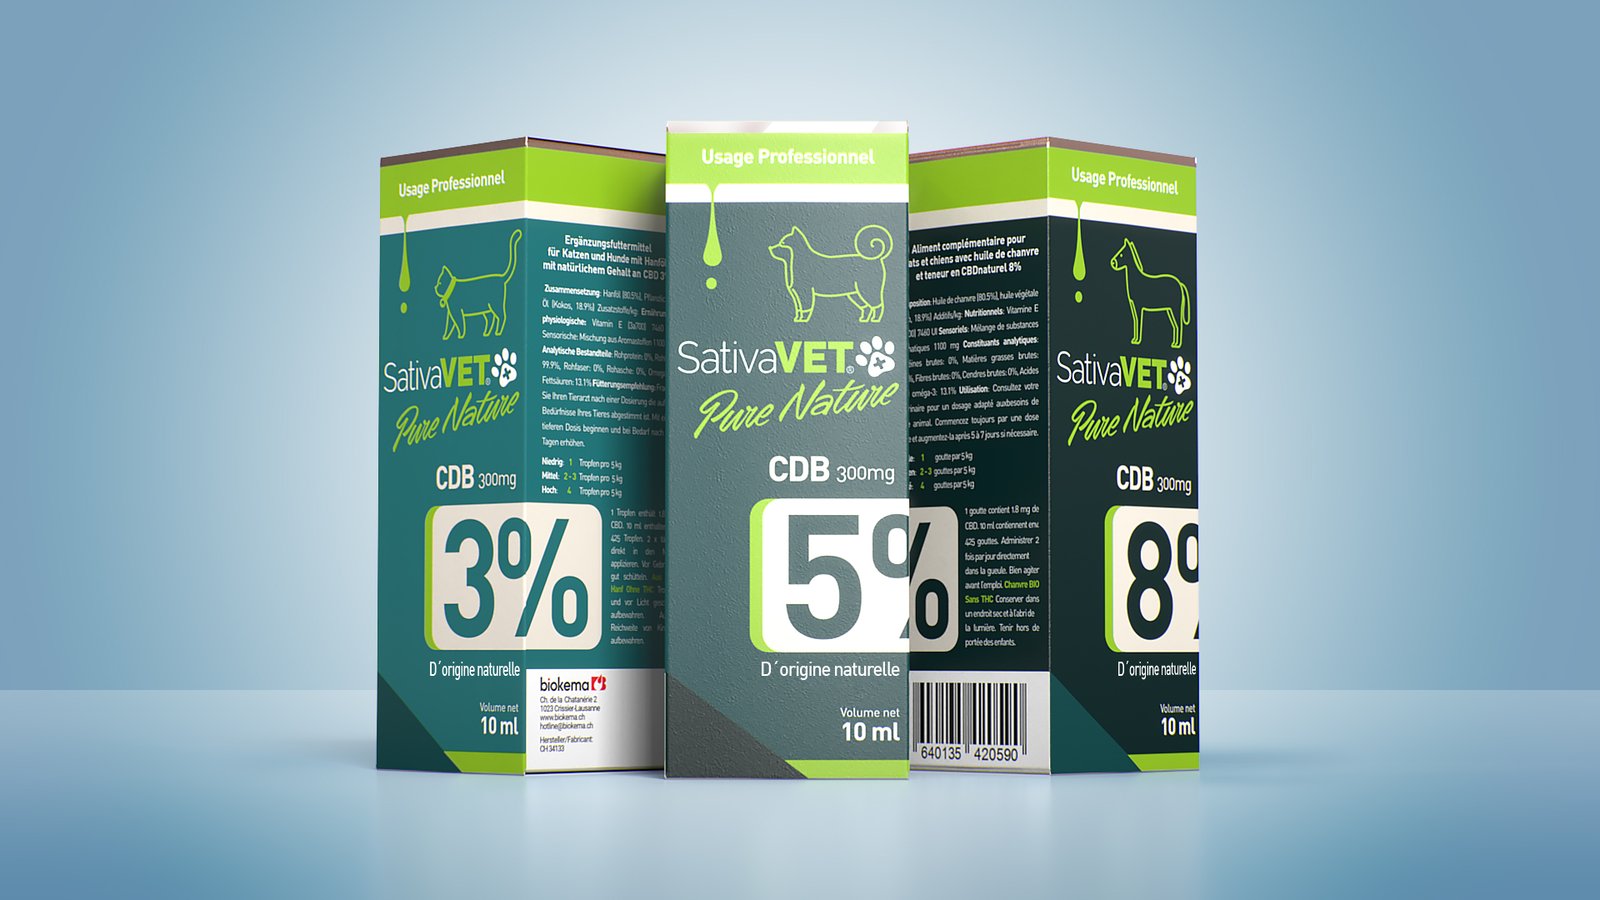
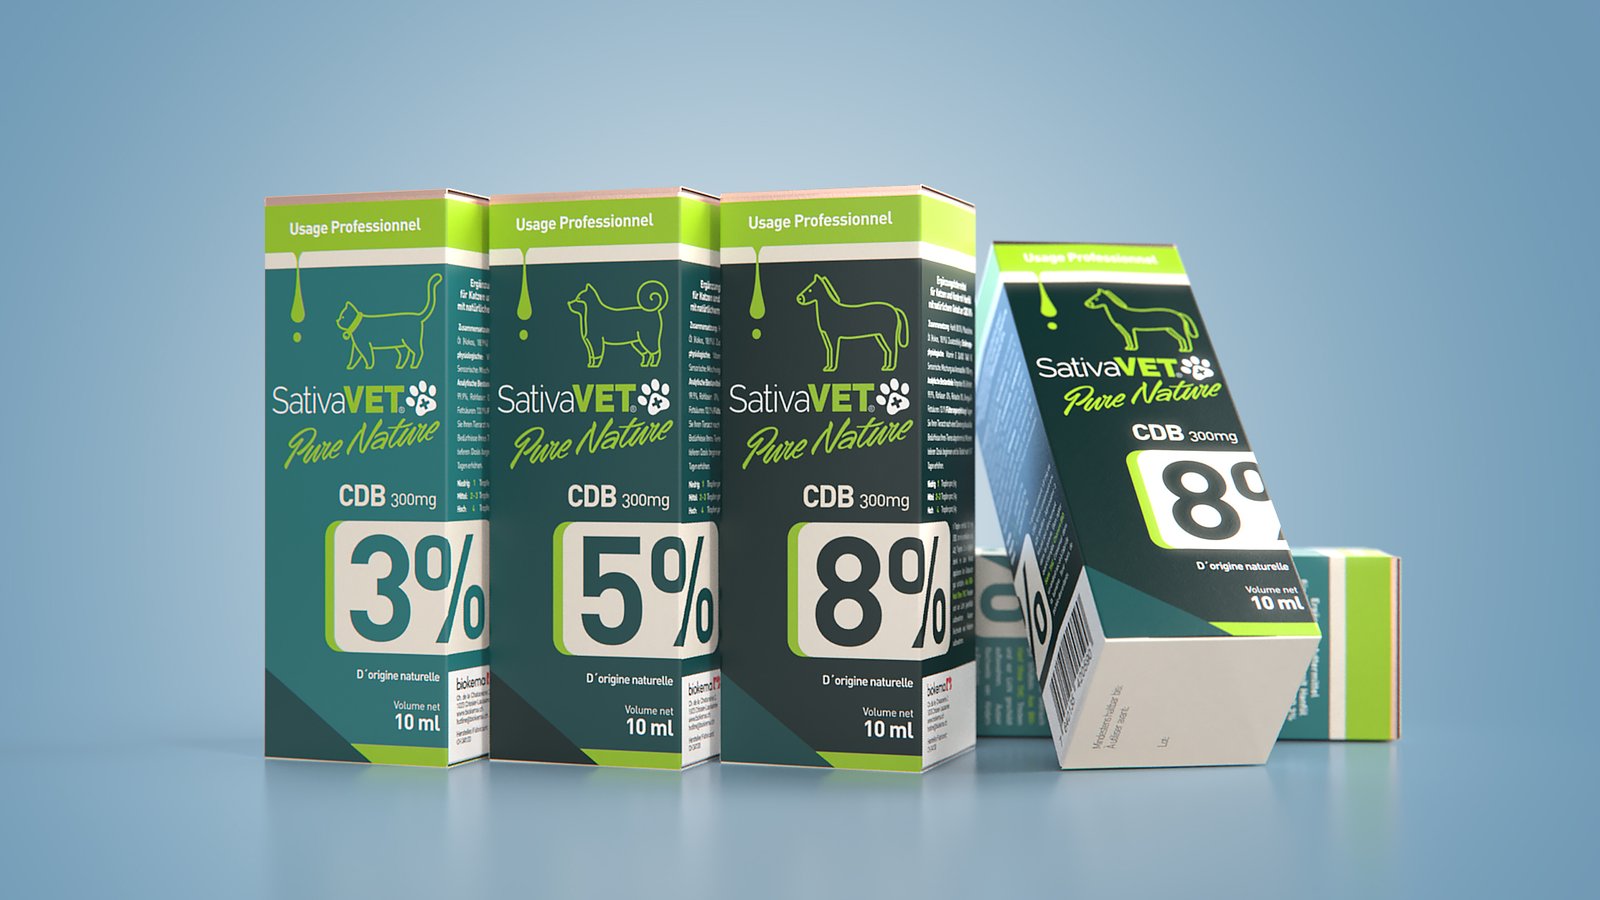
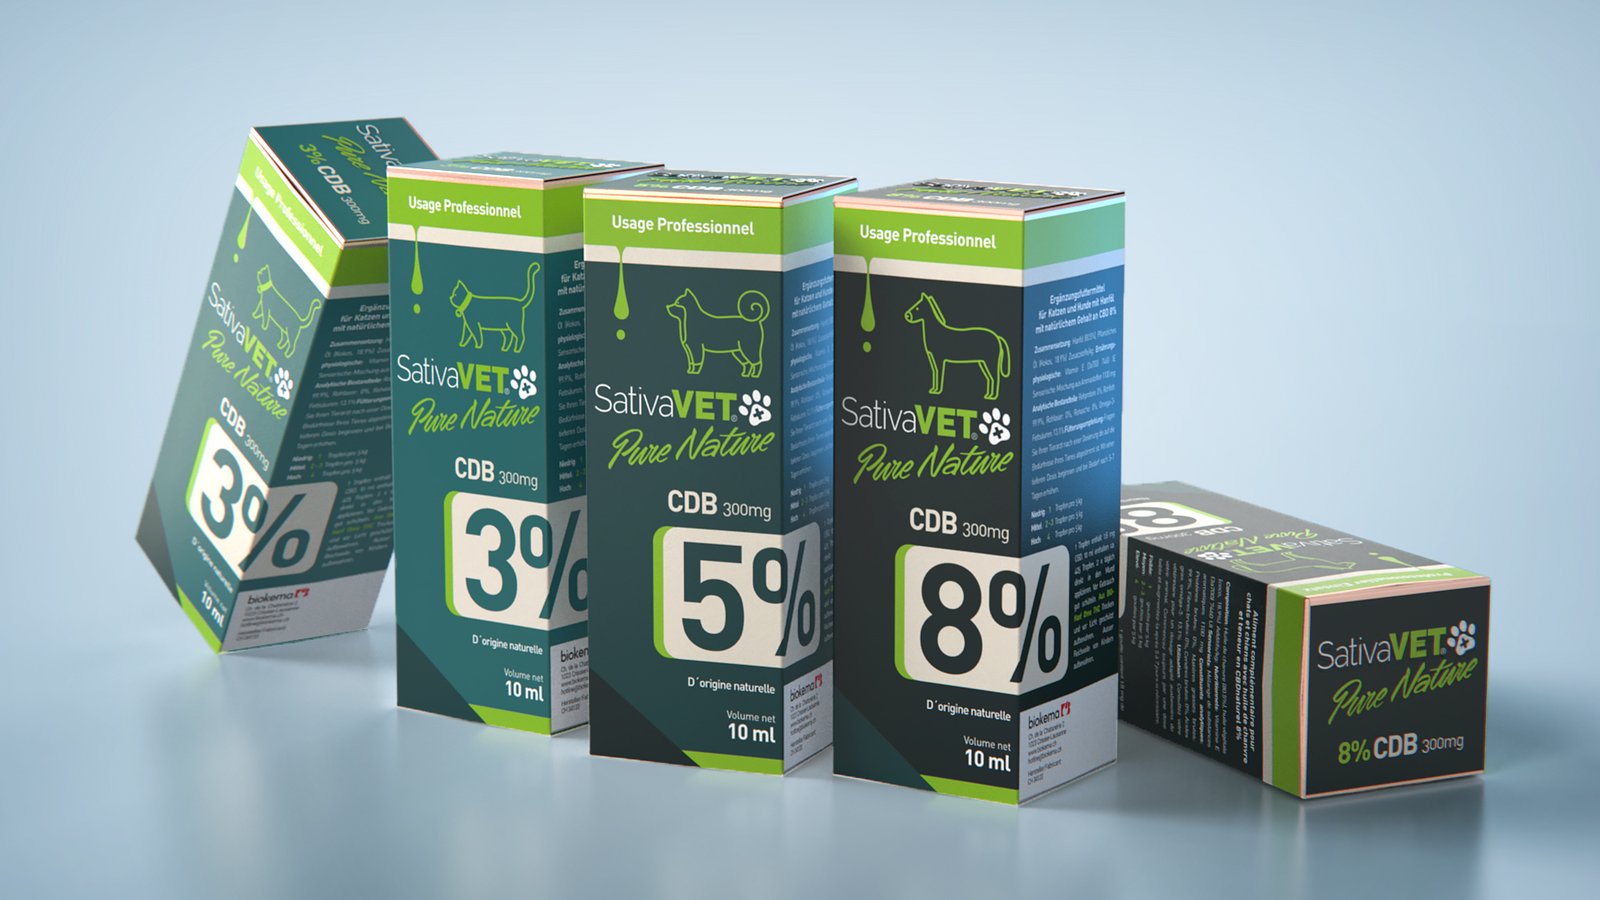
    The original Sativa Vet Pure Nature’s CDB Oil family was facing a strong sense of outdated design and part of the request was that the CDB percentage could be more easily read for pharmacists and clients.

    I presented a package design with a consistent green color palette keeping the brand’s original color intact and displaying large percentage numbers on the bottom half.

    The animals icons and the liquid drop were symbols and icons requested to be present on the redesign as well.

    I added a hint of metallic finish on the top lip, as a golden stripe, to call the attention and contribute for a more premium finish, borrowing a sense of higher quality to the product overall.

    CLIENT

    SATIVA VET (Switzerland)

    PROJECT SCOPE

    PACKAGE DESIGN
    PRODUCT VISUALIZATION
    3D RENDERING
    MOCKUP

    SOFTWARE

    MAYA
    PHOTOSHOP
    AFFINITY DESIGNER
    KEYSHOT

  • Z-Image Prompt Assist

    Z-Image Prompt Assist

    Z-Image Prompt Assist

    Benchmark comparison chart of all aesthetics offered via “PASS” and how Z-IMAGE failed most of them.

    comfyui

    generative ai

    Comparison

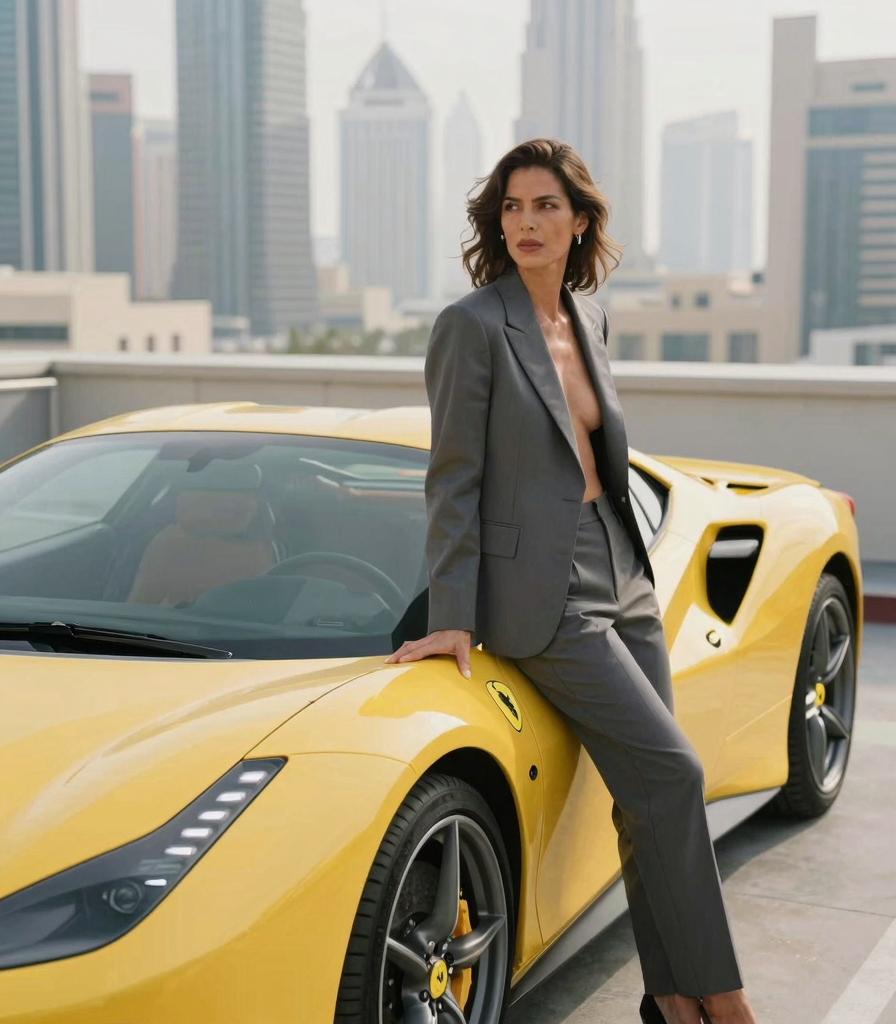
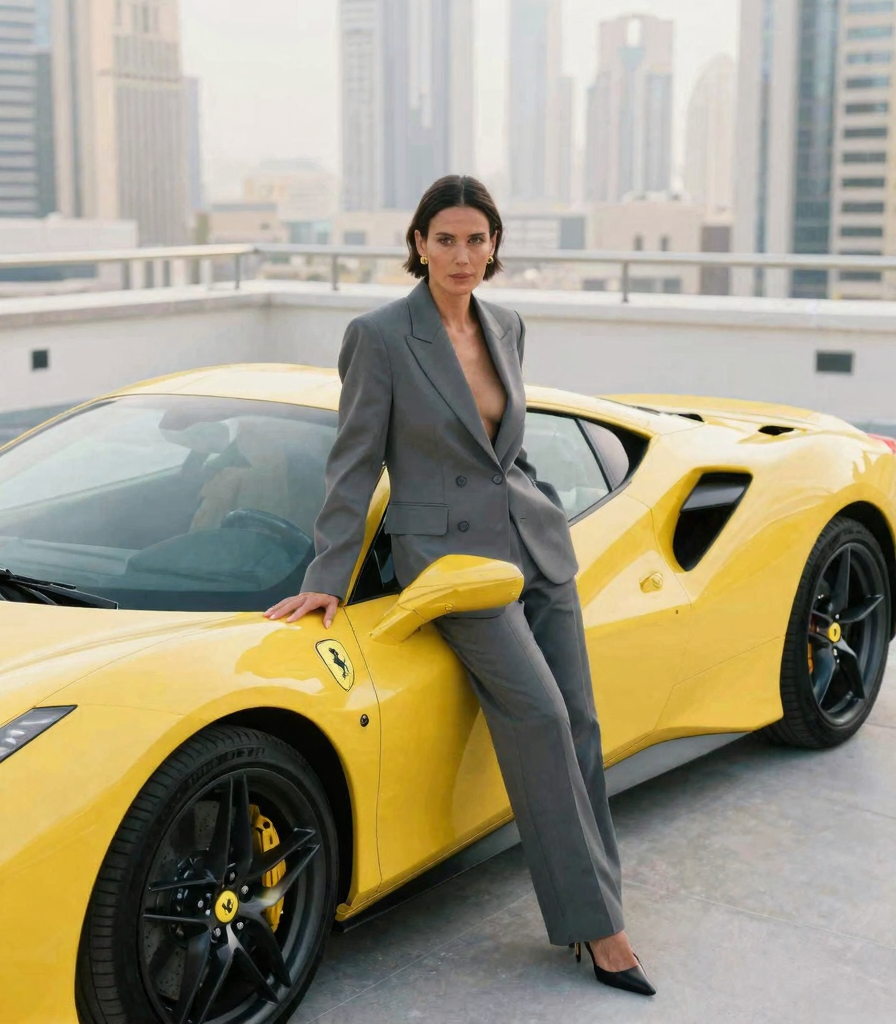
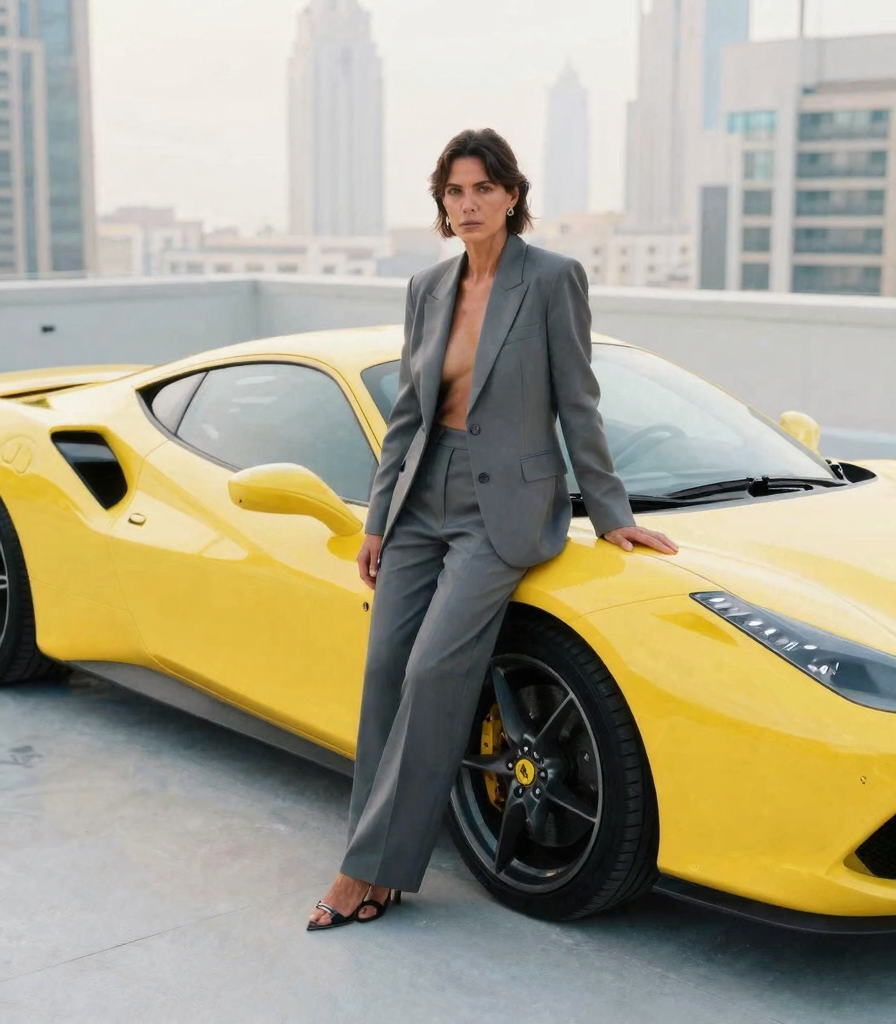
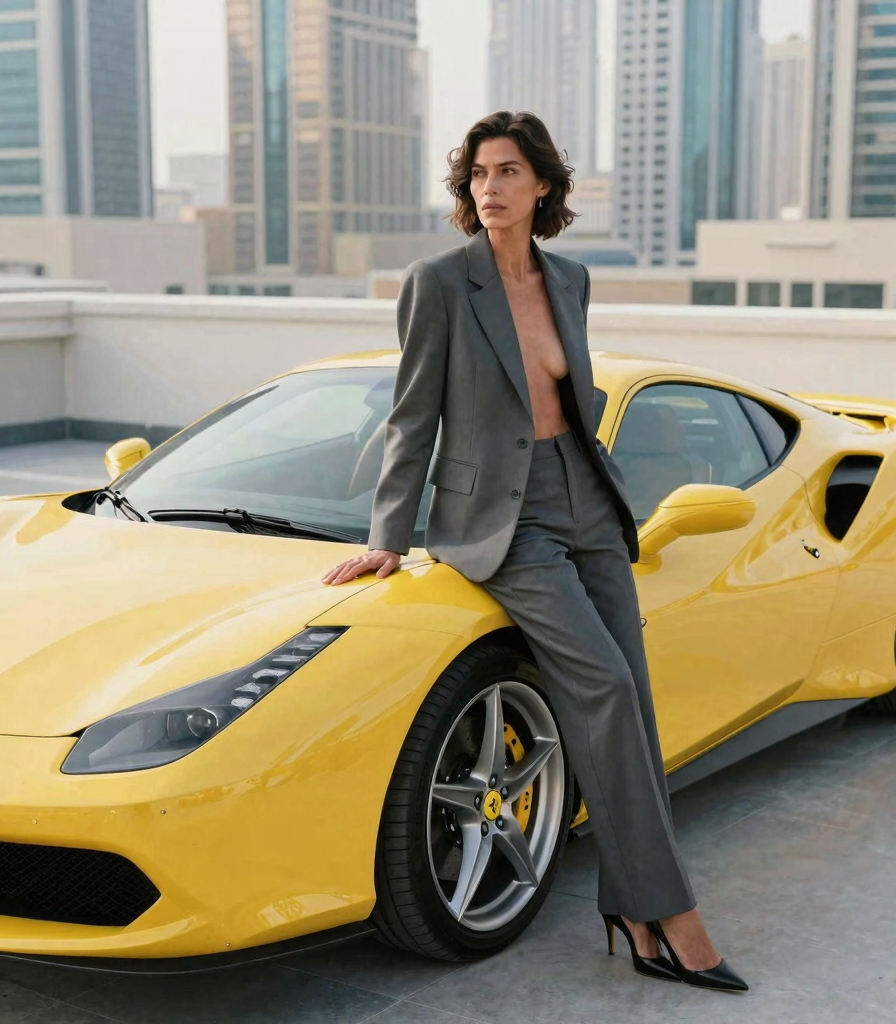
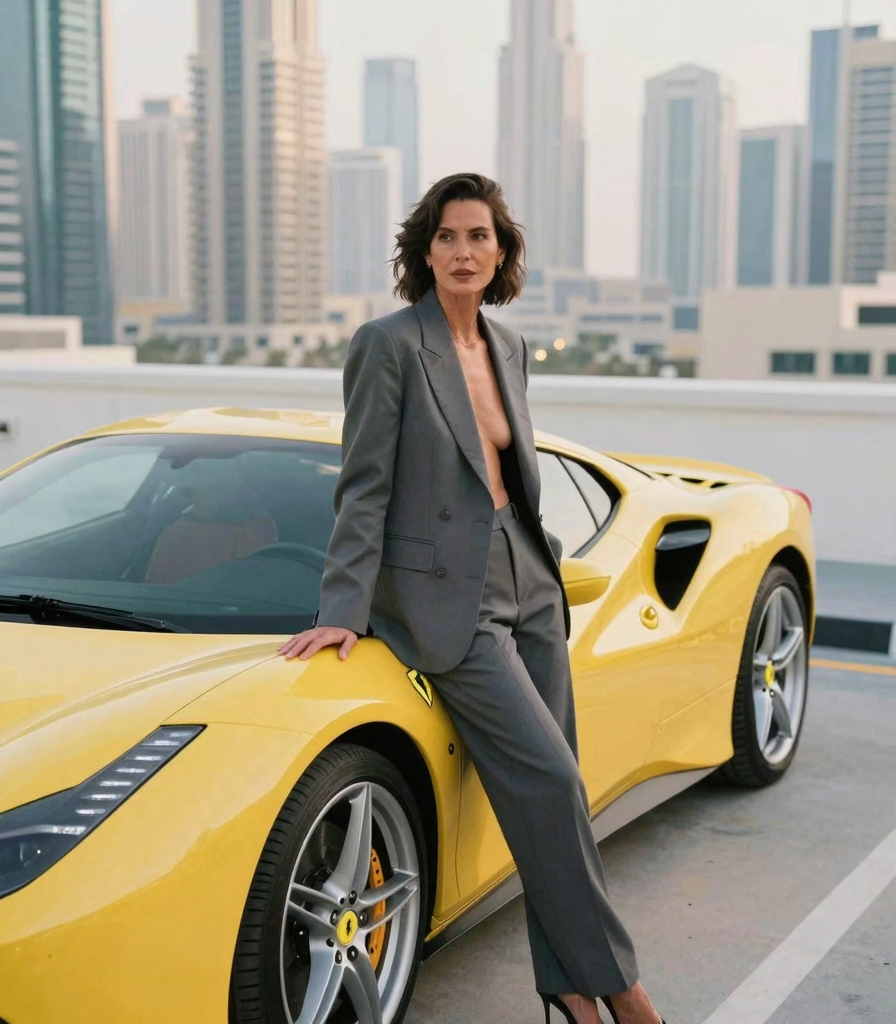
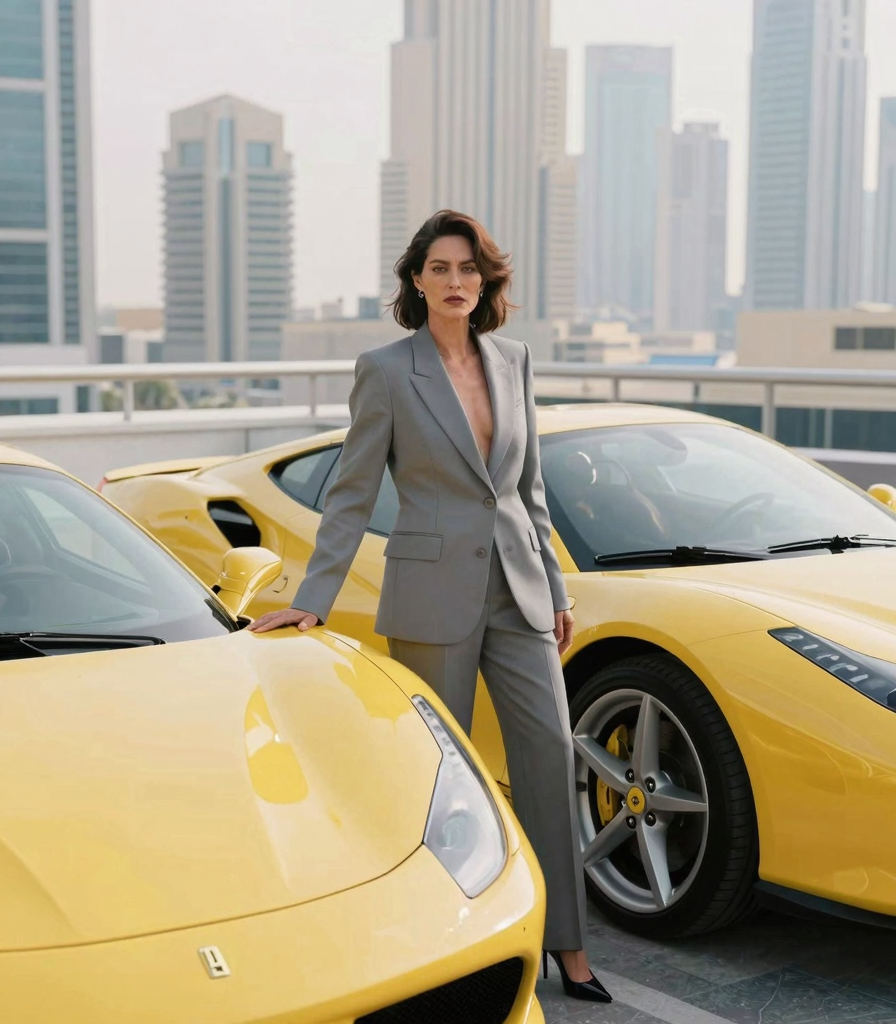
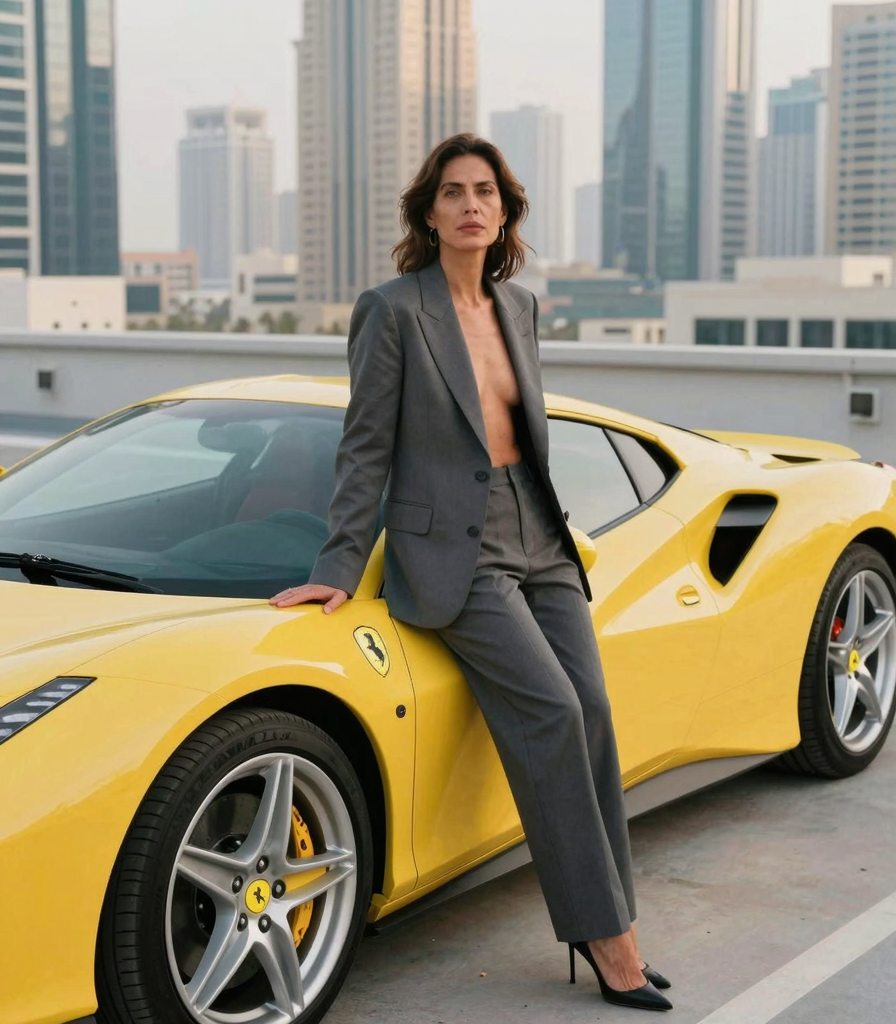
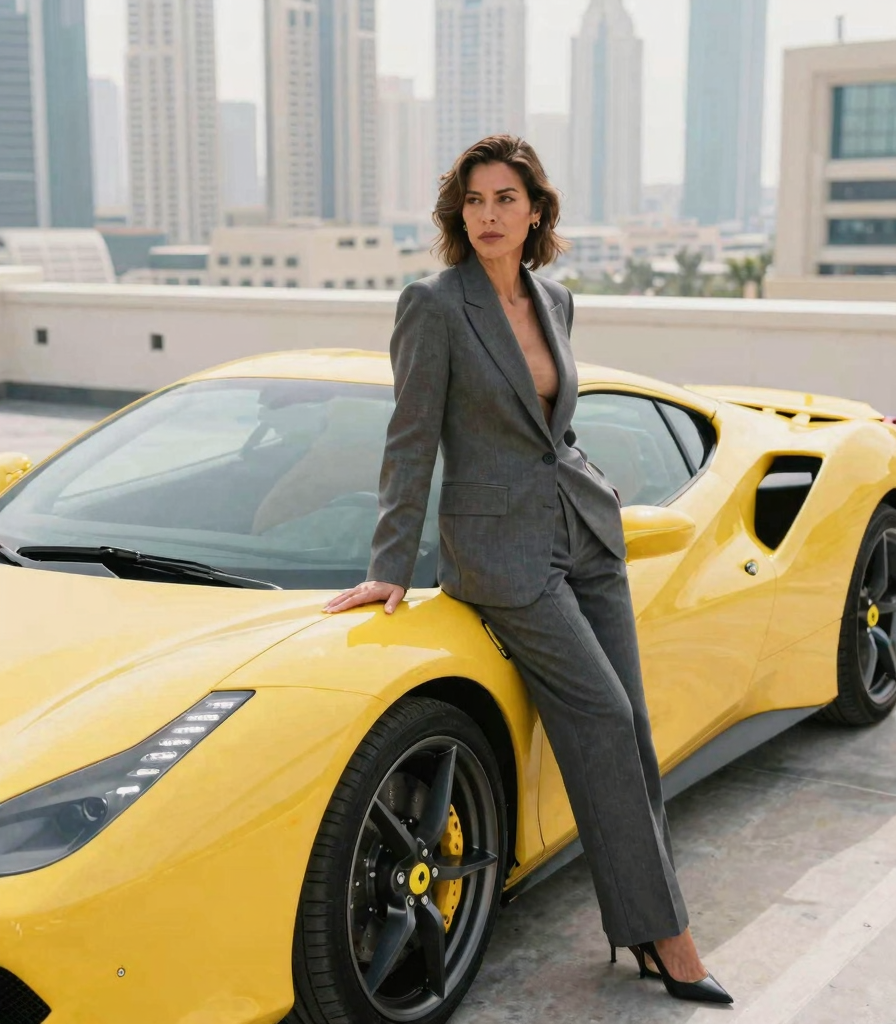
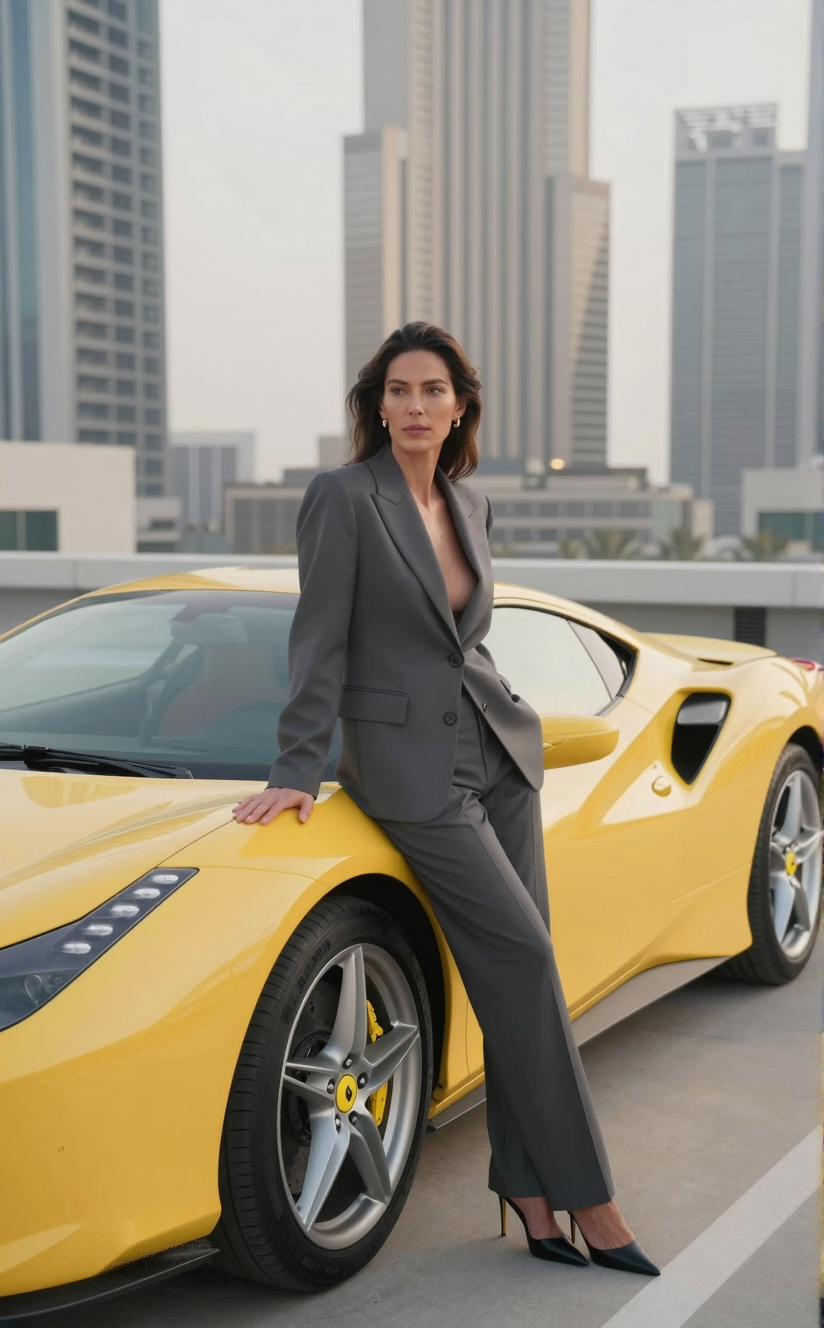
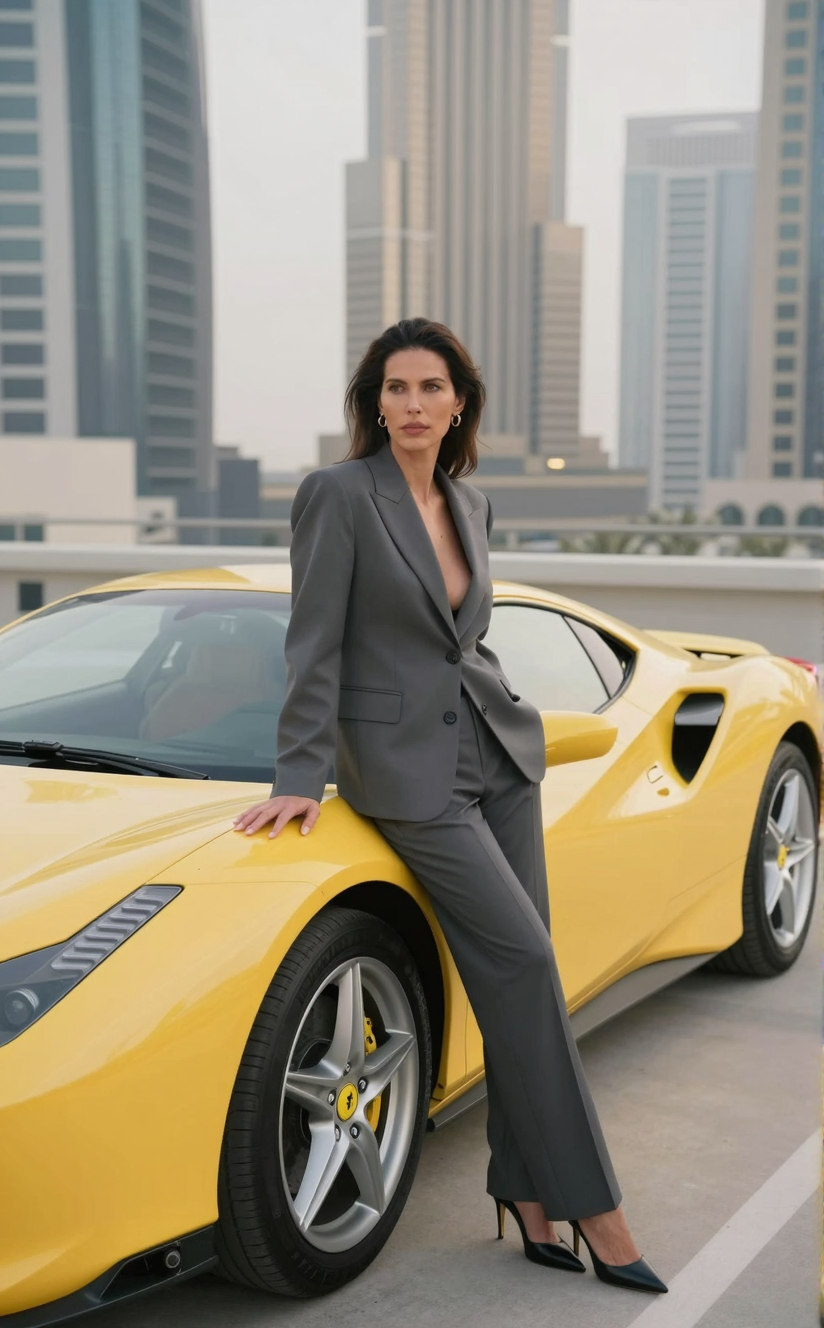
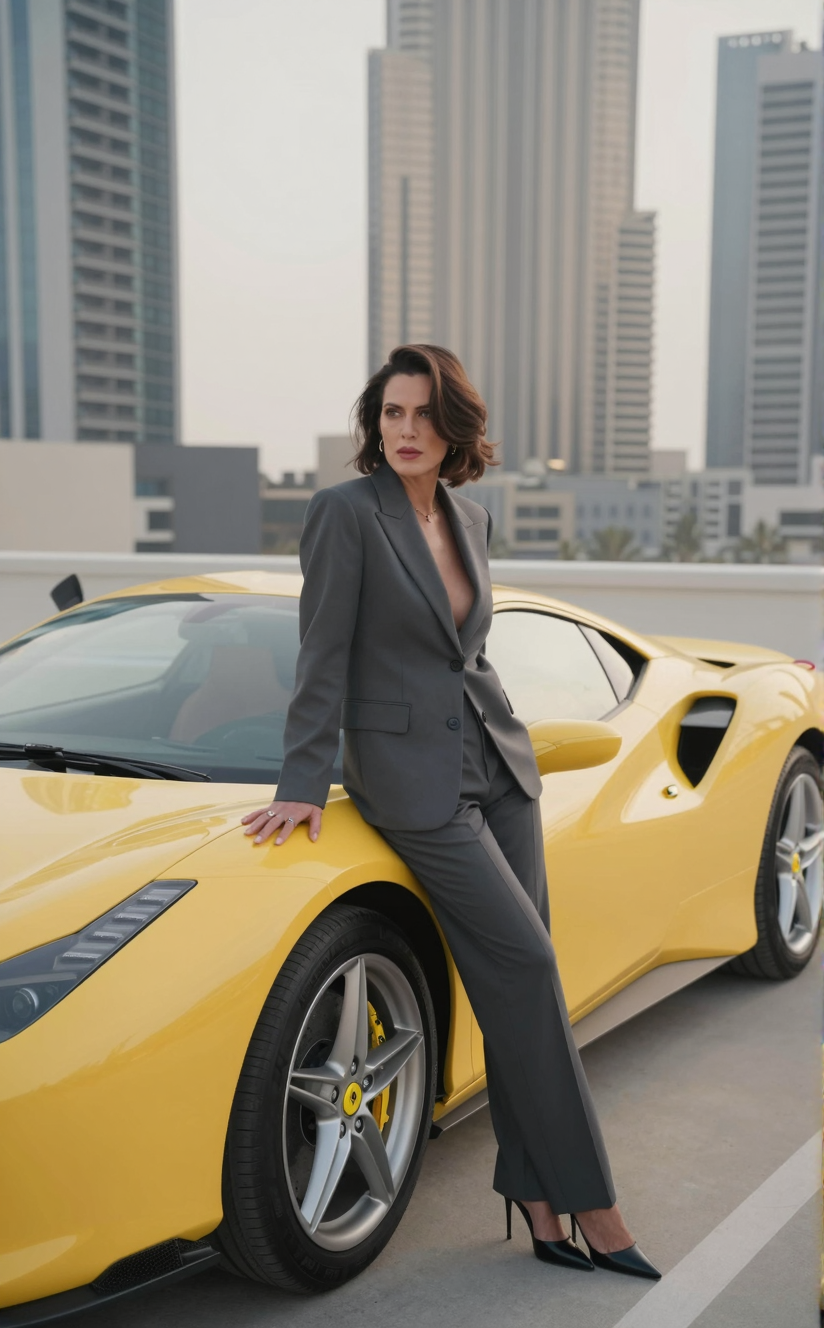
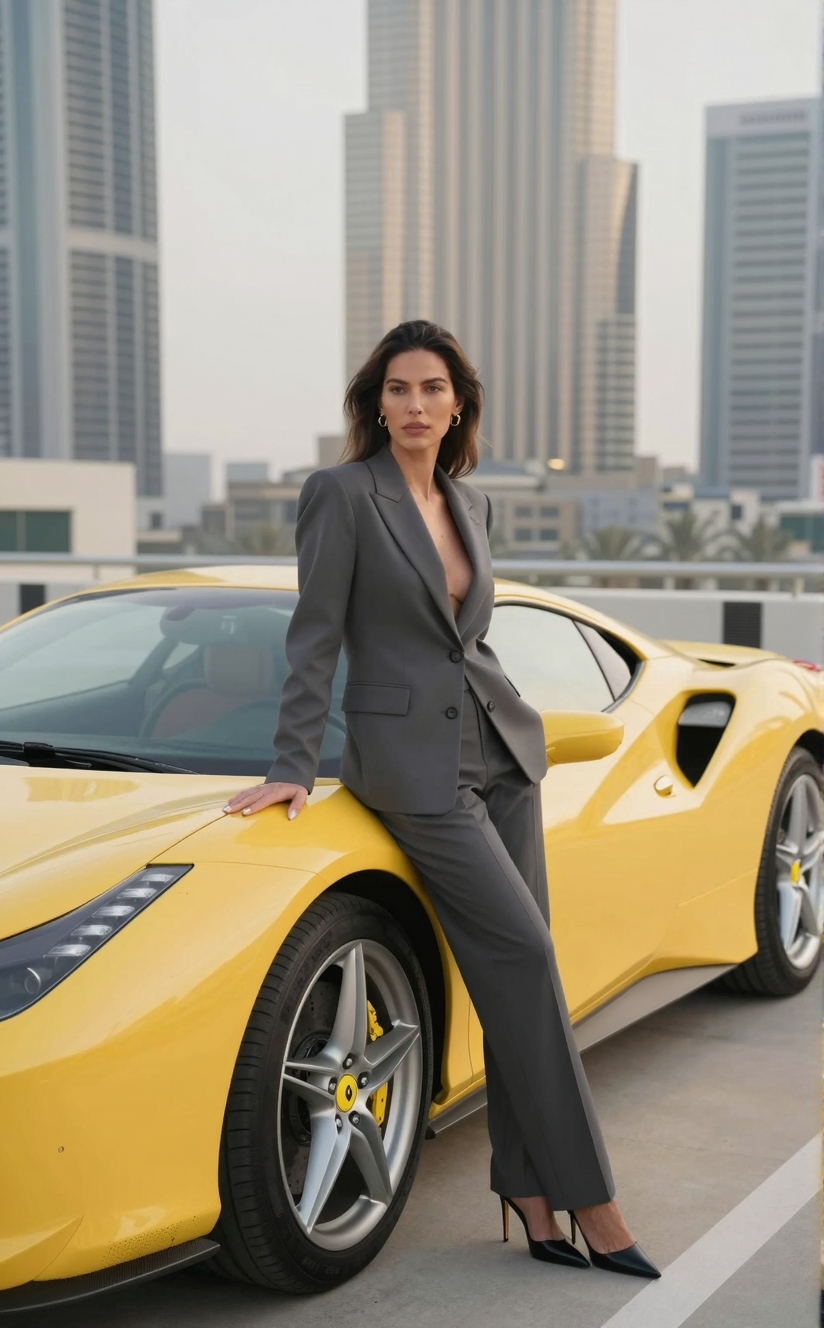
    This is a comparison benchmark running Z-Image Turbo model testing the various Genre options found in my latest toll Prompt Assistant v1.1, affectionately nicknamed PASS.

    For the sake of testing purposes, I am using exactly the same prompt, same seed, the same sampler, same scheduler and same resolution of 824 x 1328 ( 1536 x 2048 would have been ideal ). The only change will be on the initial aesthetic value that will be note on each image caption.

    I hope this comparision can be somewhat useful to understand what genre means in generative art. You are invited to play around with the PASS tool and use to guide your future generations with JSon and Long string text outputs ready to be copied and pasted nto your workflow.

    Z-Image using Sampler DMPP_SDE + Scheduler BETA
    Z-Image using DMPP_SDE + BETA
    Z-Image using Sampler DMPP_SDE + Scheduler BETA
    Z-Image using EULER_ANCESTRAL + DDIM UNIFORM

    Prompt to be used

    				
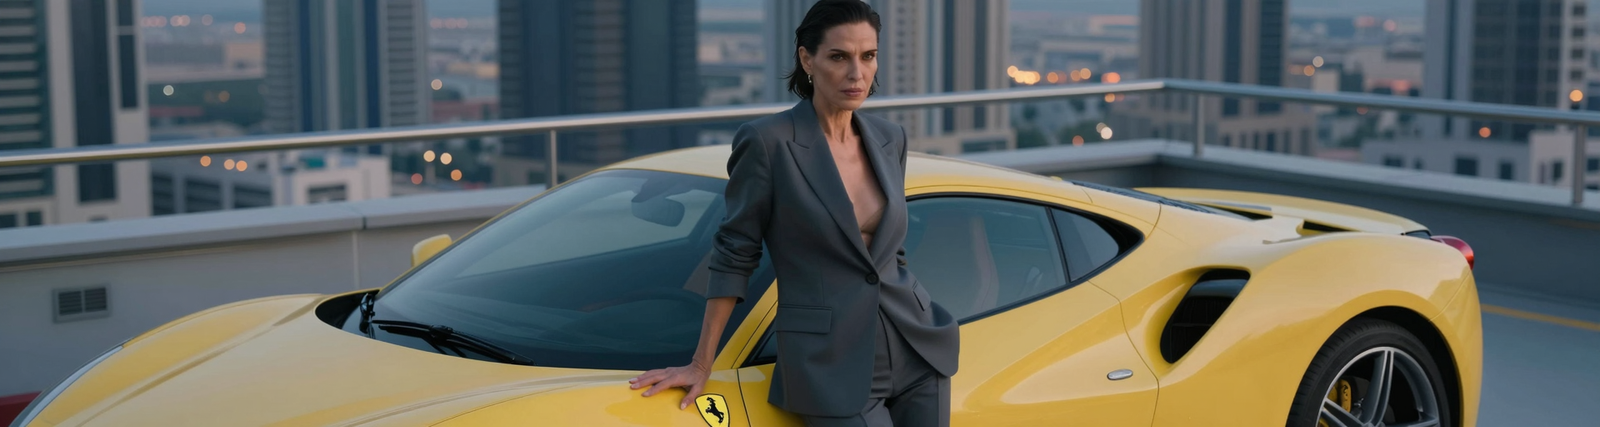
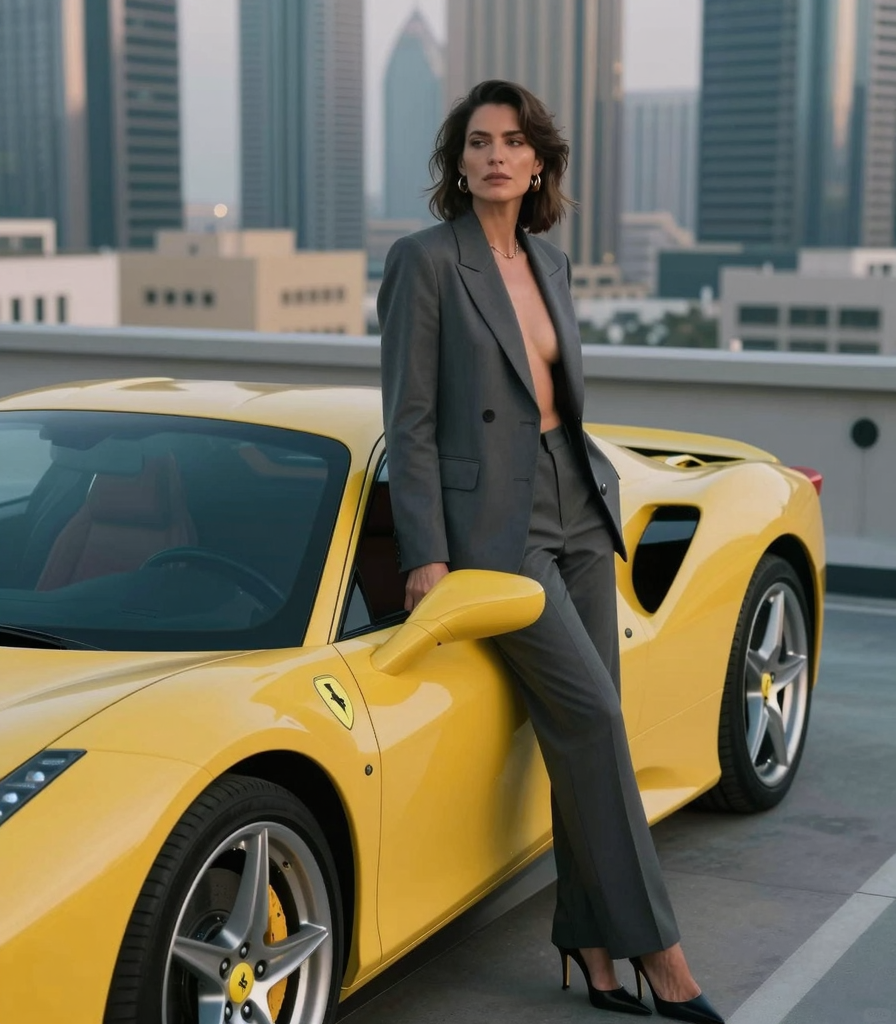
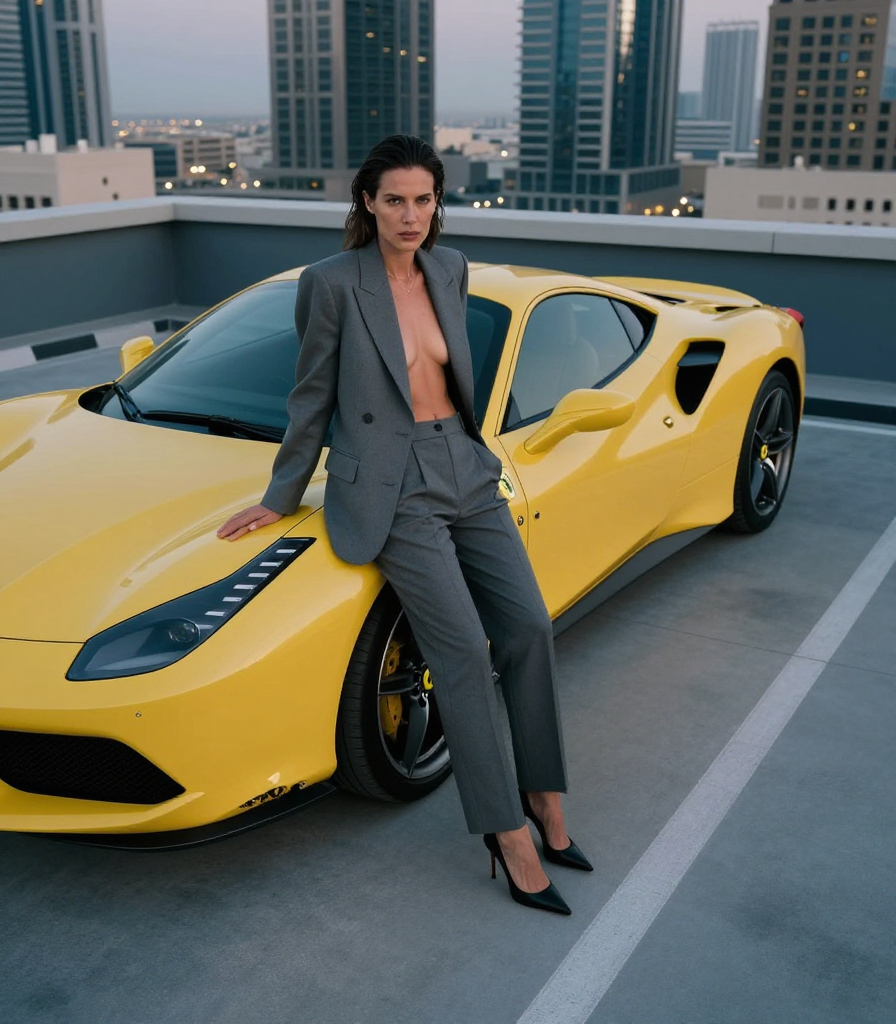
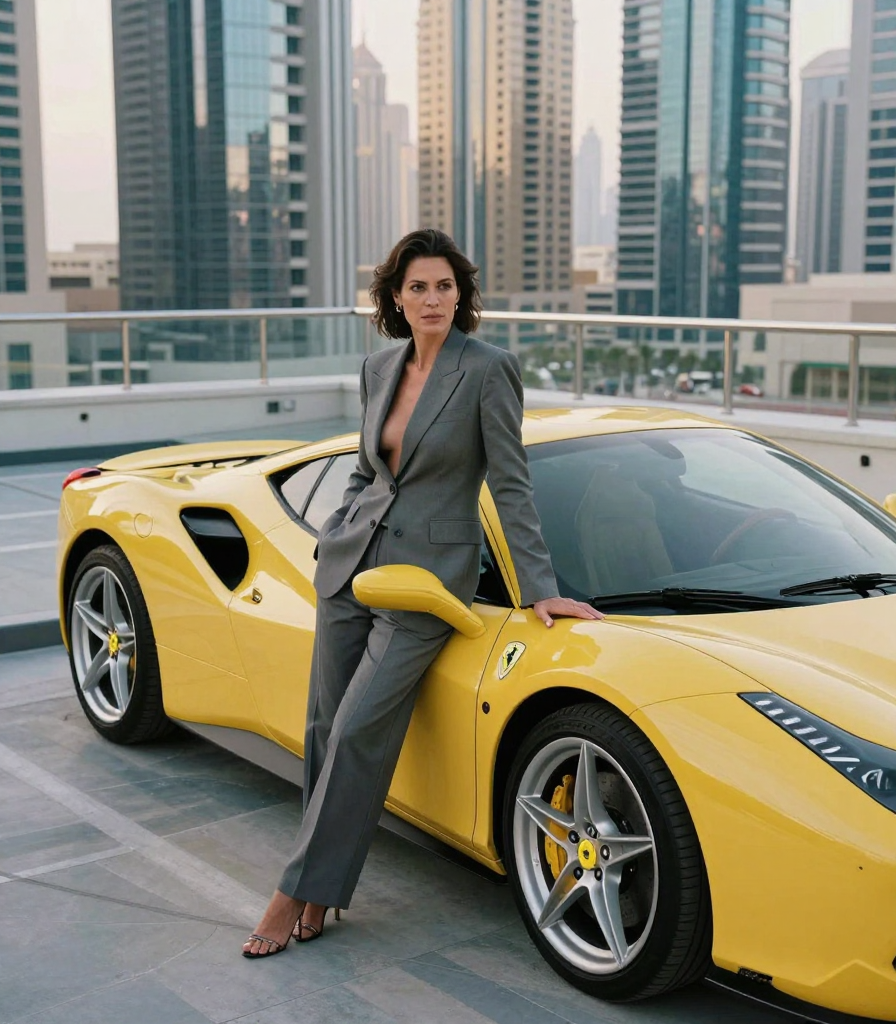
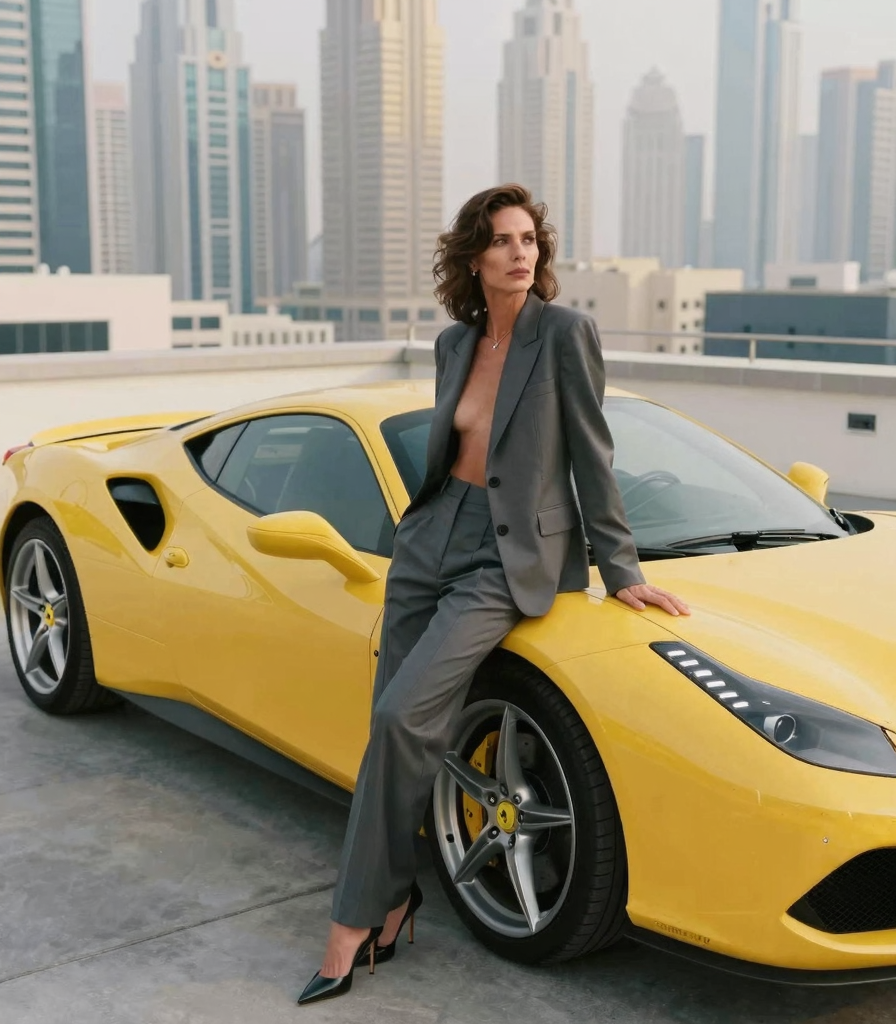
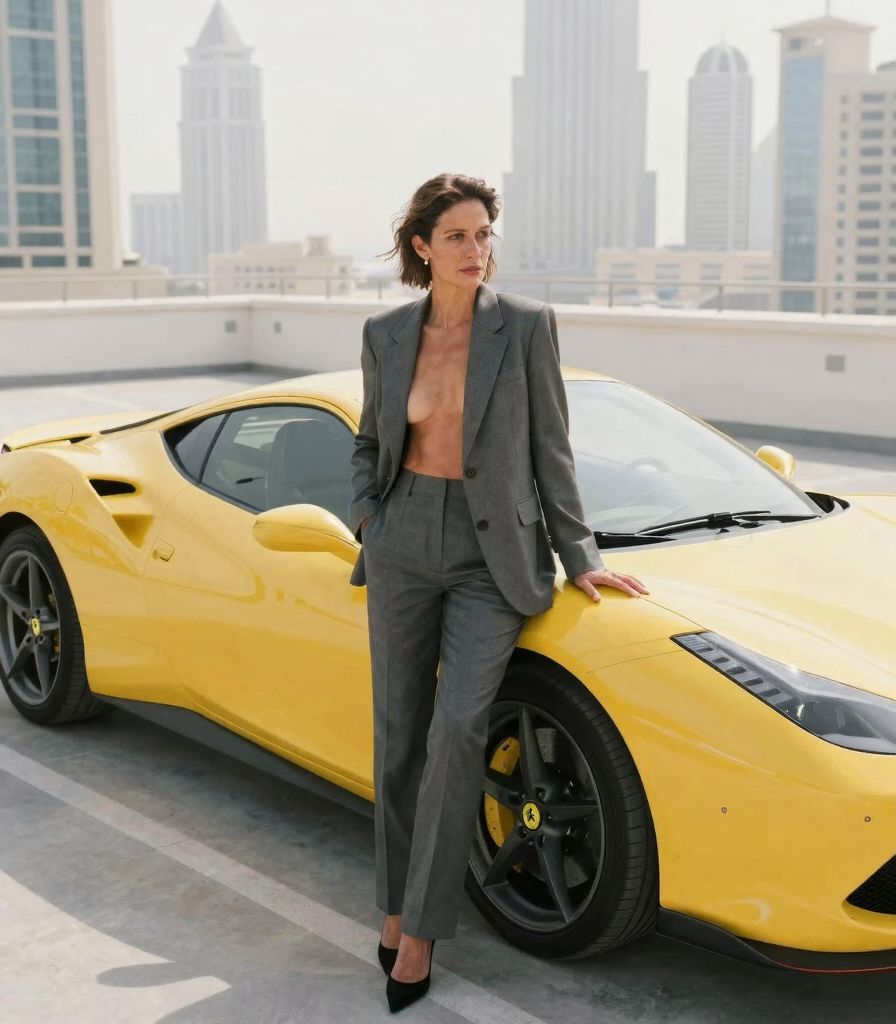
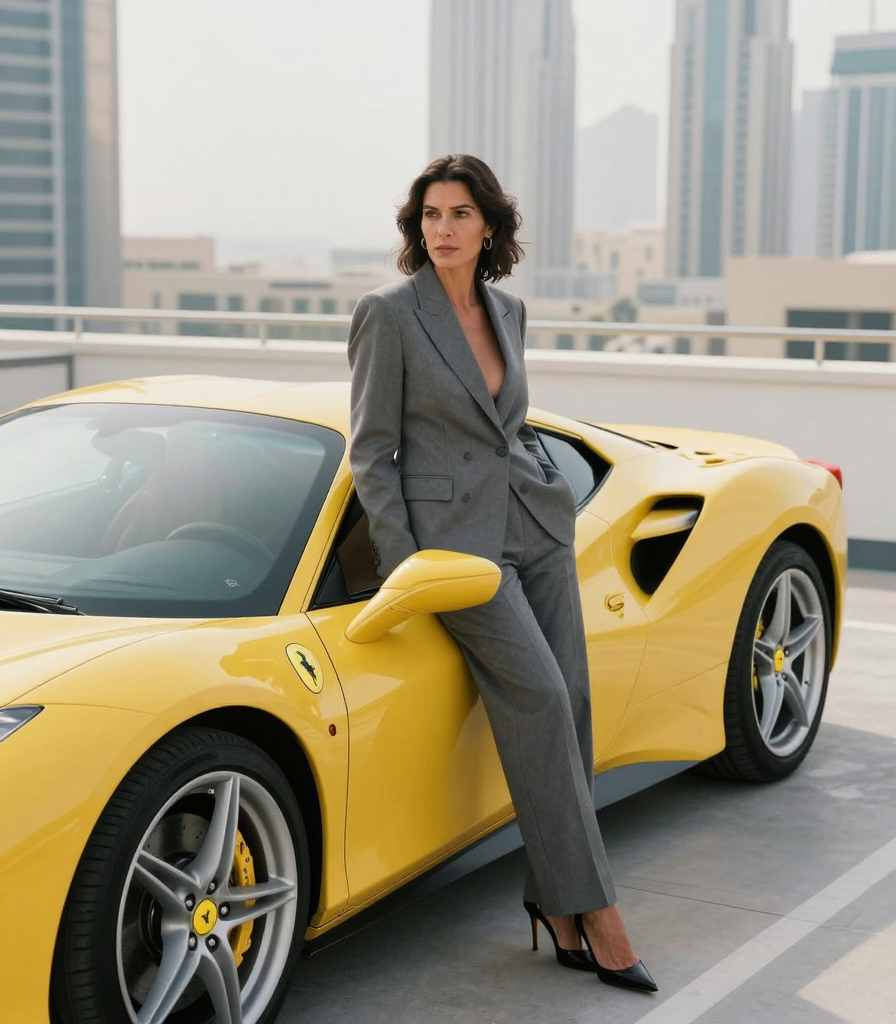
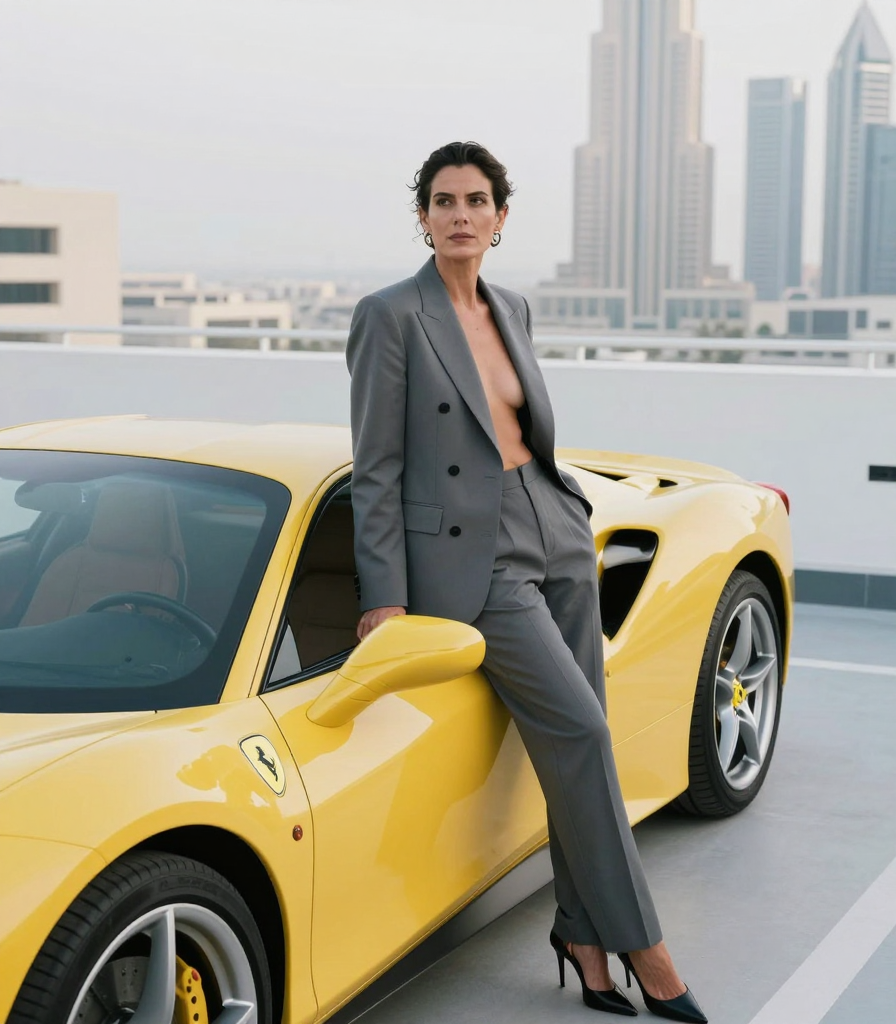
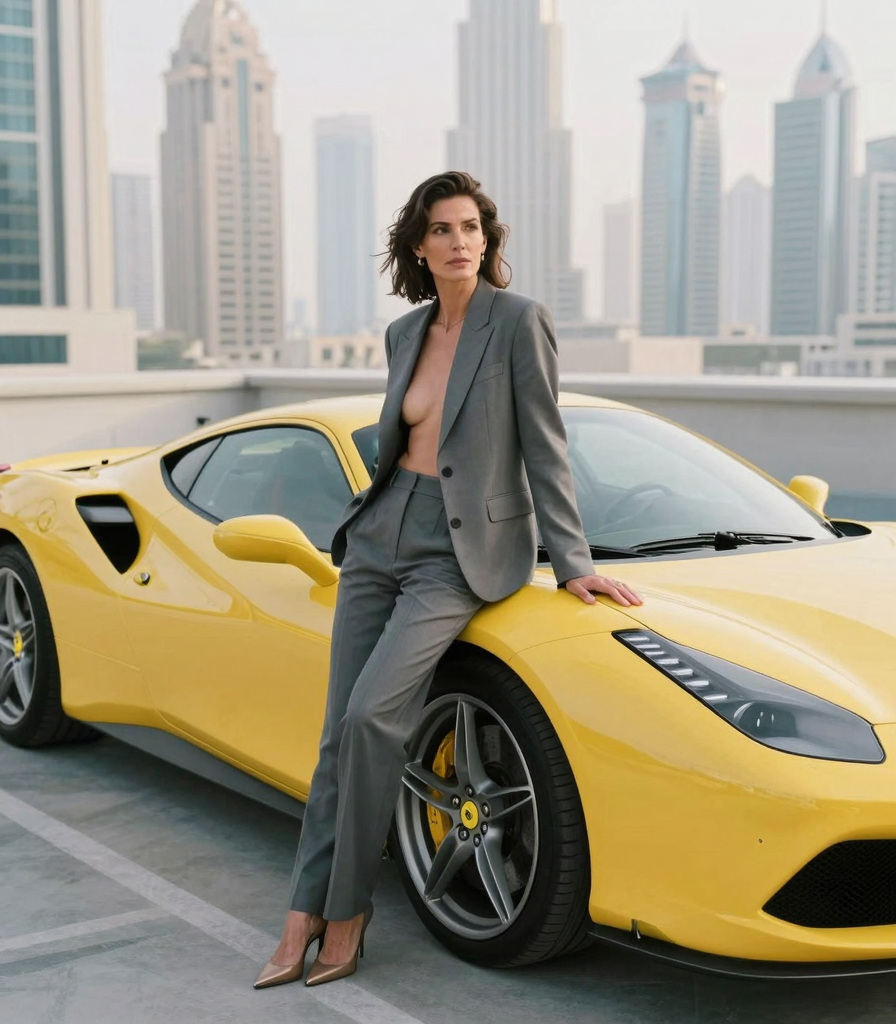
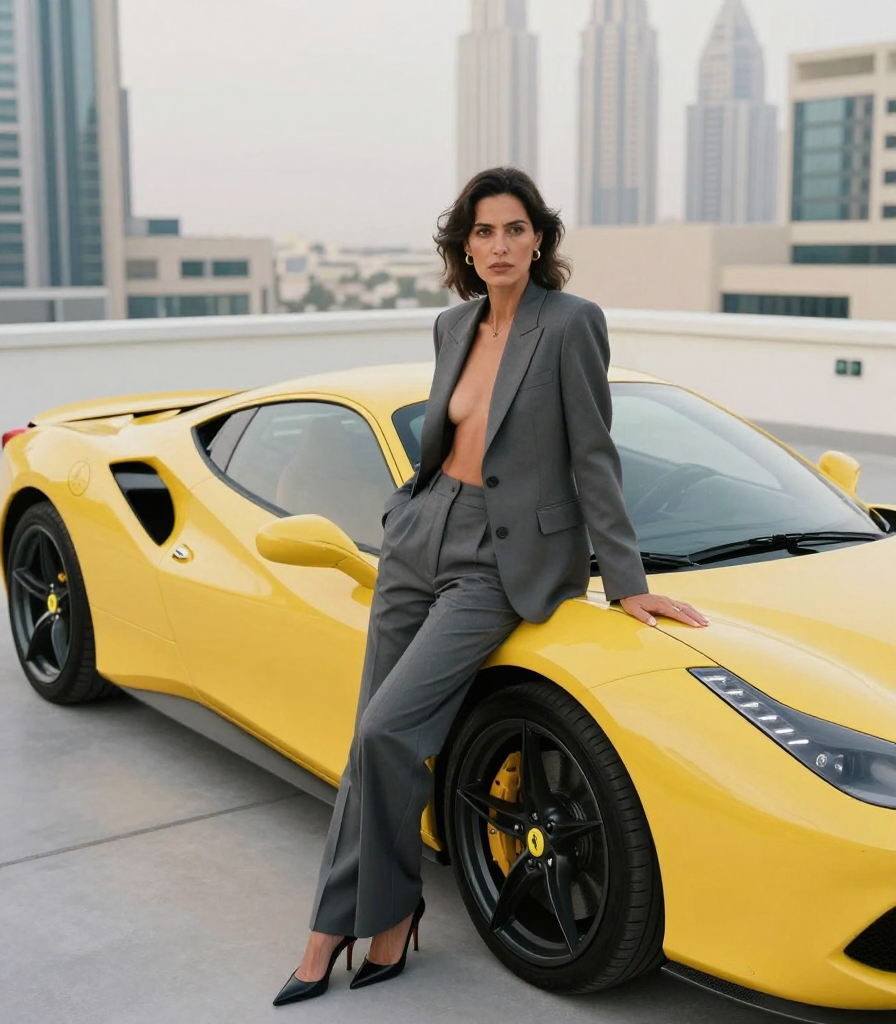
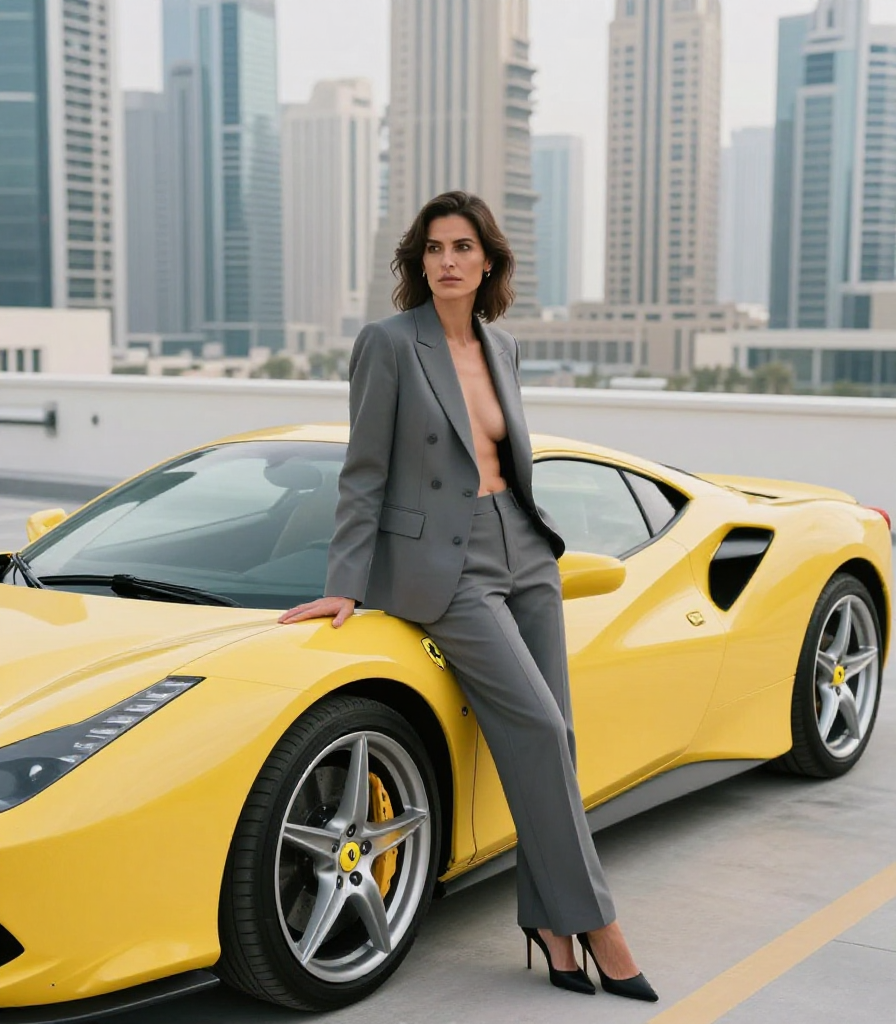
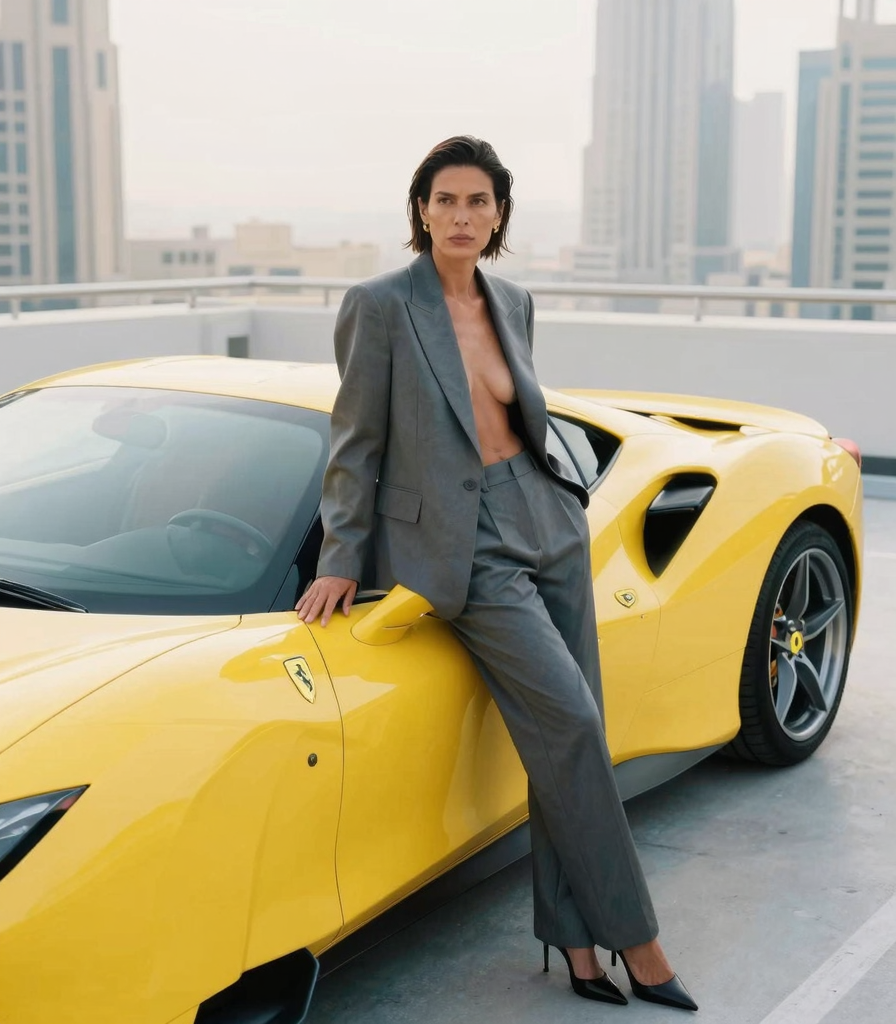
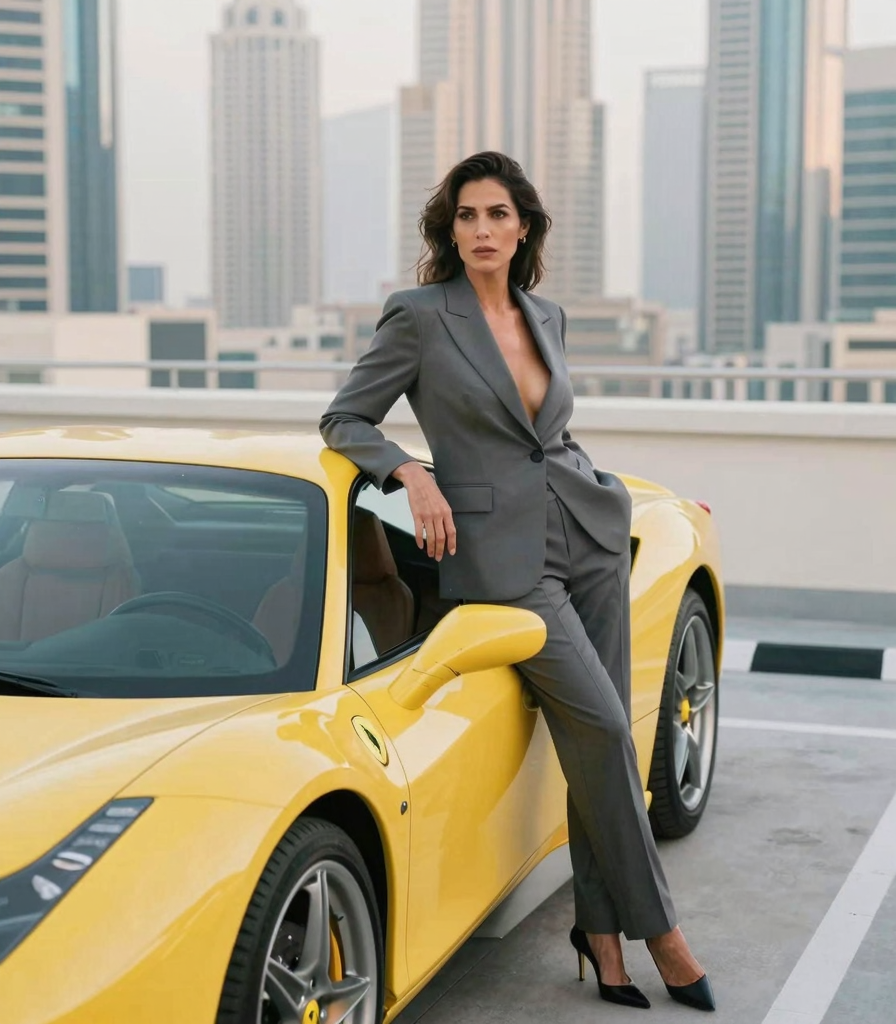
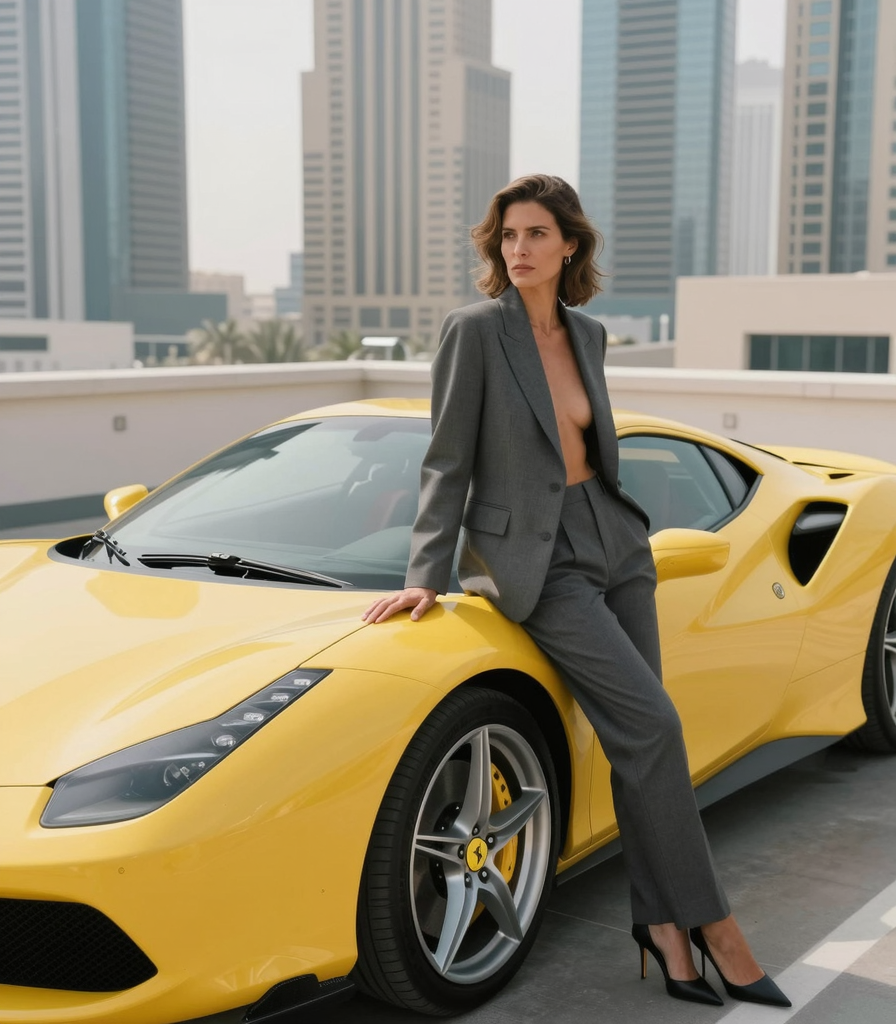
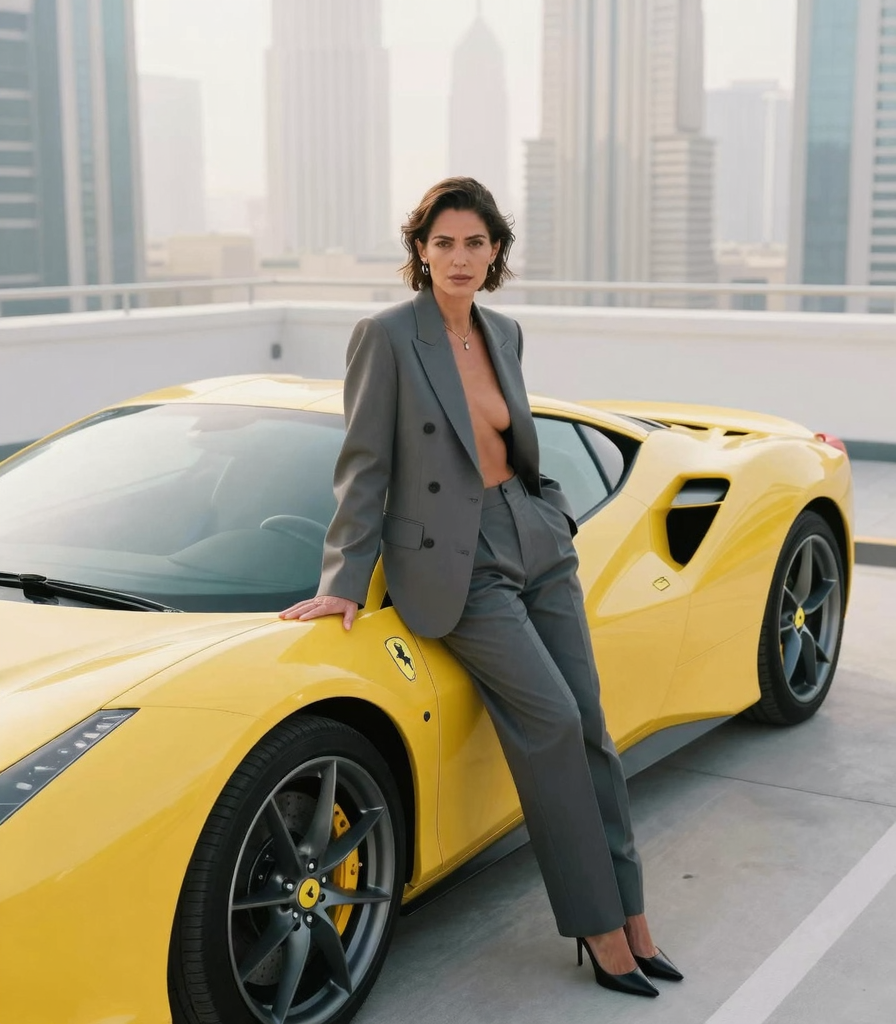
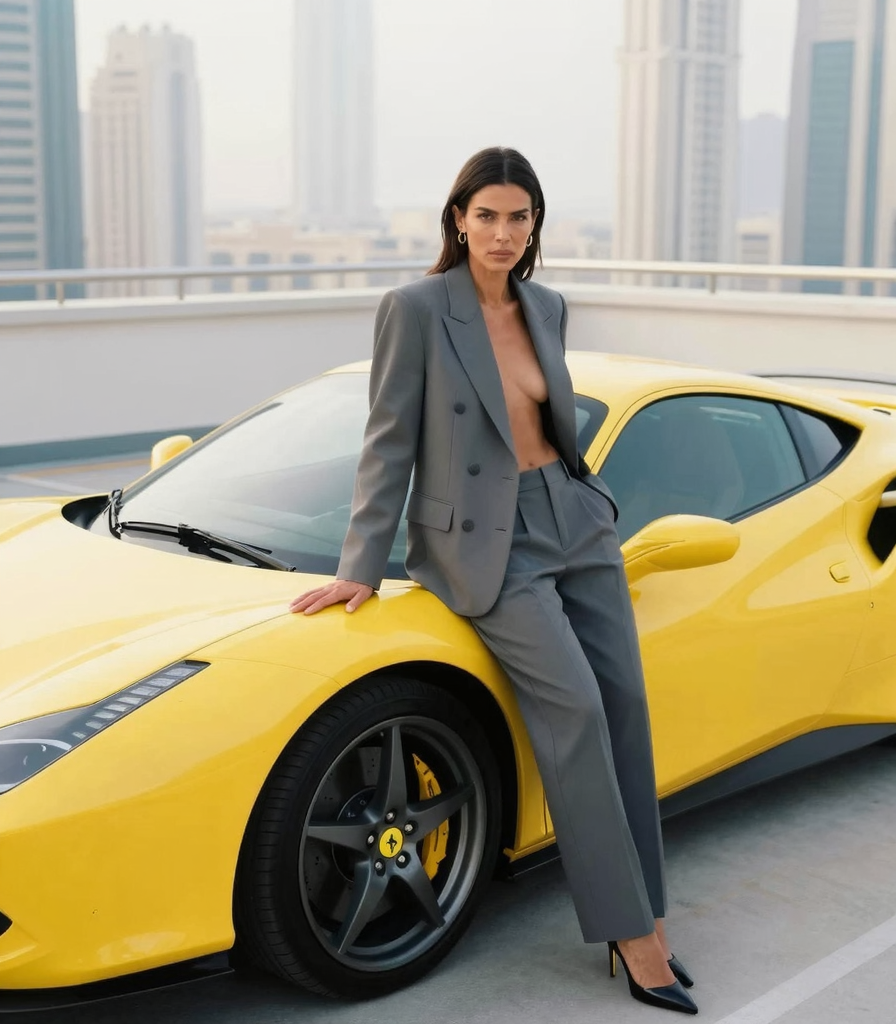
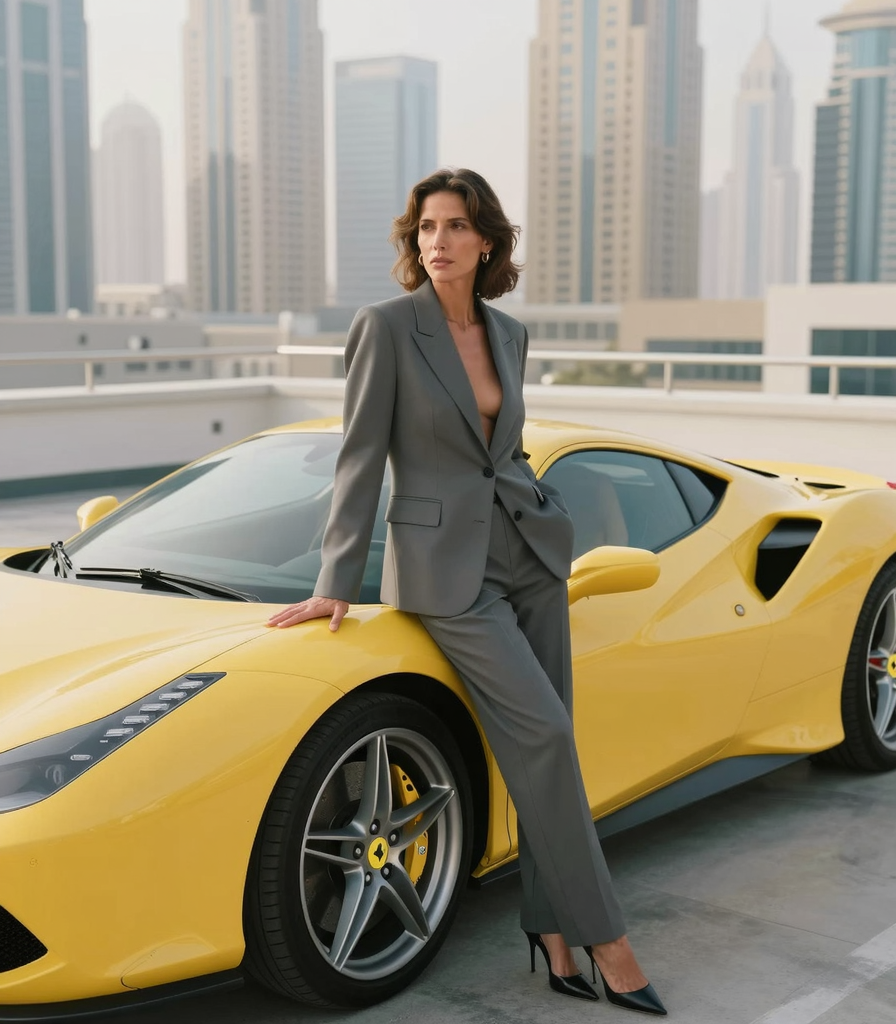
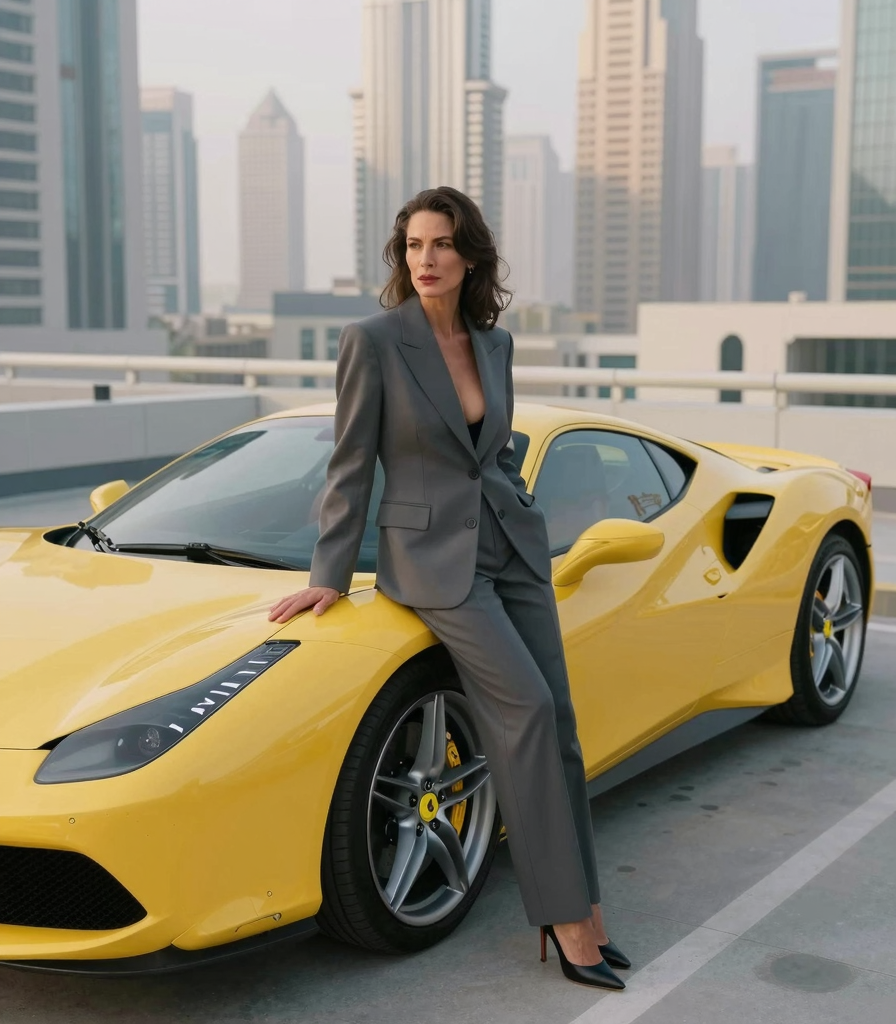
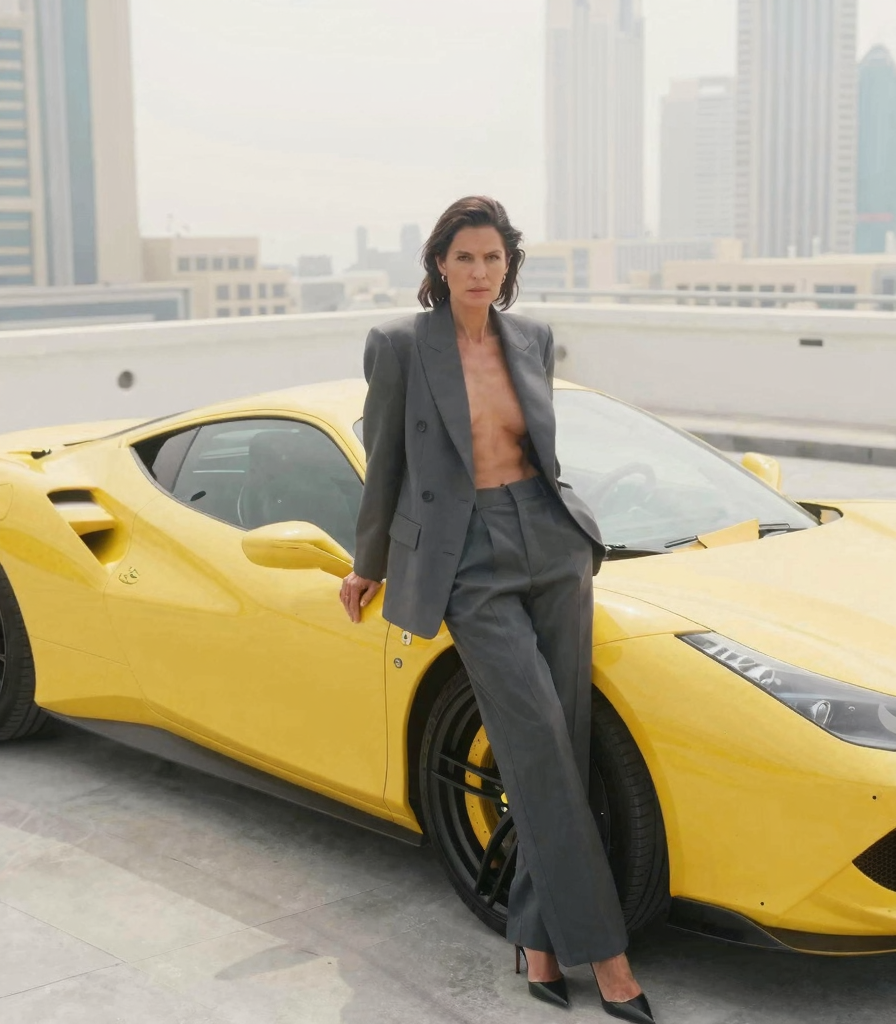
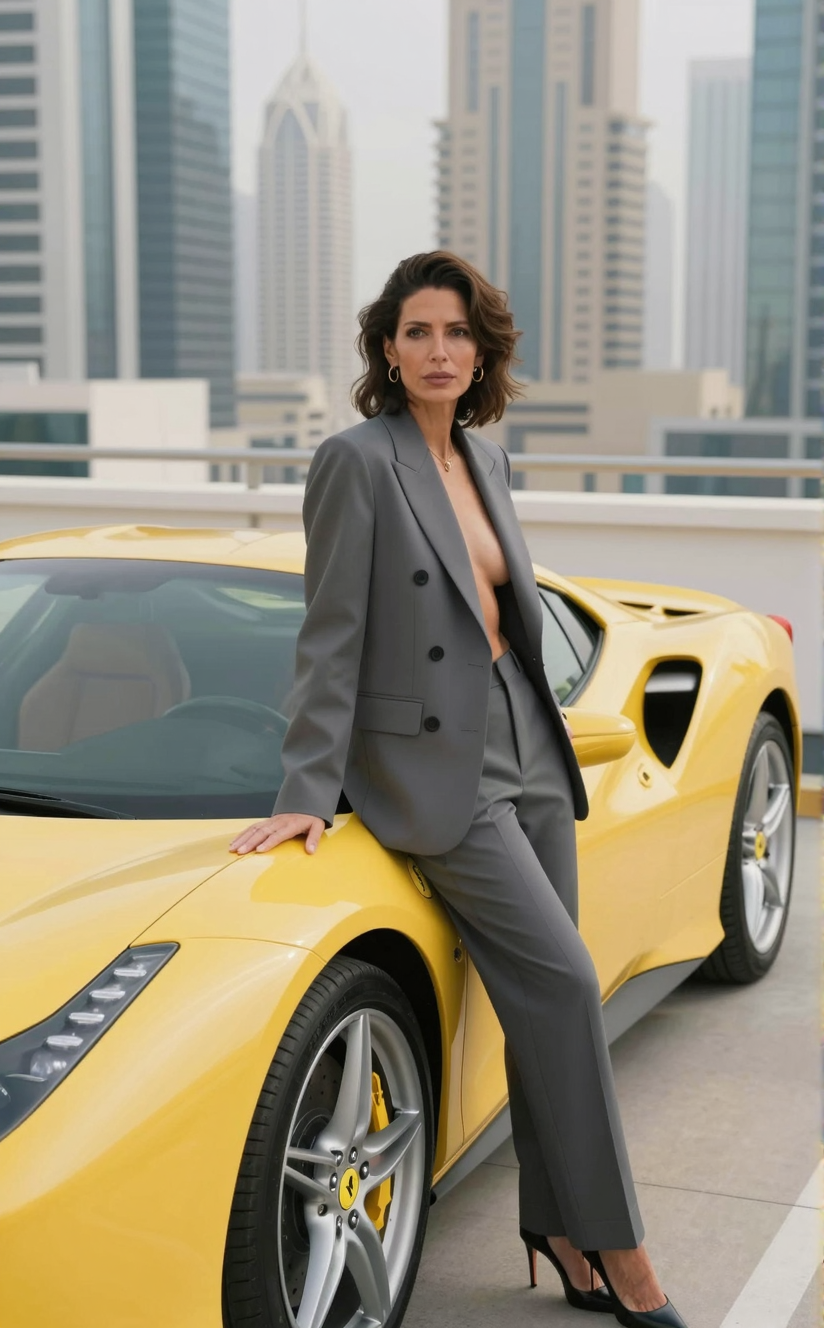
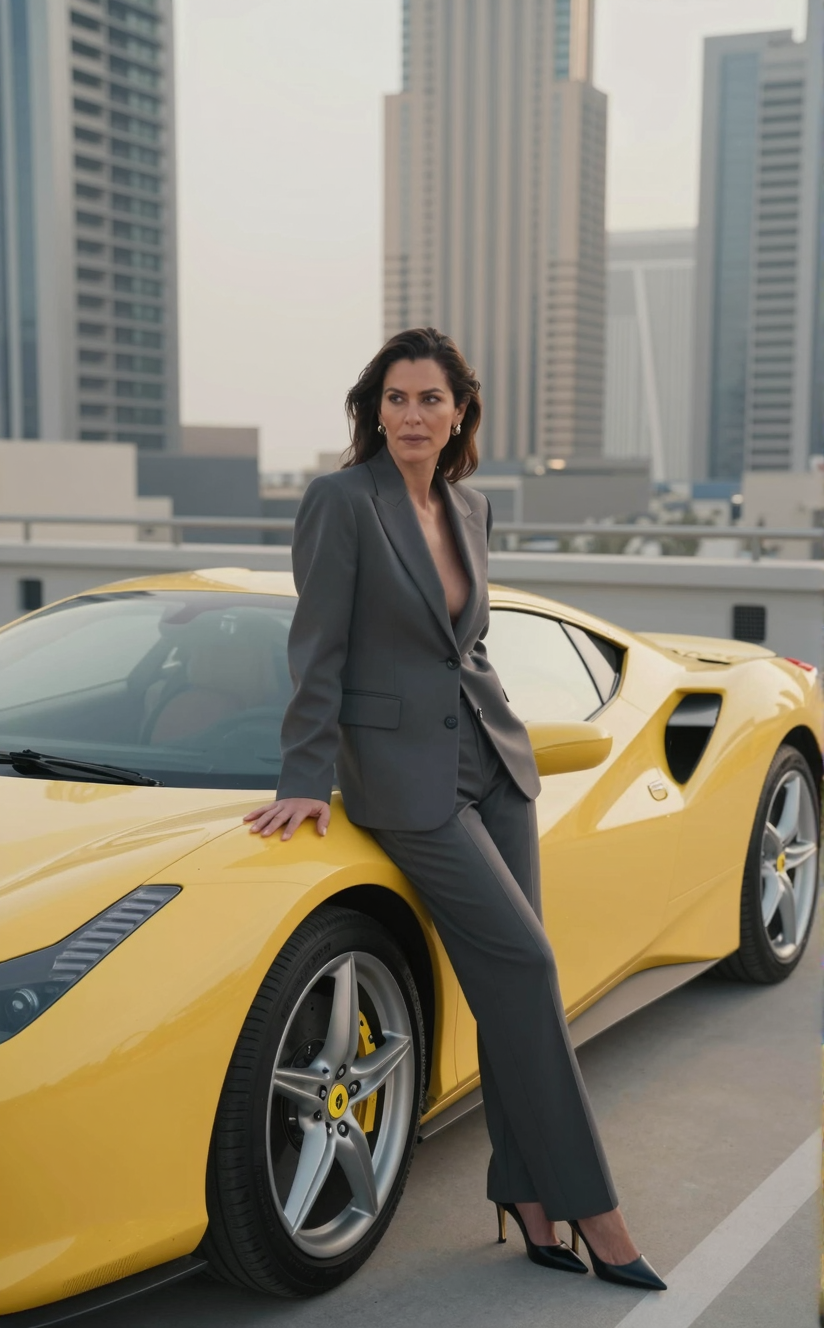
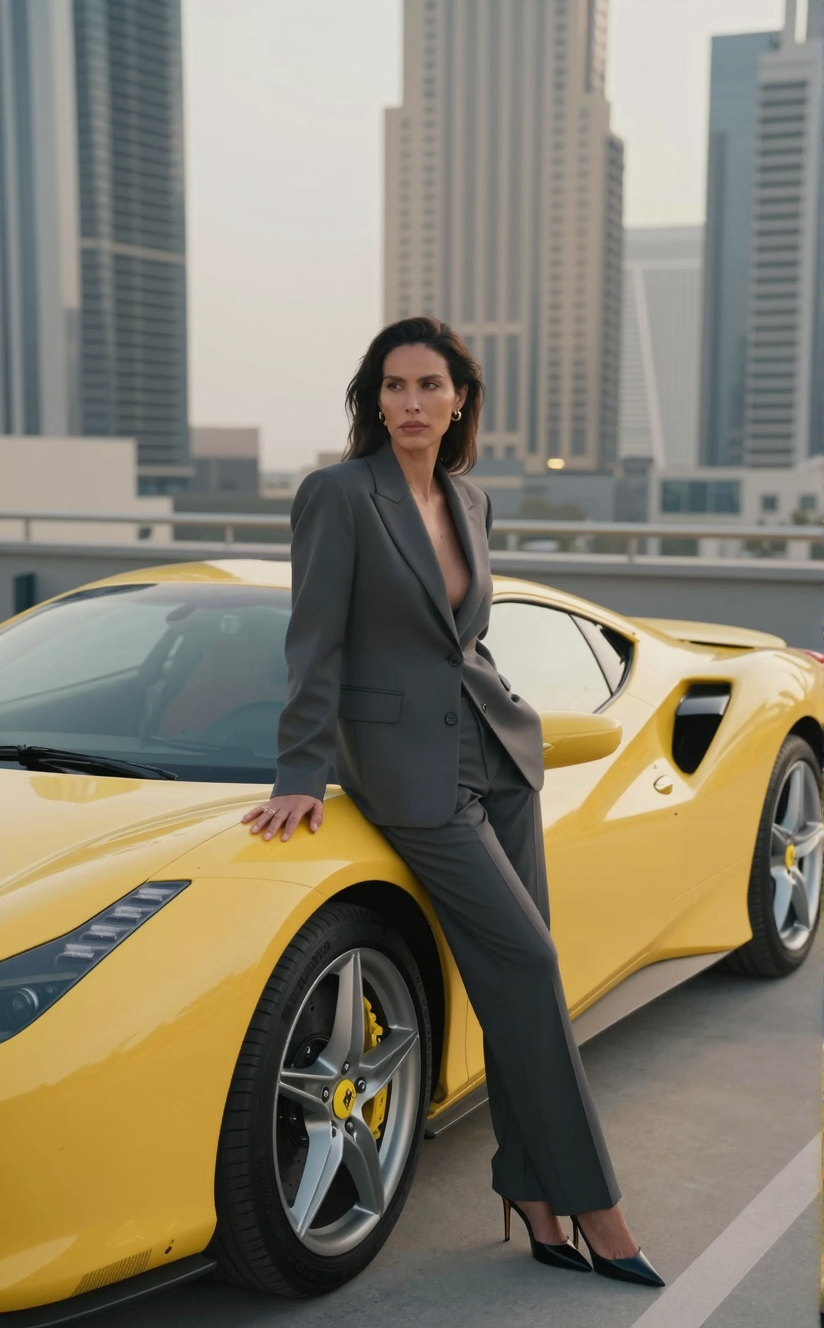
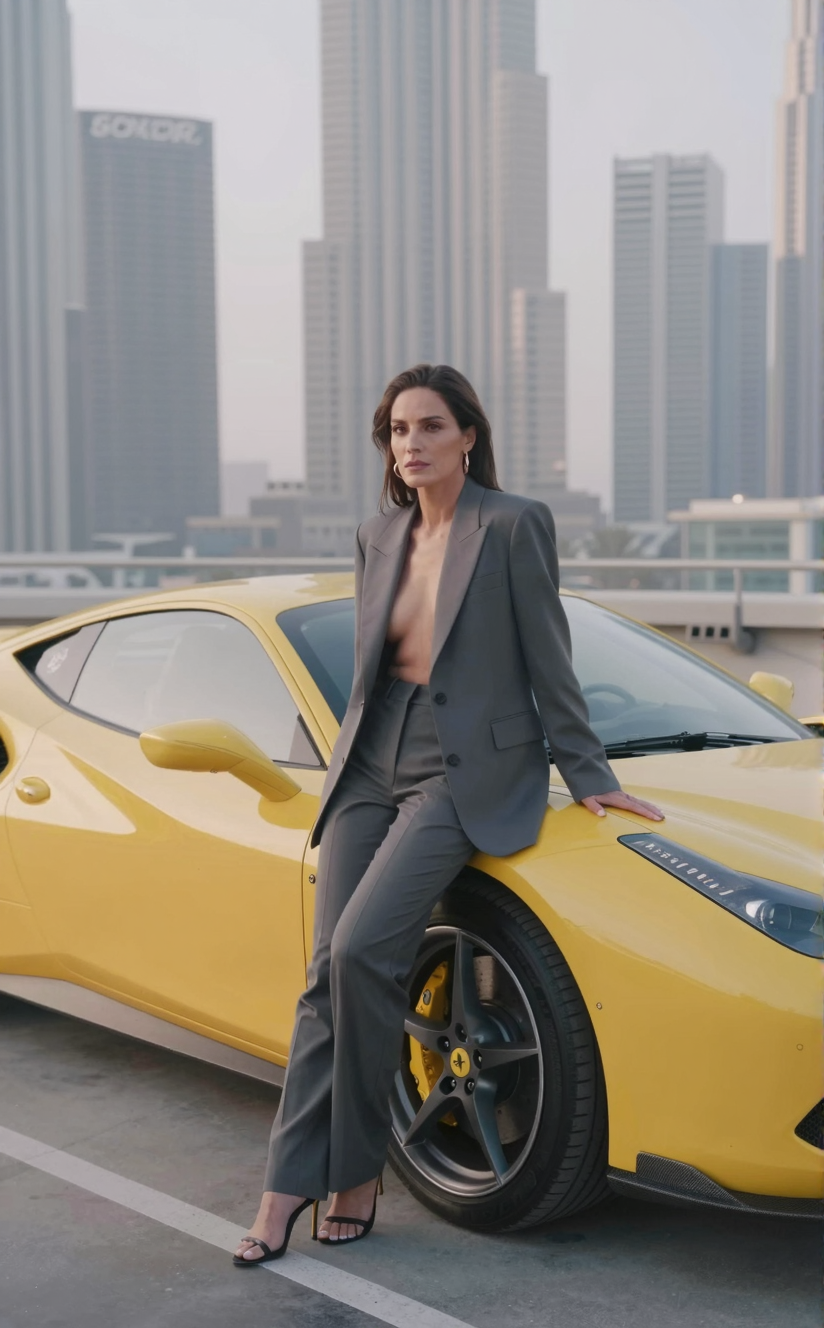
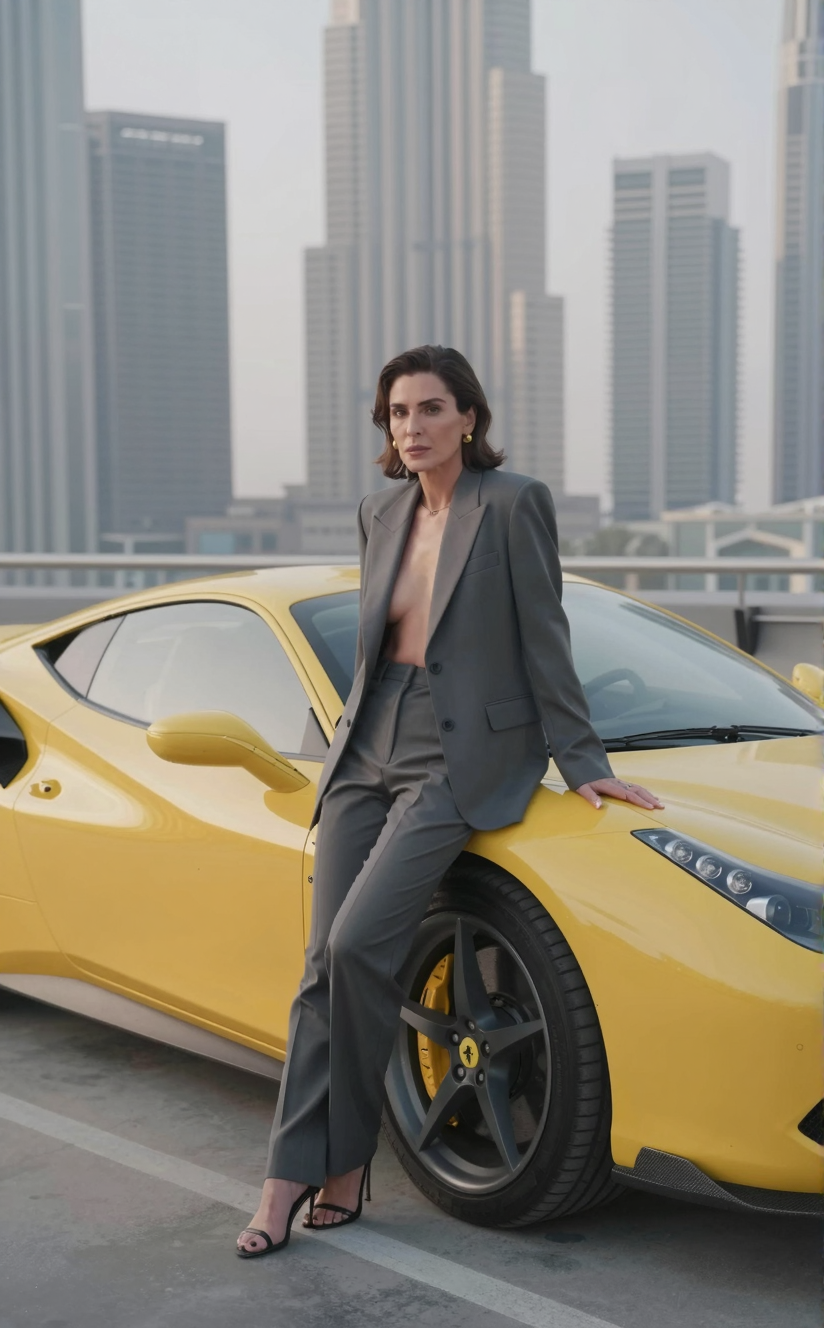
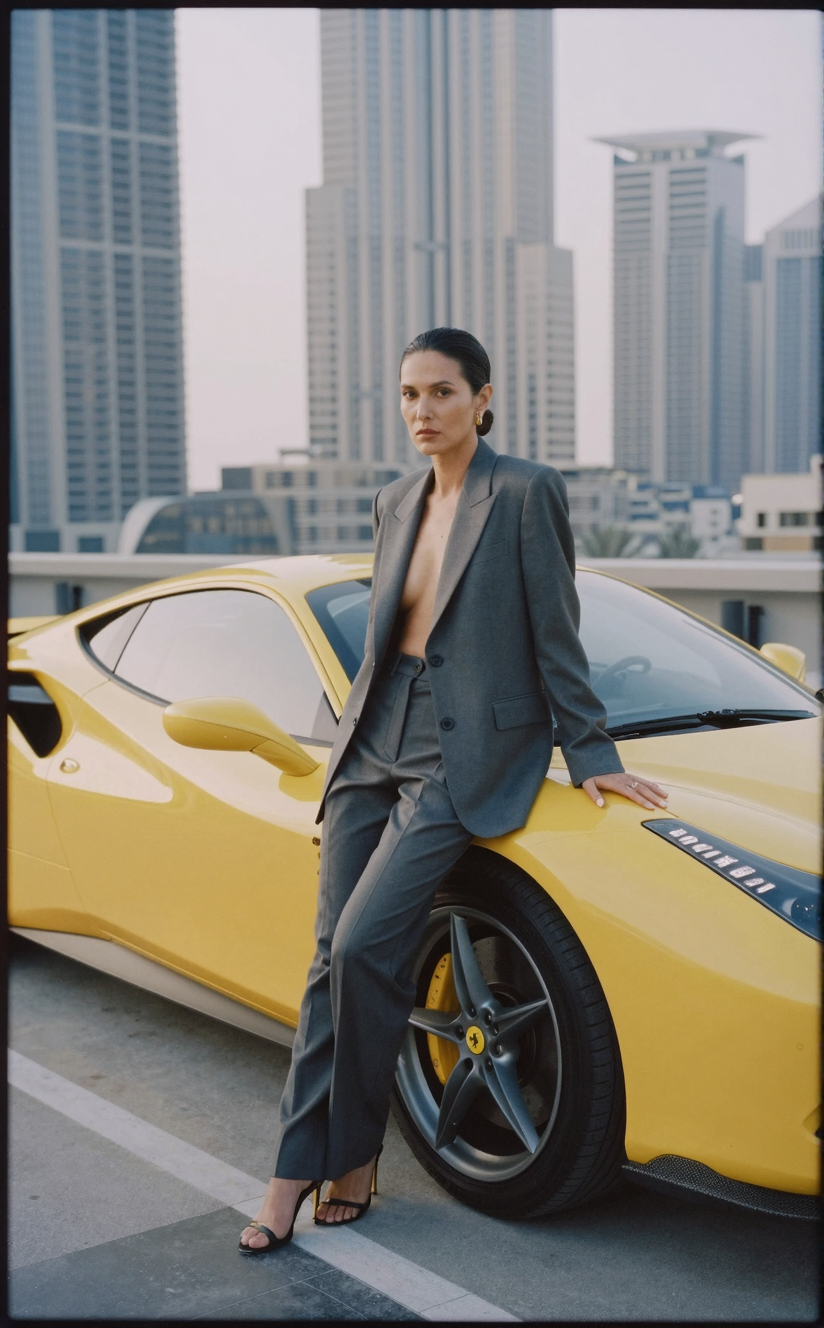
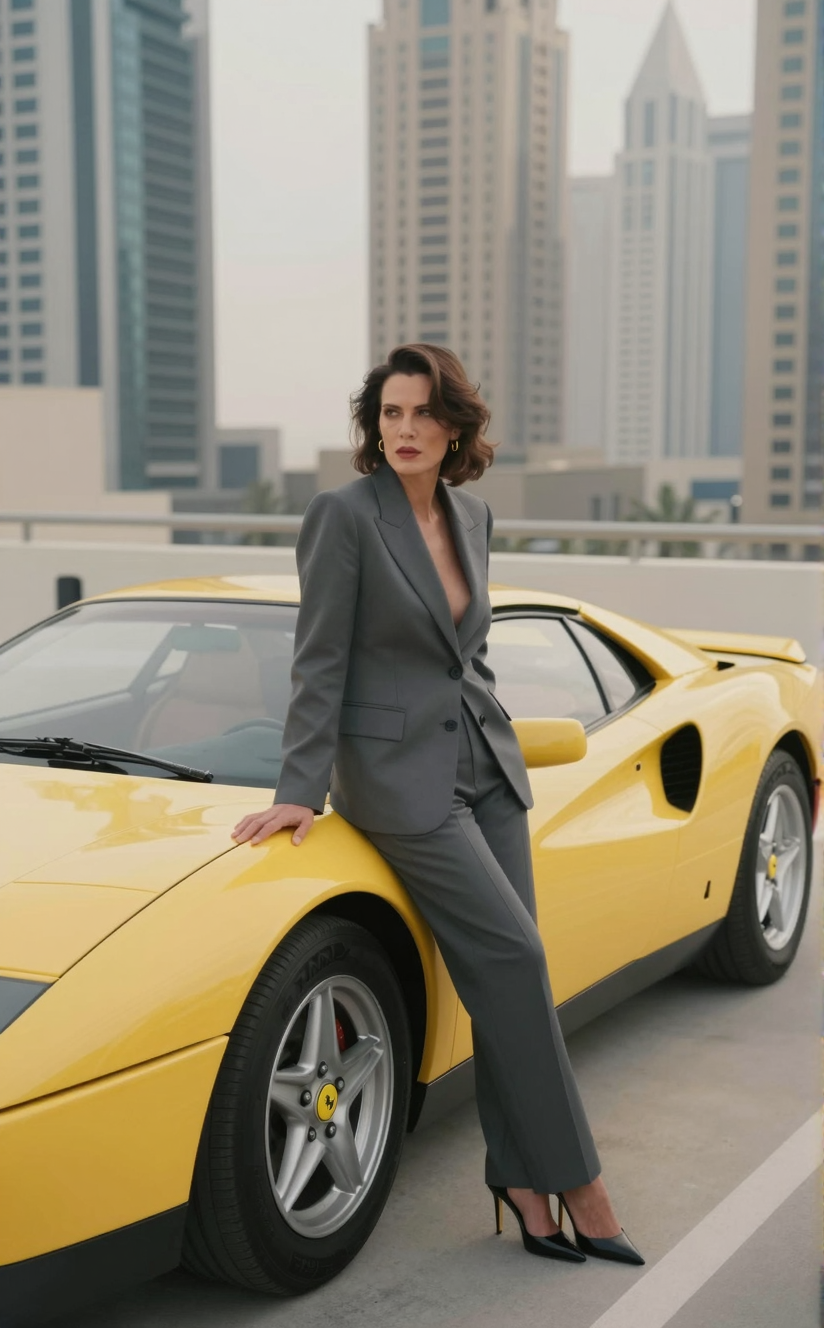
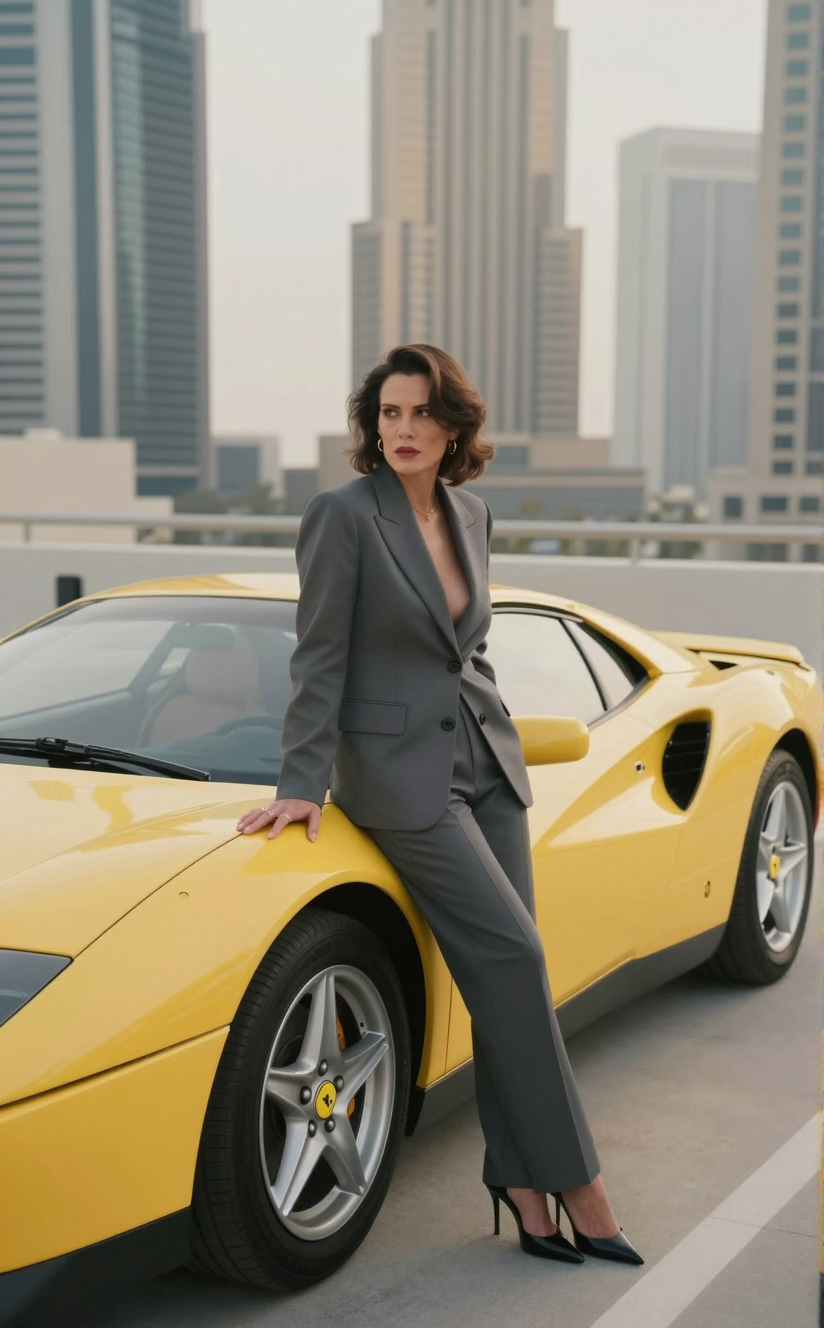
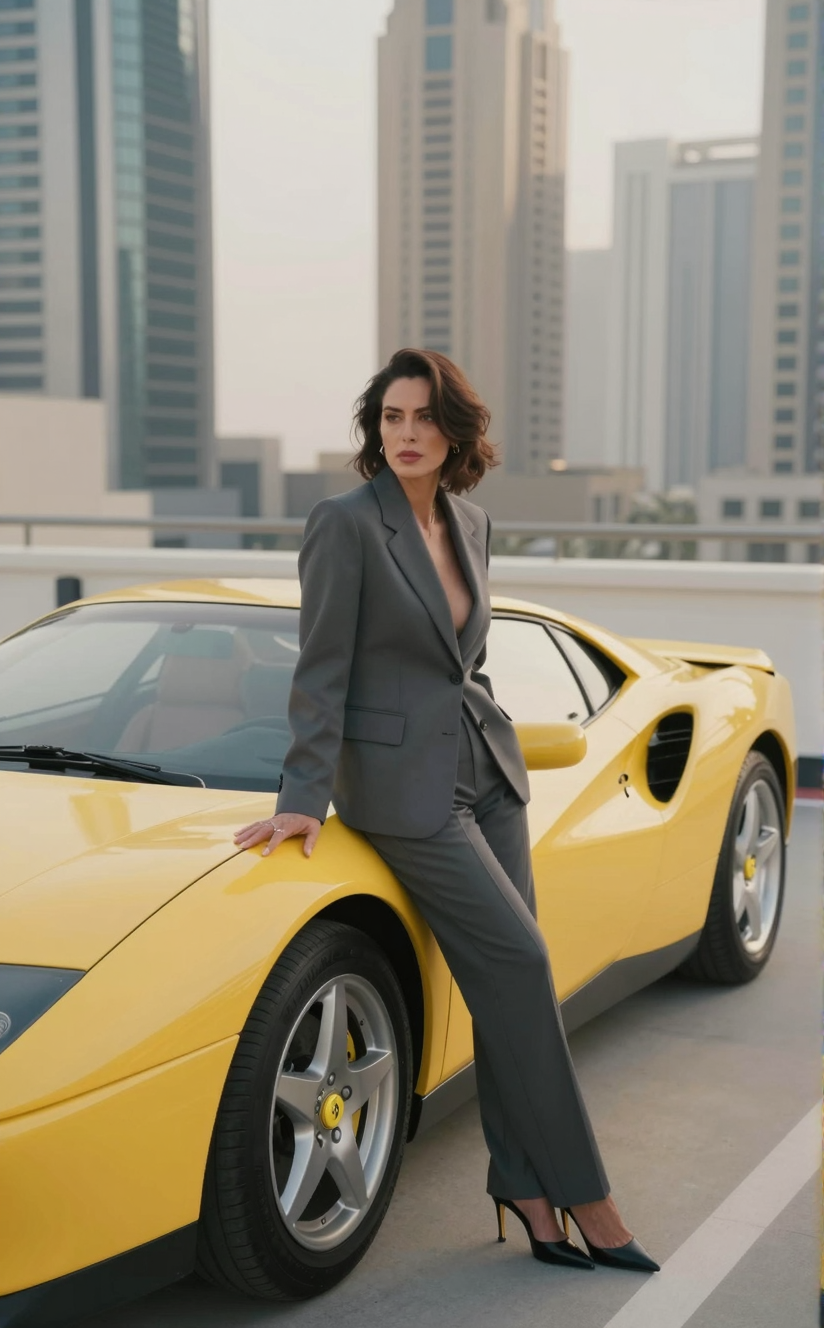
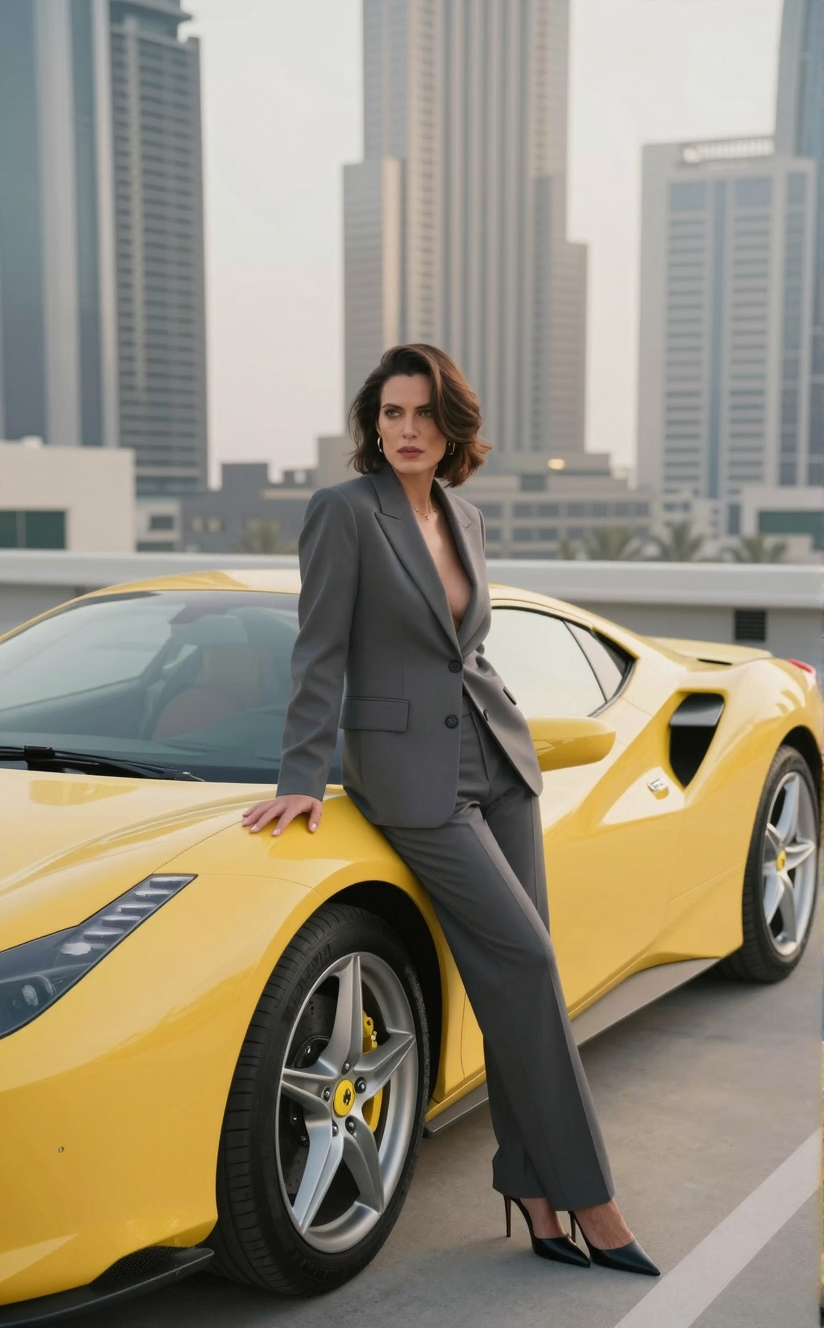
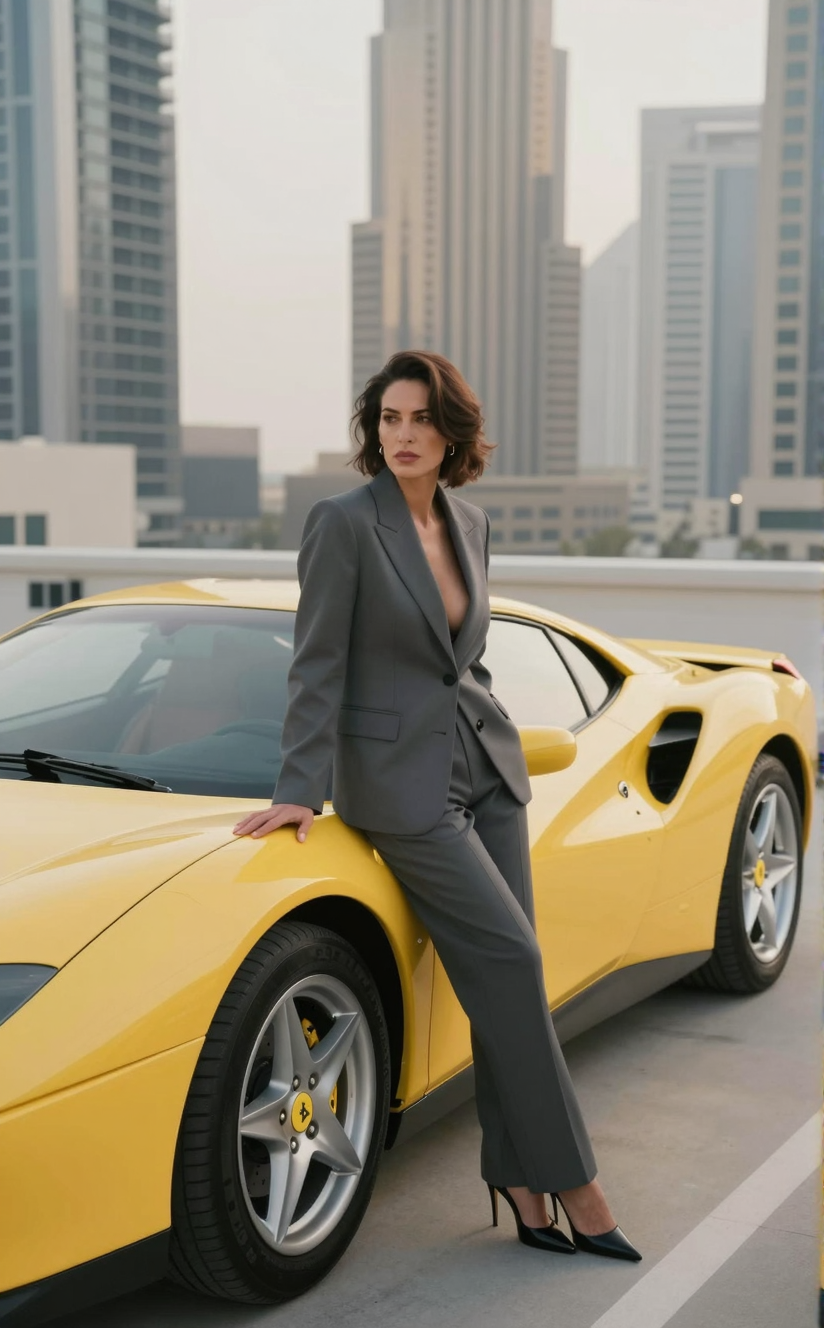
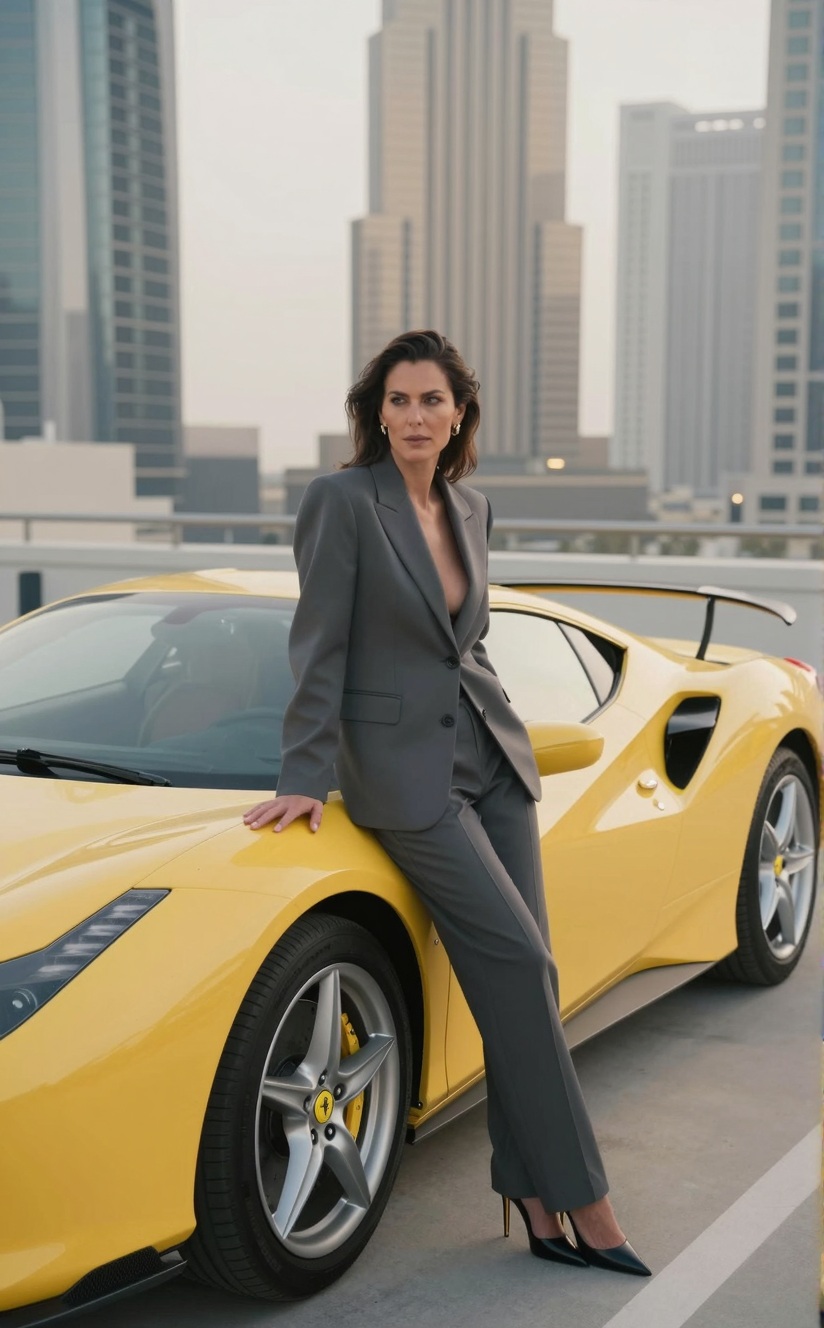
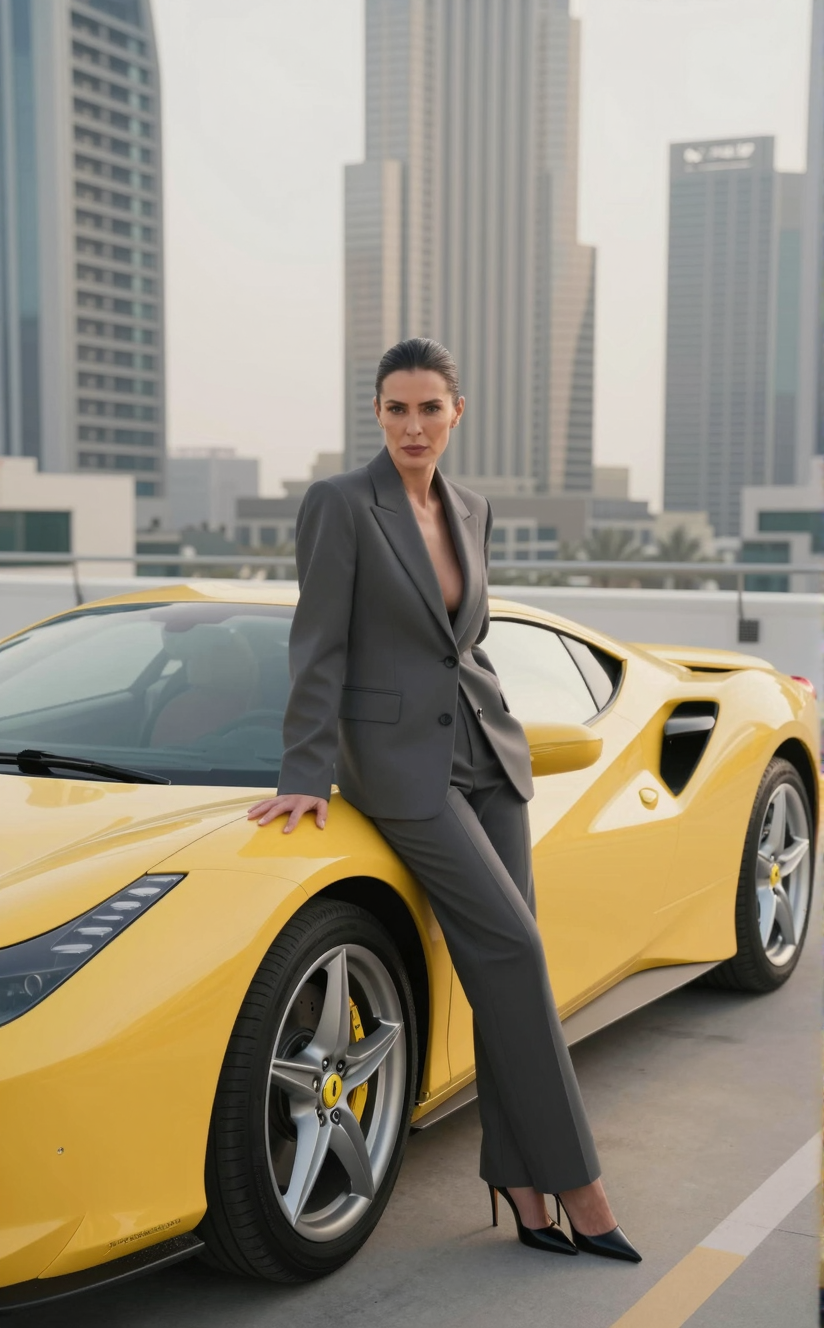
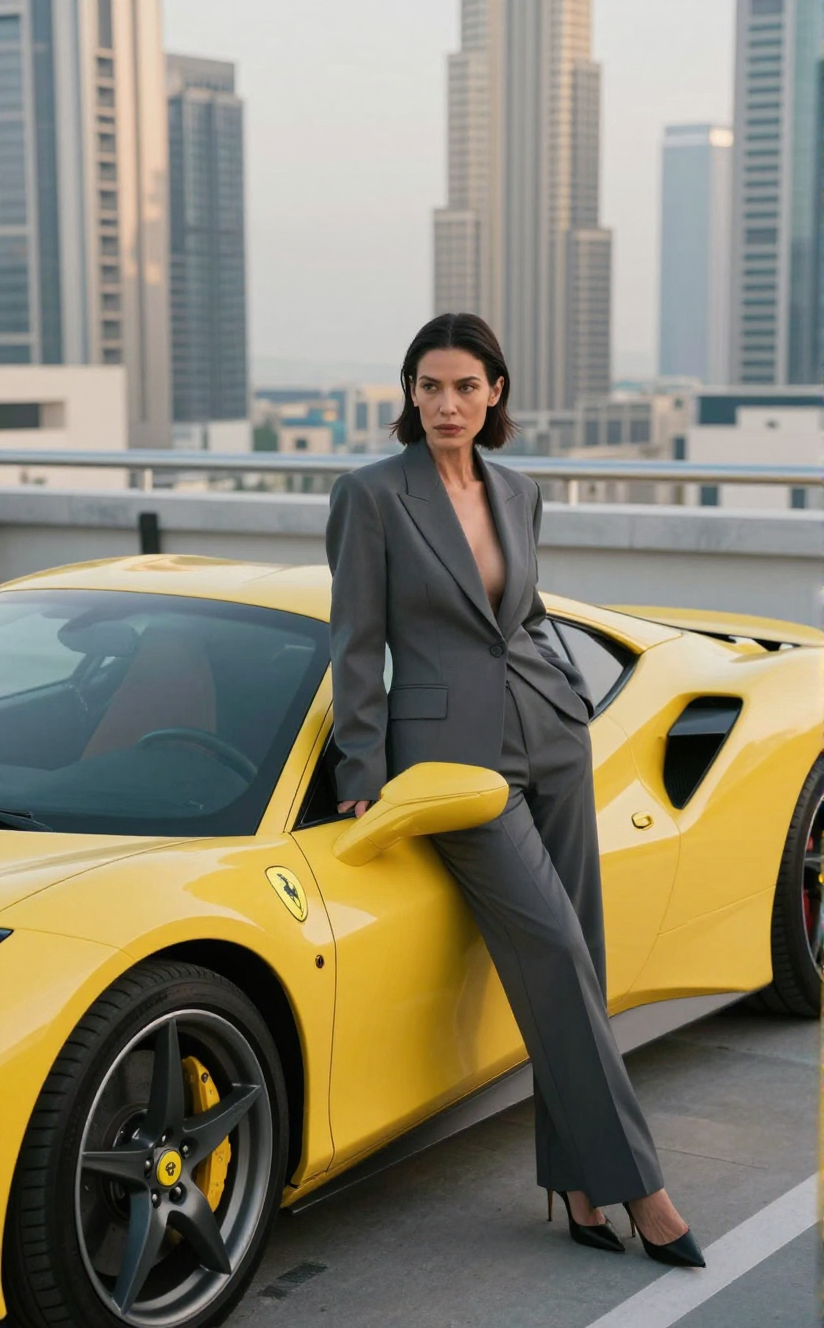
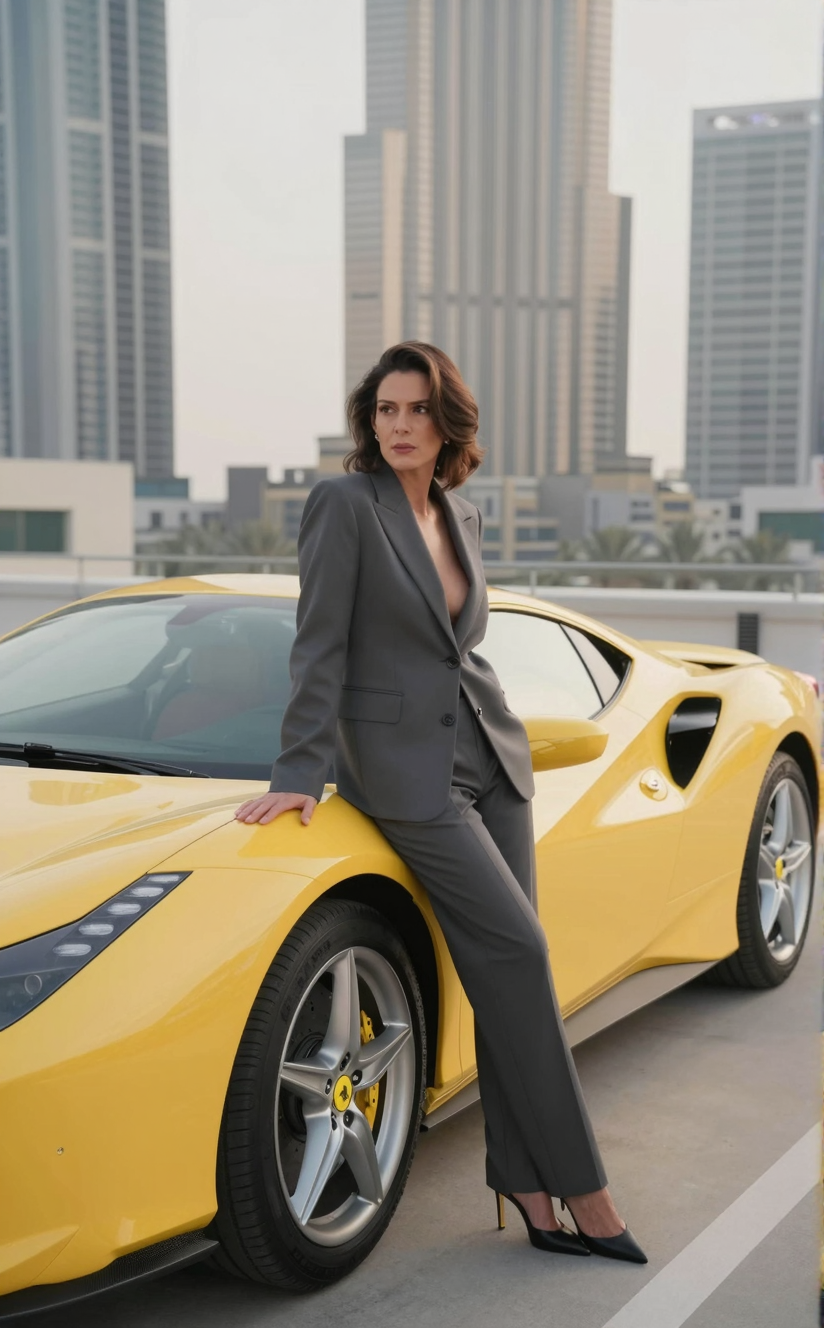
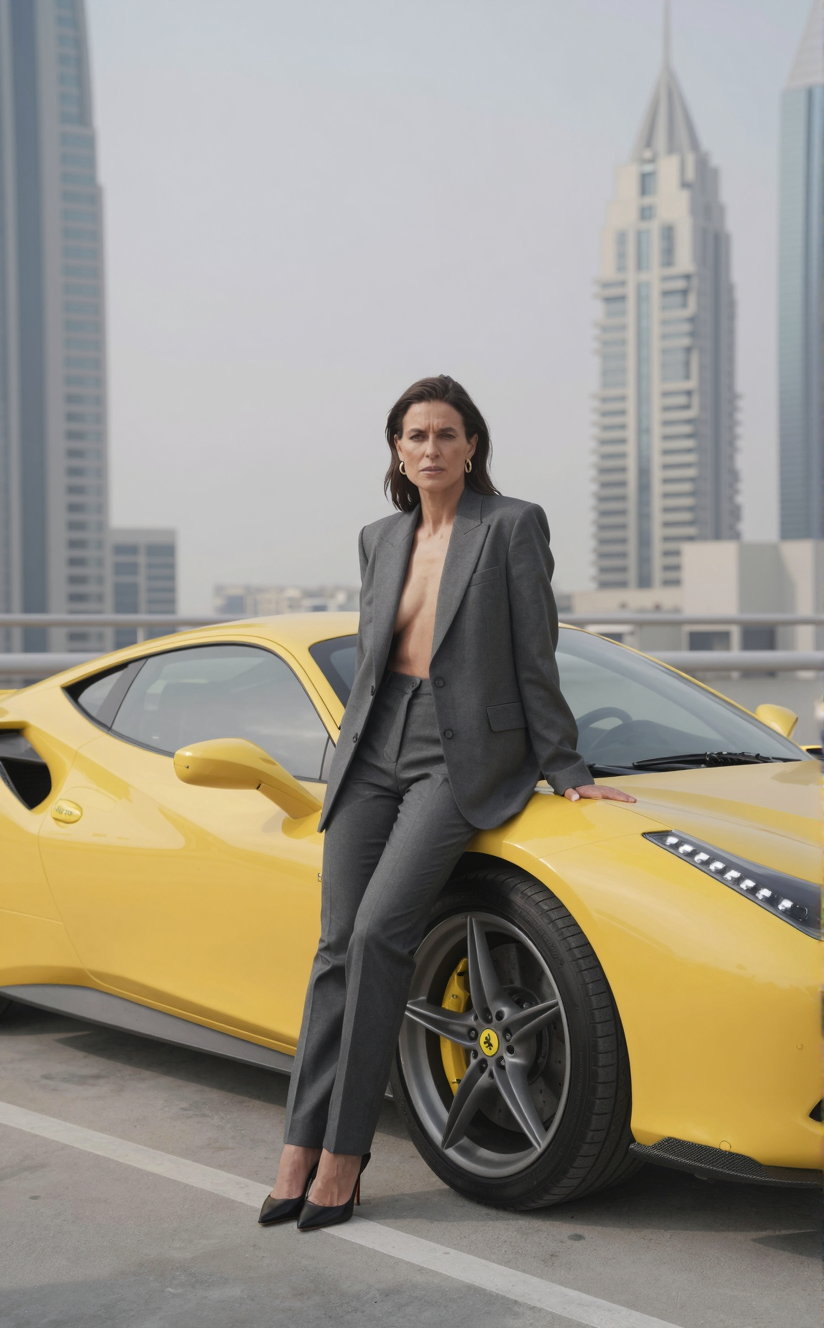
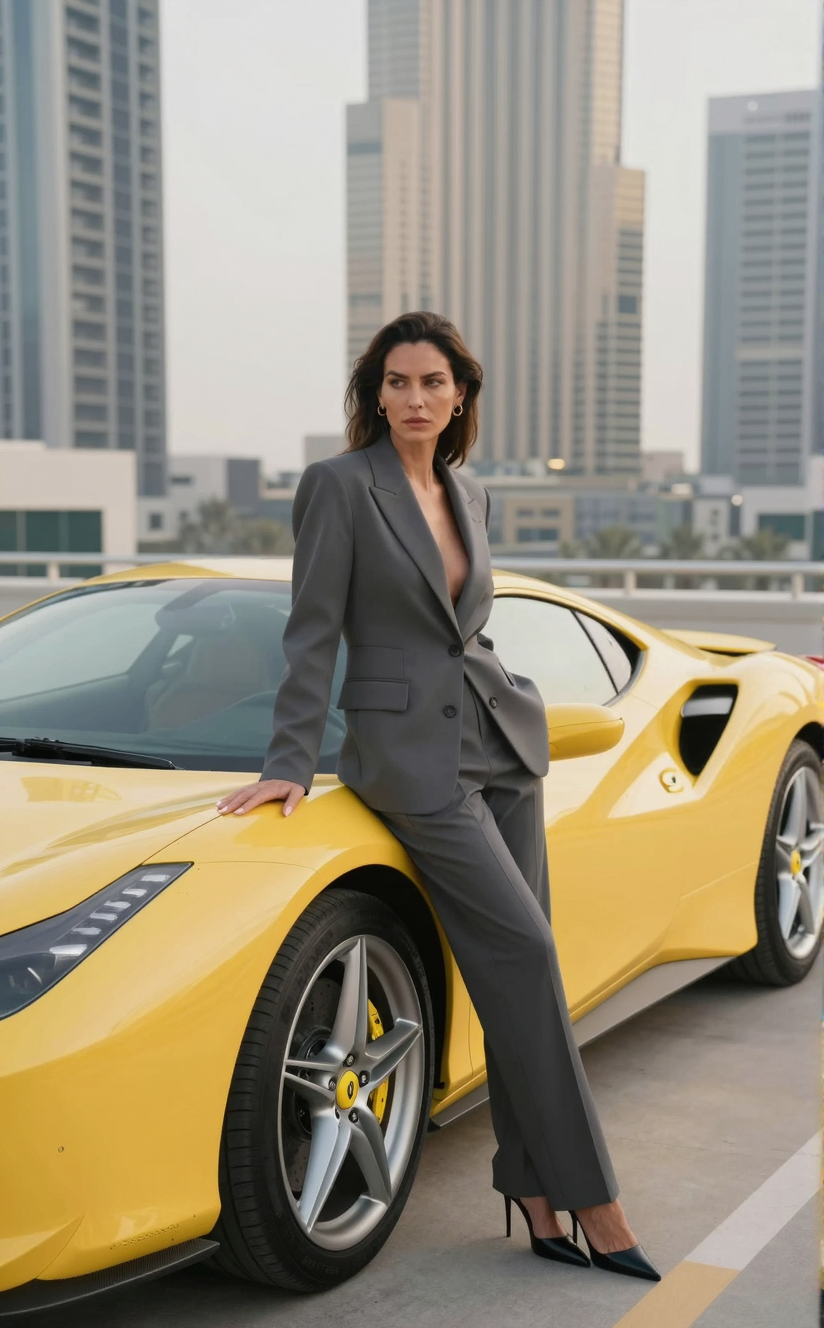
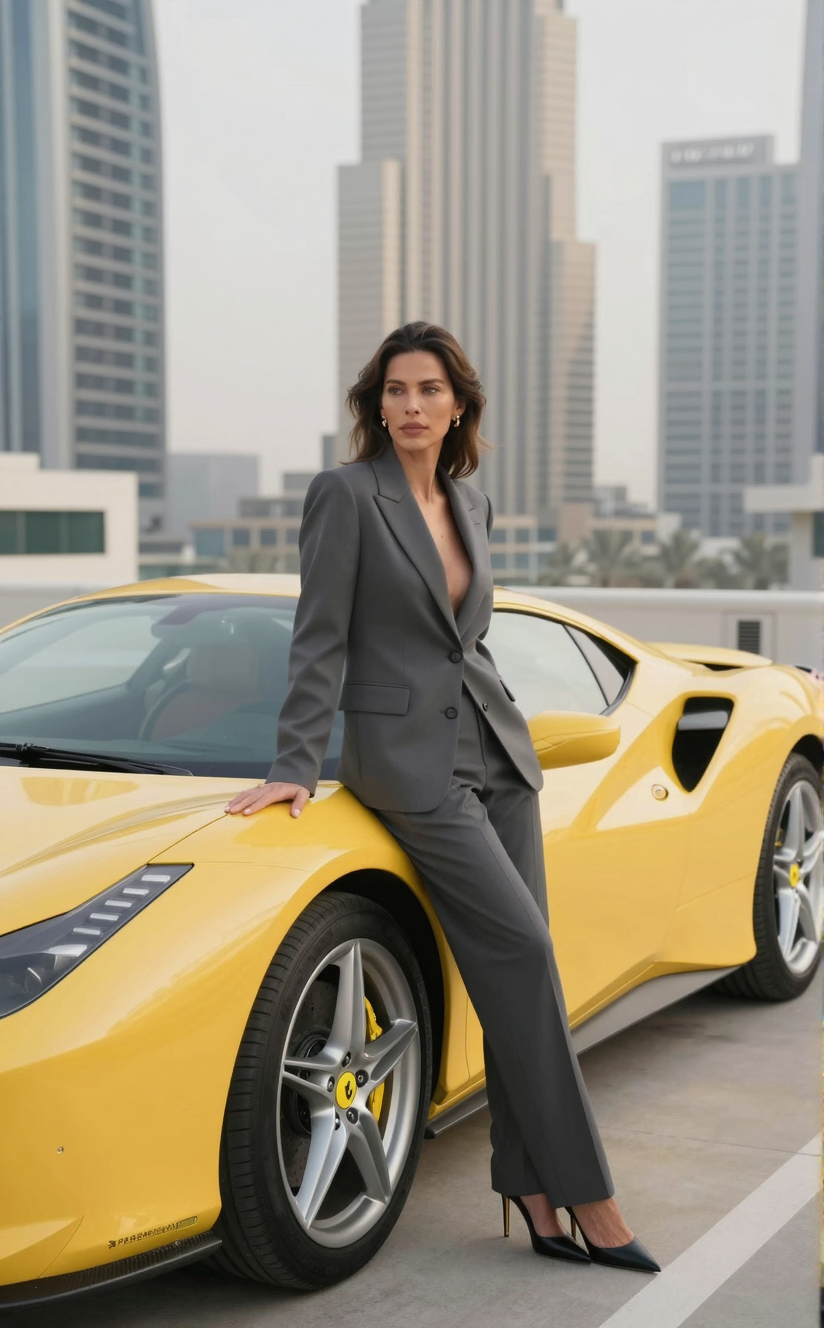
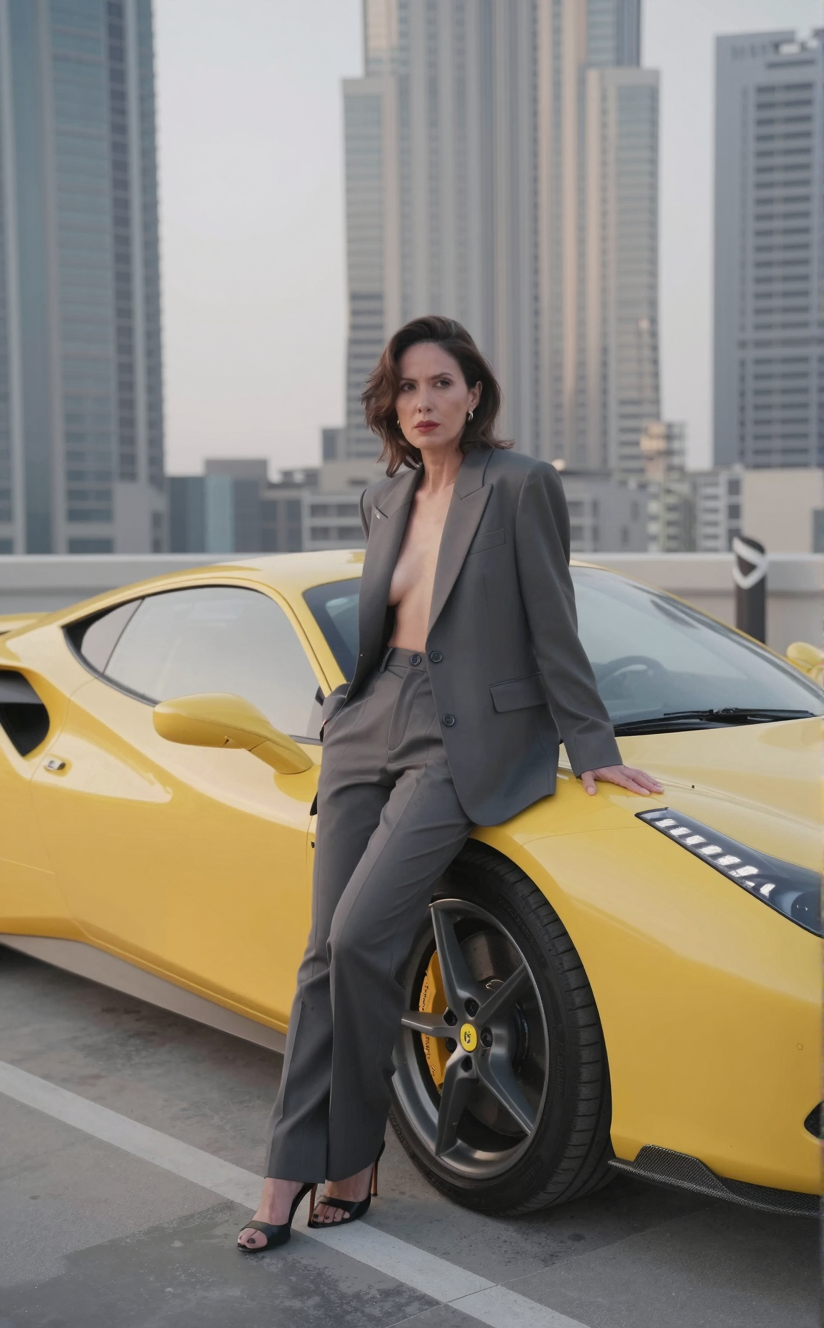
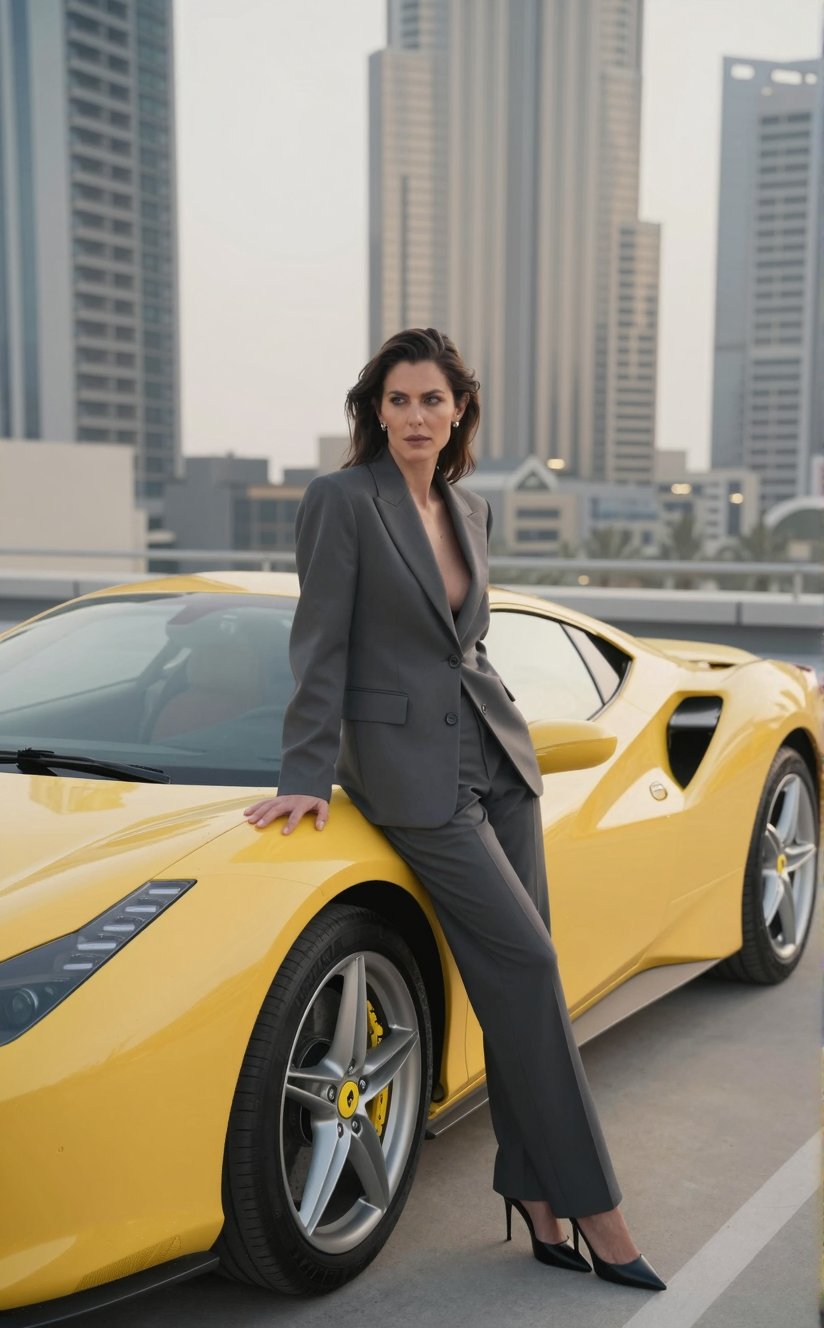
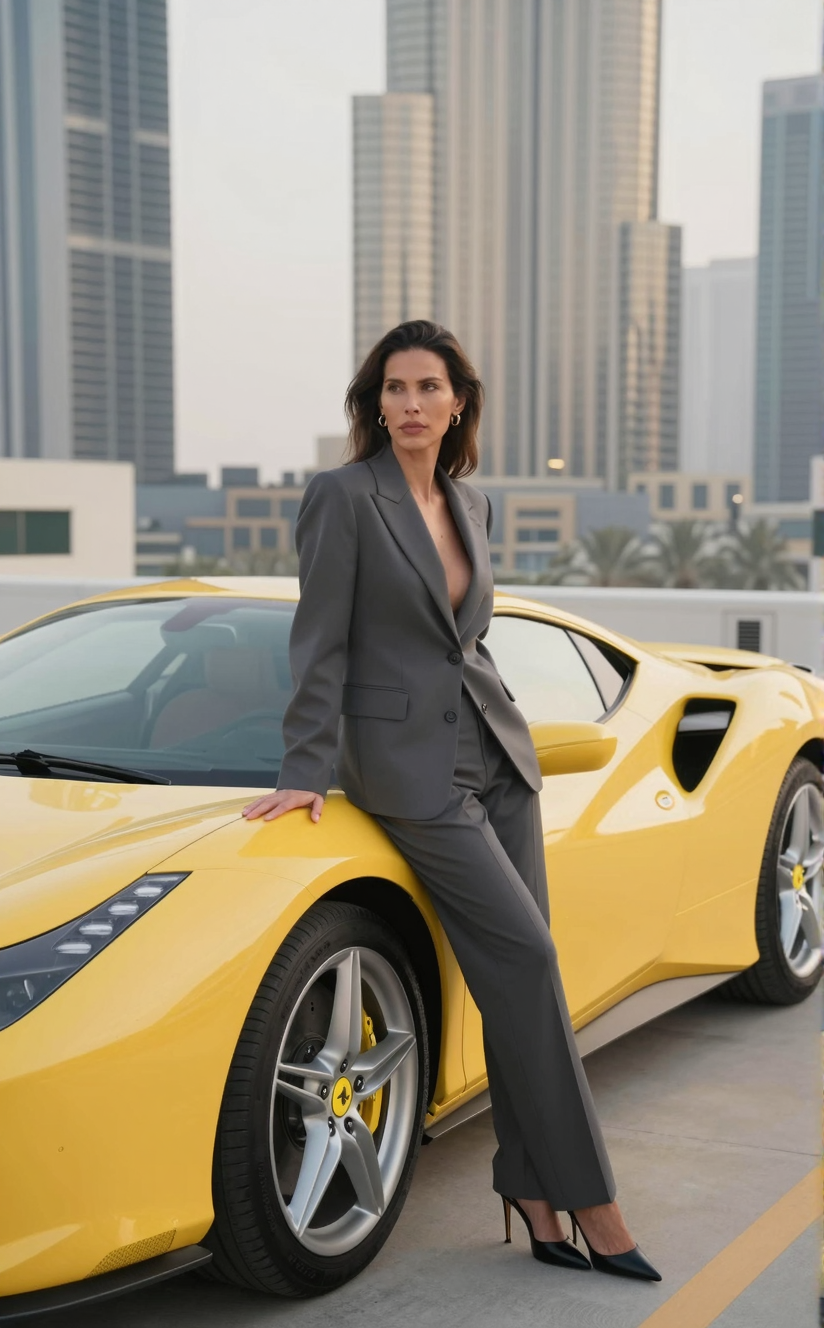
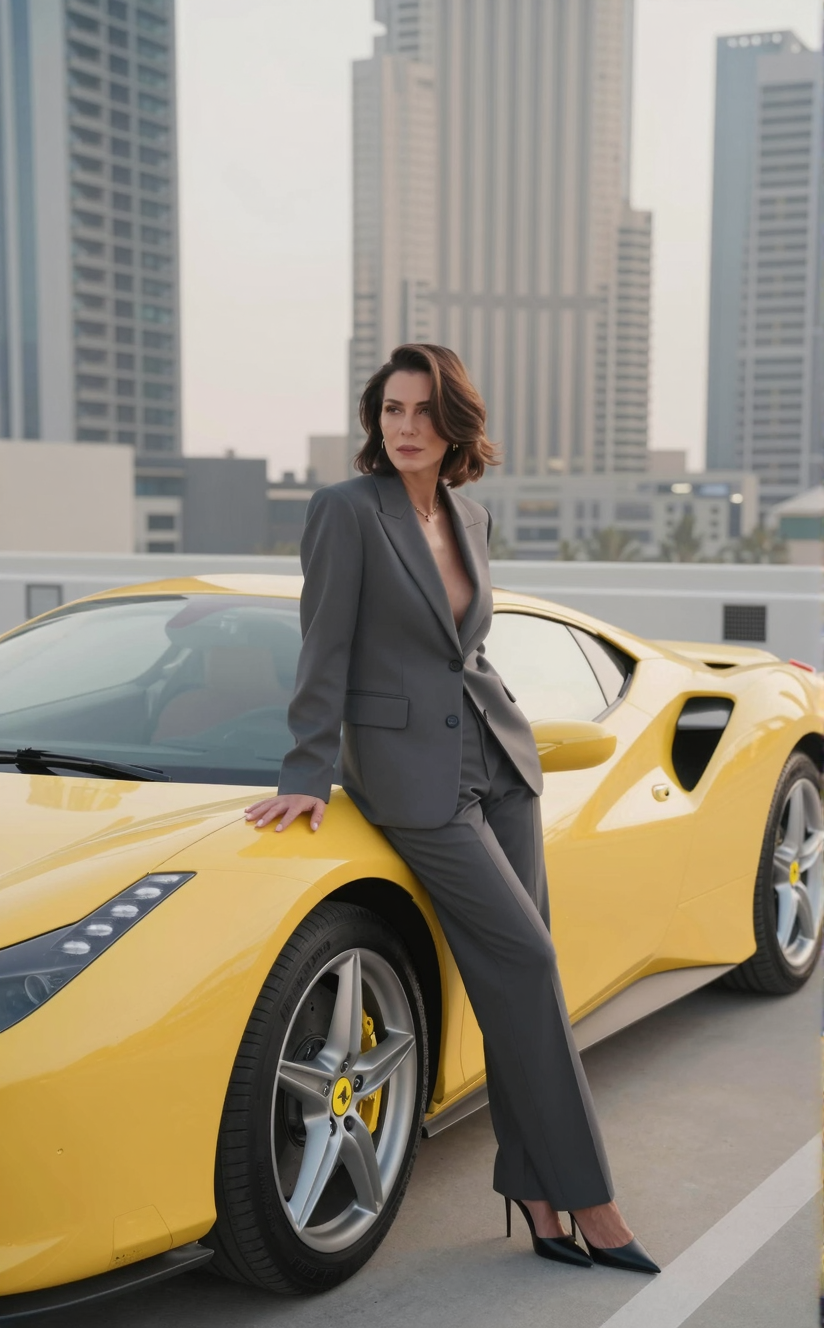
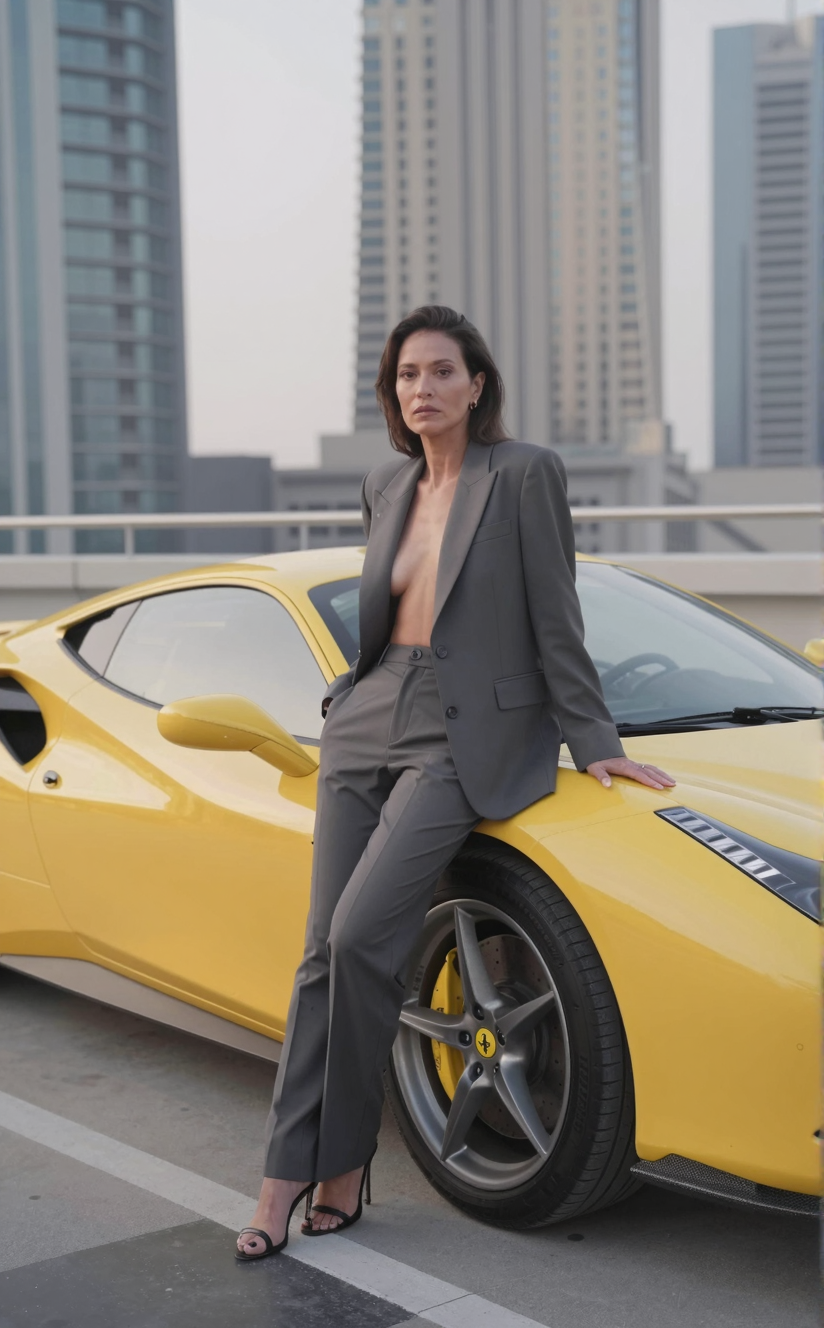
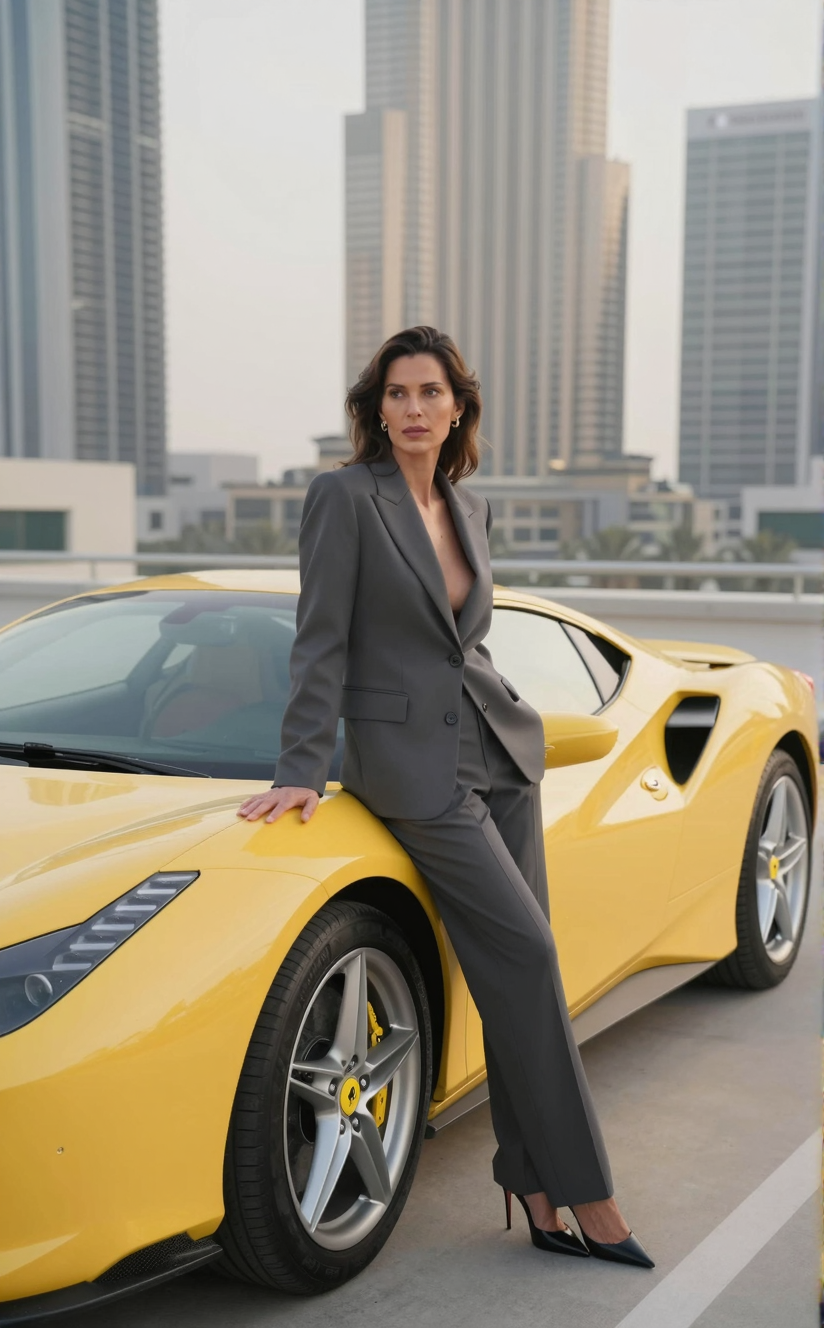
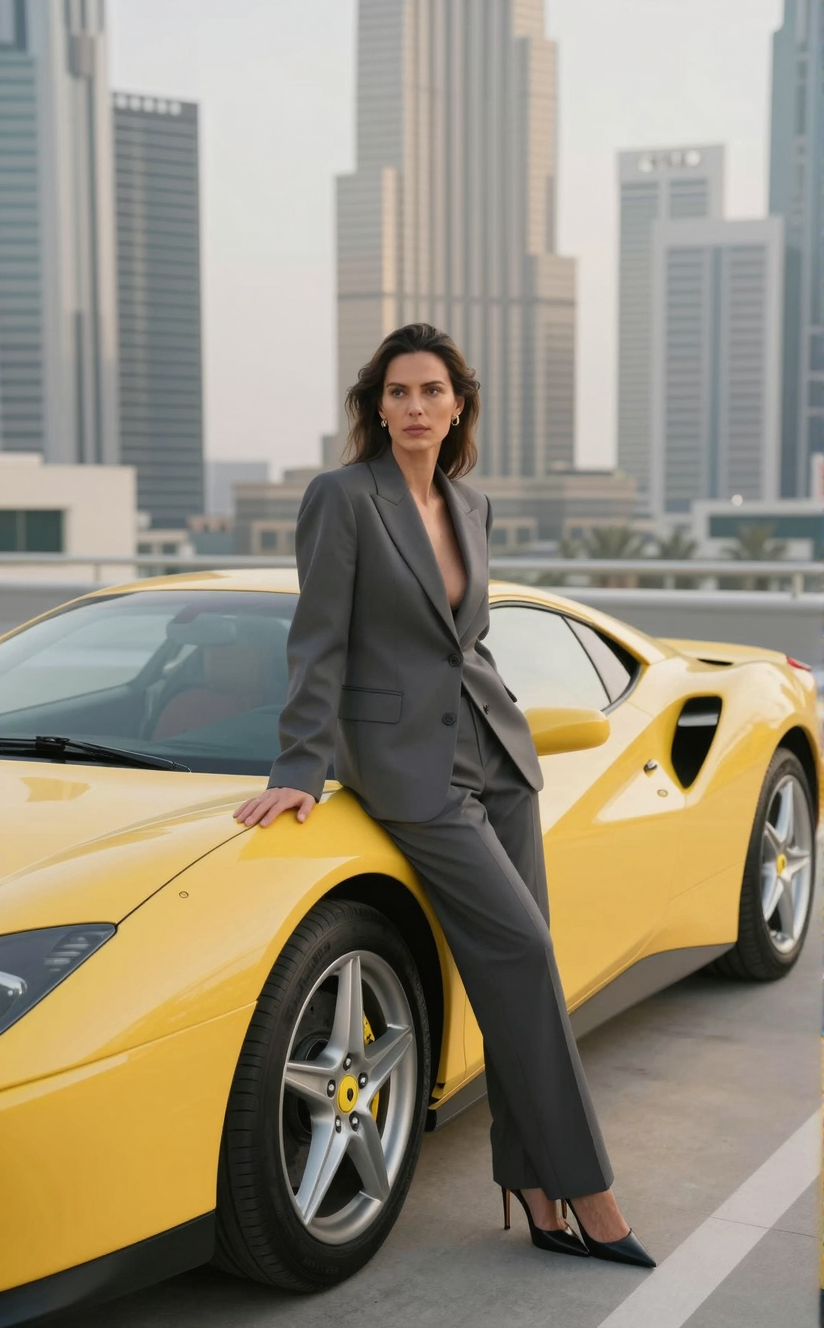
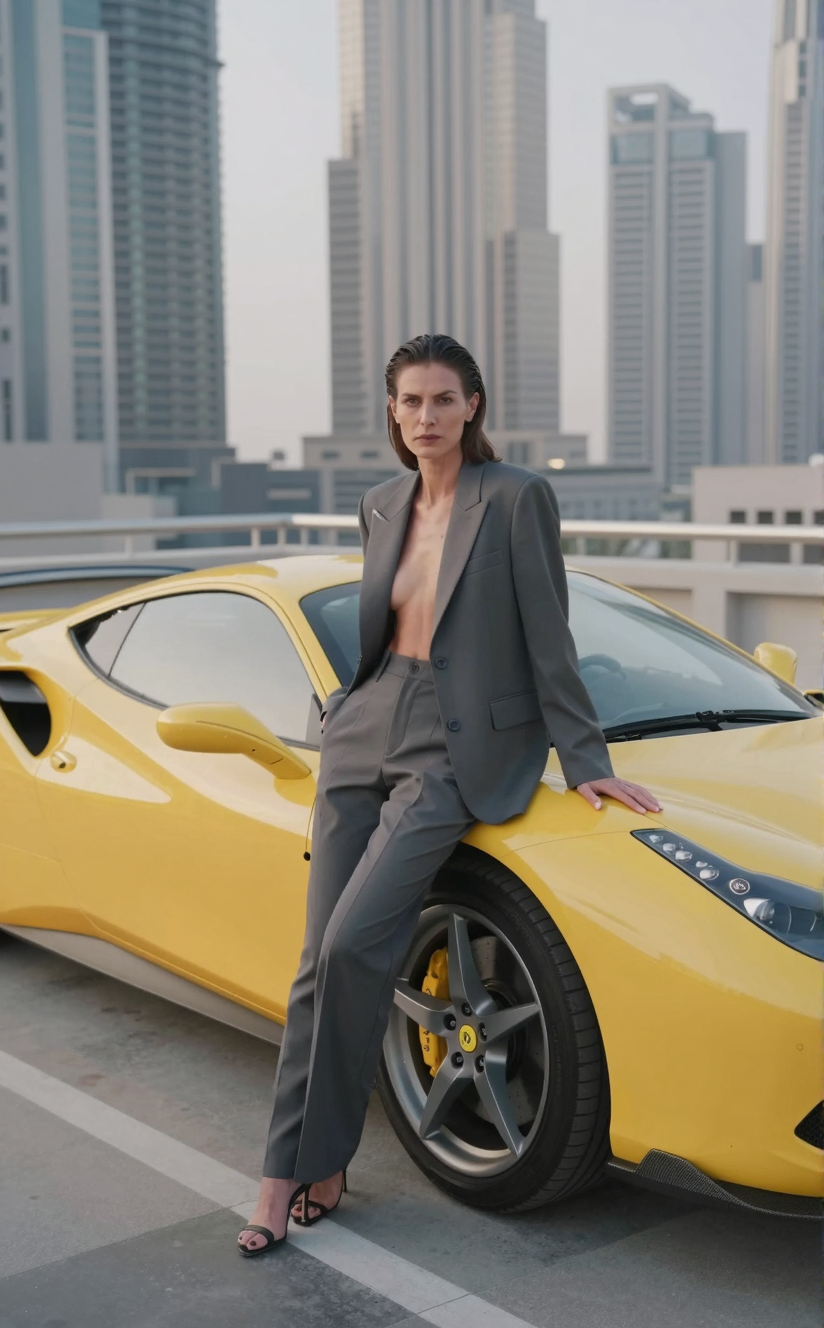
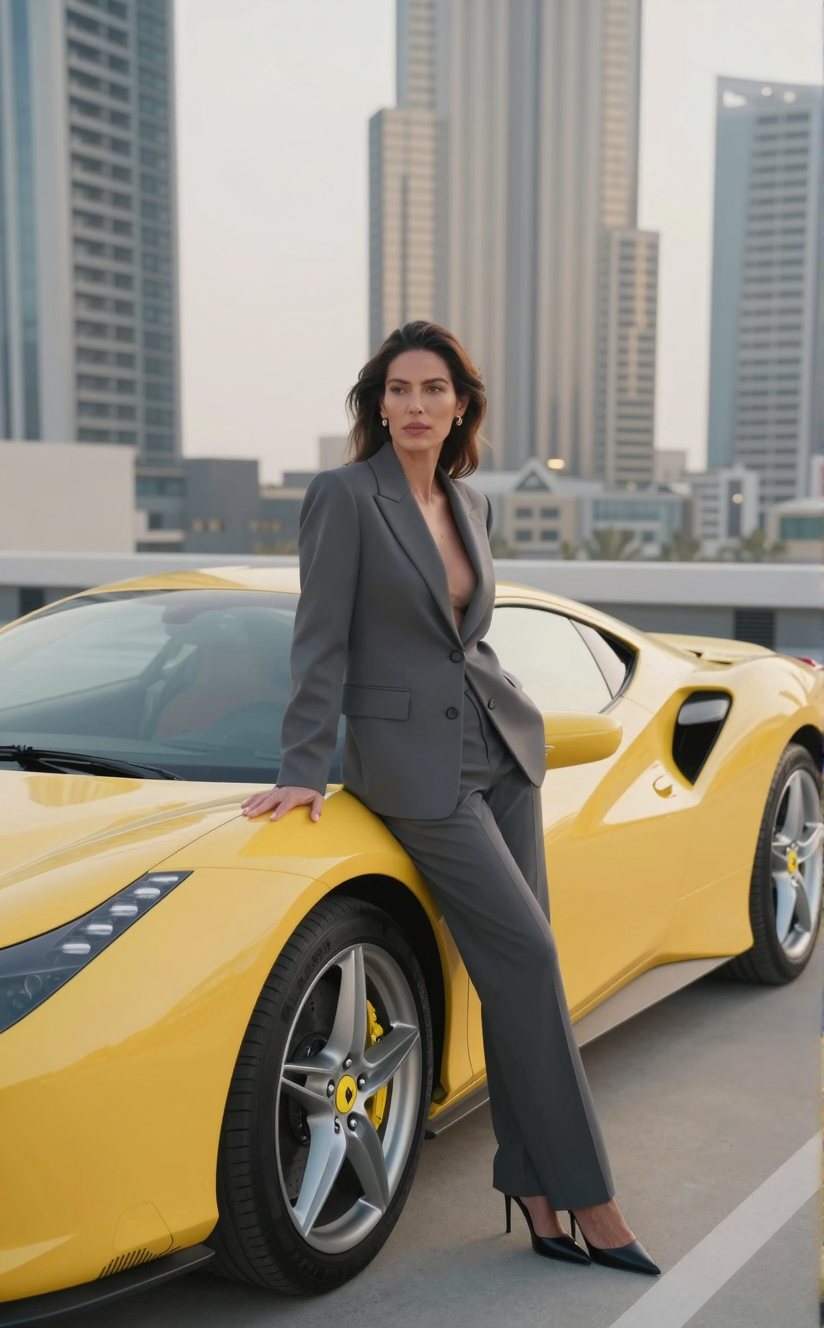
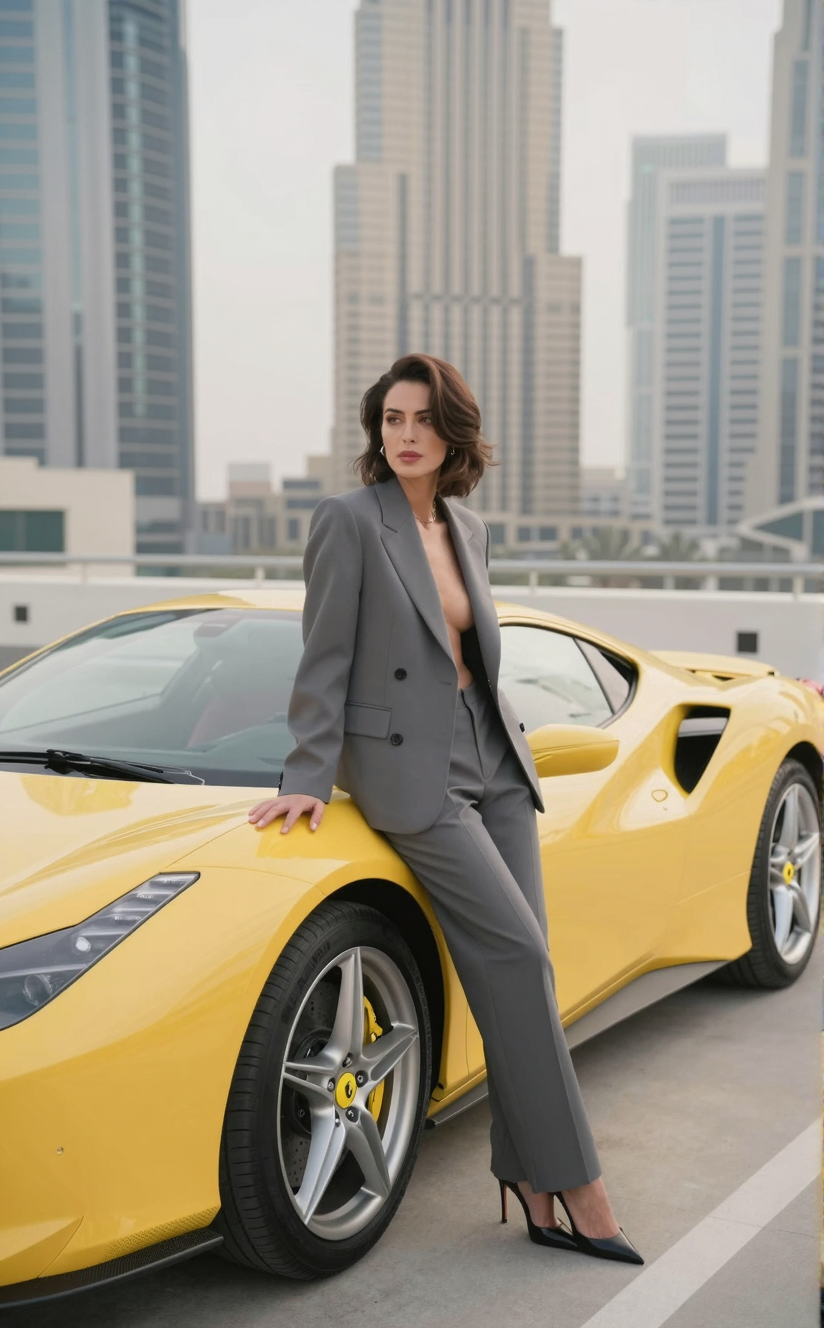
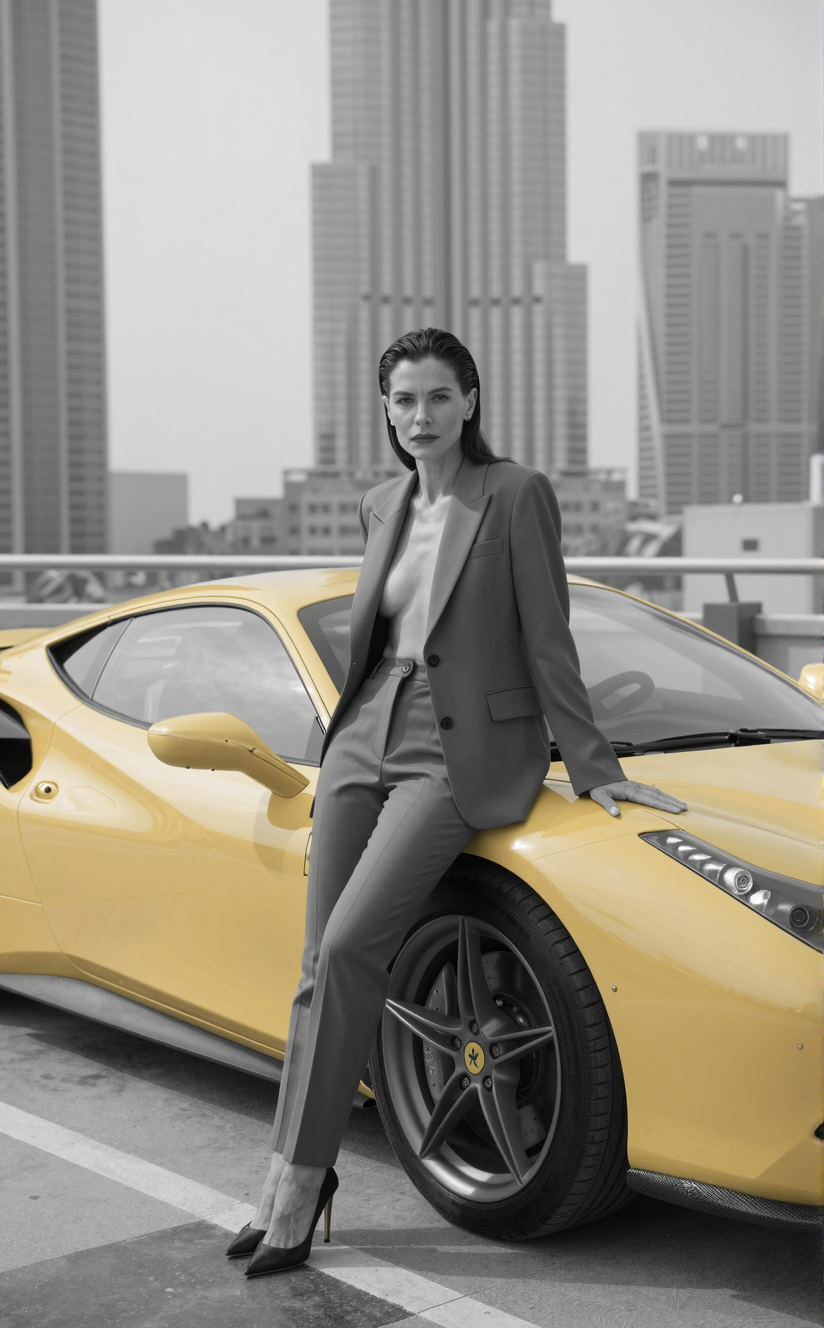
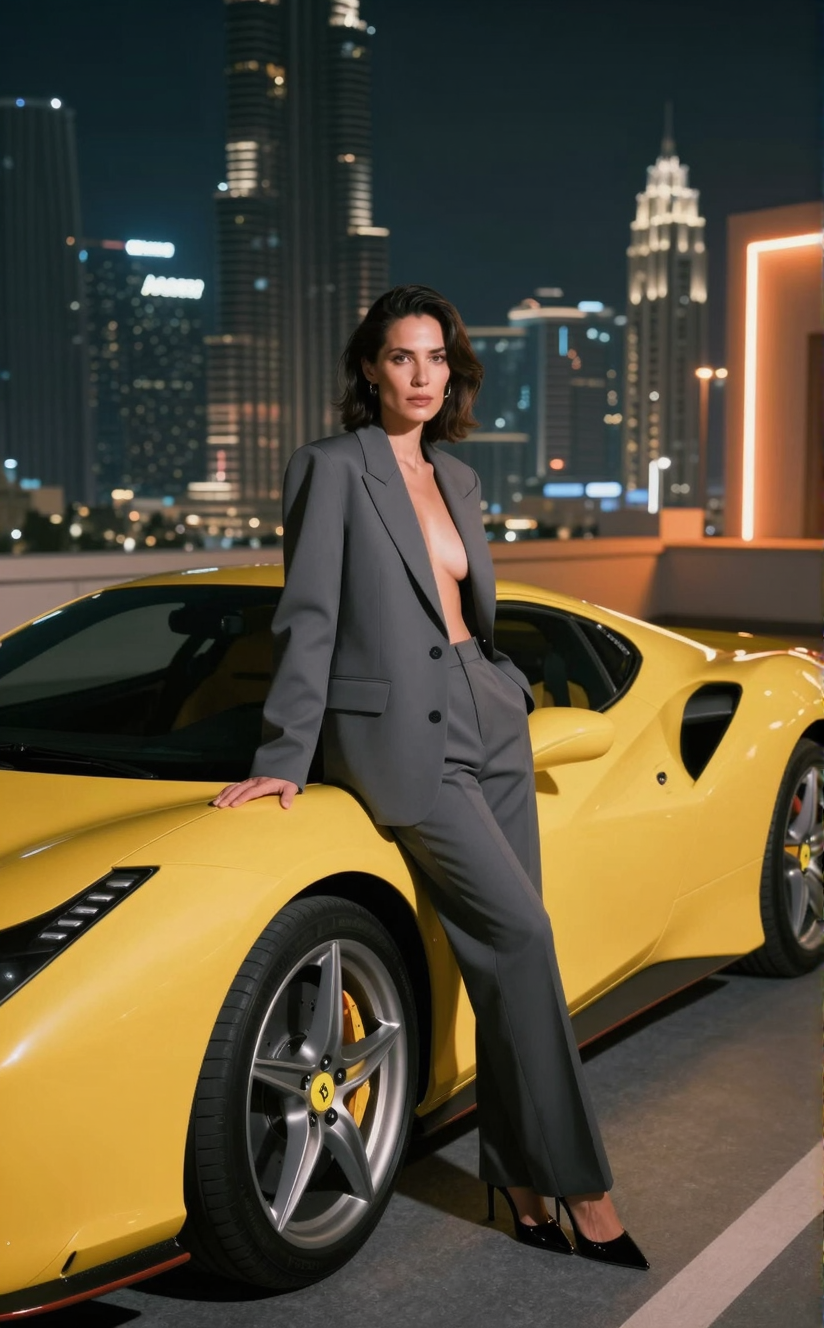
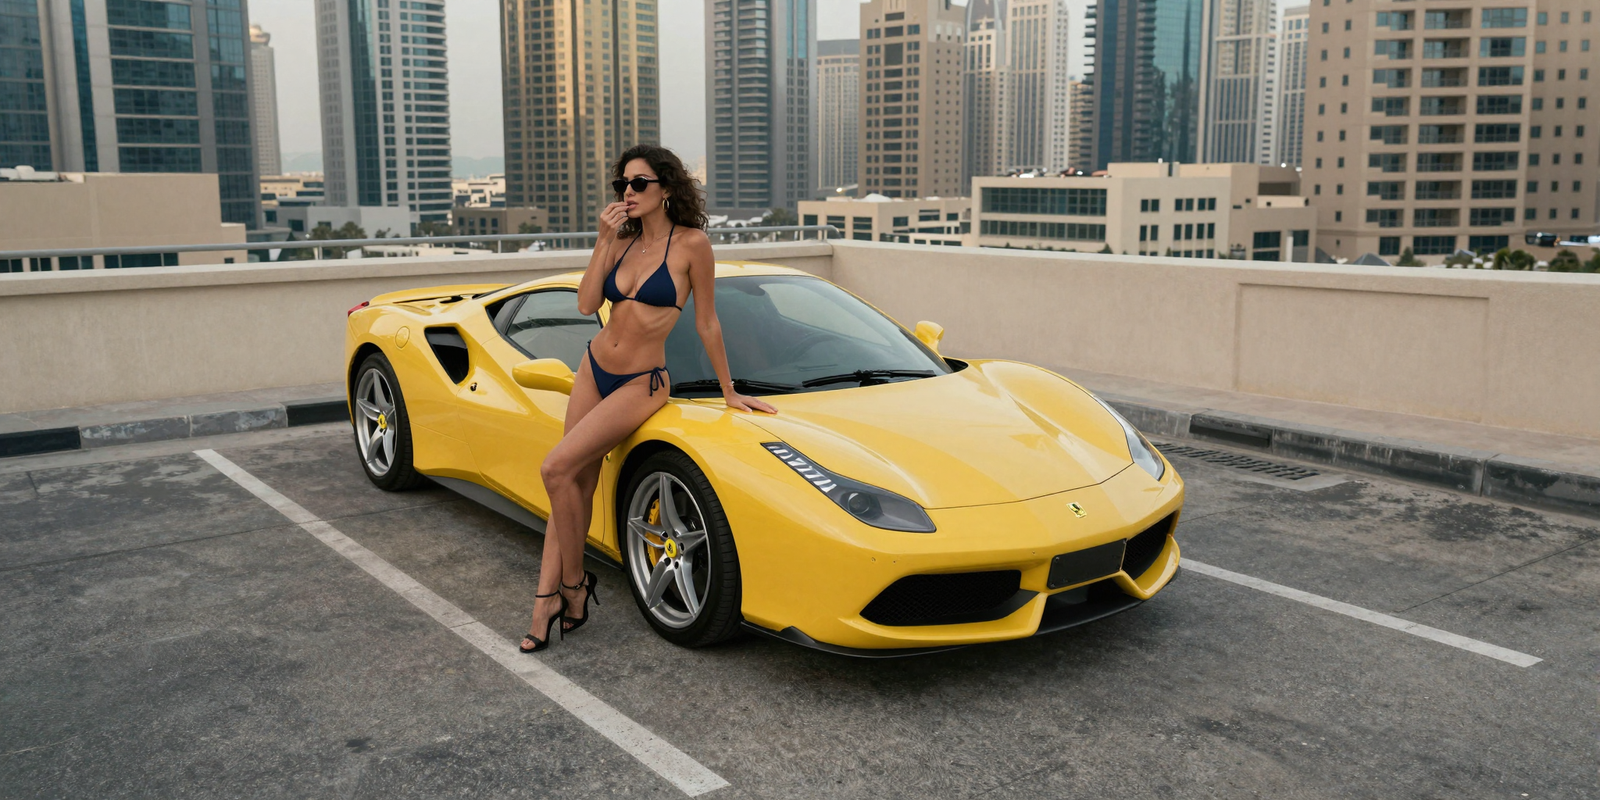
    					Photorealistic, Bright / Airy aesthetic. Subject: A 40yr female Mixed Latino-European minimalist (wearing a matte grey suit without shirt underneath, long trousers and high-heels), pose: leaning on her car, intense gaze expression. Featuring: a Ferrari (yellow with pristine body conditions). Scene set in a skyscrapper rooftop in Dubai with soft diffused light. Technical: high angle, shot on Hasselblad medium format, 50mm lens.


    WHAT I LEARNED FROM THIS BENCHMARK

    Z-Image Turbo excels in beautiful photorealistic images of daily subjects as long it stays within a cinematic / editorial portraiture realm.

    When experimenting with more artistic and edgy prompts pushing the aesthetics far away from the common reality, Z-Image Turbo starts to fail and ignores these prompt instructions, as if it is addicted or trained only to a certain aesthetic only.

    Z-Image can not follow specific Aesthetic/Genre prompts.

    Z-IMAGE BEST SAMPLER + SCHEDULER RESULTS

    DDIM + DDIM_UNIFORM
    DMPP_SDE + BETA
    DMPP_SDE + KARRAS

    Sampler + scheduler comparison – all native combinations

    DDIM + SIMPLE
    DDIM + SGM_UNIFORM
    DDIM + KARRAS
    DDIM + EXPONENTIAL
    DDIM + BETA
    DDIM + NORMAL
    DDIM + DDIM_UNIFORM
    DDIM + LINEAR_QUADRATIC
    DDIM + KL_OPTIMAL
    EULER + SIMPLE
    EULER + SGM_UNIFORM
    EULER + KARRAS
    EULER + EXPONENTIAL
    EULER + BETA
    EULER + NORMAL
    EULER + DDIM_UNIFORM
    EULER + LINEAR_QUADRATIC
    EULER + KL_OPTIMAL
    EULER ANCESTRAL + SIMPLE
    EULER ANCESTRAL + SGM_UNIFORM
    EULER ANCESTRAL + KARRAS
    EULER ANCESTRAL + EXPONENTIAL
    EULER ANCESTRAL + BETA
    EULER ANCESTRAL + NORMAL
    EULER ANCESTRAL + DDIM_UNIFORM
    EULER ANCESTRAL + LINEAR_QUADRATIC
    EULER ANCESTRAL + KL_OPTIMAL
    DMPP_SDE + SIMPLE
    DMPP_SDE + SGM_UNIFORM
    DMPP_SDE + KARRAS
    DMPP_SDE + EXPONENTIAL
    DMPP_SDE + BETA
    DMPP_SDE + NORMAL
    DMPP_SDE + DDIM_UNIFORM
    DMPP_SDE + LINEAR_QUADRATIC
    DMPP_SDE + KL_OPTIMAL
    Bright / Airy
    Bright / Airy
    Moody
    Moody
    Dark
    Dark
    Soft / Dreamy
    Soft / Dreamy
    Ethereal
    Ethereal
    Analog / Film Grain
    Analog / Film Grain
    Vintage
    Vintage
    Retro
    Retro
    Nostalgic
    Nostalgic
    Vaporwave
    Vaporwave
    Synthwave
    Synthwave
    Cyberpunk
    Cyberpunk
    Futuristic
    Futuristic
    Dystopian
    Dystopian
    Utopian
    Utopian
    Minimalist
    Minimalist
    Maximalist
    Maximalist
    Clean
    Clean
    Grunge
    Grunge
    Gothic
    Gothic
    Luxury
    Luxury
    Cozy
    Cozy
    Street Style
    Street Style
    Whimsical
    Whimsical
    Surreal
    Surreal
    Psychedelic
    Psychedelic
    Glitch
    Glitch
    Y2K
    Y2K
    Dark Academia
    Dark Academia
    Light Academia
    Light Academia
    Neon
    Neon
    Pastel
    Pastel
    Monochrome
    Monochrome

    Just aesthetics is not enough

    The benchmark proved that by changing just the aesthetics value will cause no identifiable changes to the output result. Z-Image can not understand the aesthetic value on it’s own, rather you have to change completely one portion of the prompt to ensure the aesthetic is described in more words.

    Take a closer look on the next examples with comparison on aesthetics word value and whole portion prompt rewriting.

    Important note: Styles like surreal, glitch, dystopian and others similar that pushes a very specific appeal to the end result will absolutely not be considered by Z-Image rendering this model useless if your intent is anything other than Editorial / Street / Cinematic or Photorealistic.

    Neon
    Neon
    Neon + Extra prompting
    Neon + Extra prompting

    Final veridict

    By no means I am assuming that Z-Image Turbo has severe flaws, rather pin-pointing that this model seems to be built to attend a specific use: realism for editorial, cinematic and street photography featuring humans.

    Rendering objects can be complex for Z-Image and logos and specific parts details on objects can not be handled properly. For example: the vehicle is identifiable as a Ferrari but the logo, emblem and details on the wheels, handles and front lights are completely mishandled.

    Some of the details flaws can be rebuilt with upscaling techniques or even inpainting, thus, requiring an extra process to fix it.

  • Short Guide on Generating Perfect Product Imagery with AI for Small Business

    Short Guide on Generating Perfect Product Imagery with AI for Small Business

    Short Guide on Generating Perfect Product Imagery with AI for Small Business

    Using AI to generate the perfect shot or product placement of your product

    comfyui

    generative ai

    Product visualization

    The goal for any local or small-scale retailer is to produce content that performs two distinct roles: it must stop the scroll on social media and answer technical questions on the product page.

    For many small business owners, the primary barrier to digital growth isn’t the quality of the product—it’s the quality of the content. Capturing the rich texture of a fine leather purse or the subtle sheen of hardware requires a level of photographic skill, studio lighting, and post-production that is often financially out of reach for a lean operation. Without these professional visuals, even the most premium items can appear “homemade” on a storefront, which can inadvertently signal a lack of credibility and lead to lower conversion rates.

    Artificial Intelligence has fundamentally changed this dynamic, democratizing high-end production for local retailers. Instead of requiring a physical studio and a professional crew, business owners can now use AI as a digital art director and editor. By leveraging generative models, you can take a basic, well-lit photo from your smartphone and transform it into a sophisticated asset library. AI solves the perennial challenges of staging, lighting, and perspective, allowing small brands to present a visual identity that rivals global luxury houses at a fraction of the cost.

    From Smartphone to Storefront, build Brand Narrative and Lifestyle Context one Step at a time

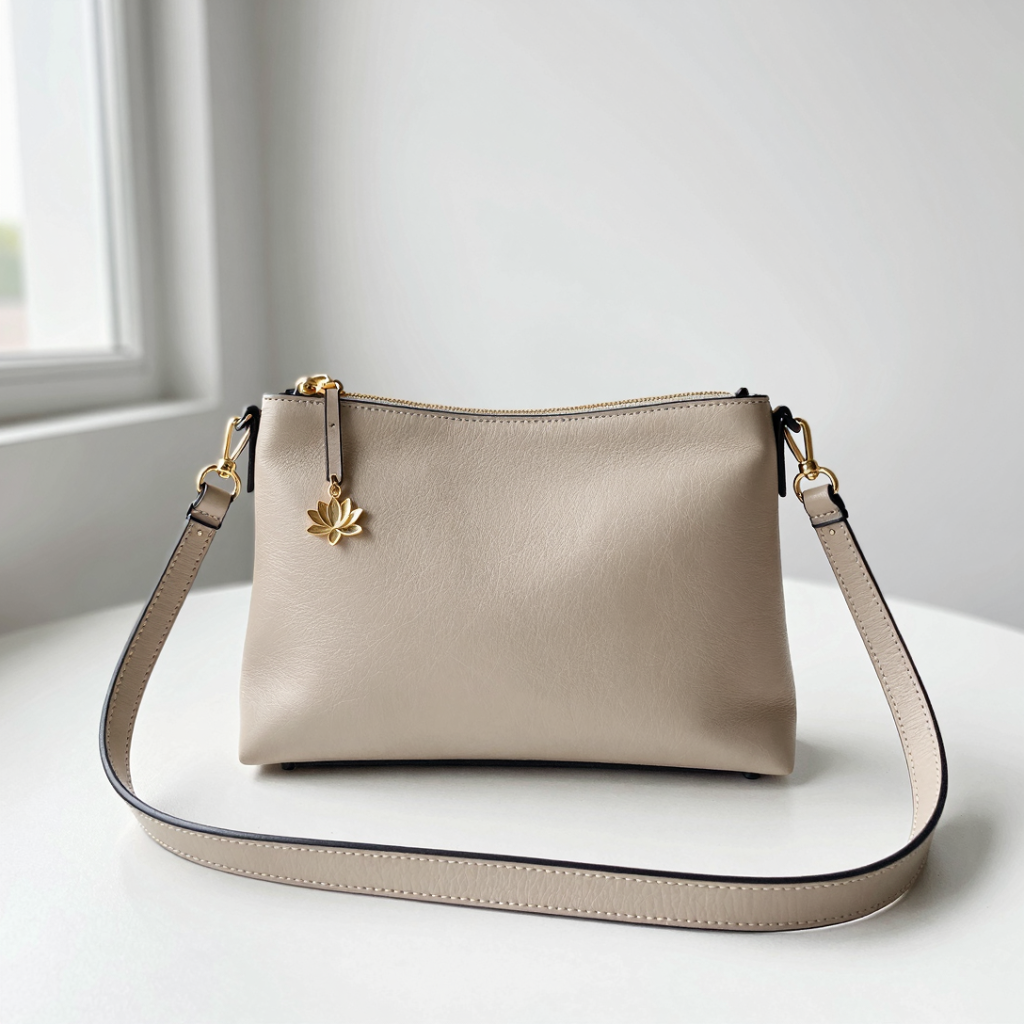
    Light beige leather handbag with gold-tone hardware and a lotus charm
    iPhone shot of the product taken by a person with no photography expertise

    1. Starting point

    For platforms like Instagram and TikTok, the goal is “aspirational storytelling.” The product needs to look like it belongs in the hands of your ideal customer.

    Using various AI models and workflows, we can take that basic iPhone photo and transplant the purse into a high-end, realistic setting without losing the integrity of the original leather texture, features, dimensions, details and other characteristics.

    ◄ Take the example here on the left: the purse was shot on iPhone using basic camera settings and natural lighting. The picture itself is not bad, would suffice for Marketplace or other online selling markets, but certainly is not good enough for a social media ad or e-commerce presentation.

    2. The German, the Chinese and the American Models

    The original image has to have some correction done. By adding some dynamic characteristics to the main element we can better grab the attention of the audience. But how/which AI Model to use?

    In order to accomplish that, we have to remove the background, change the camera lens length, maybe even change the angle a little bit. Adding more context to the image means choosing a scenario and a story to tell.

    As of January 2026 there are three main AI Edit Models competitors on the market: Flux Kontext is the German AI model, Qwen Edit is the Chinese AI model and Gemini Nano Banana  is the popular American AI model. All of them have pros and cons which let us adjust through a prompt all the changes we need. Take a look at the comparison pictures below using the same edit requests.

    Click images to see larger version.

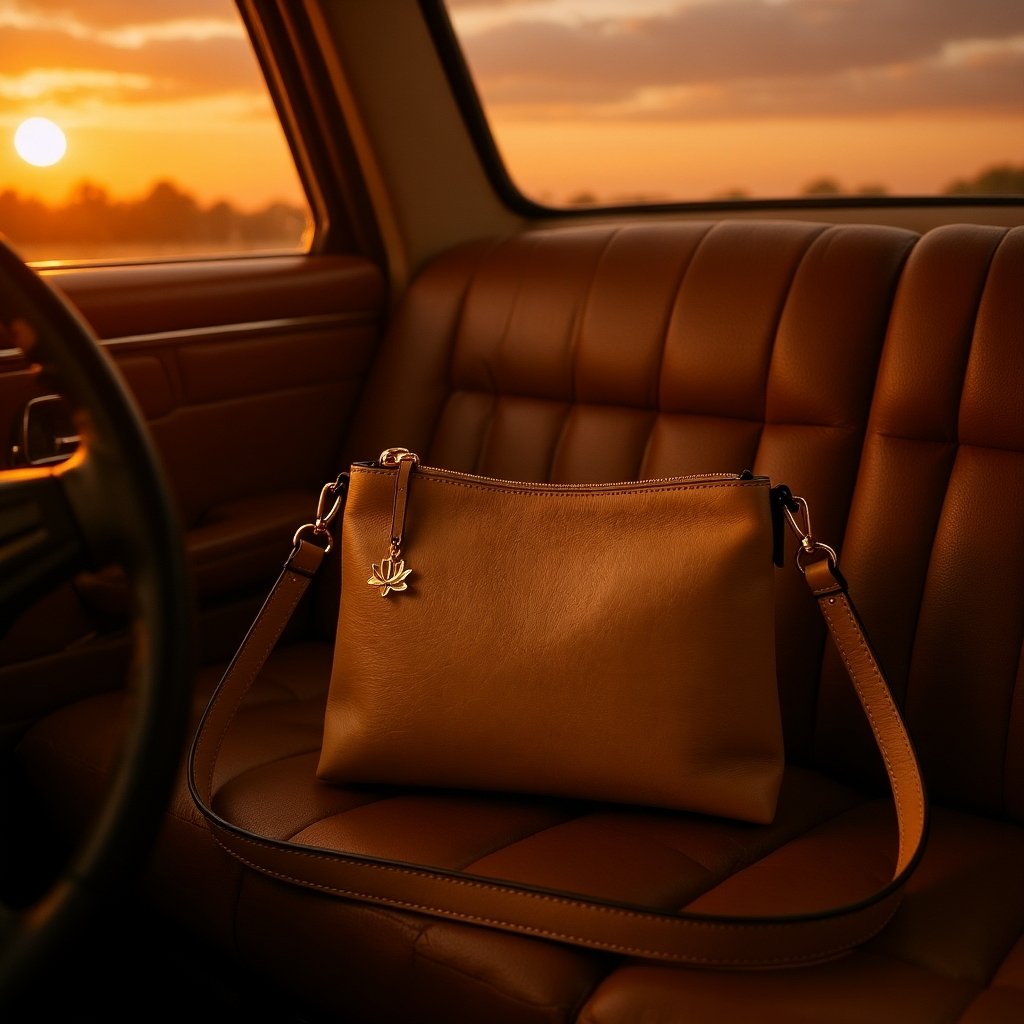
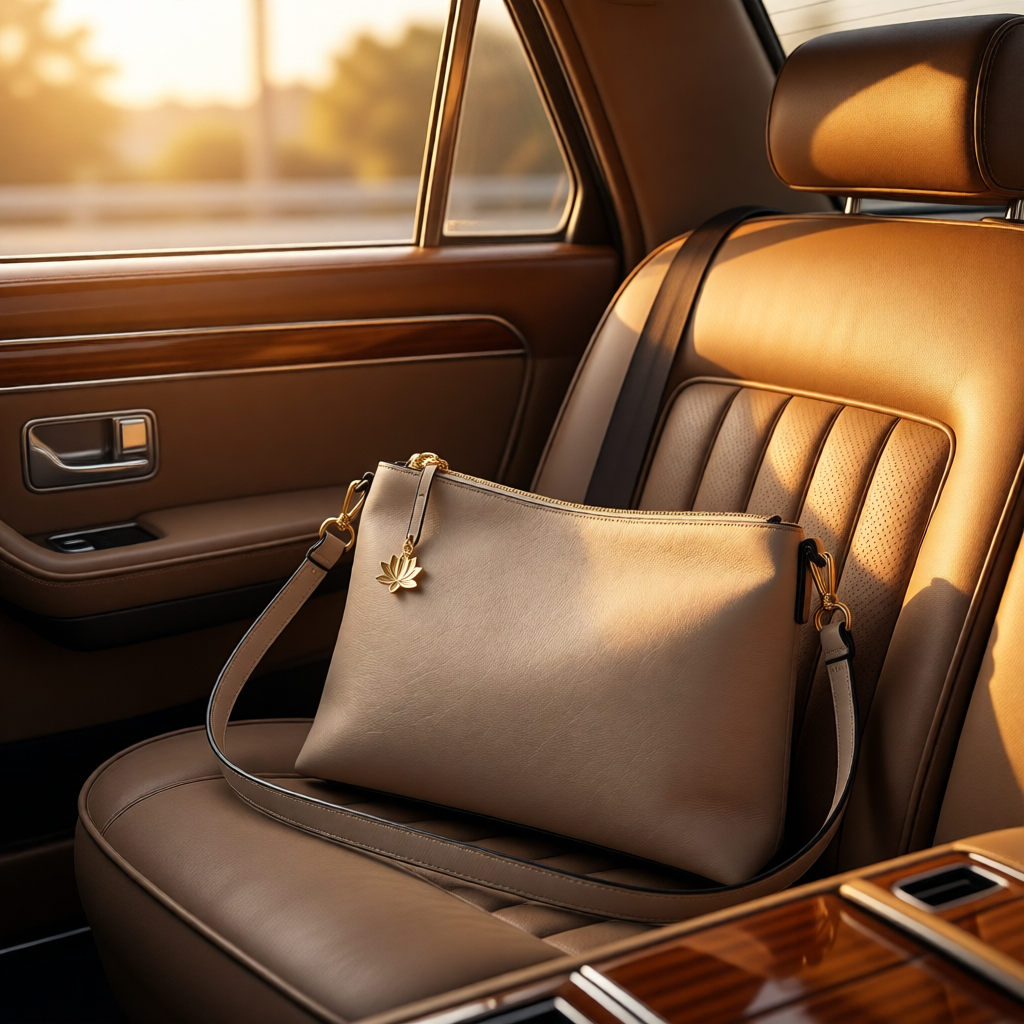
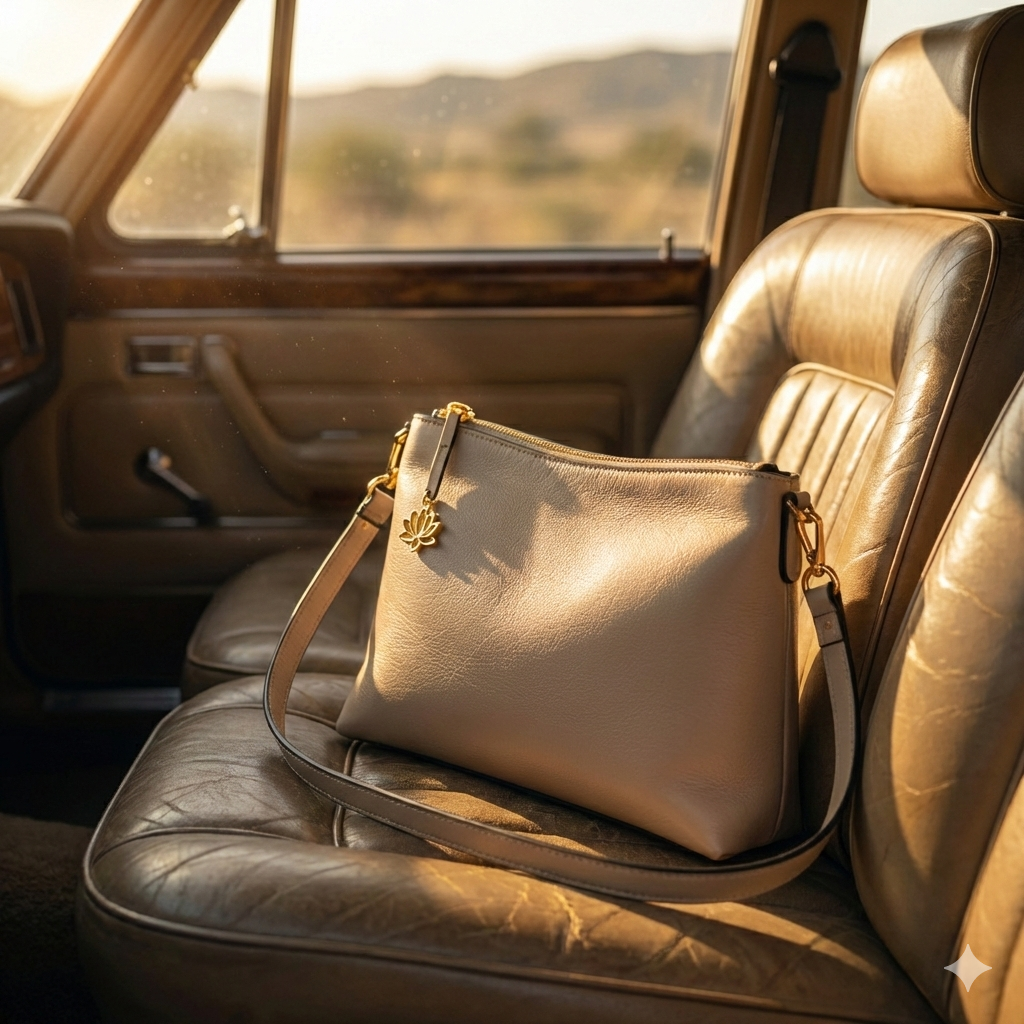
    Beige leather crossbody bag with a gold lotus charm sitting on the worn leather seat of a vintage car during golden hour.
    Edit generated with Flux Kontext – German model
    Beige leather crossbody bag with a gold lotus charm sitting on the worn leather seat of a vintage car during golden hour
    Edit generated using Qwen – Chinese model
    Beige leather crossbody bag with a gold lotus charm sitting on the worn leather seat of a vintage car during golden hour.
    Edit generated using Gemini – American model

    Although all three results looks good, they are far beyond something professional. The dimension of the purse is affected and even the background looks distorted or way too much artificial. The overall mood, light technique and camera angle seems good, but placing the product requires more steps. For that, we are going to add extremely targeted details in the prompting.

    All of them need obvious adjusts, including the purse dimensions that are way too off.

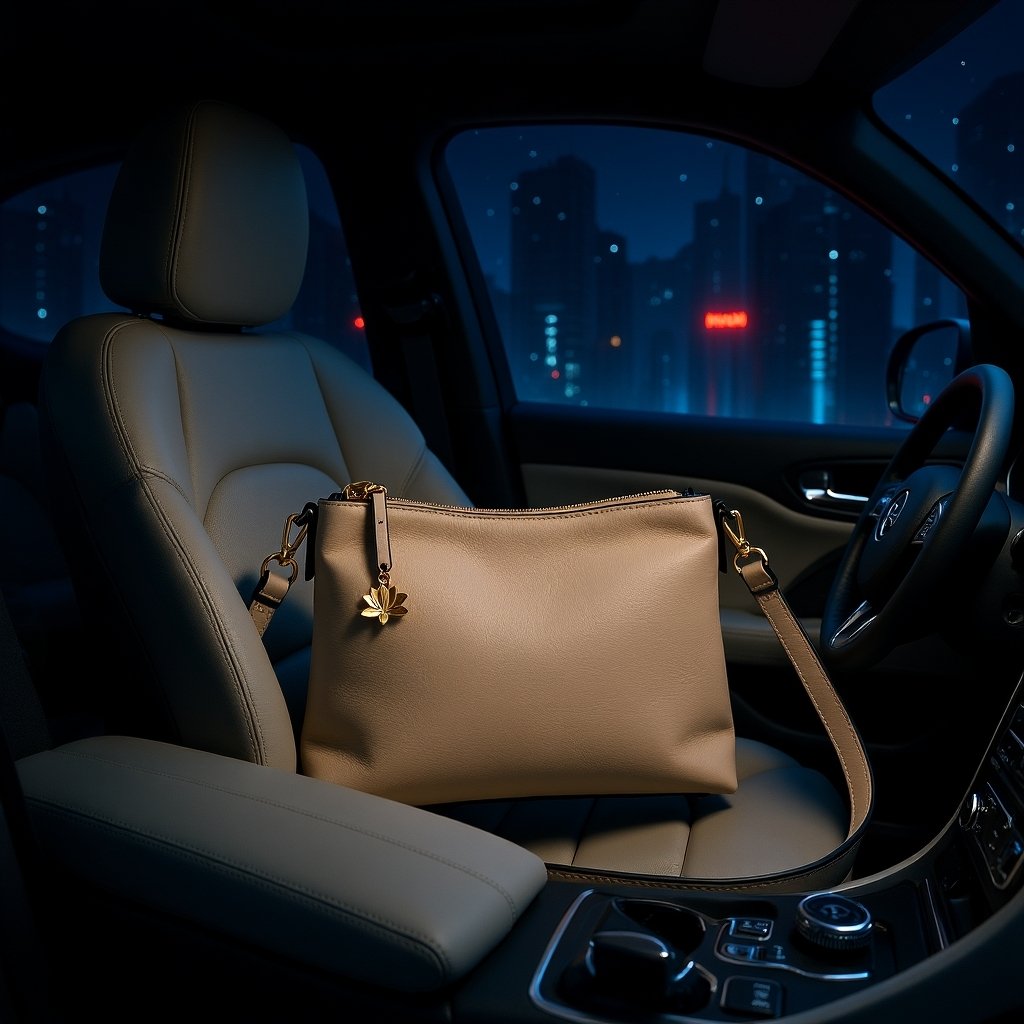
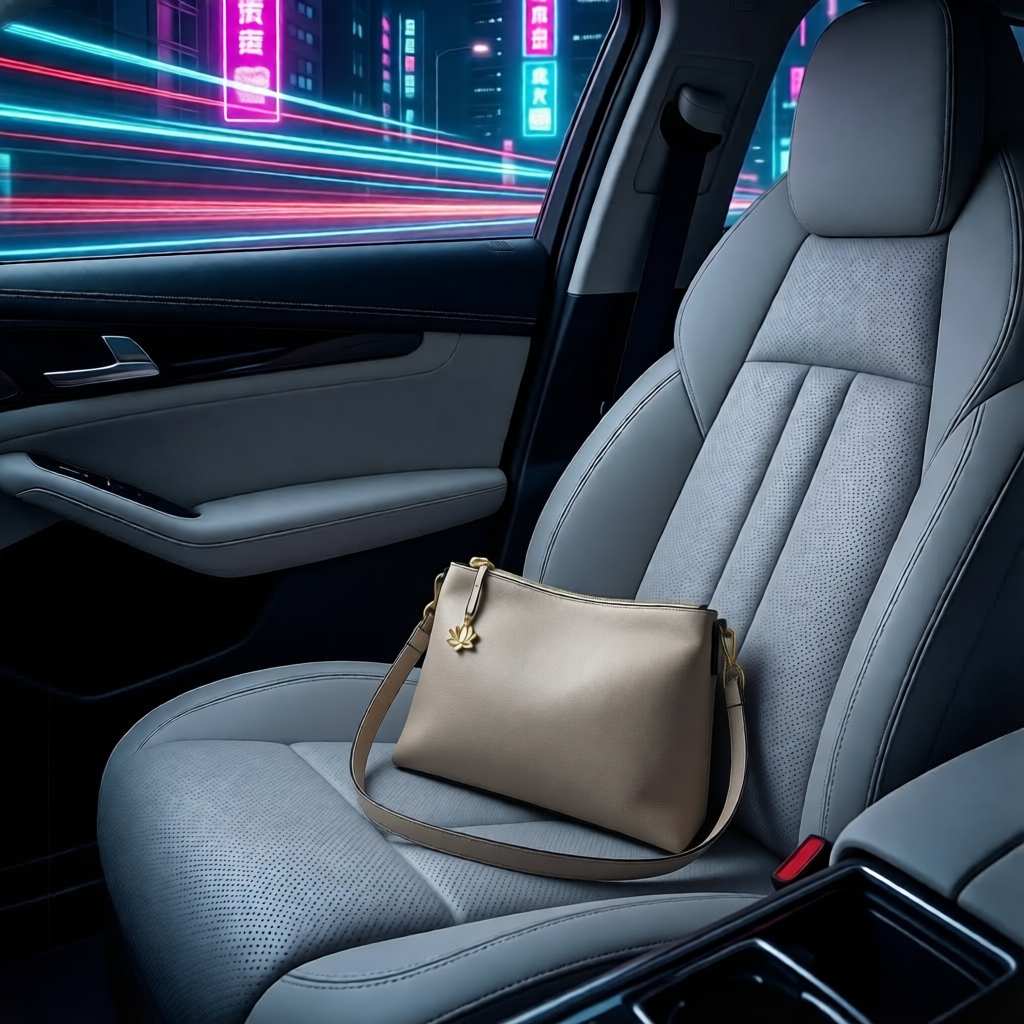
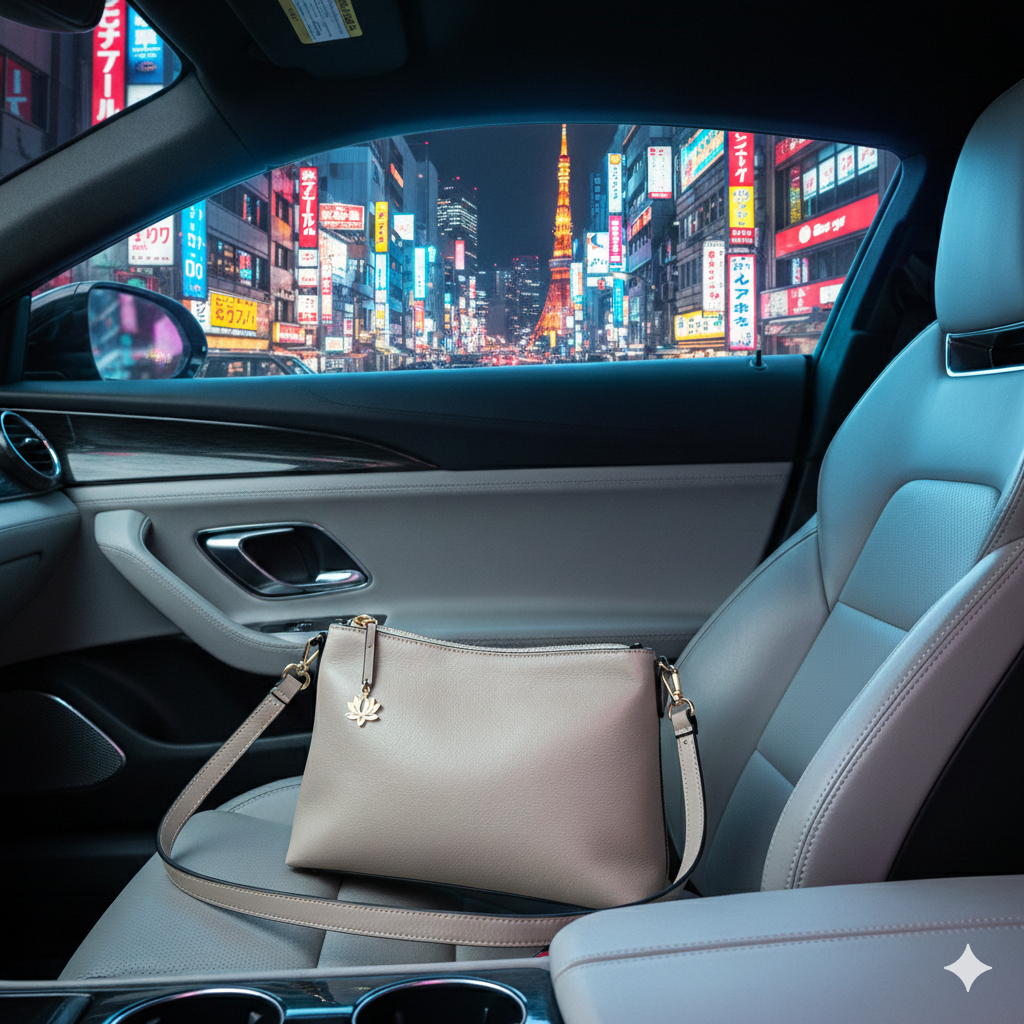
    A fashion photography showing this light tan beige textured leather handbag with its gold lotus charm resting on the light grey leather passenger seat of a sports luxury car. Neon and artificial city lights streams through the side window, creating a bit of chromatic aberration and highlighting the rich textures of the bag and the modern car interior. The atmosphere is cyberpunk and cinematic. Sharp details, sharp textures.
    Edited with Flux – German model
    Purse is smaller – Qwen Edit – Chinese version
    Futuristic background is removed and changed to a night scene in Tokyo – Gemini – American version

    3. Reshooting the product for professional usage

    Light beige leather handbag with gold-tone hardware and a lotus charm
    Original iPhone shot

    High-quality, professional images are rewarded by search engine algorithms. By using AI to generate clean, high-resolution catalog shots, you improve your chances of appearing in Google Image Search. When you name these files descriptively, you are actively building an SEO foundation that brings local customers directly to your door.

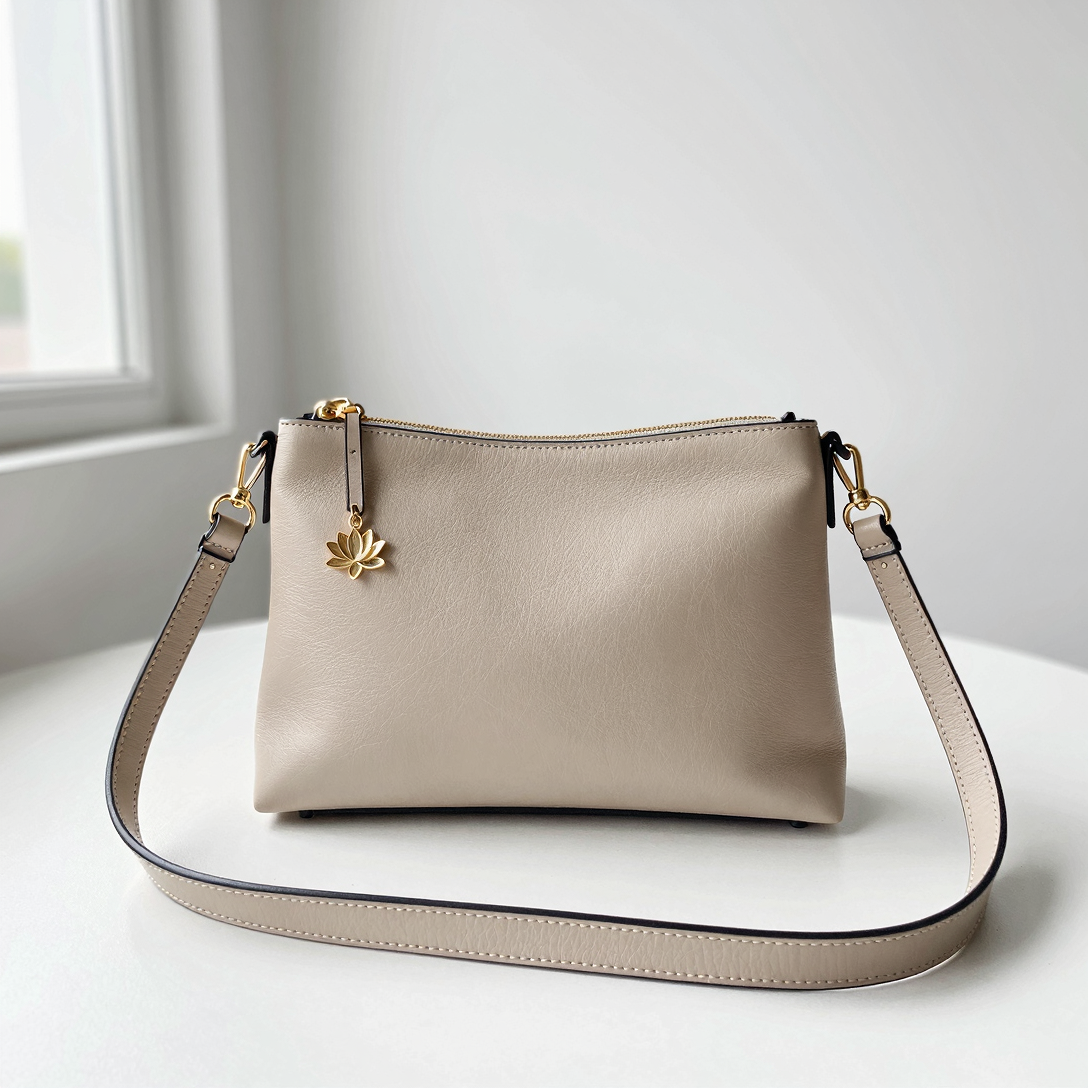
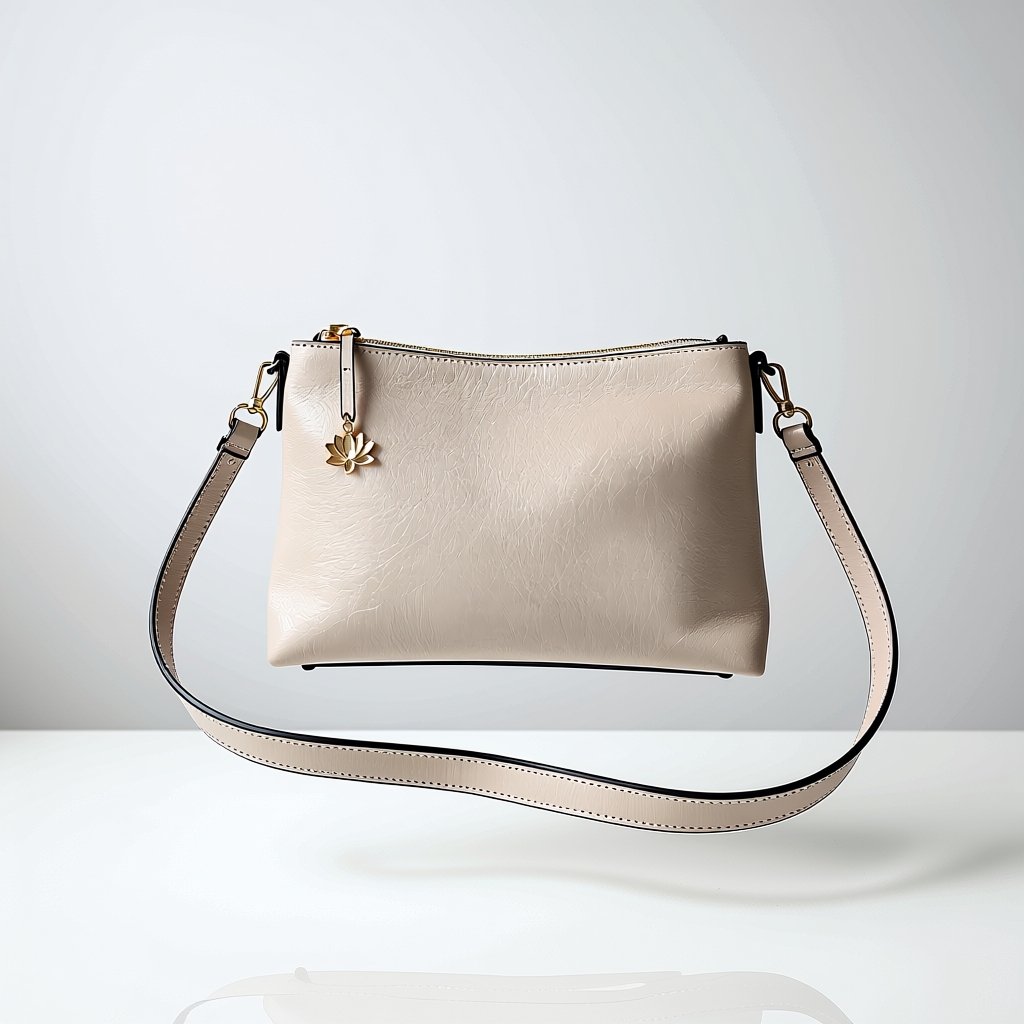
    Beige leather handbag with a gold lotus charm floating in a minimalist, bright studio setting with soft lighting.
    Edit using DEIS Sampler
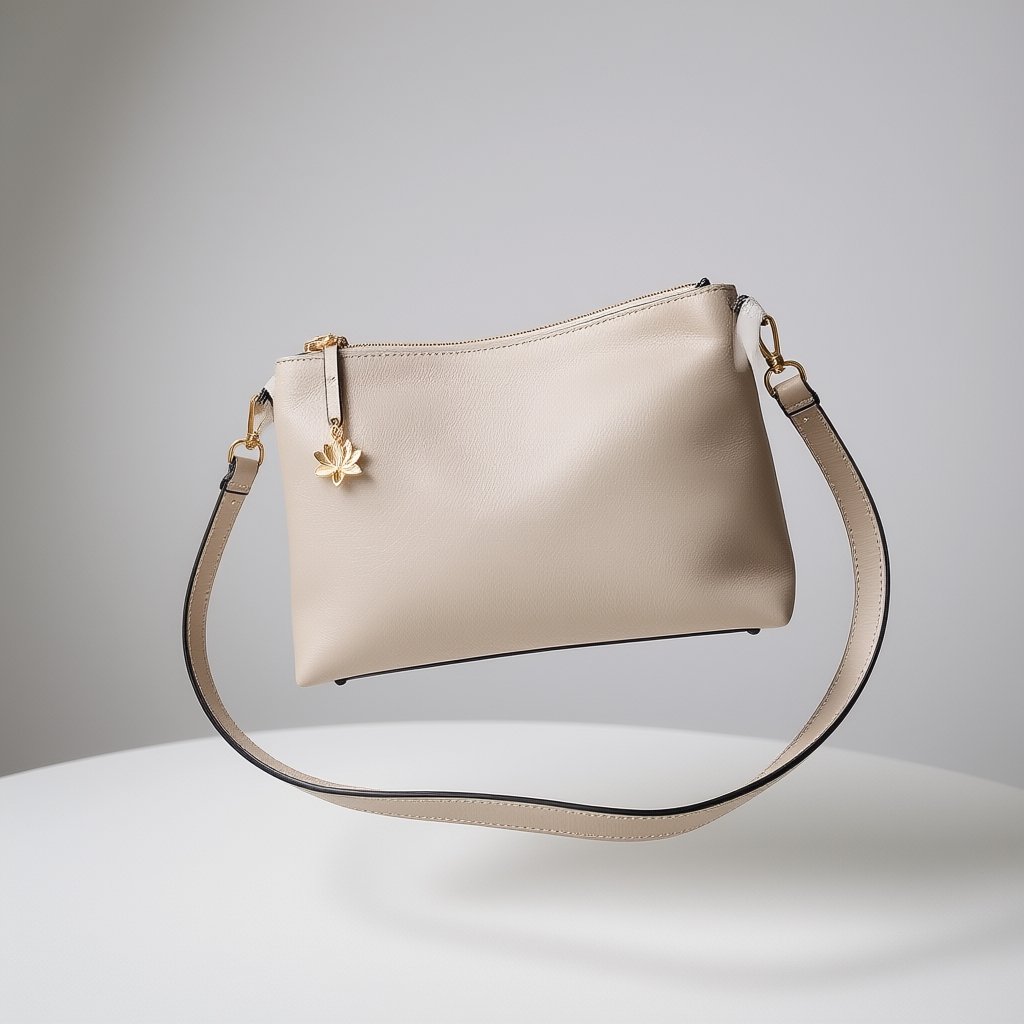
    Beige leather handbag with a gold lotus charm floating in a minimalist, bright studio setting with soft lighting.
    Edit using EULER Sampler
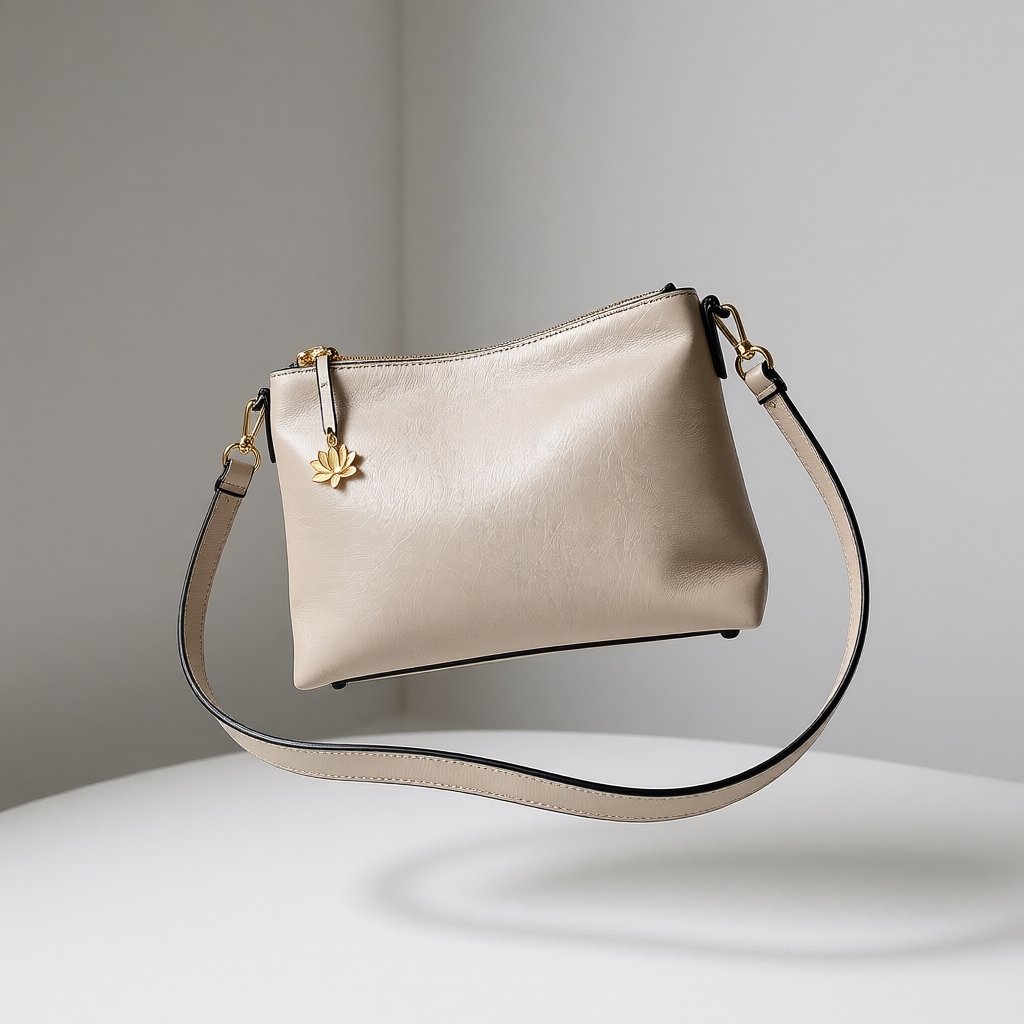
    Beige leather handbag with a gold lotus charm floating in a minimalist, bright studio setting with soft lighting.
    Edit using DMPP_2M Sampler

    The “levitating” approach for this product goes hand in hand with its premise. This is why we are going to make further edits and use this idea as our main central point to promote this product.

    Light beige leather handbag with gold-tone hardware and a lotus charm
    Original product shot on iPhone

    +

    Minimalistic abstract gentle light beige background for product presentation with light andand intricate shadow from the window and vegetation on wall.
    Background image on sale on iStockPhoto

    All of them are loosing quality as new generations are made. Once the right posing is found, we have to take it to an upscale model.

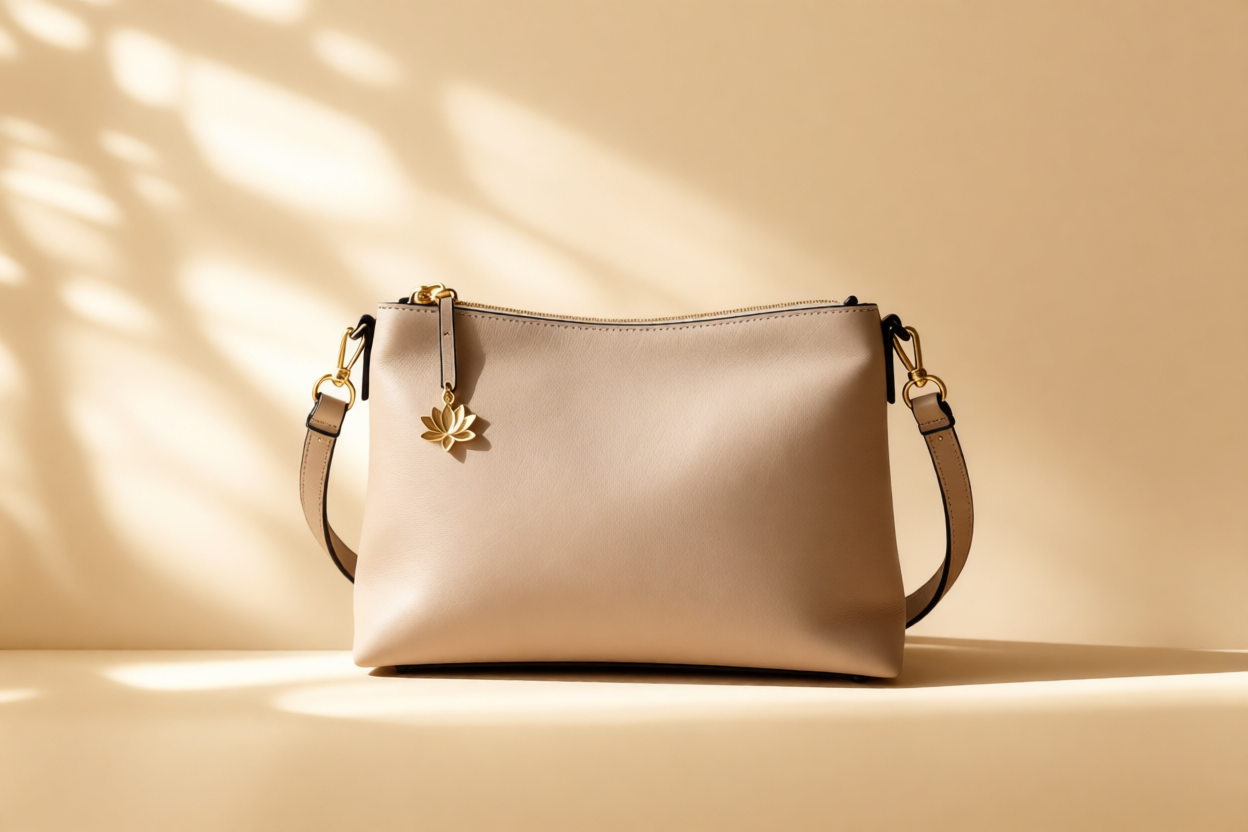
    The product was placed on the chosen background and all the merge details were taken care of by the AI model
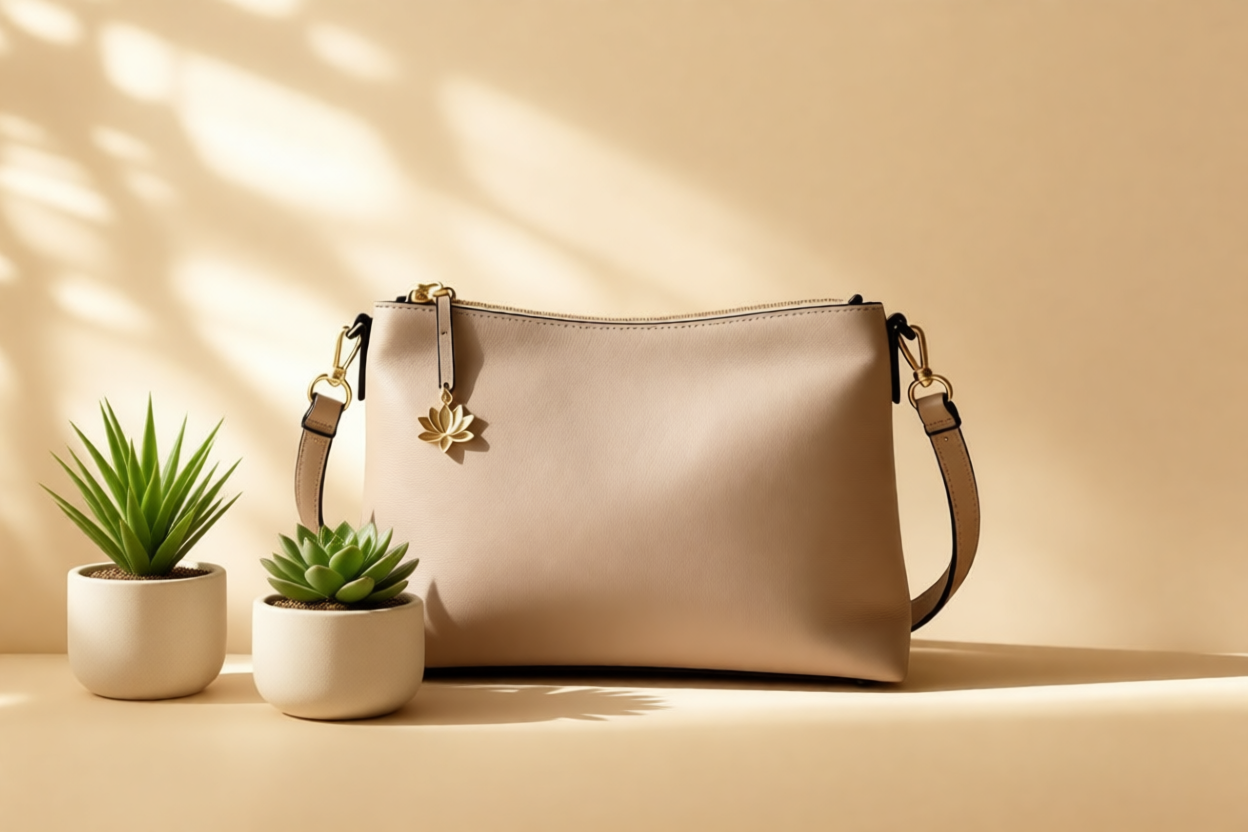
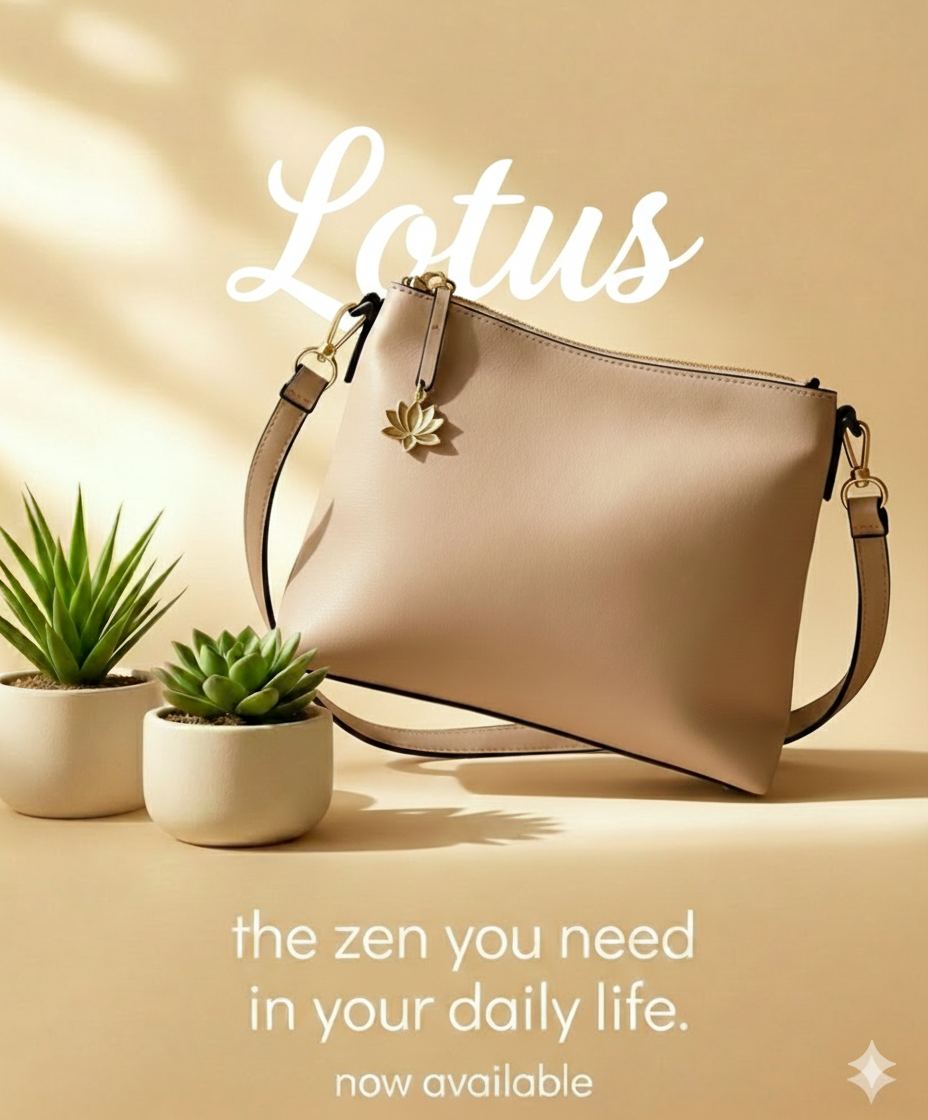
    Added a pair of plants to contrast and counterbalance the composition, so it does not look flat and even.
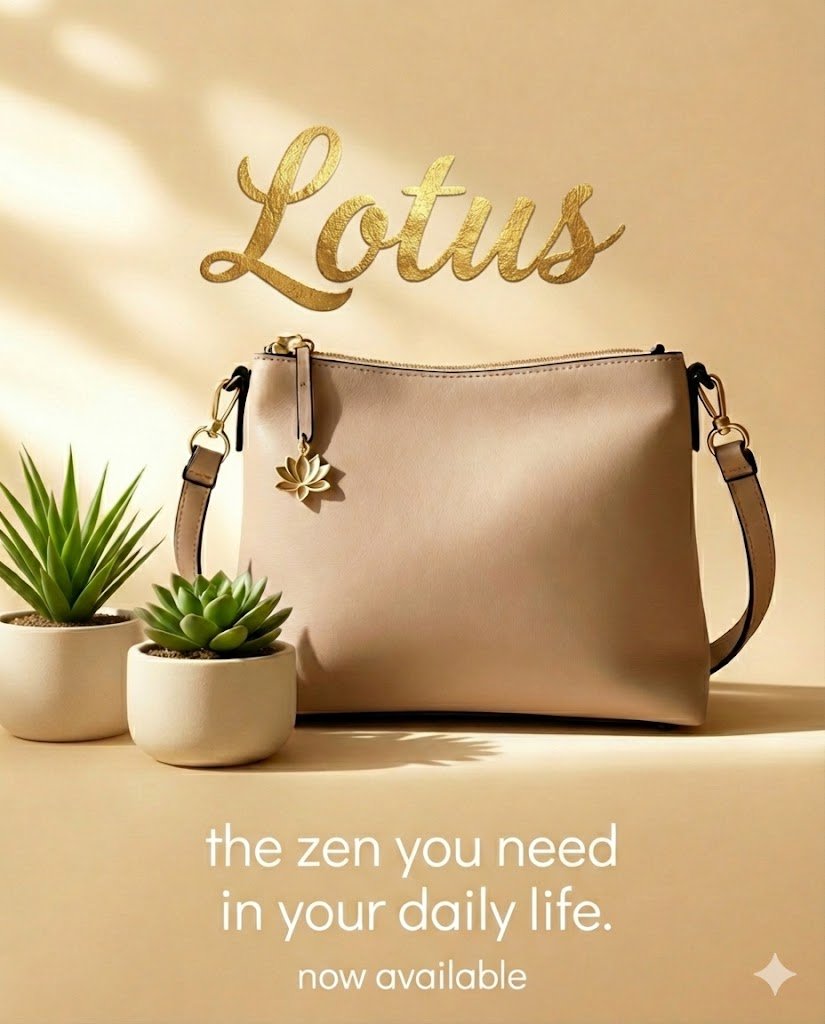
    Edited with Gemini - Changed product position and added text element
    Changed product position and added text element
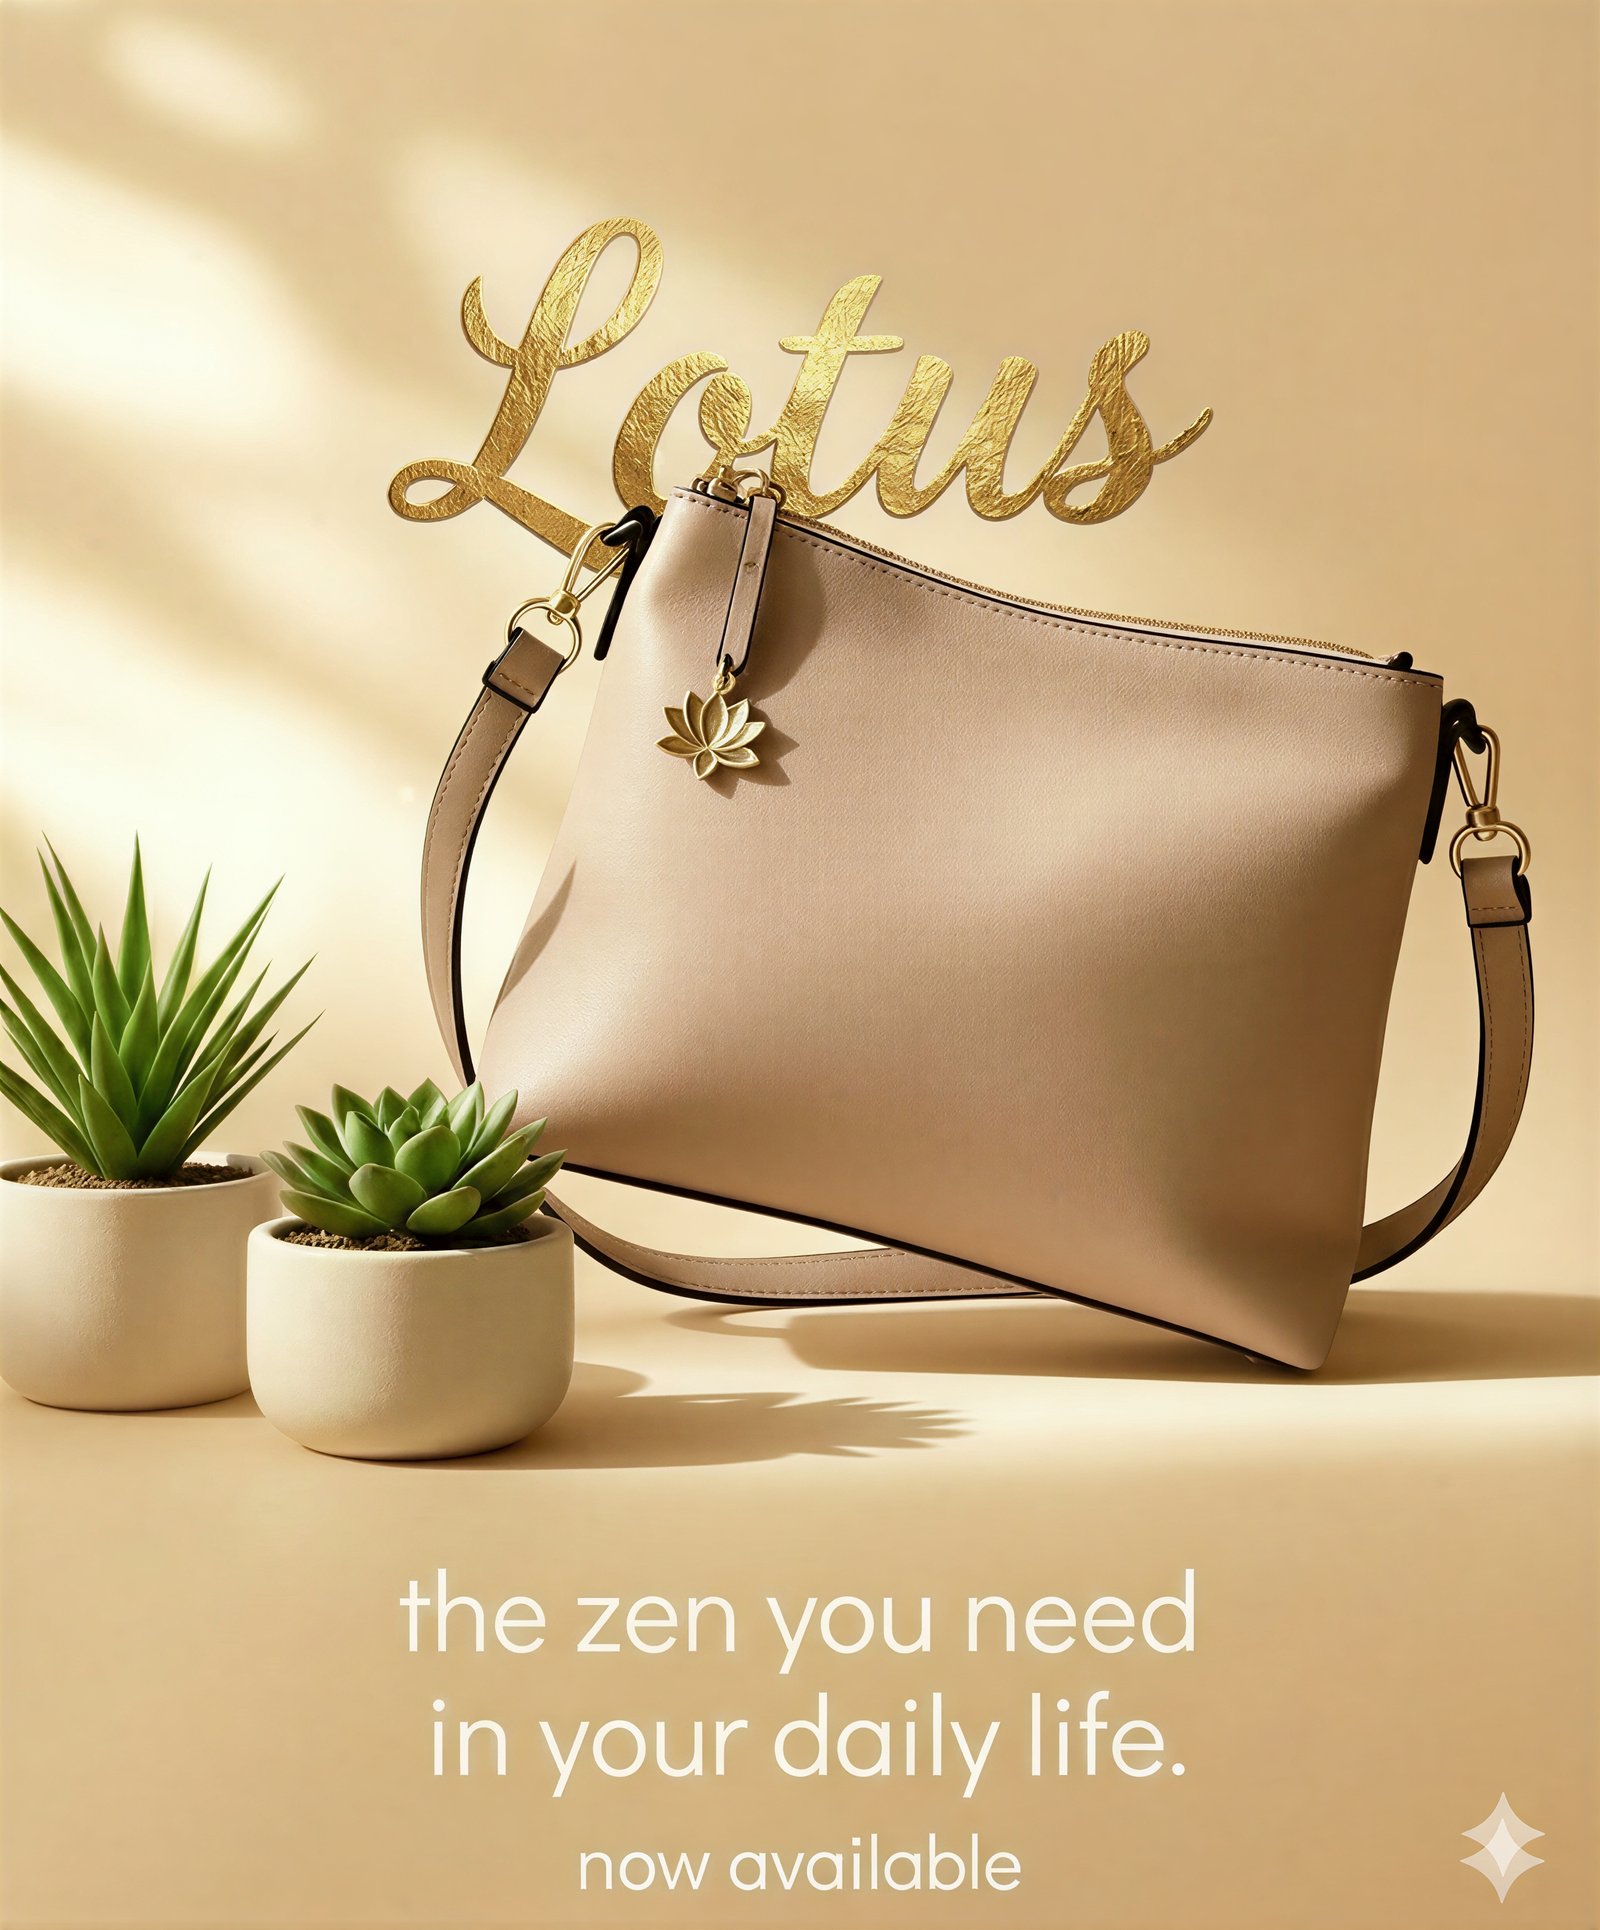
    Edited with Gemini - Changed logo texture
    Changed logo texture
    Upscaled final image ready to be used for a social media ad
  • Z-Image Comparison Test

    Z-Image Comparison Test

    Z-Image Comparison test

    benchmark on model shift / steps / scheduler

    Just a few days after Flux 2 hiting the AI scene on end November 2025, the chinese came along and shove both feet at the door with this Qwen based fast model called Z-Image that excels in realistic portraits, celebrities and landmarks.

    This my personal comparison chart to benchmark its features and this is my attempt to understand what each node does and what each settings affects the generated result. Follow along to check it for yourself too.

    Seed = fixed
    Steps = see comparison below
    CFG = 1 (will adhere strictly to the prompt, without deviations)
    Sampler = res_multistep (suggested by the model’s author)
    Scheduler = simple (suggested by the model’s author)
    Denoise = 1

    No LORAS, no extra nodes

    Timestamps are based on a GeForce 3080TI 12 GB RAM

    Positive Prompt below / Negative Prompt = none

    steps

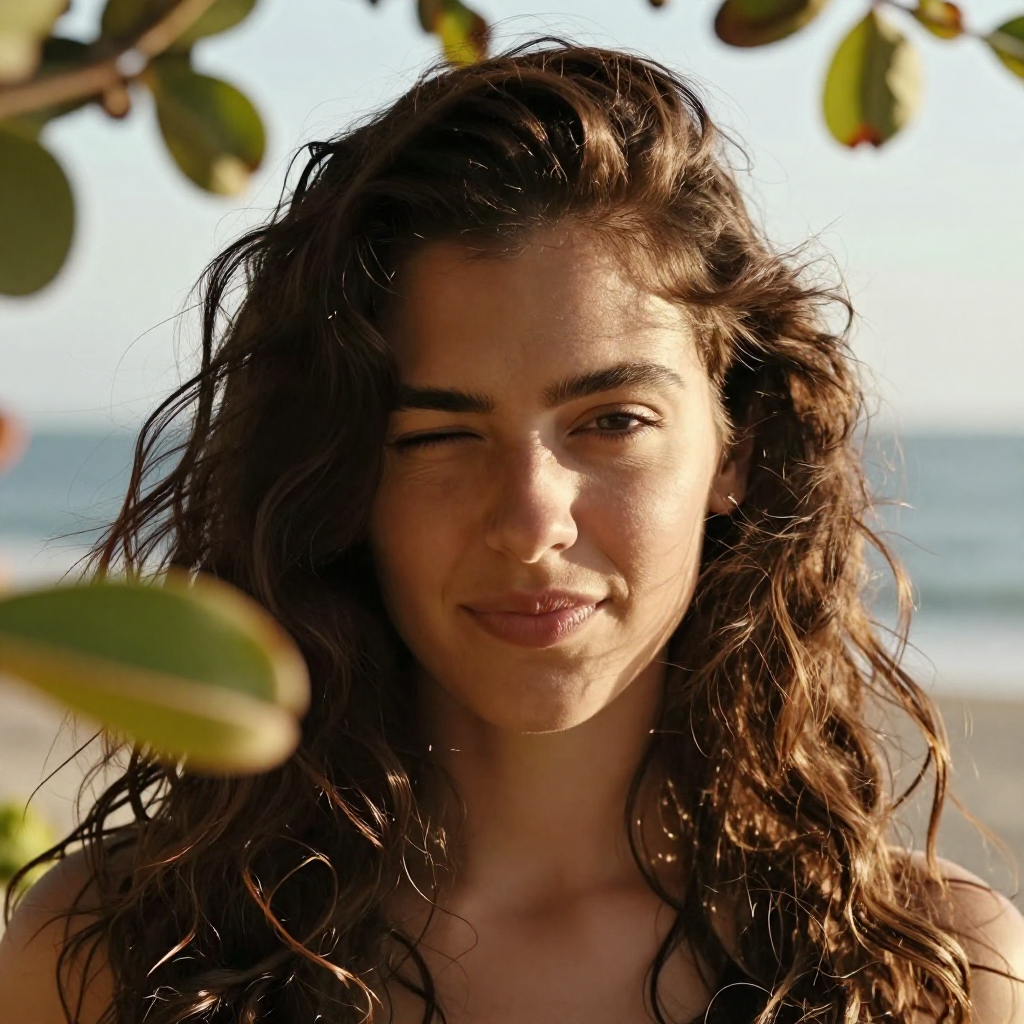
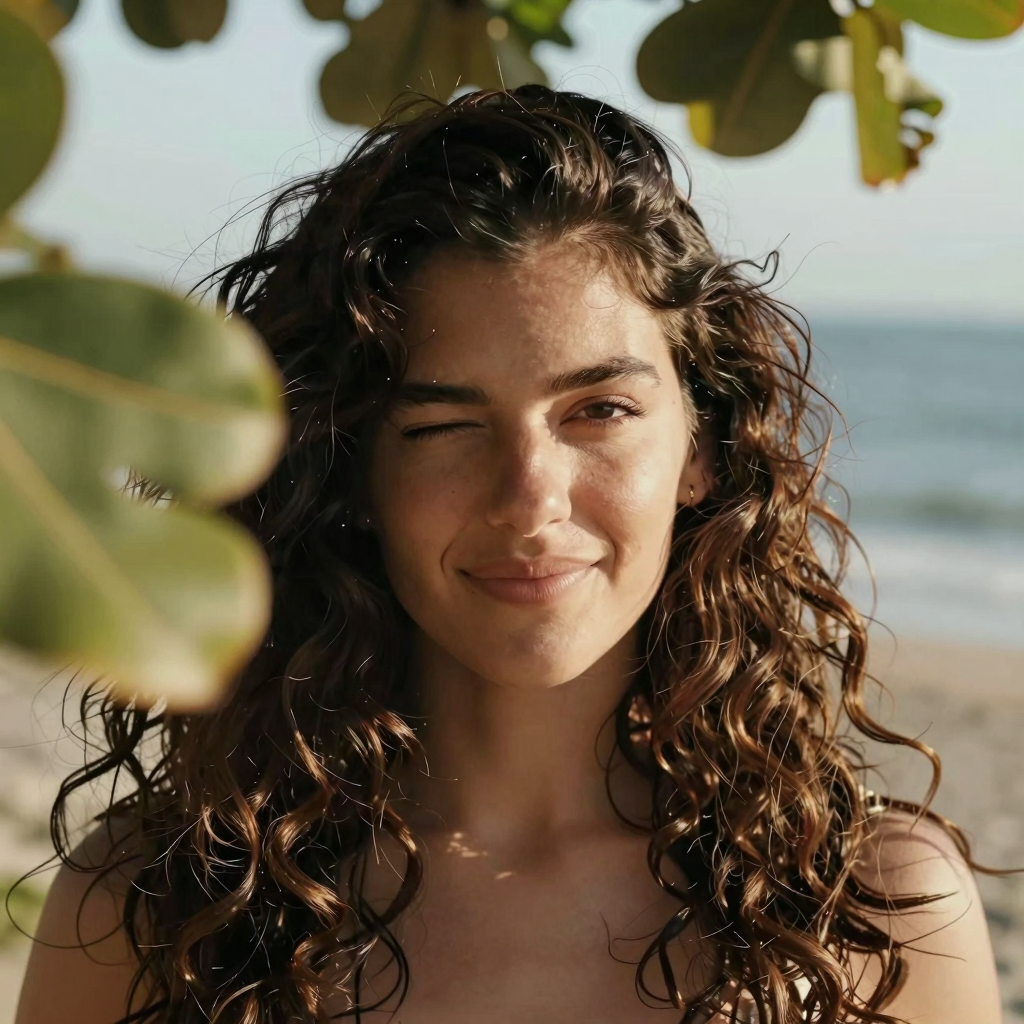
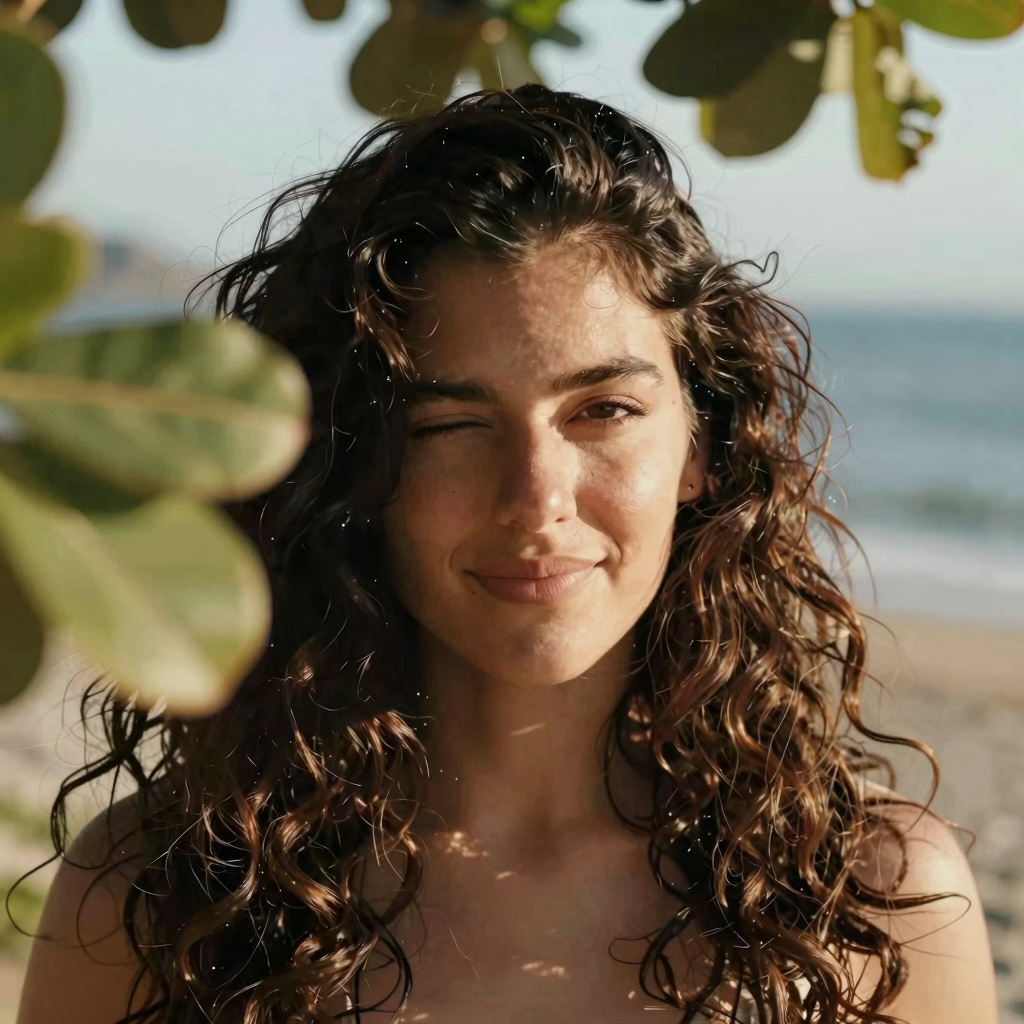
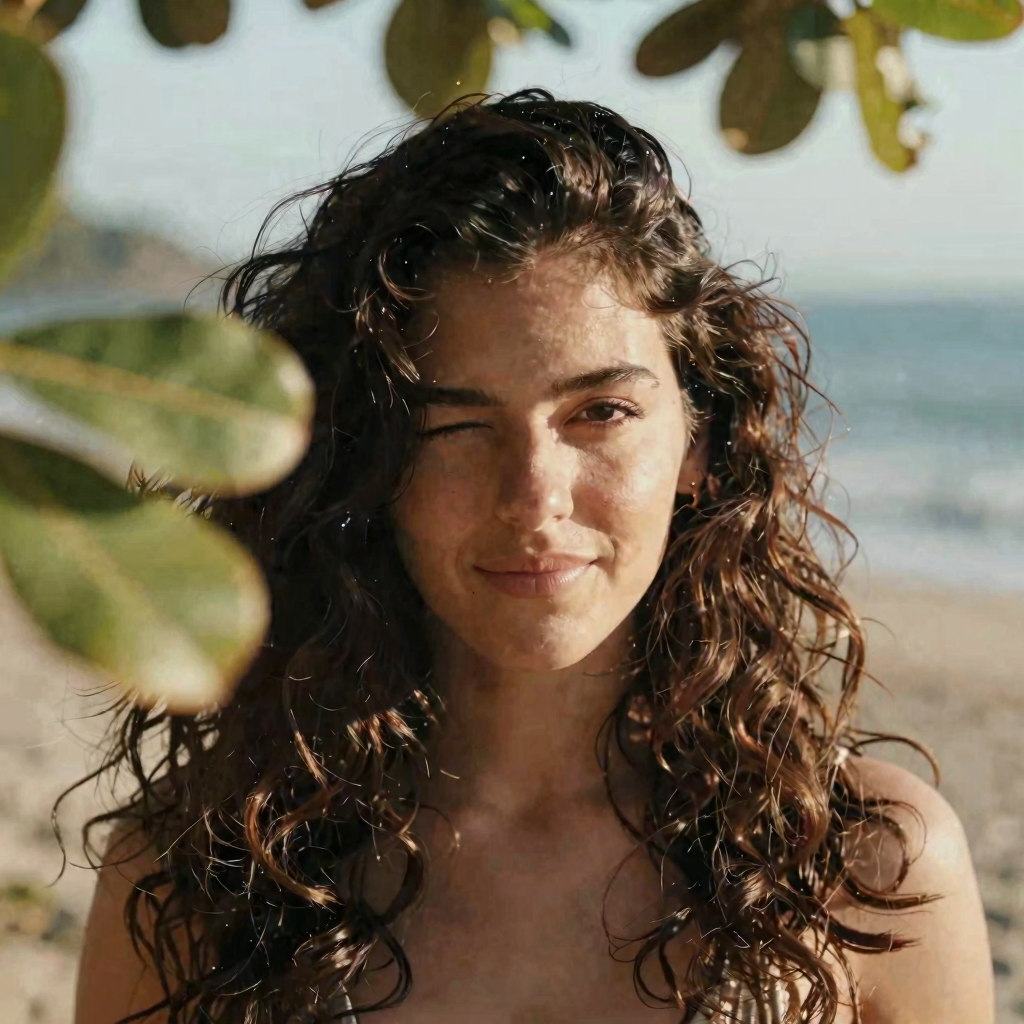
    Steps means how many times the latent space will be calculated before delivering the final output. Z-Image is a fast model and was developed to use less steps. Here, I found the best results are between 8 and 12. Less steps generates too few details, more steps generates extra noise and some inconsistencies, mainly on the hair.

    				
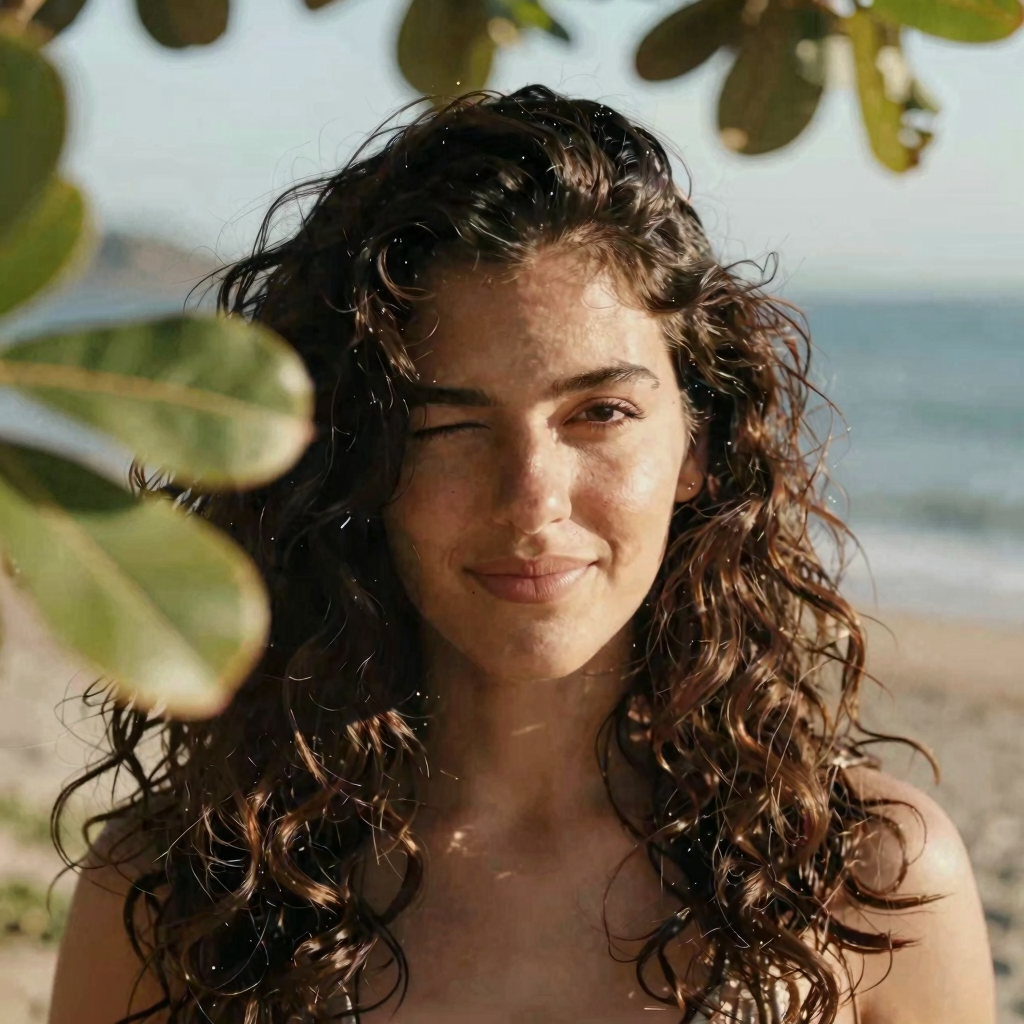
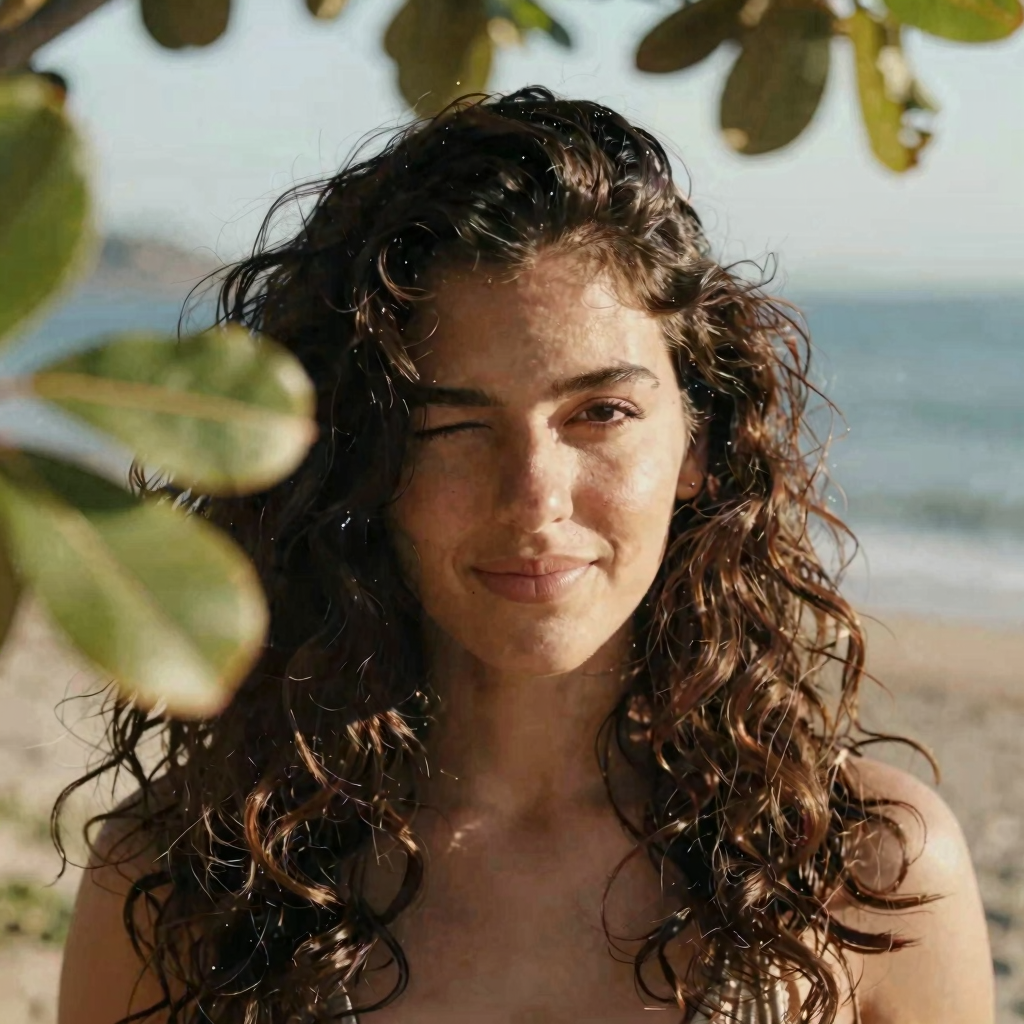
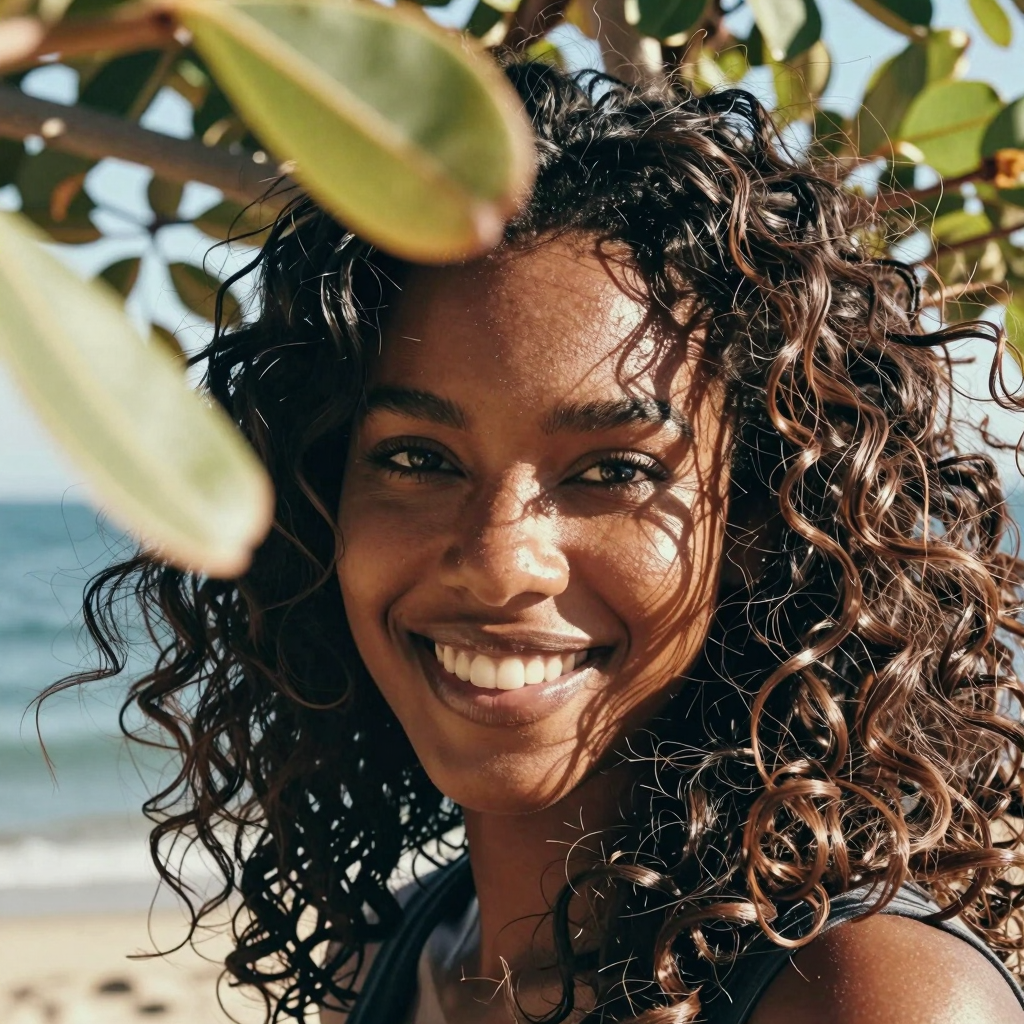
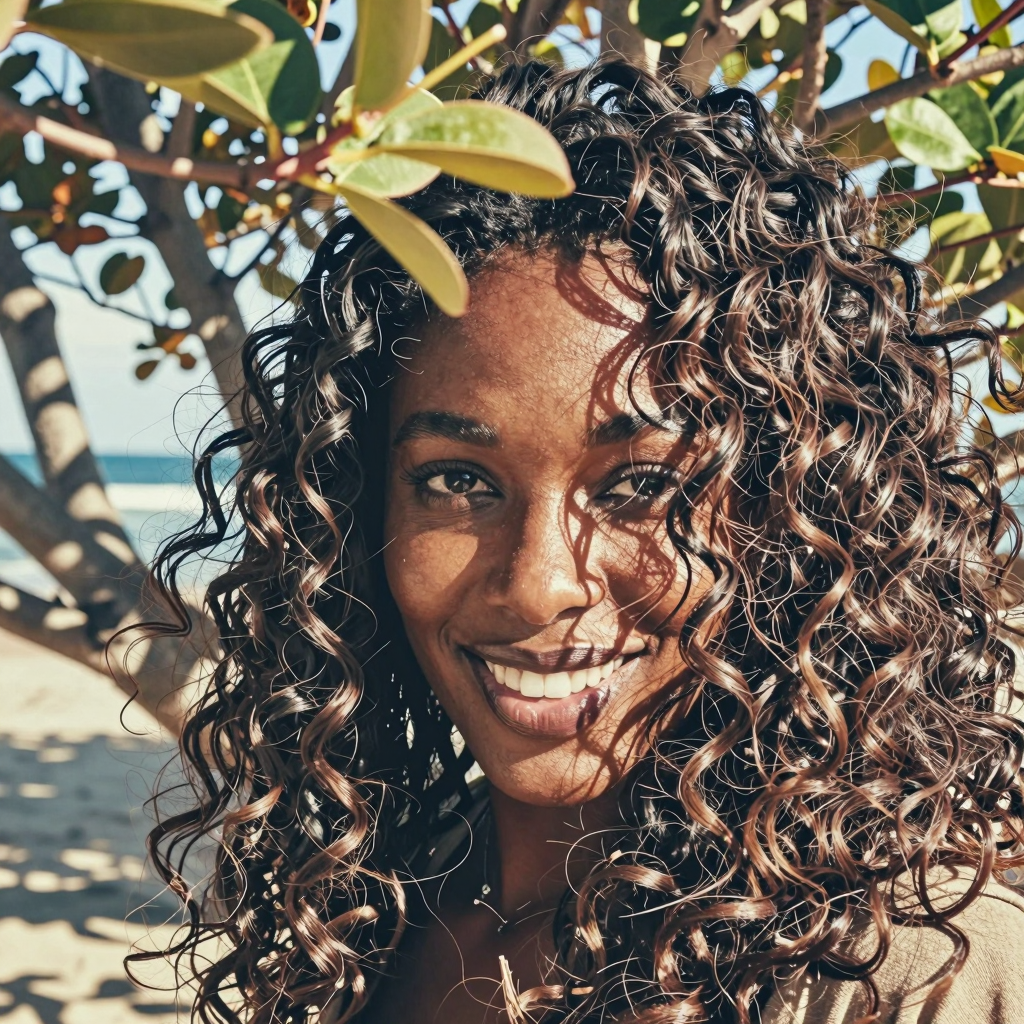
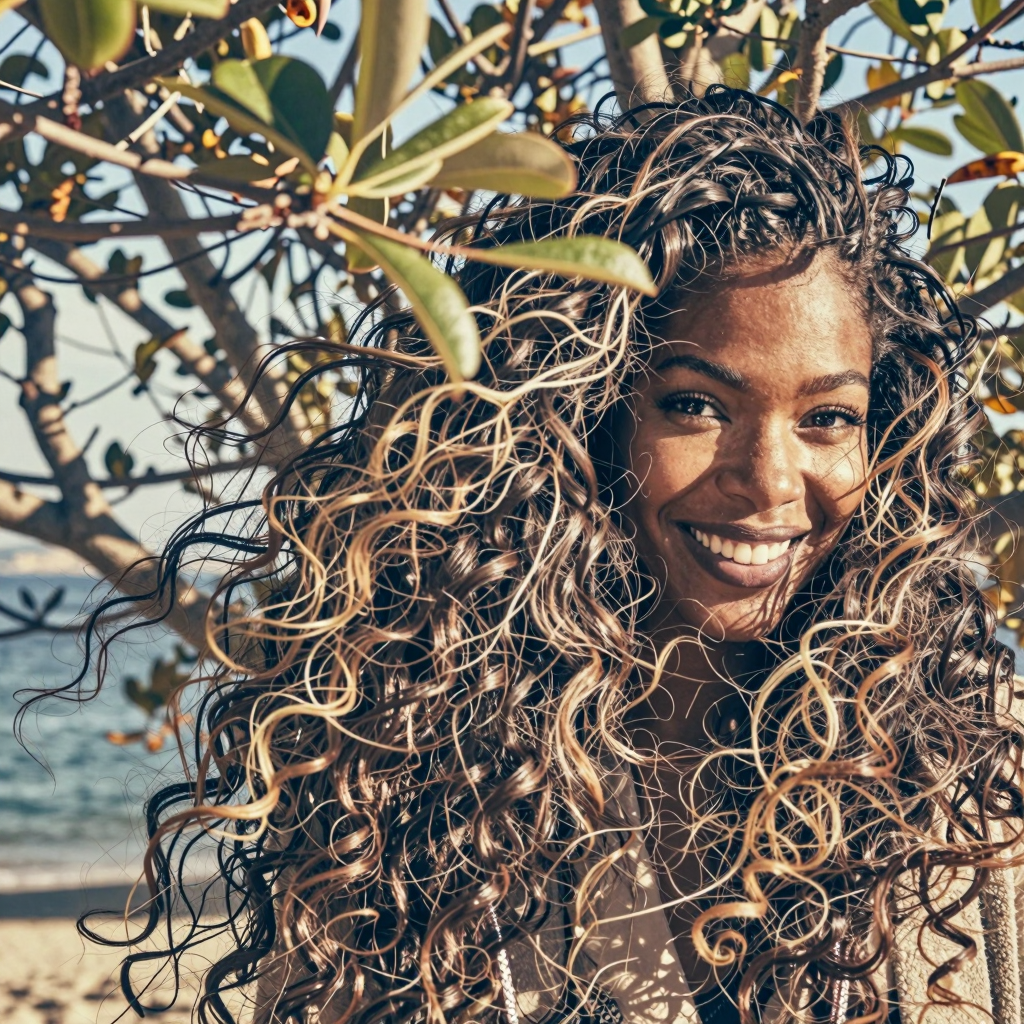
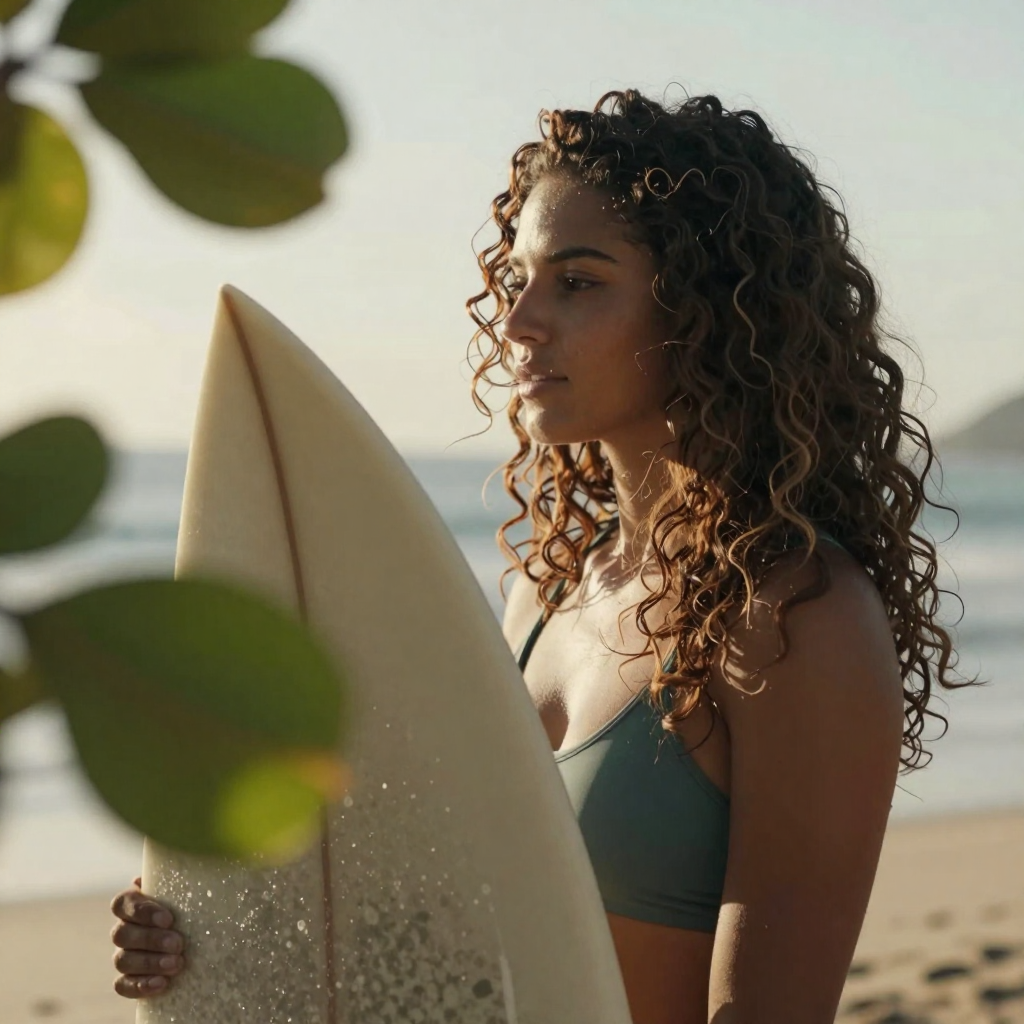
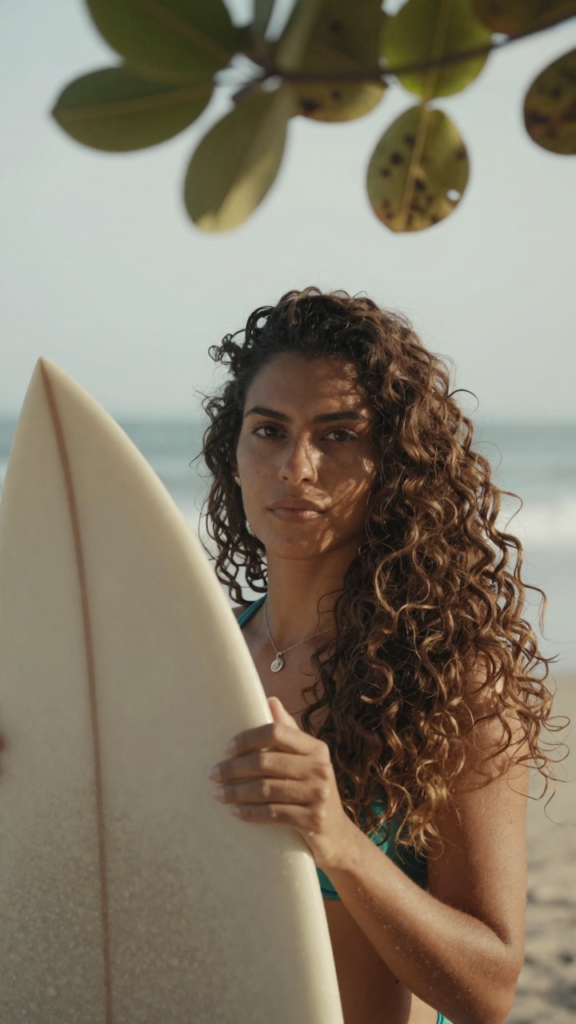
    					Latina female with thick wavy hair, blinking to the camera, there are some out of focus tree leaves in front of her. Breezy seaside light, warm tones, cinematic close-up.


    Steps 4
    Time 7″

    Steps 8
    Time 12″

    Steps 12
    Time 18″

    Steps 24
    Time 26″

    Steps 32
    Time 44″

    Steps 50
    Time 68″

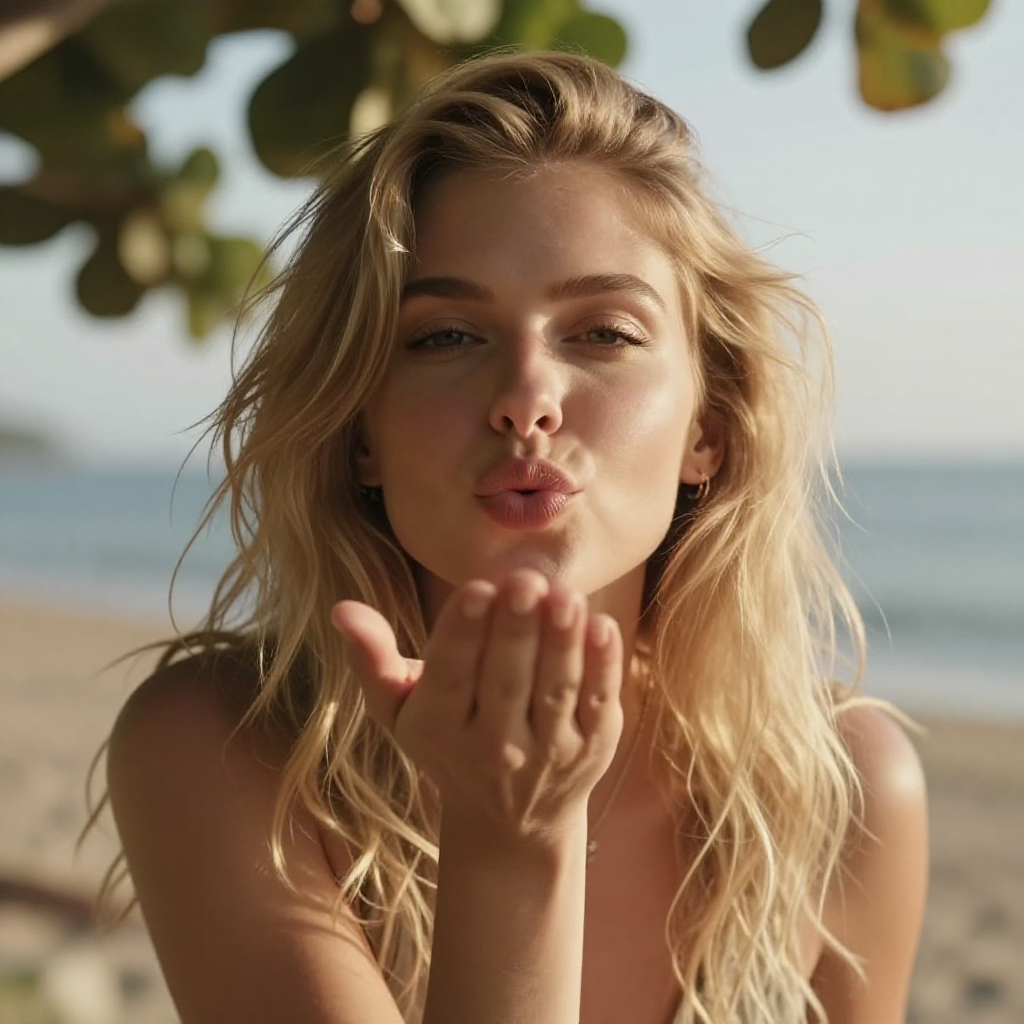
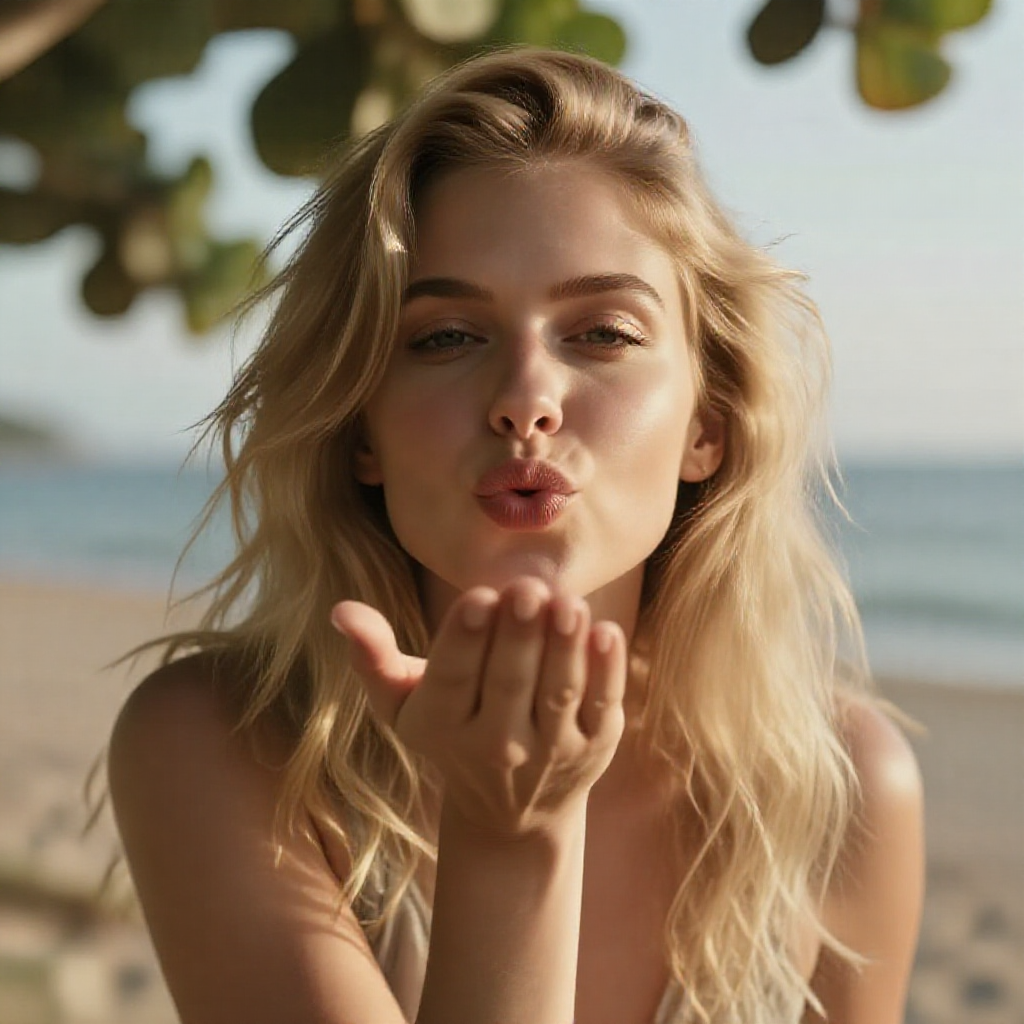
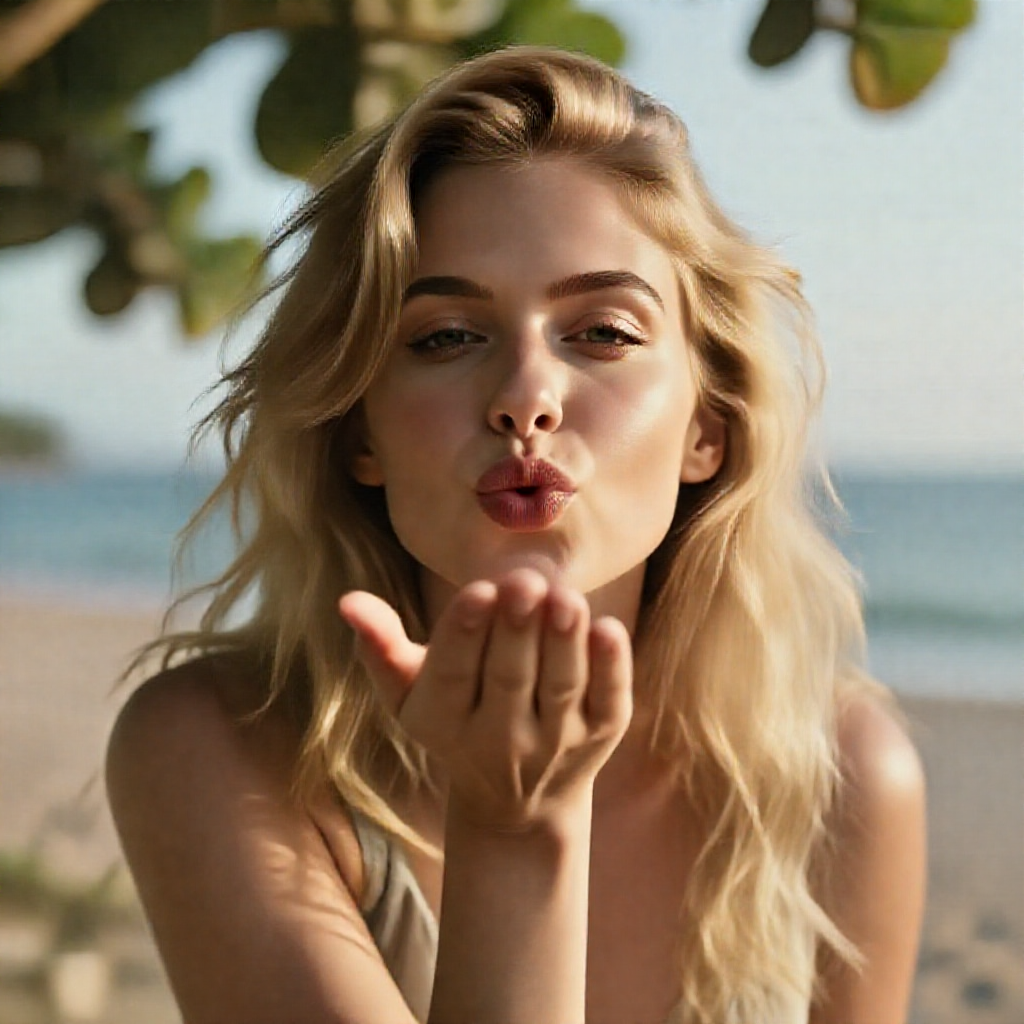
    Model shift

    Model Shift node means how noise or how polished the output will be. The lower the value, more artifacts will be present, the greater the value, more waxy the result. The model’s author recommends using Model Shift value = 3. All generations below were using 9 steps.

    				
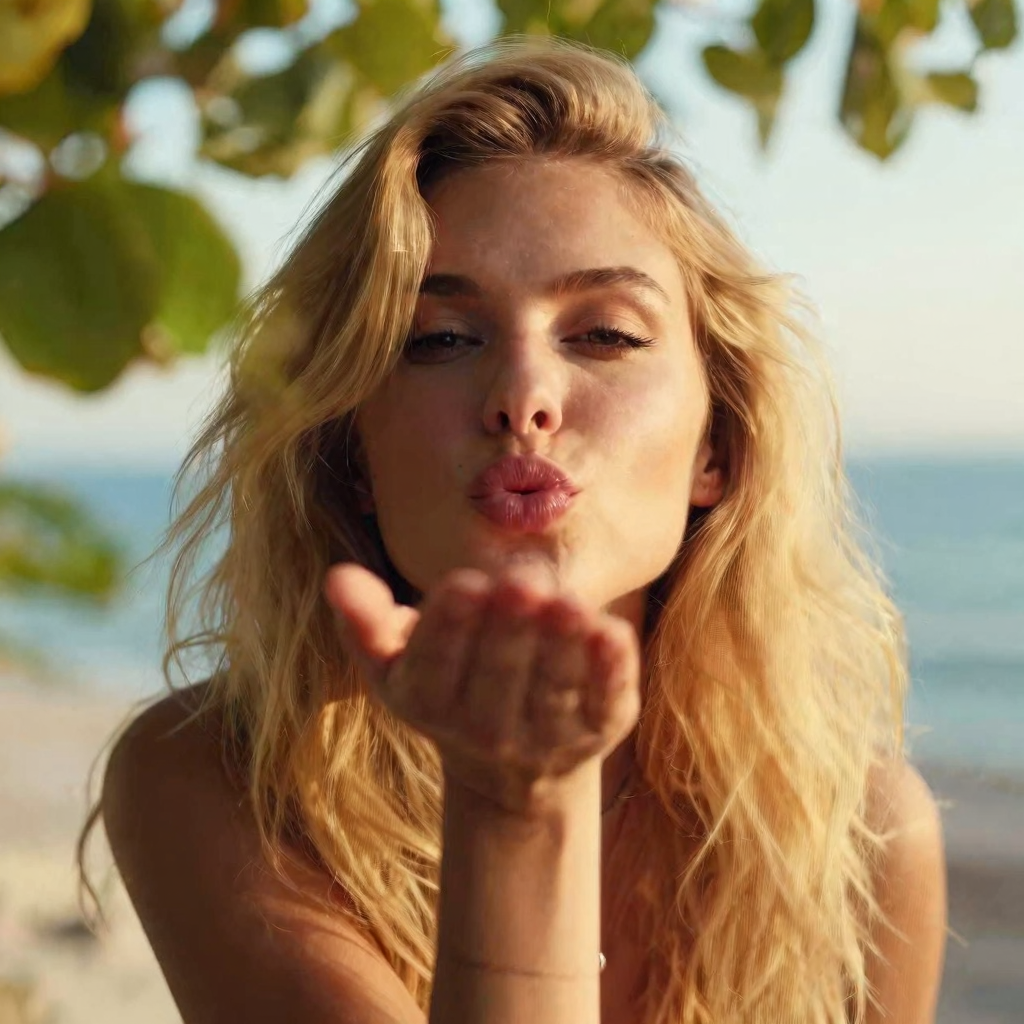
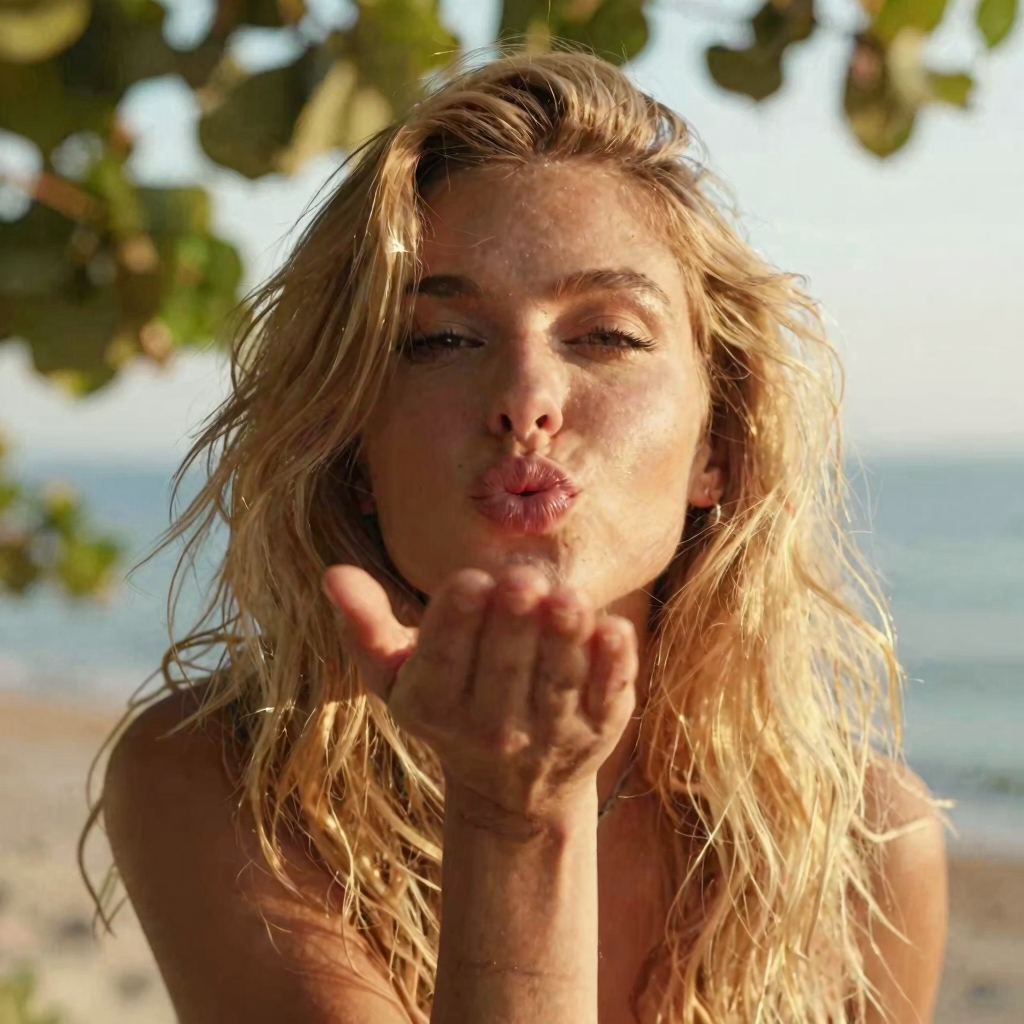
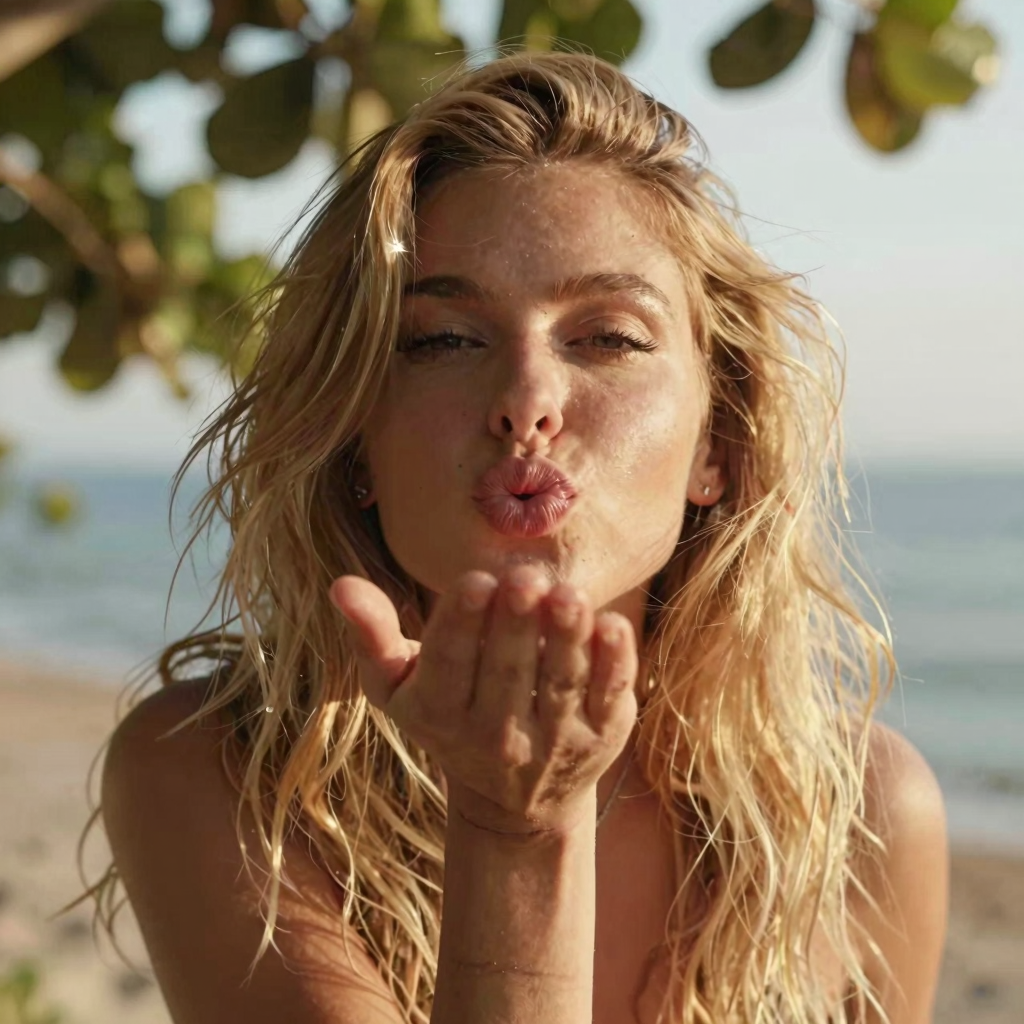
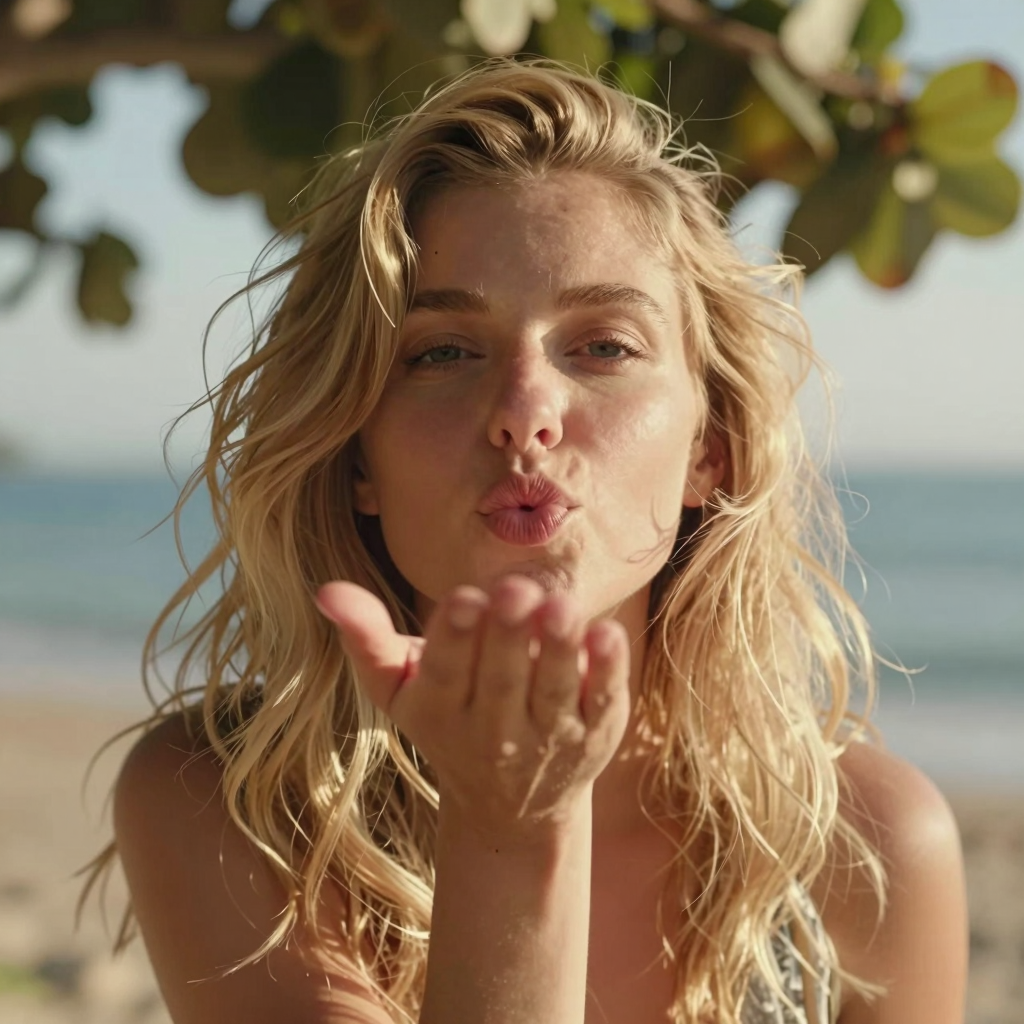
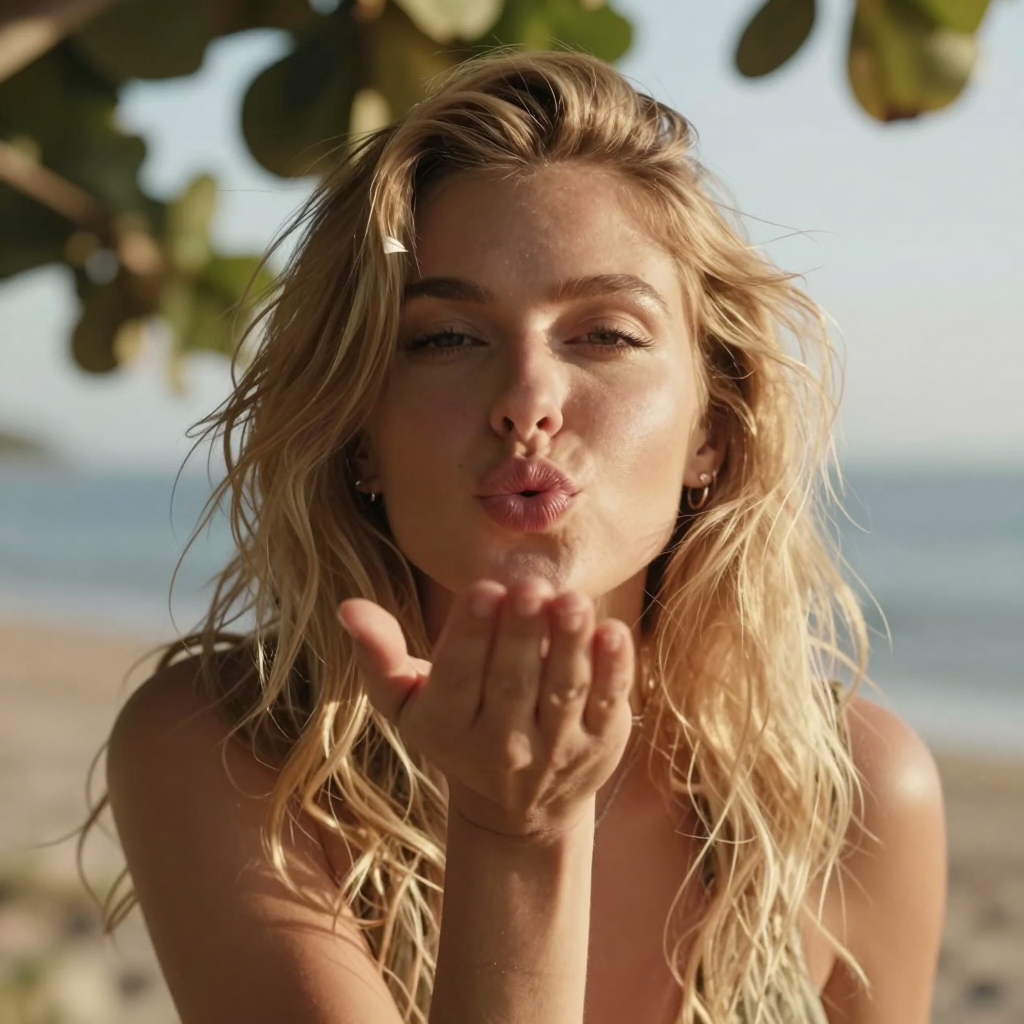
    					Blonde female with thick wavy hair, is sending a cute kiss to the camera, there are some out of focus tree leaves in front of her. Breezy seaside light, warm tones, cinematic close-up.


    Model Shift 0.2
    Time 14″

    Model Shift 0.5
    Time 14″

    Model Shift 1
    Time 14″

    Model Shift 2
    Time 18″

    Model Shift 3
    Time 14″

    Model Shift 2
    Time 18″

    Model Shift 30
    Time 14″

    Model Shift 100
    Time 18″

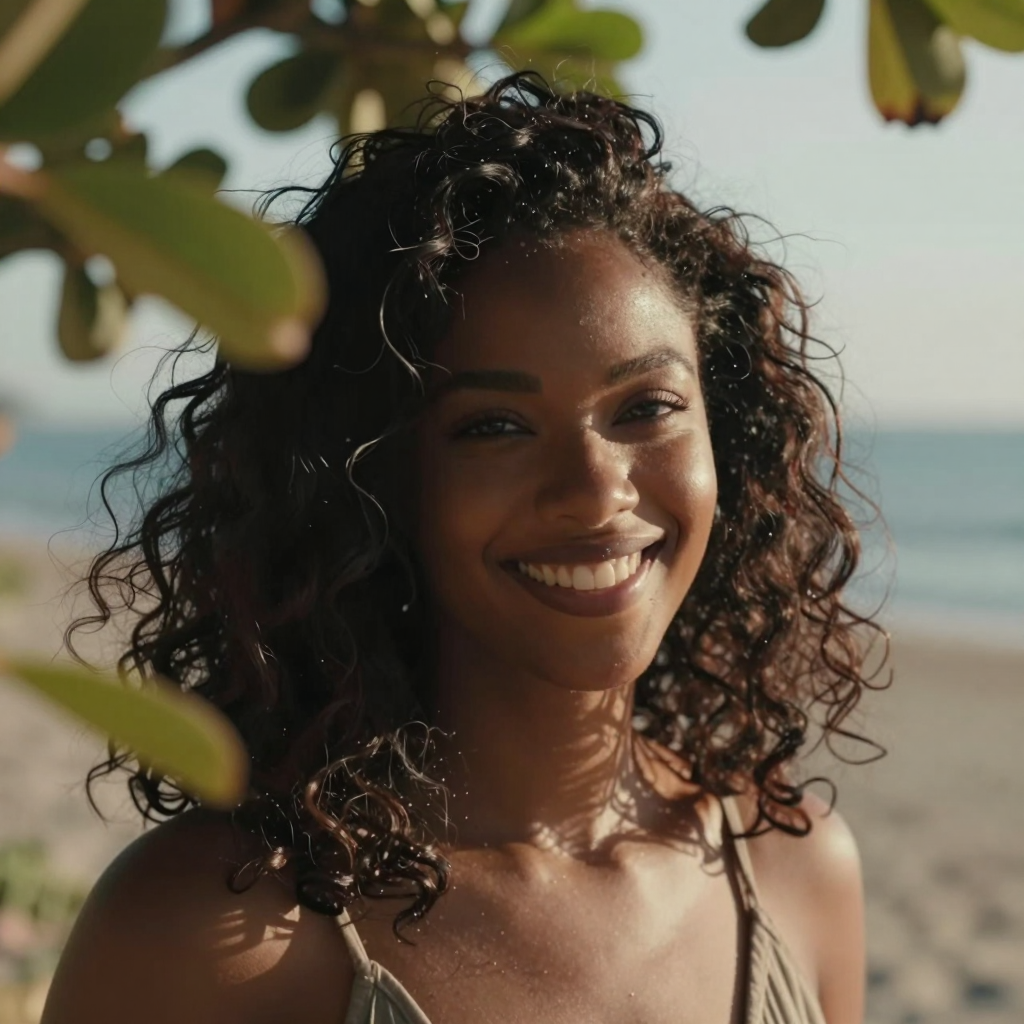
    Denoise

    Noise means how soon must the model’s latent space calculations stop before processing the final output. The model’s author recommends using Noise value = 1. All generations below were using 9 steps and shift 3. Very interesting to see how noise greatly affects the output.

    				
    					Black female with thick wavy hair, is spontaneously smiling to the camera, there are some out of focus tree leaves in front of her. Breezy seaside light, warm tones, cinematic close-up.


    Denoise 1
    Time 14″

    Denoise 0.9
    Time 14″

    Denoise 0.8
    Time 14″

    Denoise 0.7
    Time 13″

    Denoise 0.6
    Time 13″

    Denoise 0.5
    Time 13″

    Sampler

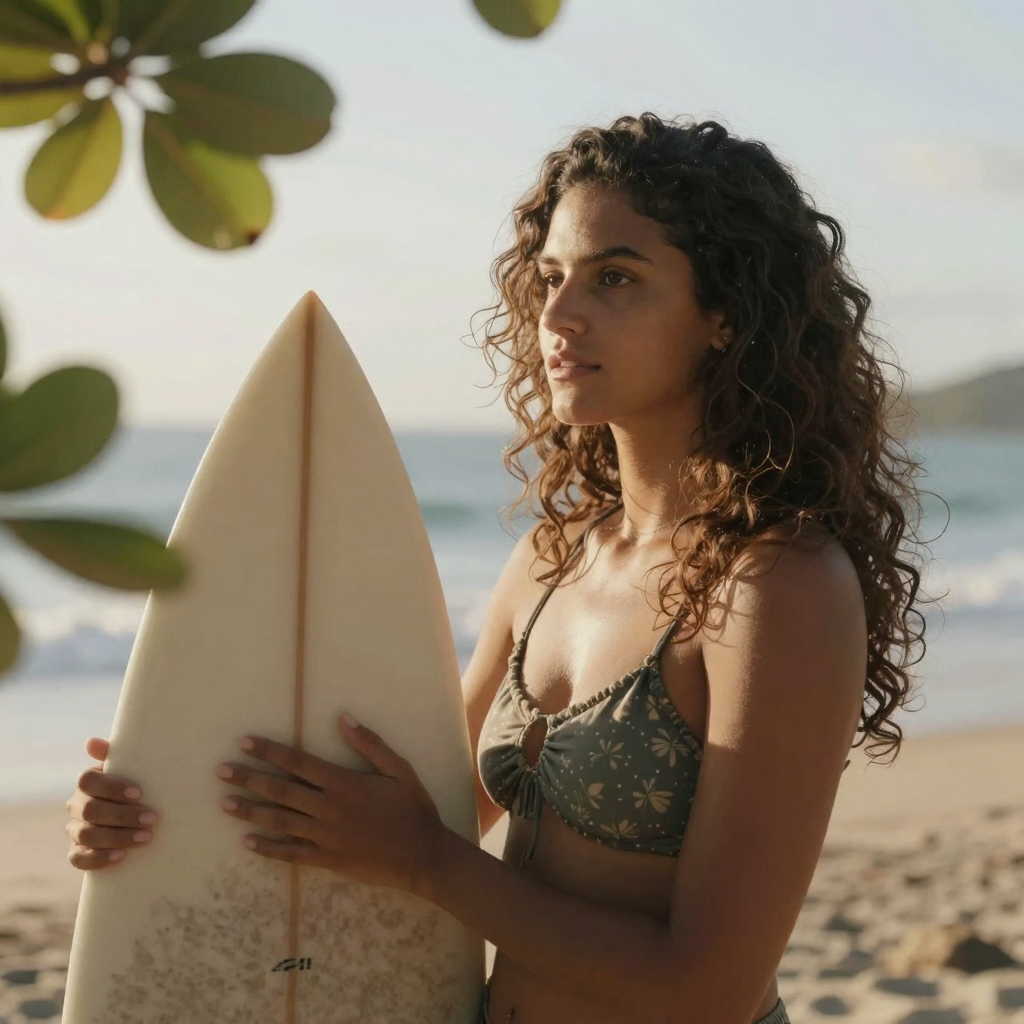
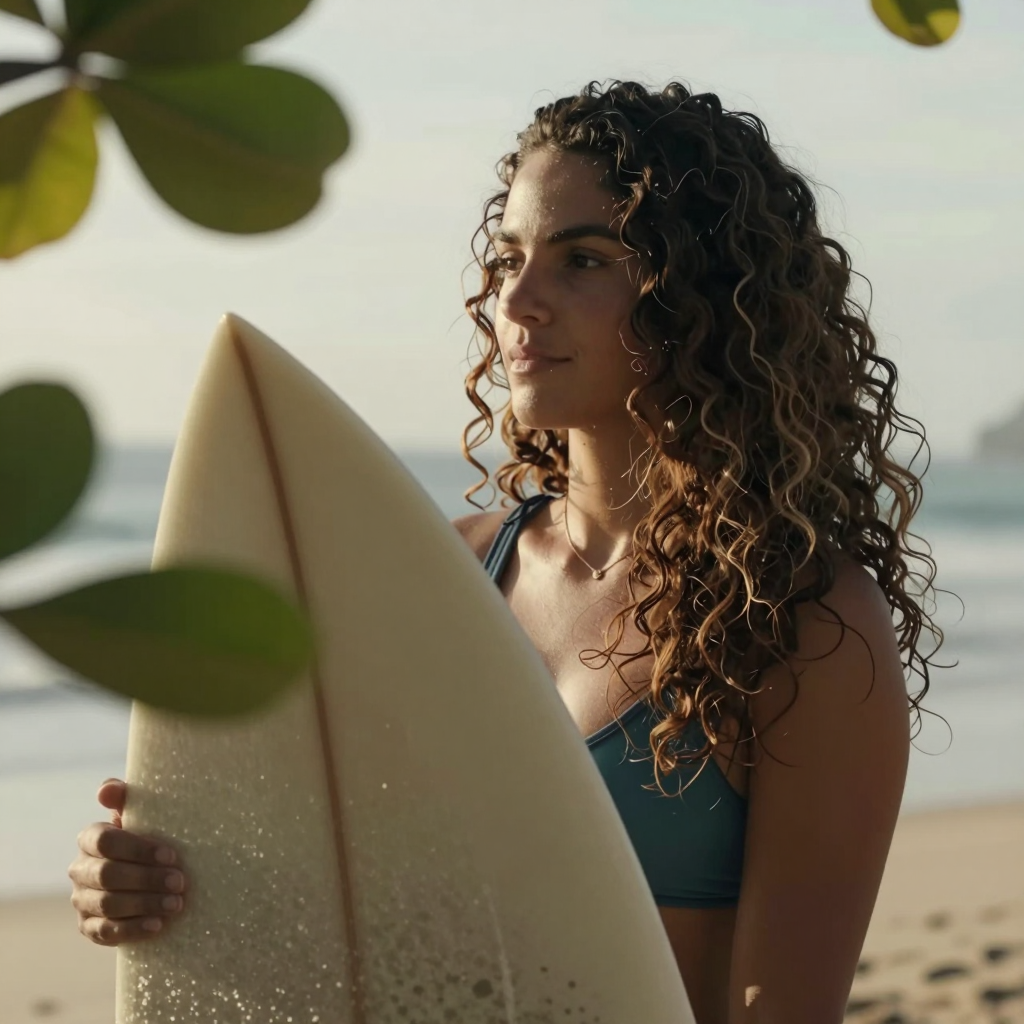
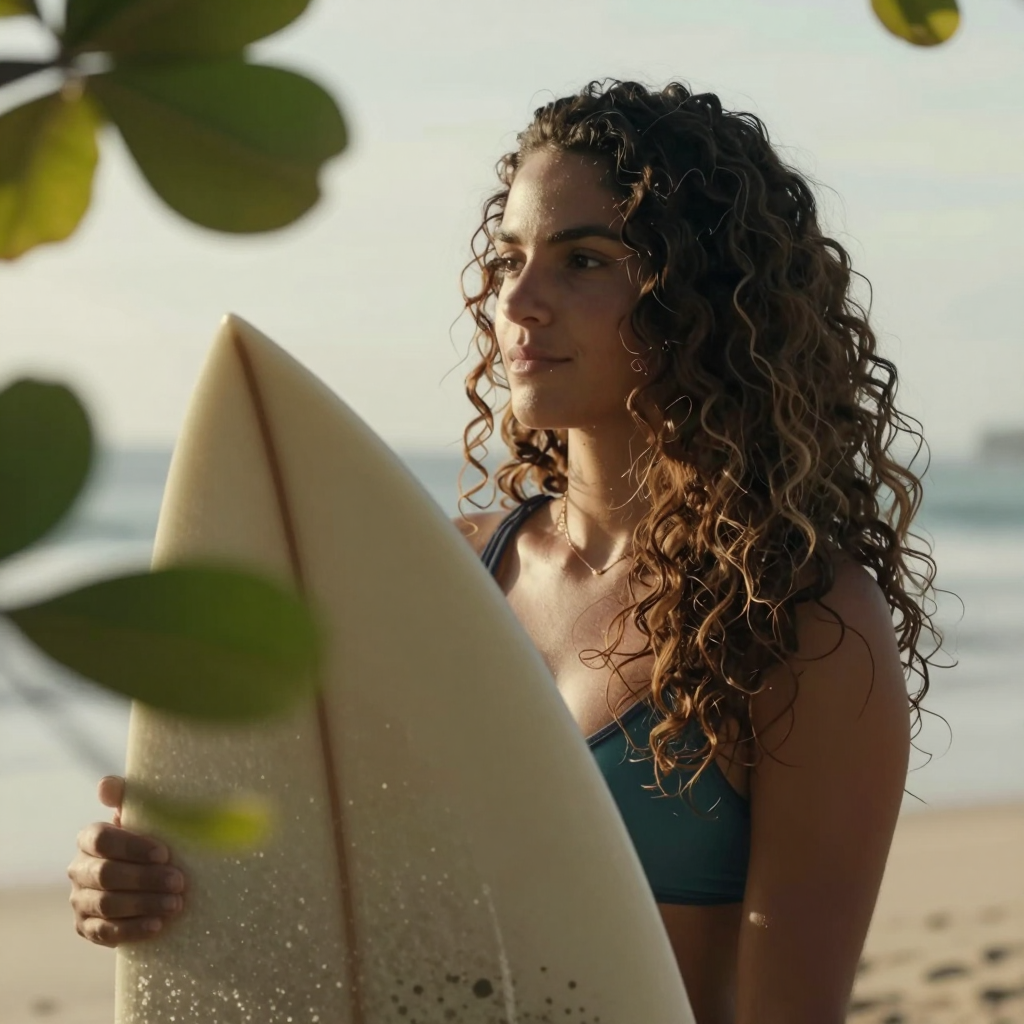
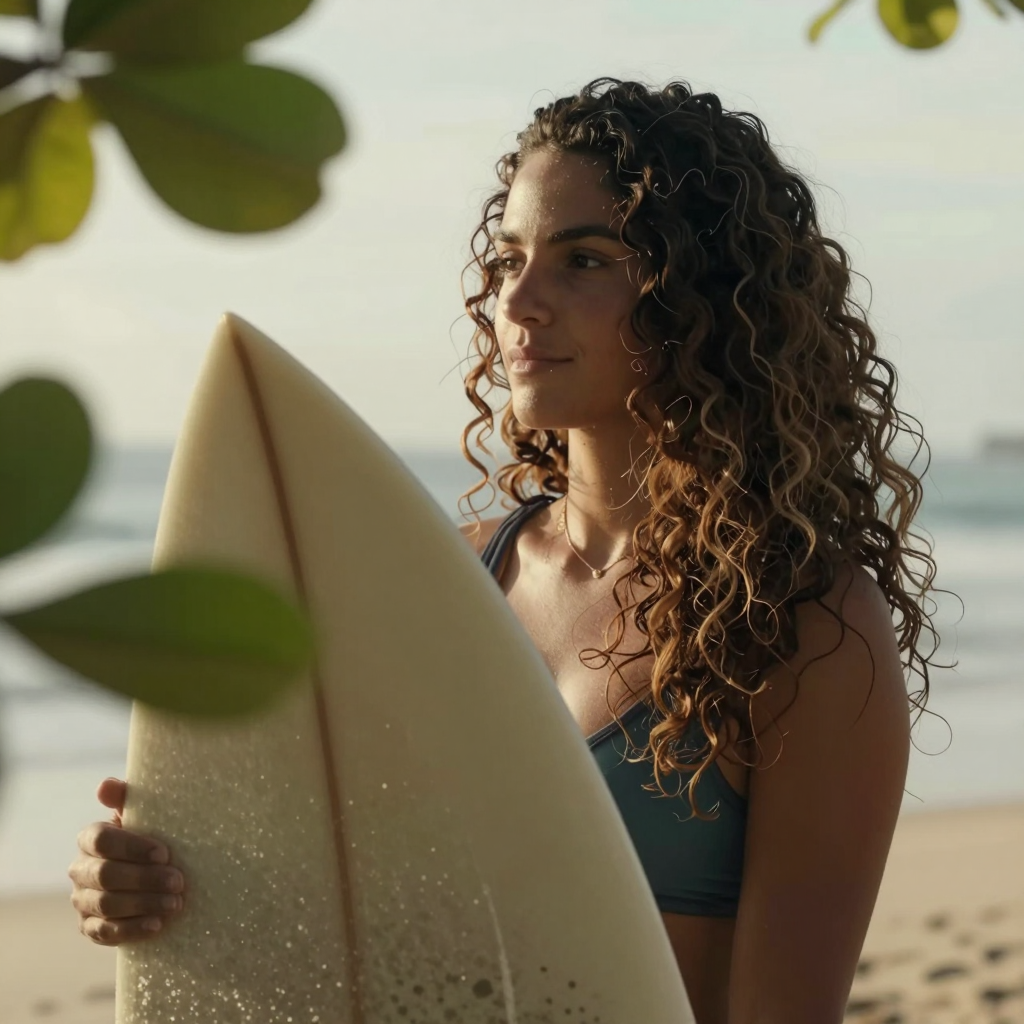
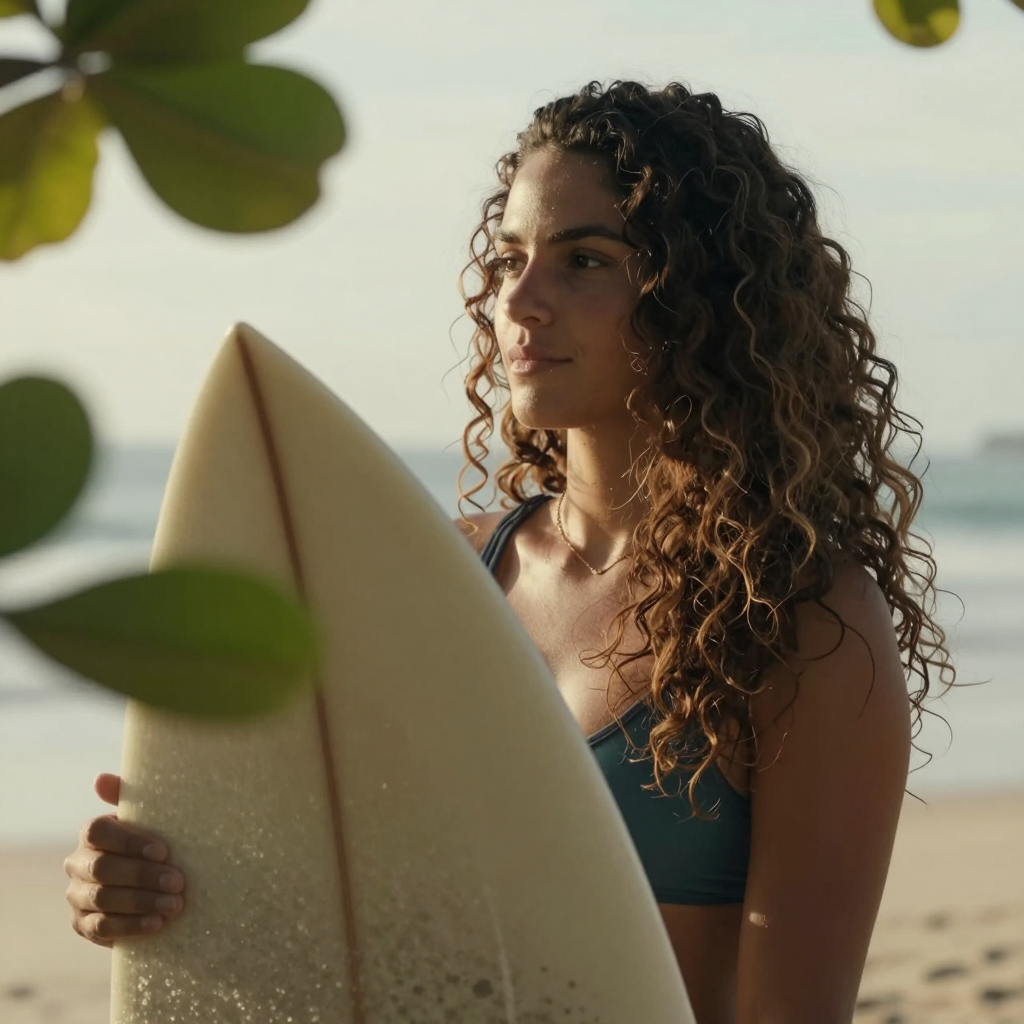
    Sampler means the agent technology that will interpret the latent space according to the scheduler model and convert to a visual output. Each agent has it’s own algorithm and will influence mainly the time it needs to generate the final output, with some minor subtle aspect changes.  The model’s author recommends using sampler = res_multistep. More noticeable are the light streaks on her arm and the out of focus leaves. All generations below were using 9 steps and shift 3.

    				
    					Brazilian female with thick wavy hair, is holding her surf board, there are some out of focus tree leaves in front of her. Breezy seaside light, warm tones, cinematic close-up.


    Sampler res_multistep
    Time 19″

    Sampler euler
    Time 13″

    Sampler heun
    Time 24″

    Sampler dmpp_2m
    Time 14″

    Sampler ipndm
    Time 13″

    Sampler deis
    Time 13″

    Sampler ddim
    Time 13″

    Sampler res_5s
    Time 64″

    Sampler res_6s_ode
    Time 76″

  • RES4LYF Sampler Comparison Chart

    RES4LYF Sampler Comparison Chart

    RES4LYF Sampler Comparison Chart

    All the ClownsharKSampler compared side by side

    comfyui

    generative ai

    Comparison

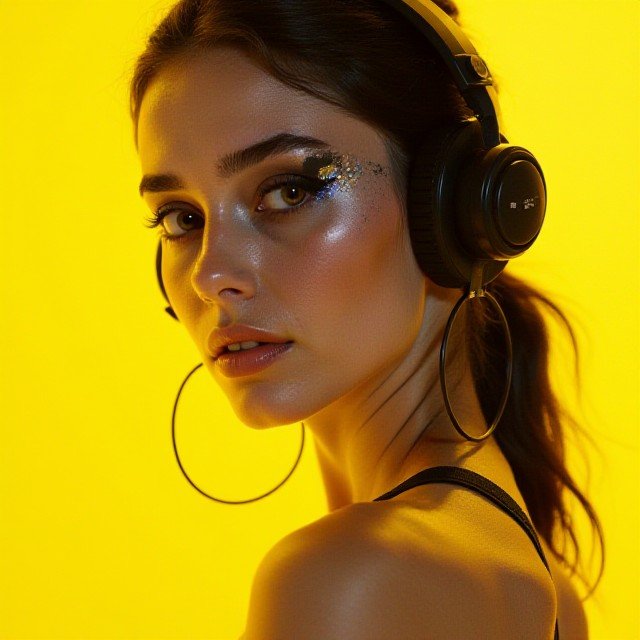
    Since RES4LYF was released and gained popularity for having almost a hundred samplers using ClownSharkSampler, I decided to test each one of them to the same prompt and resolution in an attempt to find the most sharp and realistic generative render.

    Positive promtp used:

    				
    					In a futuristic world, there is this beautiful woman wearing heavy make-up in geometric shapes. She is standing in front of a neutral vibrant yellow background, while the dynamic city lights casts high contrasting light on her face and mechanical parts. This is a portrait shot on Leica M6 using 85 mm lens. The skin texture is very sharp to the pore-level and has some imperfections. Film grain. fluxlisimo_cinematic


    Official workflow JSON: download from GitHub

    Model: flux1-dev-fp8.safetensors
    Clip 1: clip_l.safetensors
    Clip 2: t5xxl_fp16.safetensors
    VAE: ae.safetensors
    LORA: 3d_illustration + fluxlisimo_cinematic + grain_scape
    Dimension: 640 x 640
    Flux Conditioning: 1.5
    Fixed Seed: 347746757495977
    Steps: 16
    eta: 0.8
    Scheduler: normal
    Rendered using GTX 3080

    Veredict

    Fastest
    Exponential DDIM and Linear Euler in  24,5 seconds

    Veredict

    Best quality and prompt adeherence
    Linear rk6_7s in 167 seconds

    Veredict

    Very good result I
    Fully implicit radau_iia_7s in 227,5 seconds

    Veredict

    Very good result II
    Exponential Res_4_Minchev in 95 seconds

    All samplers compared side to side

    Below you will find each Sampler Algorithm Method followed by the sampler’s name and the time (in seconds) it took to generate/render a 640 x 640 px image on a GTX 3080 10GB.

    Overall selected samplers for good resulting

    At the end of this Article you will find some generations using the Samplers I am electing as the best out-coming results. These generations were rendered at 24 steps and at 512 x 1024 px on a GTX 3080 10GB. Jump directly to this section.

    Multistep

    Res_2m, Res_3m, Dpmpp_2m, Dpmpp_3m, Abnorsett_2m, Abnorsett_3m, Abnorsett_4m, Deis_2, Deis_3m, DEis_4m

    multistep
    res_2m
    29”

    multistep
    res_3m
    36”

    multistep
    dpmpp_2m
    29”

    multistep
    dpmpp_3m
    36”

    multistep
    abnorsett_2m
    29”

    multistep
    abnorsett_3m
    32”

    multistep
    abnorsett_4m
    42”

    multistep
    deis_2m
    28”

    multistep
    deis_3m
    36”

    multistep
    deis_4m
    47”

    Exponential

    Res2, Res3, Res4, Res5, res6, Res8, Res10, Res 15, Res16, etdrk2, etdrk3, dpmpp, lawson, ddim

    exponential
    res_2s
    47”

    exponential
    res_2s_stable
    47,5”

    exponential
    res_2s_rkmk2e
    47”

    exponential
    res_3s
    70”

    exponential
    res_3s_non-monotonic
    69,5”

    exponential
    res_3s_alt
    70,5”

    exponential
    res_3s_cox_matthews
    70”

    exponential
    res_3s_lie
    71”

    exponential
    res_3s_sunstar
    71,5”

    exponential
    res_3s_strehmel_weinner
    92,5”

    exponential
    res_3s_krogstadt
    92,5”

    exponential
    res_4s_cox_matthews
    93,5”

    exponential
    res_4s_cfree4
    93”

    exponential
    res_4s_friedli
    106”

    exponential
    res_4s_minchev
    95”

    exponential
    res_4s_munthe-kaas
    91”

    exponential
    res_5s
    116”

    exponential
    res_5s_hochbruck-ostermann
    115”

    exponential
    res_6s
    140”

    exponential
    res_8s
    187”

    exponential
    res_10s
    239”

    exponential
    res_15s
    366”

    exponential
    res_16s
    384”

    exponential
    etdrk2_2s
    46”

    exponential
    etdrk3_a_3s
    69”

    exponential
    etdrk3_b_3s
    69”

    exponential
    etdrk4_4s
    93,5”

    exponential
    etdrk3_4s_alt
    92”

    exponential
    dpmpp_2s
    47,5”

    exponential
    dpmpp_sde_2s
    47”

    exponential
    dpmpp_3s
    70”

    exponential
    lawson_2a_2s
    48”

    exponential
    lawson_2b_2s
    48”

    exponential
    lawson4_4s
    93”

    exponential
    lawson41-gen_4s
    93”

    exponential
    lawson41-gen-mod_4s
    92”

    exponential
    ddim
    24,5”

    Hybrid

    Pec423, pec 433, abnorsett, lawson

    hybrid
    pec423_2h3s
    47”

    hybrid
    pec433_2h3s
    70”

    hybrid
    abnorsett2_1h2s
    48”

    hybrid
    abnorsett3_2h2s
    47,5”

    hybrid
    lawson42-gen-mod_1h4s
    93”

    hybrid
    lawson42-gen-mod_2h4s
    94”

    hybrid
    lawson42-gen-mode_3h4s
    94”

    Linear

    ralston, midpoint, heun, houwen-wray, kutta, ssprk3, RK, bogacki_shampine, dormand-prince, tsi, euler

    linear
    ralston_2s
    47,5”

    linear
    ralston_3s
    71”

    linear
    ralston_4s
    93”

    linear
    midpoint_2s
    47”

    linear
    heun_2s
    48,5”

    linear
    heun_3s
    71”

    linear
    houwen-wray_3s
    71,5”

    linear
    kutta_3s
    71”

    linear
    ssprk3_3s
    71”

    linear
    ssprk4_4s
    110”

    linear
    rk38_4s
    95”

    linear
    rk4_4s
    93”

    linear
    rk6_7s
    167”

    linear
    bogacki_shampine_4s
    95”

    linear
    bogacki_shampine_7s
    165”

    linear
    dormand-prince_6s
    141”

    linear
    dormand-prince_13s
    318,5”

    linear
    tsi_7s
    167”

    linear
    euler
    24,5”

    Diagonal implicit

    irk_exp_diag, kraaijevanger_spijkjer, qin_zhang, pareschi_russo, crouzeix

    diagonal implicit
    irk_exp_diag_2s
    74”

    diagonal implicit
    kraaijevanger_spijkjer_2s
    74”

    diagonal implicit
    qin_zhang_2s
    74”

    diagonal implicit
    pareschi_russo_2s
    73”

    diagonal implicit
    pareschi_russo_alt_2s
    76”

    diagonal implicit
    crouzeix_2s
    74”

    diagonal implicit
    crouzeix_3s
    100”

    diagonal implicit
    crouzeix_3s_alt
    102”

    Fully implicit

    gauss_legendre, RADAU, lobatto

    fully implicit
    gauss_legendre_2s
    74”

    fully implicit
    gauss_legendre_3s
    101”

    fully implicit
    gauss_legendre_4s
    130”

    fully implicit
    gauss_legendre_5s
    160”

    fully implicit
    gauss_legendre_5s_ascending
    159”

    fully implicit
    radau_ia_2s
    73”

    fully implicit
    radau_ia_3s
    76”

    fully implicit
    radau_iia_2s
    74”

    fully implicit
    radau_iia_3s
    99,5”

    fully implicit
    radau_iia_3s_alt
    100”

    fully implicit
    radau_iia_5s
    164”

    fully implicit
    radau_iia_7s
    227,5”

    fully implicit
    radau_iia_9s
    303”

    fully implicit
    radau_iia_11s
    375”

    fully implicit
    lobatto_iiia_2s
    54”

    fully implicit
    lobatto_iiia_3s
    80”

    fully implicit
    lobatto_iiia_4s
    109,5”

    fully implicit
    lobatto_iib_2s
    54”

    fully implicit
    lobatto_iib_3s
    77,5”

    fully implicit
    lobatto_iib_4s
    103,5”

    fully implicit
    lobatto_iic_2s
    50,5”

    fully implicit
    lobatto_iic_3s
    78,5”

    fully implicit
    lobatto_iic_4s
    106,5”

    fully implicit
    lobatto_iic_star_2s
    51”

    fully implicit
    lobatto_iic_star_3s
    78”

    fully implicit
    lobatto_iid_2s
    51”

    fully implicit
    lobatto_iid_3s
    77,5”

    … end of the sampler’s list …

    Overall good results

    RES_4S_MINCHEV, DEIS_3M, RES_2M, RK6_7S, lobatto_iiib_4s, lobatto_iiic_4s

    exponential
    res_4s_minchev
    24 steps
    150”

    exponential
    res_4s_minchev
    24 steps
    151.5”

    exponential
    res_4s_minchev
    24 steps
    151,5”

    exponential
    res_4s_minchev
    24 steps
    157”

    multistep
    deis_3m
    24 steps
    60”

    multistep
    deis_3m
    24 steps
    60”

    multistep
    deis_3m
    24 steps
    59”

    multistep
    deis_3m
    24 steps
    59”

    multistep
    res_2m
    24 steps
    51”

    multistep
    res_2m
    24 steps
    51”

    multistep
    res_2m
    24 steps
    50”

    multistep
    res_2m
    24 steps
    51”

    linear
    rk6_7s
    24 steps
    275”

    linear
    rk6_7s
    24 steps
    169”

    linear
    rk6_7s
    24 steps
    169”

    linear
    rk6_7s
    24 steps
    296”

    fully implicit
    lobatto_iiib_4s
    24 steps
    169”

    fully implicit
    lobatto_iiib_4s
    24 steps
    169”

    fully implicit
    lobatto_iiib_4s
    24 steps
    175”

    fully implicit
    lobatto_iiib_4s
    24 steps
    173,5”

    fully implicit
    lobatto_iiic_4s
    24 steps
    170”

    fully implicit
    lobatto_iiic_4s
    24 steps
    167”

    fully implicit
    lobatto_iiic_4s
    24 steps
    174”

    fully implicit
    lobatto_iiic_4s
    24 steps
    166,5”

    End of the first study and batch comparison test.

    Workflow: {“id”: “72f6123a-4c3f-4675-9e45-86722ffa8aeb”, “revision”: 0, “last_node_id”: 22, “last_link_id”: 33, “nodes”: [{“id”: 13, “type”: “VAEDecode”, “pos”: [859.5225830078125, 217.15052795410156], “size”: [140, 46], “flags”: {}, “order”: 8, “mode”: 0, “inputs”: [{“name”: “samples”, “type”: “LATENT”, “link”: 12}, {“name”: “vae”, “type”: “VAE”, “link”: 13}], “outputs”: [{“name”: “IMAGE”, “type”: “IMAGE”, “links”: [14, 16]}], “properties”: {“cnr_id”: “comfy-core”, “ver”: “0.3.44”, “Node name for S&R”: “VAEDecode”}, “widgets_values”: [], “color”: “#322”, “bgcolor”: “#533”, “shape”: 1}, {“id”: 10, “type”: “CLIPTextEncode”, “pos”: [115.9236831665039, 642.4409790039062], “size”: [400, 200], “flags”: {“collapsed”: true}, “order”: 3, “mode”: 0, “inputs”: [{“name”: “clip”, “type”: “CLIP”, “link”: 7}], “outputs”: [{“name”: “CONDITIONING”, “type”: “CONDITIONING”, “links”: [9]}], “title”: “Negative Prompt”, “properties”: {“cnr_id”: “comfy-core”, “ver”: “0.3.44”, “Node name for S&R”: “CLIPTextEncode”}, “widgets_values”: [“”], “color”: “#322”, “bgcolor”: “#533”, “shape”: 1}, {“id”: 14, “type”: “SaveImageExtended”, “pos”: [1060, 210], “size”: [231.4296875, 718], “flags”: {}, “order”: 9, “mode”: 0, “inputs”: [{“name”: “images”, “type”: “IMAGE”, “link”: 14}, {“name”: “positive_text_opt”, “shape”: 7, “type”: “STRING”, “link”: null}, {“name”: “negative_text_opt”, “shape”: 7, “type”: “STRING”, “link”: null}], “outputs”: [], “properties”: {“cnr_id”: “save-image-extended-comfyui”, “ver”: “2.64.0”, “Node name for S&R”: “SaveImageExtended”}, “widgets_values”: [“RES4LYF_”, “sampler_name, cfg, steps, %F %H-%M-%S”, “comparisionbatch”, “”, “-“, “disabled”, false, “”, true, 4, “last”, true, true, “.jpg”, 90], “shape”: 1}, {“id”: 1, “type”: “ClownModelLoader”, “pos”: [-203.28634643554688, 222.3040313720703], “size”: [270, 266], “flags”: {}, “order”: 0, “mode”: 0, “inputs”: [], “outputs”: [{“name”: “model”, “type”: “MODEL”, “links”: [33]}, {“name”: “clip”, “type”: “CLIP”, “links”: [7, 28]}, {“name”: “vae”, “type”: “VAE”, “links”: [10, 13]}], “properties”: {“cnr_id”: “RES4LYF”, “ver”: “81fe5f4d02c1a86d4cbb1ef92c652055f574810a”, “Node name for S&R”: “ClownModelLoader”}, “widgets_values”: [“flux1-dev-fp8.safetensors”, “default”, “clip_l.safetensors”, “t5xxl_fp16.safetensors”, “.none”, “.none”, “flux”, “ae.safetensors”], “shape”: 1}, {“id”: 11, “type”: “FluxGuidance”, “pos”: [-211.47117614746094, 563.1766357421875], “size”: [270, 58], “flags”: {}, “order”: 1, “mode”: 0, “inputs”: [{“name”: “conditioning”, “type”: “CONDITIONING”, “link”: null}], “outputs”: [{“name”: “CONDITIONING”, “type”: “CONDITIONING”, “links”: null}], “properties”: {“cnr_id”: “comfy-core”, “ver”: “0.3.44”, “Node name for S&R”: “FluxGuidance”}, “widgets_values”: [1.5]}, {“id”: 22, “type”: “Lora Loader Stack (rgthree)”, “pos”: [120, 90], “size”: [271.8785095214844, 246], “flags”: {}, “order”: 4, “mode”: 0, “inputs”: [{“name”: “model”, “type”: “MODEL”, “link”: 33}, {“name”: “clip”, “type”: “CLIP”, “link”: 28}], “outputs”: [{“name”: “MODEL”, “type”: “MODEL”, “links”: [32]}, {“name”: “CLIP”, “type”: “CLIP”, “links”: [29]}], “properties”: {“cnr_id”: “rgthree-comfy”, “ver”: “944d5353a1b0a668f40844018c3dc956b95a67d7”, “Node name for S&R”: “Lora Loader Stack (rgthree)”}, “widgets_values”: [“3d-illustration.safetensors”, 0.5000000000000001, “fluxlisimo_cinematic_v1_FLUX.safetensors”, 0.8500000000000002, “GrainScape.safetensors”, 0.5000000000000001, “None”, 0], “color”: “#233”, “bgcolor”: “#355”, “shape”: 1}, {“id”: 9, “type”: “CLIPTextEncode”, “pos”: [111.22306060791016, 391.9552917480469], “size”: [418.7828674316406, 200], “flags”: {}, “order”: 6, “mode”: 0, “inputs”: [{“name”: “clip”, “type”: “CLIP”, “link”: 29}], “outputs”: [{“name”: “CONDITIONING”, “type”: “CONDITIONING”, “links”: [8]}], “title”: “Positive Prompt”, “properties”: {“cnr_id”: “comfy-core”, “ver”: “0.3.44”, “Node name for S&R”: “CLIPTextEncode”}, “widgets_values”: [“In a futuristic world, there is this beautiful woman wearing heavy make-up in geometric shapes. She is standing in front of a neutral vibrant yellow background, while the dynamic city lights casts high contrasting light on her face and mechanical parts. This is a portrait shot on Leica M6 using 85 mm lens. The skin texture is very sharp to the pore-level and has some imperfections. Film grain. fluxlisimo_cinematic”], “color”: “#232”, “bgcolor”: “#353”, “shape”: 1}, {“id”: 15, “type”: “PreviewImage”, “pos”: [1320, 200], “size”: [508.1442565917969, 708.9977416992188], “flags”: {}, “order”: 10, “mode”: 0, “inputs”: [{“name”: “images”, “type”: “IMAGE”, “link”: 16}], “outputs”: [], “properties”: {“cnr_id”: “comfy-core”, “ver”: “0.3.44”, “Node name for S&R”: “PreviewImage”}, “widgets_values”: [], “shape”: 1}, {“id”: 19, “type”: “Note”, “pos”: [840, 530], “size”: [210, 88], “flags”: {}, “order”: 2, “mode”: 0, “inputs”: [], “outputs”: [], “properties”: {}, “widgets_values”: [“347746757495977n347746757495977”], “color”: “#432”, “bgcolor”: “#653”, “shape”: 1}, {“id”: 12, “type”: “VAEEncodeAdvanced”, “pos”: [116.57431030273438, 690.6495361328125], “size”: [270, 278], “flags”: {}, “order”: 5, “mode”: 0, “inputs”: [{“name”: “image_1”, “shape”: 7, “type”: “IMAGE”, “link”: null}, {“name”: “image_2”, “shape”: 7, “type”: “IMAGE”, “link”: null}, {“name”: “mask”, “shape”: 7, “type”: “IMAGE”, “link”: null}, {“name”: “latent”, “shape”: 7, “type”: “LATENT”, “link”: null}, {“name”: “vae”, “shape”: 7, “type”: “VAE”, “link”: 10}], “outputs”: [{“name”: “latent_1”, “type”: “LATENT”, “links”: null}, {“name”: “latent_2”, “type”: “LATENT”, “links”: null}, {“name”: “mask”, “type”: “MASK”, “links”: null}, {“name”: “empty_latent”, “type”: “LATENT”, “links”: [11]}, {“name”: “width”, “type”: “INT”, “links”: null}, {“name”: “height”, “type”: “INT”, “links”: null}], “properties”: {“cnr_id”: “RES4LYF”, “ver”: “81fe5f4d02c1a86d4cbb1ef92c652055f574810a”, “Node name for S&R”: “VAEEncodeAdvanced”}, “widgets_values”: [“false”, 512, 1024, “red”, false, “4_channels”], “color”: “#322”, “bgcolor”: “#533”, “shape”: 1}, {“id”: 4, “type”: “ClownsharKSampler_Beta”, “pos”: [553.3905639648438, 220.2578887939453], “size”: [270, 662], “flags”: {}, “order”: 7, “mode”: 0, “inputs”: [{“name”: “model”, “shape”: 7, “type”: “MODEL”, “link”: 32}, {“name”: “positive”, “shape”: 7, “type”: “CONDITIONING”, “link”: 8}, {“name”: “negative”, “shape”: 7, “type”: “CONDITIONING”, “link”: 9}, {“name”: “latent_image”, “shape”: 7, “type”: “LATENT”, “link”: 11}, {“name”: “sigmas”, “shape”: 7, “type”: “SIGMAS”, “link”: null}, {“name”: “guides”, “shape”: 7, “type”: “GUIDES”, “link”: null}, {“name”: “options”, “shape”: 7, “type”: “OPTIONS”, “link”: null}], “outputs”: [{“name”: “output”, “type”: “LATENT”, “links”: [12]}, {“name”: “denoised”, “type”: “LATENT”, “links”: null}, {“name”: “options”, “type”: “OPTIONS”, “links”: null}], “properties”: {“cnr_id”: “RES4LYF”, “ver”: “81fe5f4d02c1a86d4cbb1ef92c652055f574810a”, “Node name for S&R”: “ClownsharKSampler_Beta”}, “widgets_values”: [0.7000000000000002, “multistep/res_2m”, “normal”, 28, -1, 1, 1.0000000000000002, 586933988910742, “randomize”, “standard”, true], “color”: “#223”, “bgcolor”: “#335”, “shape”: 1}], “links”: [[7, 1, 1, 10, 0, “CLIP”], [8, 9, 0, 4, 1, “CONDITIONING”], [9, 10, 0, 4, 2, “CONDITIONING”], [10, 1, 2, 12, 4, “VAE”], [11, 12, 3, 4, 3, “LATENT”], [12, 4, 0, 13, 0, “LATENT”], [13, 1, 2, 13, 1, “VAE”], [14, 13, 0, 14, 0, “IMAGE”], [16, 13, 0, 15, 0, “IMAGE”], [28, 1, 1, 22, 1, “CLIP”], [29, 22, 1, 9, 0, “CLIP”], [32, 22, 0, 4, 0, “MODEL”], [33, 1, 0, 22, 0, “MODEL”]], “groups”: [], “config”: {}, “extra”: {“ds”: {“scale”: 1.2884080000000004, “offset”: [-62.504483003015366, -106.68595565476912]}, “frontendVersion”: “1.23.4”, “VHS_latentpreview”: false, “VHS_latentpreviewrate”: 0, “VHS_MetadataImage”: true, “VHS_KeepIntermediate”: true}, “version”: 0.4, “seed_widgets”: {“4”: 7}}
    RES4LYF ClownsharKSampler

    Comparison chart generated on 19/20 July 2025

plugins premium WordPress